vibecosystem
Your AI software team. Built on Claude Code.


Türkçe | English | Espanol | Francais | Deutsch | Portugues | Italiano | Nederlands | 中文 | 日本語 | 한국어 | العربية | हिन्दी | Русский
vibecosystem turns Claude Code into a full AI software team — 138 specialized agents that plan, build, review, test, and learn from every mistake. No configuration needed — just install and code.
v2.0: 13 new agents (sast-scanner, mutation-tester, graph-analyst, mcp-manager, community-manager, benchmark, dependency-auditor, api-designer, incident-responder, data-modeler, test-architect, release-engineer, documentation-architect) + 23 new skills (SAST, compliance, product, marketing, MCP) + 4 new hooks + Agent Monitoring Dashboard + GitHub Actions CI/CD + MCP Auto-Discovery. See UPGRADING.md for details.
v2.1: 7 new skills (minimax-pdf, minimax-docx, minimax-xlsx, pptx-generator, frontend-dev, fullstack-dev, clone-website) + 2 new agents (document-generator, website-cloner). Document generation, pixel-perfect website cloning, and enhanced frontend/fullstack patterns.
v2.1.1: 7 new skills from oh-my-claudecode (smart-model-routing, deep-interview, agent-benchmark, visual-verdict, ai-slop-cleaner, factcheck-guard, notepad-system) + 1 new rule (commit-trailers).
v2.2: 5 features from Claude Code source — Agent Memory (persistent per-agent memory), Magic Docs (auto-updating docs), Dream Consolidation (cross-session memory cleanup), Smart Recall (frontmatter-based memory scoring), Plugin Toggle (hook enable/disable CLI). +7 hooks, skill references for 21 agents.
v2.2.1: Monetization stack — 1 new agent (monetization-expert), 2 new skills (paywall-optimizer, codex-orchestration), 3 updated skills (revenuecat-patterns, paywall-strategy, subscription-pricing). AI-powered paywall optimization with 14-category benchmarks, RevenueCat SDK patterns, Codex + Claude Code orchestration.
v2.3: vibeco CLI tool (stats, doctor, profiles, dashboard), 6 preset profiles for token savings, one-liner install (curl | bash).
v2.4: Terminal HUD (real-time statusline), prompt auto-improver (enriches vague prompts with context), persistent planning system (PLAN.md/PROGRESS.md/CONTEXT.md for 96.7% task completion). Competitive gap closure from analysis of 20+ ecosystem repos.
v3.0: npx vibecosystem init npm installer, plugin.json for official plugin ecosystem, worktree isolation on 60 producer agents, Claude-adapter model routing (Haiku/Sonnet/Opus tiers), knowledge graph integration (6-71x token savings), dashboard v2 with token/cost tracking.
v3.4: Lean core runtime is now the default. Codex uses one model authority, luna_worker with gpt-5.6-luna and max reasoning; Claude-only Opus/Sonnet frontmatter remains isolated to the Claude adapter. Context injectors have bounded event/session budgets, and installer ownership manifests make backups and pruning explicit.
The Problem
Claude Code is powerful, but it's one assistant. You prompt, it responds, you review. For complex projects you need a planner, a reviewer, a security auditor, a tester — and you end up being all of them yourself.
The Solution
vibecosystem is a complete Claude Code ecosystem that creates a self-organizing AI team:
- 138 agents — specialized roles from frontend-dev to security-analyst
- 296 skills — reusable knowledge from TDD workflows to Kubernetes patterns
- 74 hooks — TypeScript sensors that observe, filter, and inject context
- 20 rules — behavioral guidelines that shape every agent's output
- Self-learning — every error becomes a rule, automatically
After setup, you say "build a feature" and 20+ agents coordinate across 5 phases.
Quick Start
npm (recommended)
npx vibecosystem init
One-liner
curl -fsSL https://raw.githubusercontent.com/vibeeval/vibecosystem/main/install-remote.sh | bash
Manual
git clone https://github.com/vibeeval/vibecosystem.git
cd vibecosystem
./install.sh --profile core
That's it. Use Claude Code normally. The team activates.
vibeco CLI
After install, the vibeco command is available:
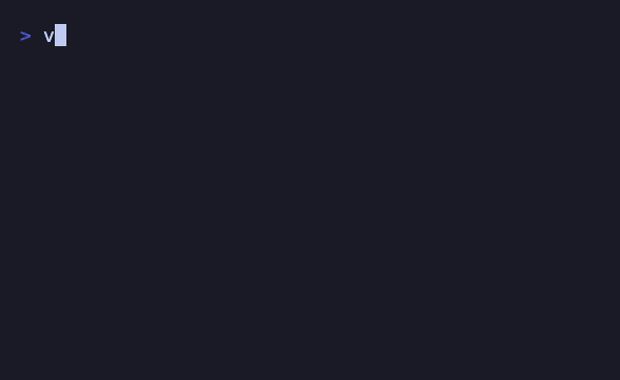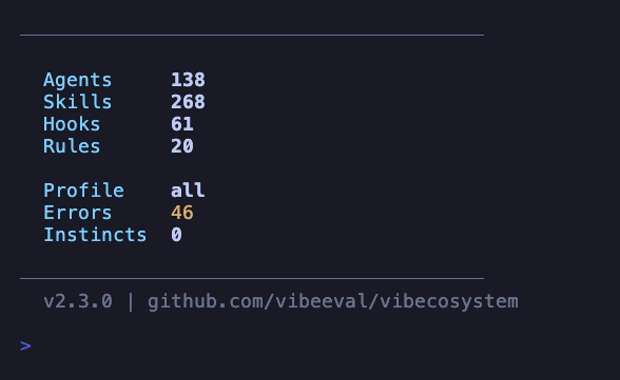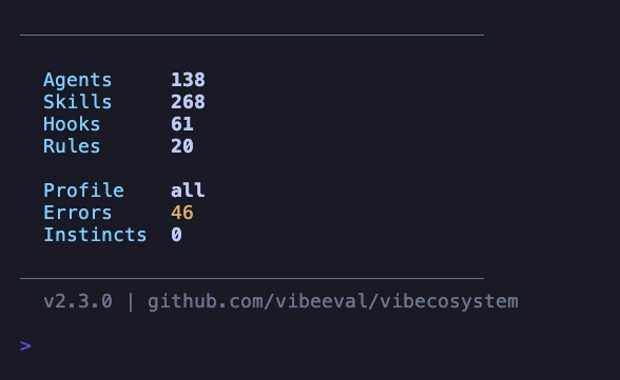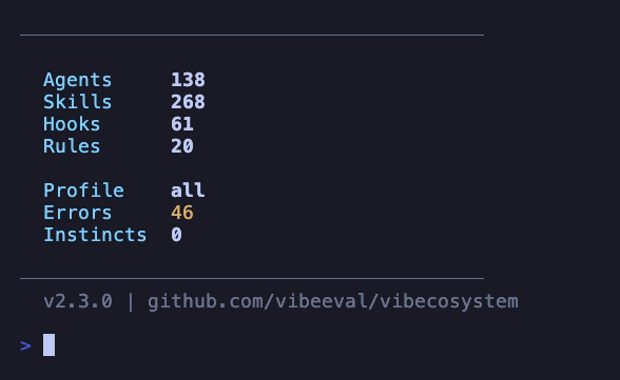
vibeco stats                          # ecosystem statistics
vibeco list agents --search security  # browse components
vibeco profile frontend               # switch profile (saves tokens)
vibeco doctor                         # health check
vibeco dashboard                      # start monitoring UI
vibeco update                         # pull latest & reinstall
vibeco effective-config               # show model, worker, profile and budgets
Profiles
Save tokens by loading only what you need:
| Profile | Agents | Skills | Use case |
|---|
core | 12 | 32 | Bounded implementation and verification (default) |
quality | 12 | 32 | Core + focused edit and verification checks |
context | 12 | 32 | Core + targeted context retrieval |
memory | 13 | 36 | Core + opt-in memory and learning hooks |
orchestration | 14 | 35 | Core + explicit multi-agent workflows |
minimal | 12 | 32 | Alias for core |
frontend | ~30 | ~60 | React/Next.js/CSS/a11y |
backend | ~44 | ~74 | API/DB/security |
fullstack | ~59 | ~96 | Frontend + Backend |
devops | ~33 | ~61 | CI/CD/K8s/cloud |
full | 138 | 296 | All legacy capabilities; 8k/event and 50k/session context budget |
smart | 12 | 32 | Alias for core |
all | 138 | 296 | Alias for full |
The lean profiles change the active component set and context budget, not the model. core uses 4,000 characters per event and 12,000 per session; full preserves the legacy 8,000/50,000 limits. Memory and orchestration are opt-in so a normal task does not trigger recall, swarm, or cross-agent chains.
vibeco profile core       # bounded default
vibeco profile full       # back to every legacy capability
How It Works
YOU SAY SOMETHING                VIBECOSYSTEM ACTIVATES              RESULT
┌──────────────┐                 ┌──────────────────────┐            ┌──────────┐
│ "add a new   │──→ Intent ──→  │ Phase 1: scout +     │──→ Code   │ Feature  │
│  feature"    │   Classifier   │   architect plan     │   Written │ built,   │
│              │                 │ Phase 2: backend-dev │   Tested  │ reviewed,│
│              │                 │   + frontend-dev     │   Reviewed│ tested,  │
│              │                 │ Phase 3: code-review │           │ merged   │
│              │                 │   + security-review  │           │          │
│              │                 │ Phase 4: verifier    │           │          │
│              │                 │ Phase 5: self-learner│           │          │
└──────────────┘                 └──────────────────────┘            └──────────┘
Hooks are sensors — they observe every tool call and inject relevant context:
"fix the bug"       → compiler-in-loop + error-broadcast      ~2,400 tok
"add api endpoint"  → edit-context + signature-helper + arch   ~3,100 tok
"explain this code" → (nothing extra)                          ~800 tok
Agents are muscles — each one specialized for a specific job:
GraphQL API      → graphql-expert   (backup: backend-dev)
Kubernetes       → kubernetes-expert (backup: devops)
DDD modeling     → ddd-expert       (backup: architect)
Bug reproduction → replay           (backup: sleuth)
... 70 more routing rules
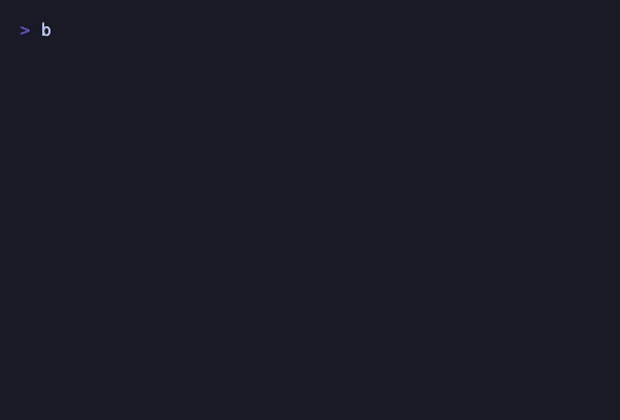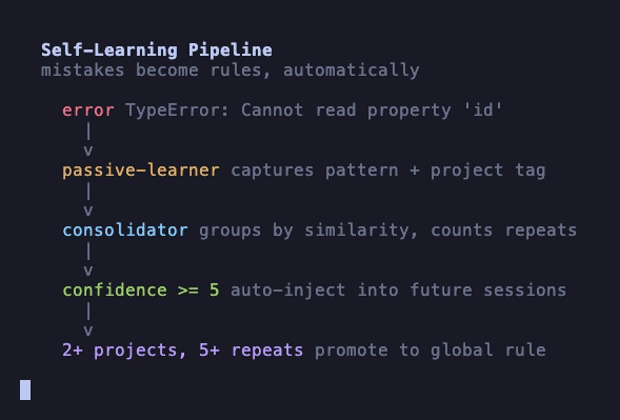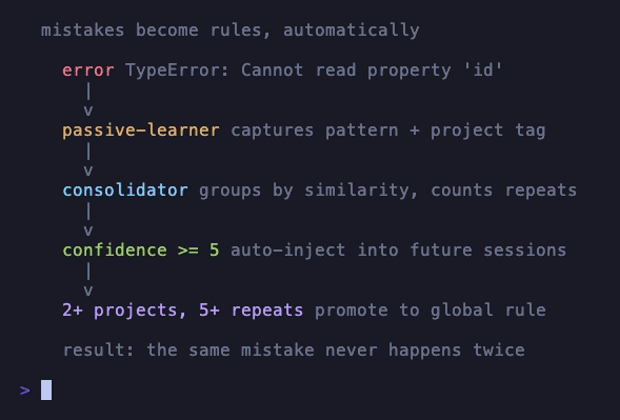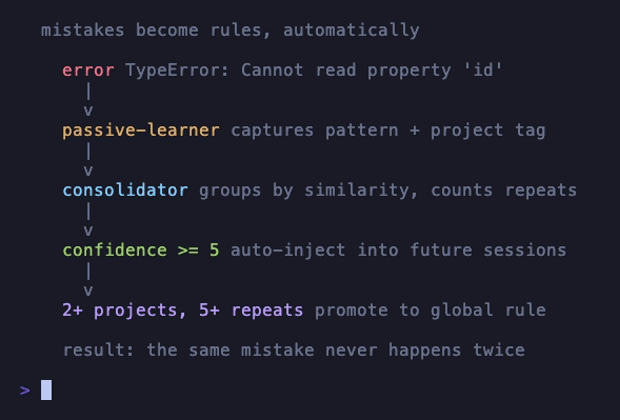
Self-Learning Pipeline turns mistakes into permanent knowledge:
Error happens → passive-learner captures pattern (+ project tag)
→ consolidator groups & counts (per-project + global)
→ confidence >= 5 → auto-inject into context
→ 2+ projects, 5+ total → cross-project promotion
→ 10x repeat → permanent .md rule file
No manual intervention. The system writes its own rules — and shares them across projects.
What's New in v2.0
- SAST Security Scanner — static analysis agent + hook for automated vulnerability detection
- Agent Monitoring Dashboard — real-time web UI for agent activity and performance
- MCP Auto-Discovery — automatic MCP server recommendations based on project type
- Changelog Automation — automatic changelog generation at session end
- Compliance Skills — SOC2, GDPR, HIPAA compliance checking
- Product & Marketing Skills — PRD writer, analytics setup, growth playbooks
- GitHub Actions CI/CD — automated PR review + issue fix workflows
- Mutation Testing — test quality measurement via mutation analysis
- Code Knowledge Graph — codebase structure analysis with graph-analyst
Core Features
Agent Swarm
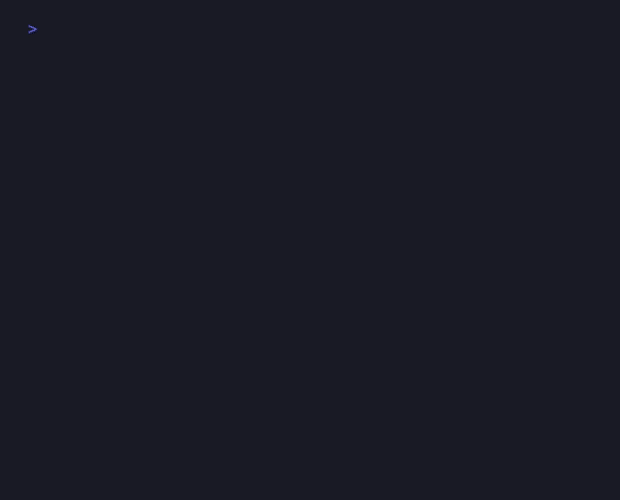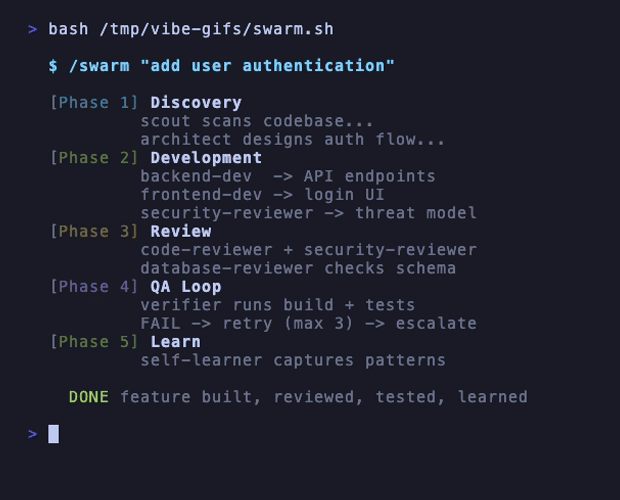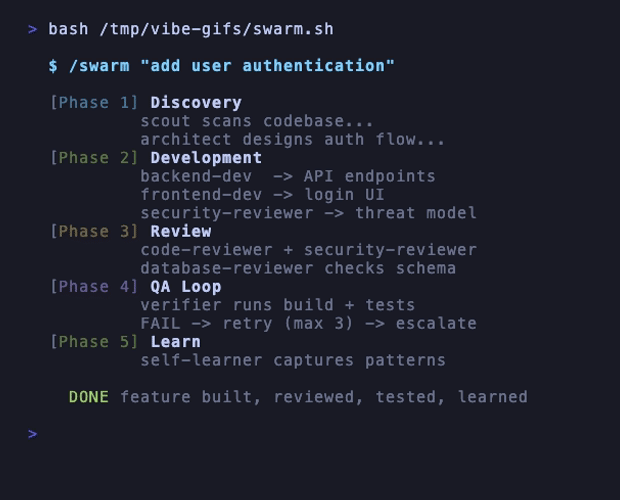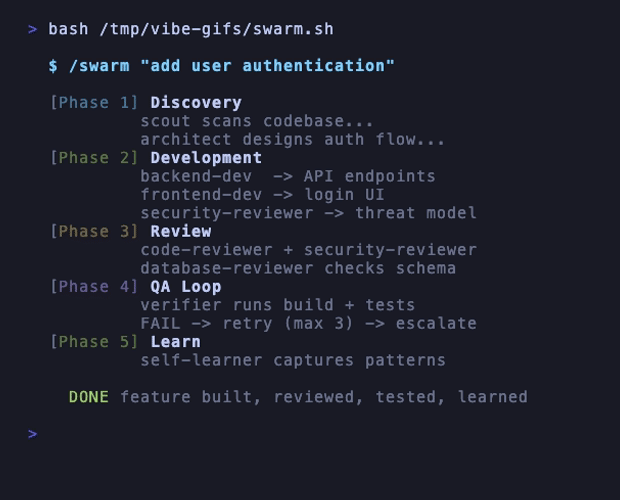
Say "add a new feature" and 20+ agents activate across 5 phases.
Phase 1 (Discovery):    scout + architect + project-manager
Phase 2 (Development):  backend-dev + frontend-dev + devops + specialists
Phase 3 (Review):       code-reviewer + security-reviewer + qa-engineer
Phase 4 (QA Loop):      verifier + tdd-guide (max 3 retry → escalate)
Phase 5 (Final):        self-learner + technical-writer
Self-Learning Pipeline
Every error becomes a rule. Automatically.
Dev-QA Loop
Every task goes through a quality gate:
Developer implements → code-reviewer + verifier check
→ PASS → next task
→ FAIL → feedback to developer, retry (max 3)
→ 3x FAIL → escalate (reassign / decompose / defer)
Cross-Project Learning
Patterns learned in one project automatically benefit all your projects.
Project A: add-error-handling (3x) ─┐
                                     ├→ 2+ projects, 5+ total → GLOBAL
Project B: add-error-handling (4x) ─┘
                                     ↓
Next session in ANY project → "add-error-handling" injected as global pattern
Each project gets its own pattern store. When the same pattern appears in 2+ projects with 5+ total occurrences, it's promoted to a global pattern that benefits every project — even brand new ones.
node ~/.claude/hooks/dist/instinct-cli.mjs portfolio      # All projects
node ~/.claude/hooks/dist/instinct-cli.mjs global          # Global patterns
node ~/.claude/hooks/dist/instinct-cli.mjs project <name>  # Project detail
node ~/.claude/hooks/dist/instinct-cli.mjs stats           # Statistics


 @obra


