

Your real coding-agent sessions already contain the rules you never wrote down: what “done” means, what you reject on sight, how you debug, how you design UI, and how you write when you are actually working.
Emulo mines selected evidence from those sessions (Claude Code, Codex, Copilot CLI, OpenCode, and Google Antigravity logs out of the box) into a private working profile, where every rule carries dated quotes from your own messages, and installs it where your agent can read it. The agent mining flow writes separate files for work, design, writing, and video, so a host can load only the one that fits the task.
The aim is an agent that works the way you do from the first message. That is an aim, not a result: what is tested so far is below, including the part that did not go our way.
Installing a profile and an agent actually reading it are two different things. In a host-by-host test on 2026-09-25, the profile reached the model through a project AGENTS.md in Codex (--target agents --repo ., verified end to end in one test) and was loaded into OpenCode's instructions. In Claude Code the you skill installs but is not reliably opened on its own; typing /you loads it. Cursor, Gemini, OpenClaw and Hermes Agent get the file where they look for it, and loading there is not verified. The support matrix has each one.
The Emulo Proof v1 methodology is an unexecuted methodology until a separately approved evidence release exists.
The video layer, and where it comes from
A spec commercial, made in Claude Design. No After Effects and no motion software:
the whole thing is a composition rendered out to video.
It is spec work. It was not commissioned by Vercel and it was not made for
them. A brand was picked to see how far the motion could go.
It is here because emulo:video is mined from sessions like the one that
produced it. The other layers work the same way: the profile is not a template,
it is what survived from real work.
Install
Inside Claude Code:
/plugin marketplace add ohad6k/emulo
/plugin install emulo@emulo
Inside Codex:
codex plugin marketplace add ohad6k/emulo --ref v0.6.7 --json
codex plugin add emulo@emulo --json
Then run emulo:mine and point it at your session history. Everything below explains what that produces and why. If you want the CLI instead of the plugin, see Quickstart.
Open source and privacy
Emulo is MIT licensed, free, and works without an account or a sign-in. The tool
itself has nothing to buy. Separately, the site
offers one optional paid service, a hand edit of a profile you already mined, and
you never need it to use Emulo.
Session extraction, redaction, caches, the profile itself, and the agent
adapters all stay on your machine. The one exception is mining: if you point it
at a hosted model, the selected evidence goes to that provider. Point it at a
local model and the whole run stays on your machine.
Not memory
Memory is what you explicitly told the model.
Emulo mines what keeps coming up in your own sessions: what you reject, what "done" means, when you ask for proof, how you talk when you're actually working, and the agent behaviors that make you stop the task.
That's why it reads raw session logs, not your CLAUDE.md or rules file.
What is tested so far
Emulo does three separate things, and they are held to different standards:
- The usage report and
emulo verify are text matches on your own messages. They count and they trace quotes. They cannot tell you why anything happened.
- Loading means a host puts the profile in front of its model. Which hosts were seen doing that is in the support matrix.
- Whether a loaded profile makes the agent's work better is not shown. It is the aim, not a result.
What the published tests do show:
- An appended mined profile changed what the model produced, compared with no profile.
- In a 60 run study with every prediction written down in advance (August 2026), the mined profile did not separate from an invented profile of the same length on any of 9 comparisons. emulo.vercel.app/placebo
- In a September 2026 rerun with a later July 2026 profile (dated 2026-07-30) and a new invented profile, the mined profile separated from the invented one on 5 of 9 comparisons on Fable 5.1 and on 1 of 9 on Opus 5. emulo.vercel.app/fable
- Both tests measure whether the output changed (rounded corners, colour saturation, card containers, length), not whether it got better.
One example, not a test
An anecdote. One line to the same agent, twice: "help me post emulo on reddit." Once cold, once with the Emulo profile loaded. One run each way, with no control and no placebo, so it shows what two replies looked like, not what the profile does. Both replies are trimmed to their opening plan and title.
Here's how I'd play it.
Subreddits: r/ClaudeAI and r/ChatGPTCoding are your core audience. r/LocalLLaMA fits the local angle. r/cursor, r/SideProject, r/opensource for reach. Don't blast all at once — post to one, tune the title, repost over a few days.
Title: I built a local tool that reads your AI coding logs and writes a "you.md" your agents read before every task
the insight first: the mining number is your whole post. "i read 1,656 of my own sessions" is a confession, not a pitch, and nobody scrolls past a confession. lead with the mirror, not the mechanism.
one sub, not five — a skills sub, where people come looking for this instead of arguing about it.
Title: I built a Claude skill from 8 months of my own Claude Code sessions
The title is the agent's wording. The profile loaded was a profile the author mined in early July 2026 (1,656 sessions).
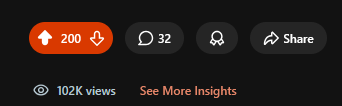
I posted the loaded version on r/ClaudeSkills. The numbers below are as shown in the screenshot, which shows the vote bar only, not the post or the date:
The controlled tests are at emulo.vercel.app/placebo and emulo.vercel.app/fable, summed up in What is tested so far.
What it finds
The kind of rules a mine pulls out, each backed by dated verbatim receipts from real sessions:
done means it runs live. never trust "done" off a code edit. show it working first.
fix the one thing. rewriting or "cleaning up" code that isn't the problem gets rejected every time.
builds faster than they understand what they built — then asks the agent to explain their own system back.
gets frustrated by repeating the same ask until it lands, not by escalating.
Nobody wrote those rules down. They came out of one person's own history, with receipts.
This is an example. Yours is mined from your logs and will read nothing like it.
The usage report
Mining answers "who is this person." The usage report answers a different question: where you keep repeating yourself to the model.
python emulo.py --coach                   # every source it can find
python emulo.py --coach --source claude   # Claude Code only
Or let your agent run it when you complain that it keeps forgetting how you work: npx skills add ohad6k/emulo@agent-profile-from-sessions installs a skill that starts with this free report and only offers mining after you see the evidence.
It runs before any mining and makes no model call. On a big history it takes about a minute: roughly 1,400 sessions took 54 to 71 s across three runs on one Windows machine.
Every check is a text match on your own messages. It counts asks you sent three or more times in a row unchanged, messages with a phrase like "as I said" or "I told you", runs of near-identical asks in a row, and how often a message opens like a correction ("no,", "that's wrong"). A phrase inside quoted or pasted text (a fenced code block, a line starting with >, or a double-quoted span) is not counted, so an email you are answering does not read as you repeating yourself. A match cannot tell why you repeated something or whether the agent had forgotten anything, so the report offers fixes as possibilities, not diagnoses.
Every finding prints the dated messages behind it, so you can judge each one yourself. Checks that come in under their bar are printed with their counts as well, so a clean result reads as a result rather than as silence.
It reads only the messages you typed, which is all Emulo keeps. It cannot see cost, tokens, tool calls, or whether the agent was right, and it never scores those.
The card
The agent mining flow (run emulo or emulo:mine) also writes a card.json, and emulo --card <card_path> renders it as a shareable card: archetype, top laws ranked by distinct supporting session receipts, coverage stats, and one sharp truth. emulo plugin status prints the card_path. The RUN_ME.md path writes you.md only, so it has no card to render.
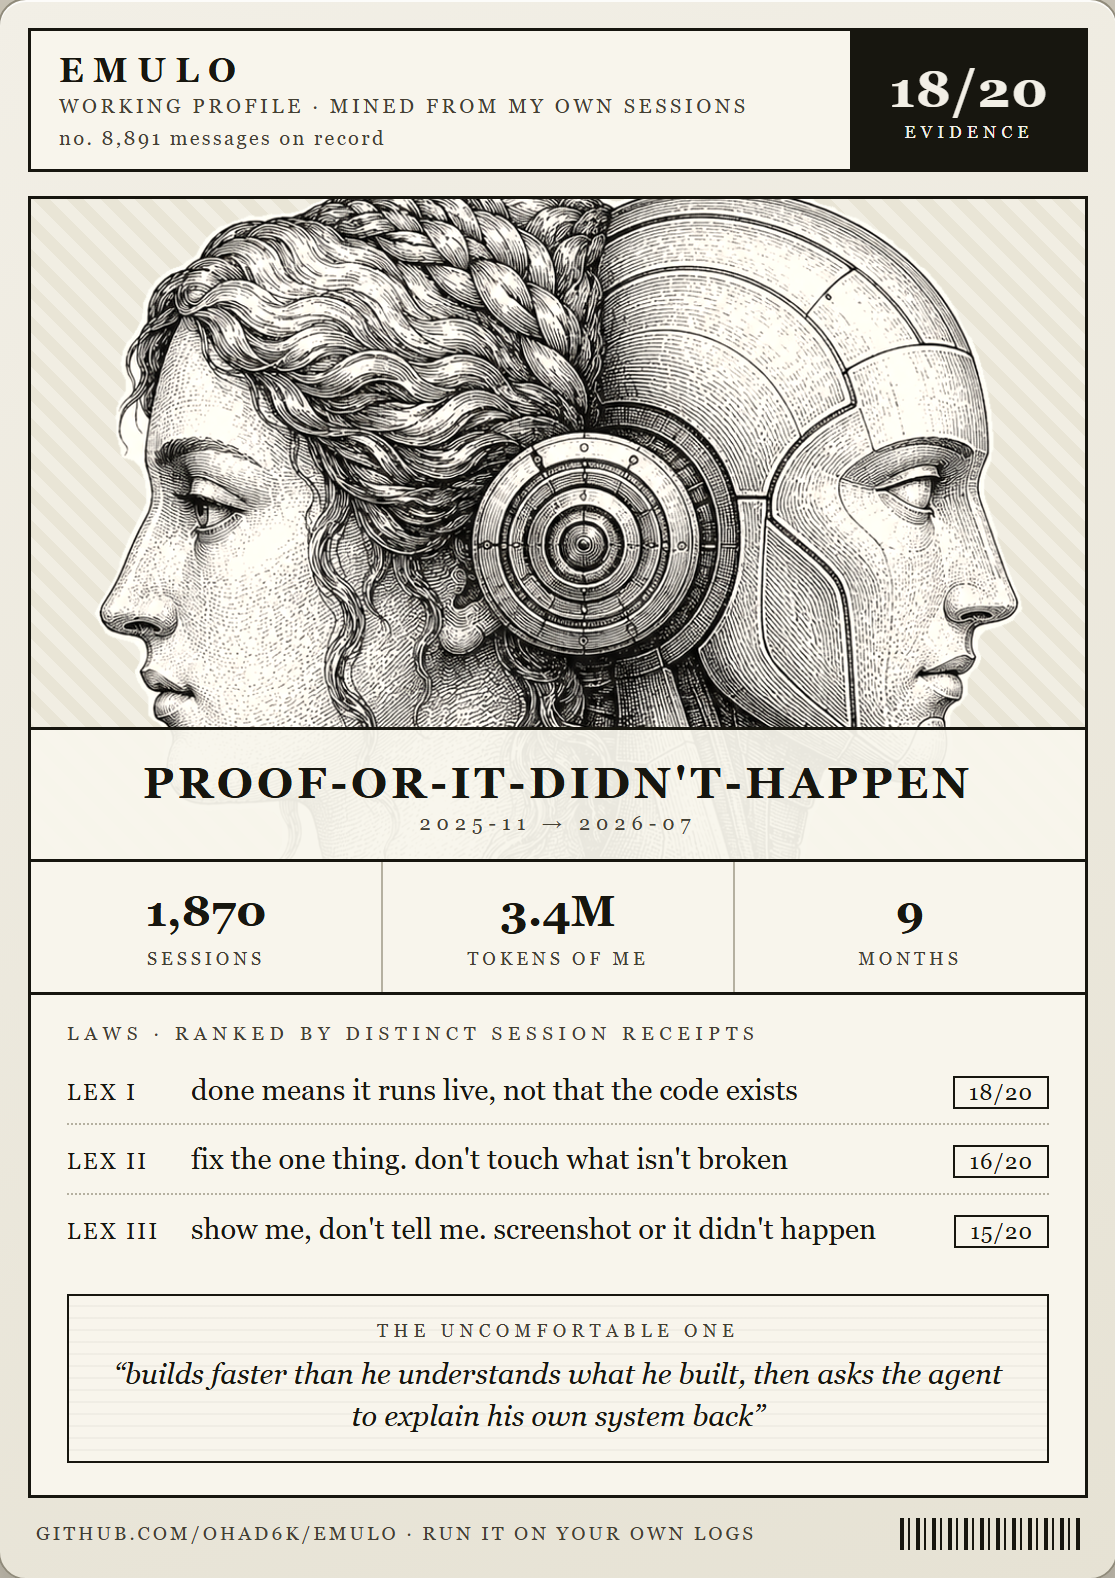
Share the card or one short trait, never your full profile.
Quickstart
Step by step, with what each command reads and writes, what reaches a model, and how to remove it: docs/PROFILE-FLOW.md.
Install the cross-agent bootstrap. It runs the mining flow in Claude Code and Codex:
npx skills add ohad6k/emulo@emulo
Then tell your agent:
run emulo


 @mattpocock


