
An OpenAI-compatible proxy that builds a knowledge graph of your
session — decisions, files, errors, goals — and replays it when the
context window runs out. Not a summary: a queryable graph that knows
"we switched from MongoDB to PostgreSQL, and here is why."
One line to adopt · works with Claude, GPT, Gemini, Grok, DeepSeek, Mistral, Cohere, Ollama · MIT




Quick start ·
See it ·
Claude Code & MCP ·
Benchmarks ·
Architecture ·
Roadmap
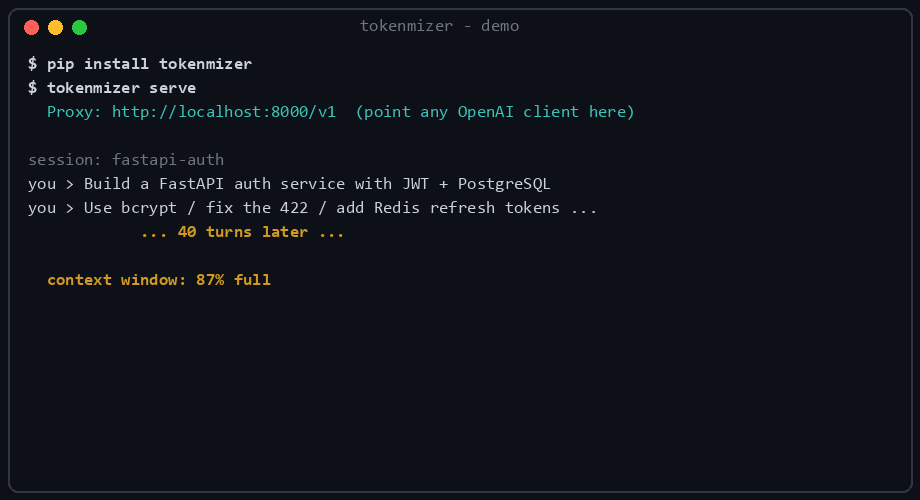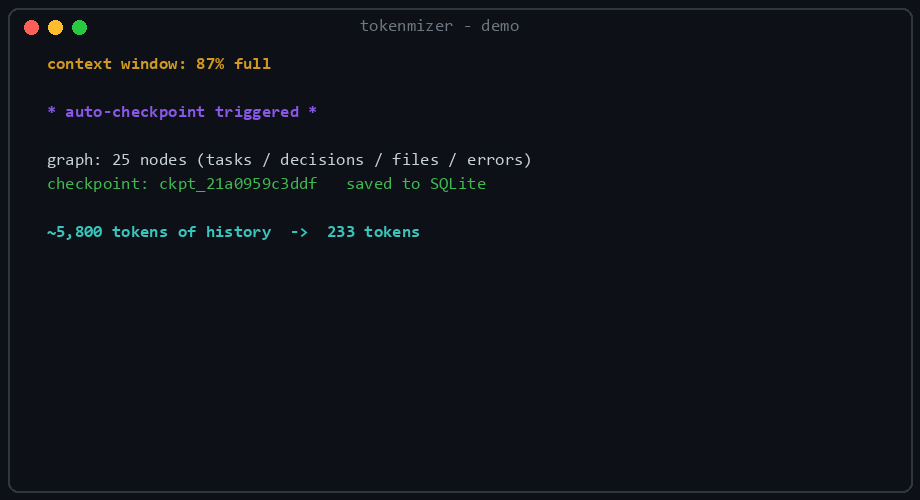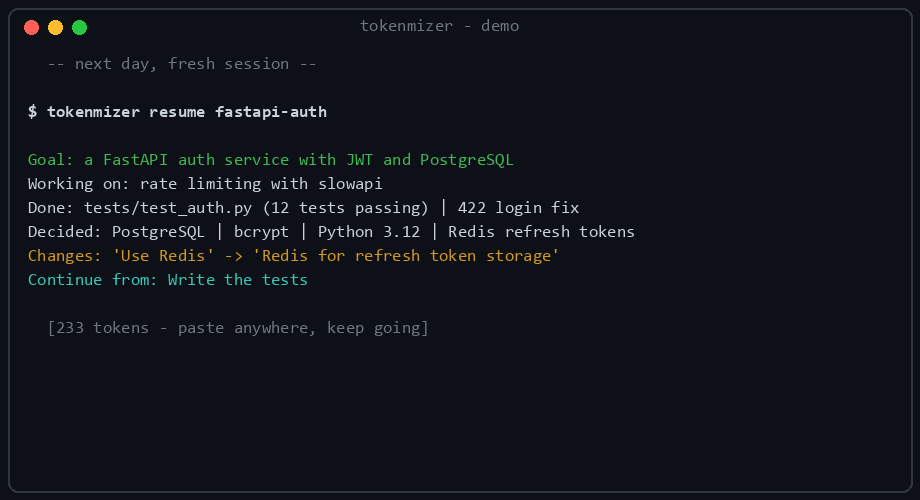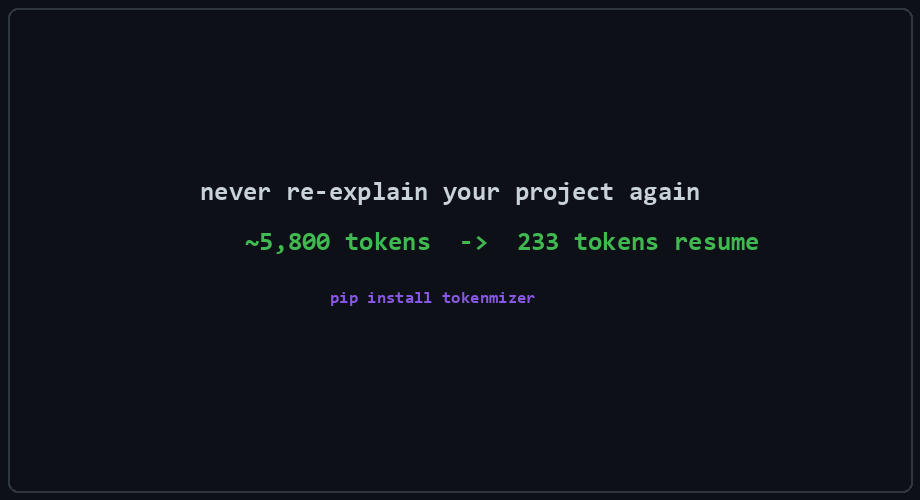
Real run: 25-node graph, checkpoint ckpt_21a0959c3ddf, 233-token resume. Regenerate with python scripts/gen_demo_gif.py.
The problem
Every AI session has a context limit. When you hit it, the model forgets
every decision and every rationale built over hours of work, and you
spend the first ten minutes of the next session re-explaining the
project.
Summarising the history does not fix this. A summary tells you what
was decided; it loses why, and it loses what was rejected — so the
model happily re-proposes the thing you moved off three sessions ago.
Quick start
pip install "tokenmizer[anthropic,cache]"
export TOKENMIZER_ANTHROPIC_API_KEY=sk-ant-...
tokenmizer serve
Then change one line in your client:
from openai import OpenAI

client = OpenAI(
    api_key="your-key",
    base_url="http://localhost:8000/v1",   # only this changes
)

resp = client.chat.completions.create(
    model="claude-sonnet-4-6",
    messages=[{"role": "user", "content": "Continue where we left off"}],
    extra_body={"session_id": "my-project"},   # optional, enables memory
)
Everything else is unchanged: same request shape, same response shape,
plus a tokenmizer block reporting what was saved. Open
http://localhost:8000 and the session is already there.
Windows, Ollama, Docker, and the full step-by-step
Windows (PowerShell)
$env:TOKENMIZER_ANTHROPIC_API_KEY = "sk-ant-..."   # this session
setx TOKENMIZER_ANTHROPIC_API_KEY "sk-ant-..."     # persistent
No API key? Ollama runs locally and free:
ollama pull llama3
pip install tokenmizer
# then set `provider: ollama` in tokenmizer.yaml
Docker
docker compose up -d
Full installation notes, every provider's environment variable, and the
configuration reference are in
docs/configuration.md and
docs/deployment.md.
See it
Nothing here is a mockup. Every screenshot and the demo below are the
shipped UI rendering a session from the labelled corpus in
benchmarks/eval/corpus.
The session graph is a page you drive, not a picture
Radial → select a node → force → filter a type → timeline → light. Regenerate with python scripts/gen_graph_demo.py.
Select a node and you get its type, status, community, importance,
confidence, when it was first seen and every relation it carries — the
provenance behind a fact, not just the fact. Filter a type or a community
and the counts move with it. Three layouts, a light theme and a PNG
export are one click each.
It is one self-contained HTML file with no external requests, so it
opens offline, works from a file:// URL, and can be sent to someone who
has never installed TokenMizer.
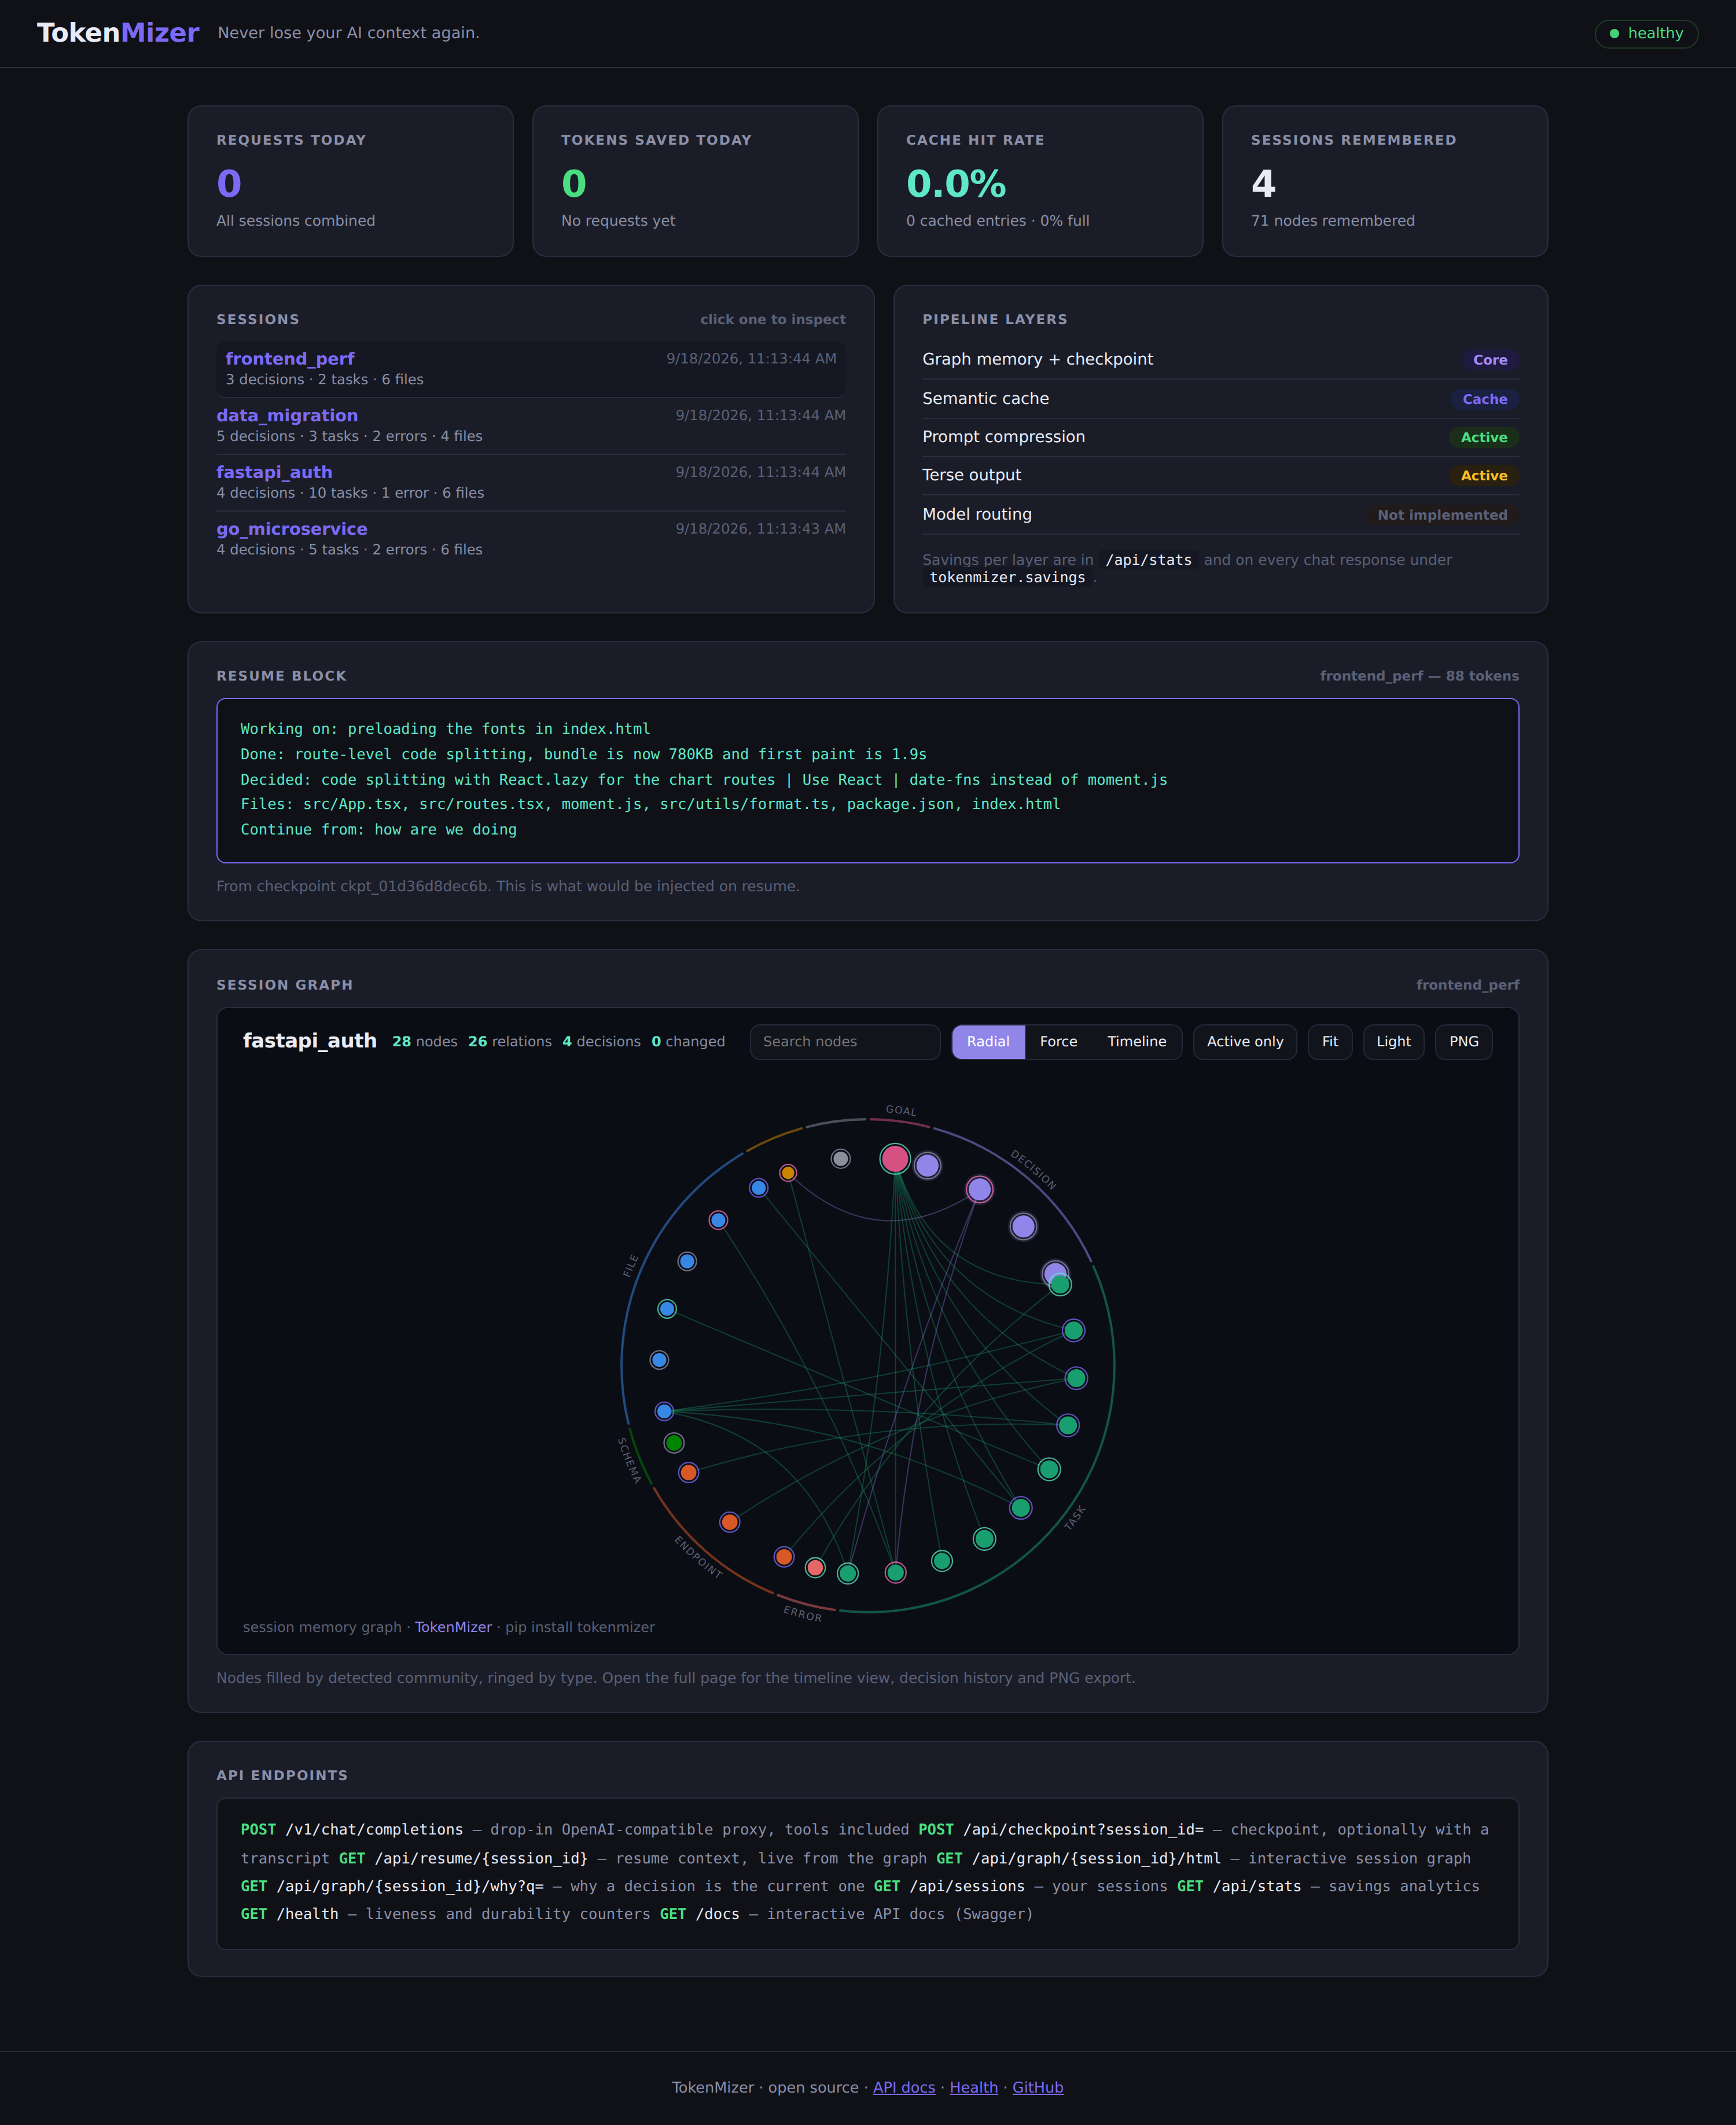
The dashboard tells you what it actually knows
Your sessions, the live resume block each one would inject right now, and
its graph — not an example of one. The health pill reads /health, which
reports degraded with the counters behind it when a write has failed,
rather than saying ok whatever happened.
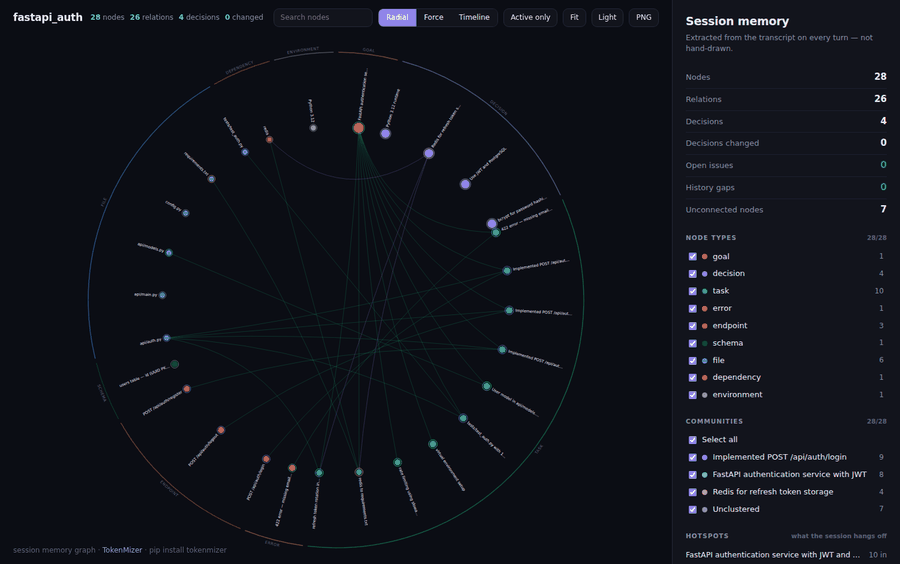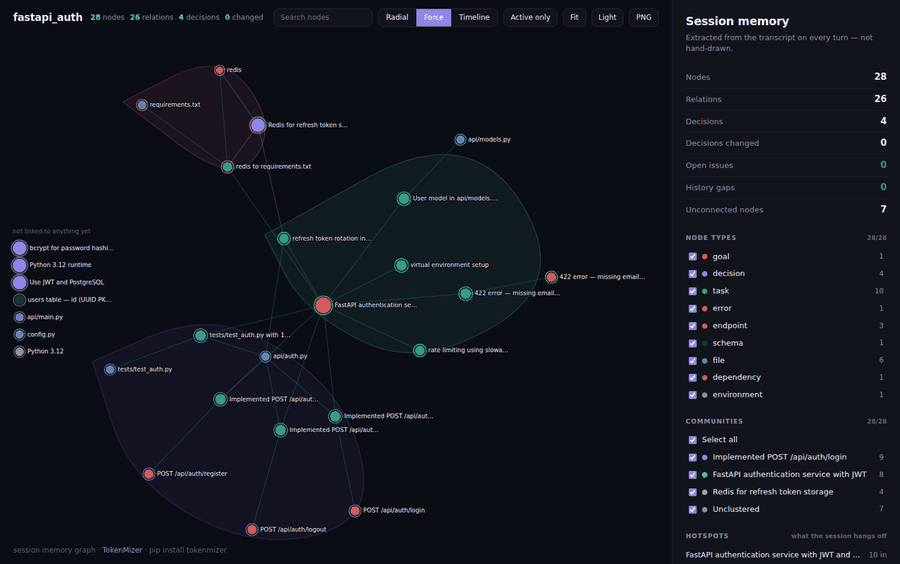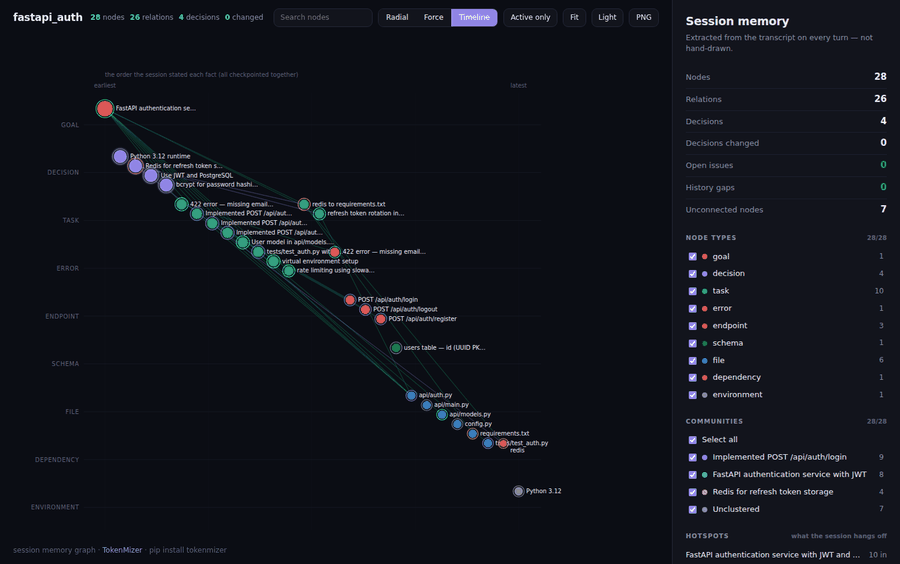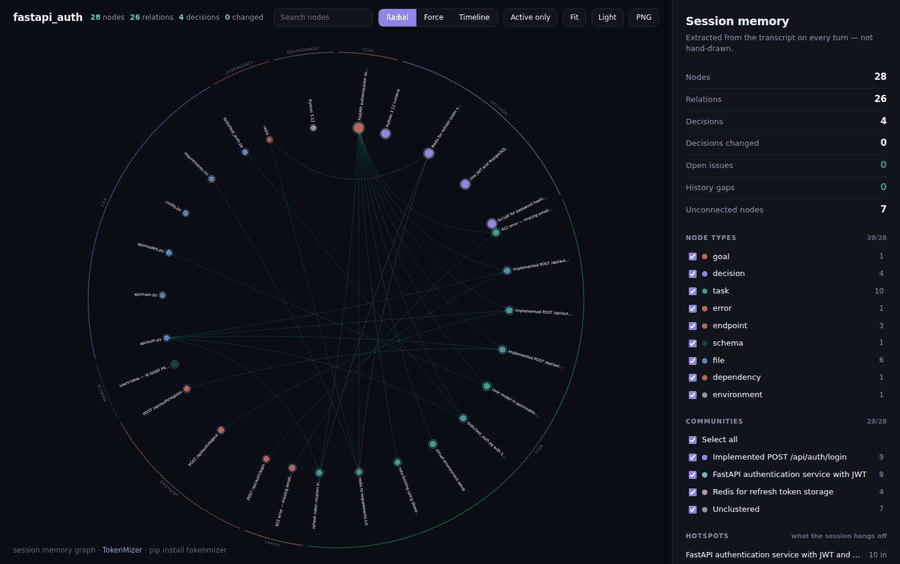
The session graph, grouped the way you would group it
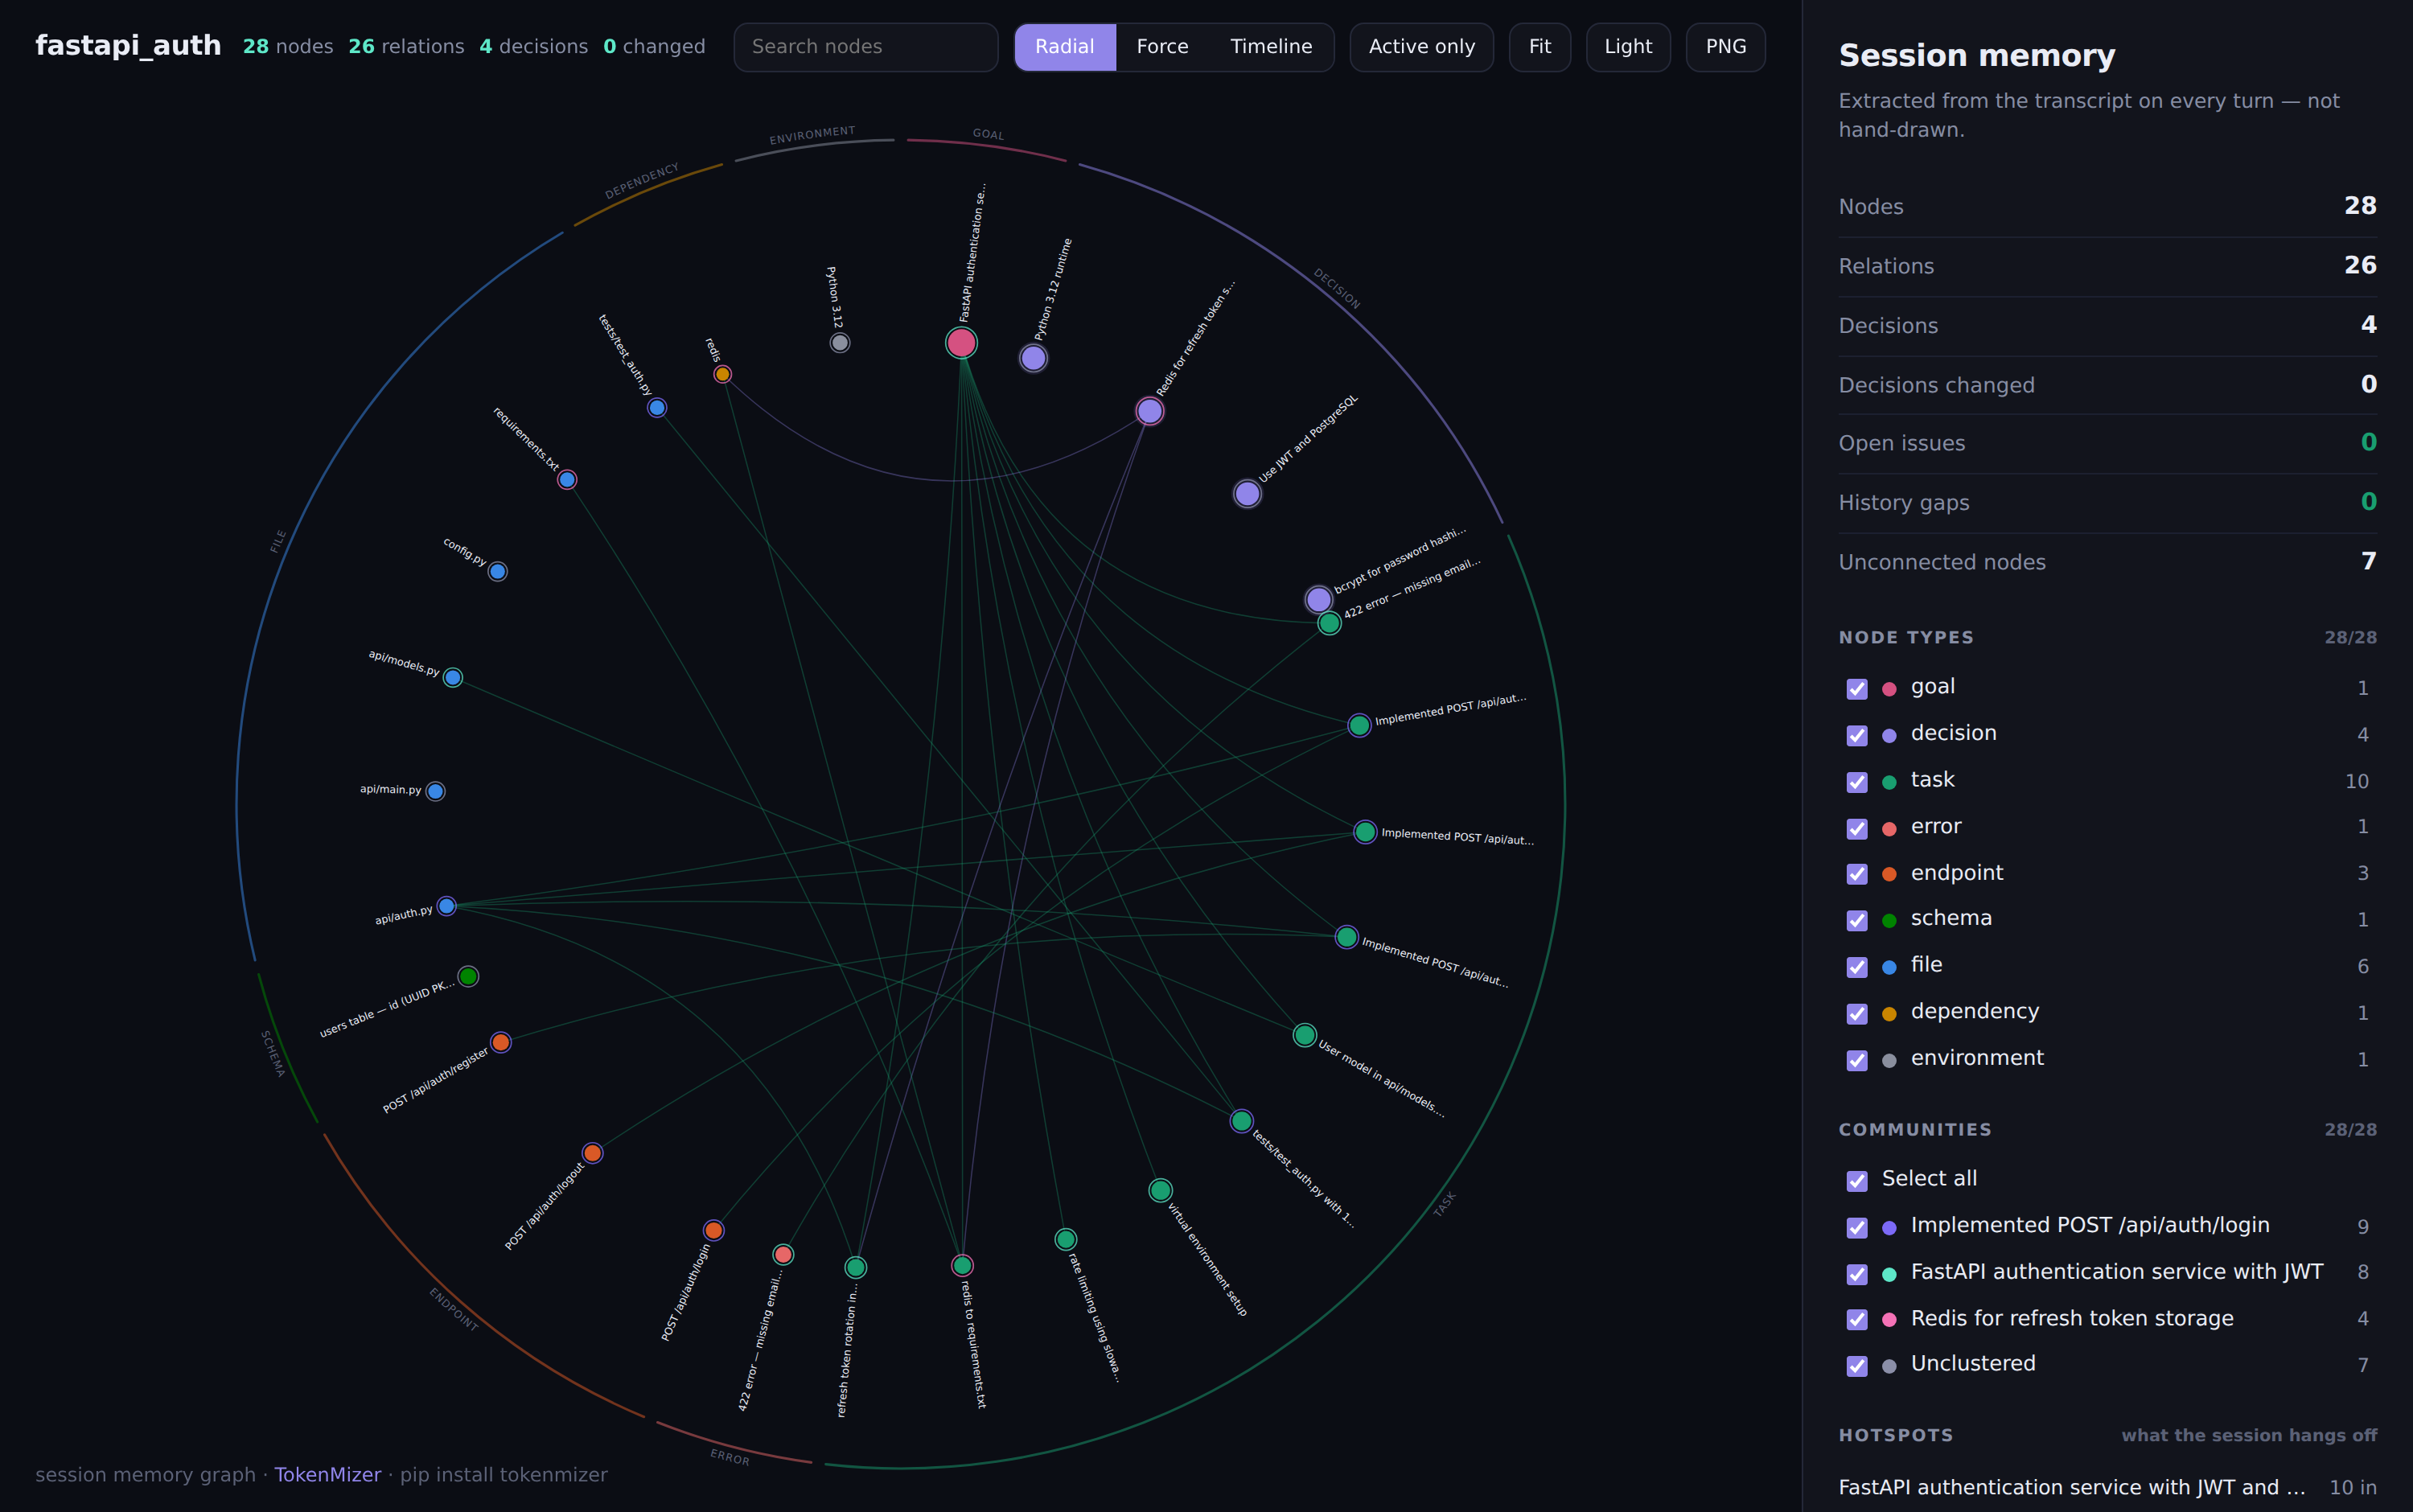
Each node type gets its own arc of the circle, named on the ring, and
relations are drawn as chords bowed through the middle — so the shape of
the session is readable before you read a single label, and which type a
node is comes from where it sits, not from telling two hues apart. The
palette is checked with a validator, not by eye: every adjacent pair
clears the colour-blind separation floor, and the four types that carry
no meaning of their own share one neutral grey.
The panel beside it counts what the session knows and what is missing —
open issues, decisions changed, history gaps, unconnected nodes — then
lists the detected communities, the hotspots everything hangs off, and
which kinds of node point at which. Filter by type or community, search,
click a node for the supersession chain behind it.
The same session as a story
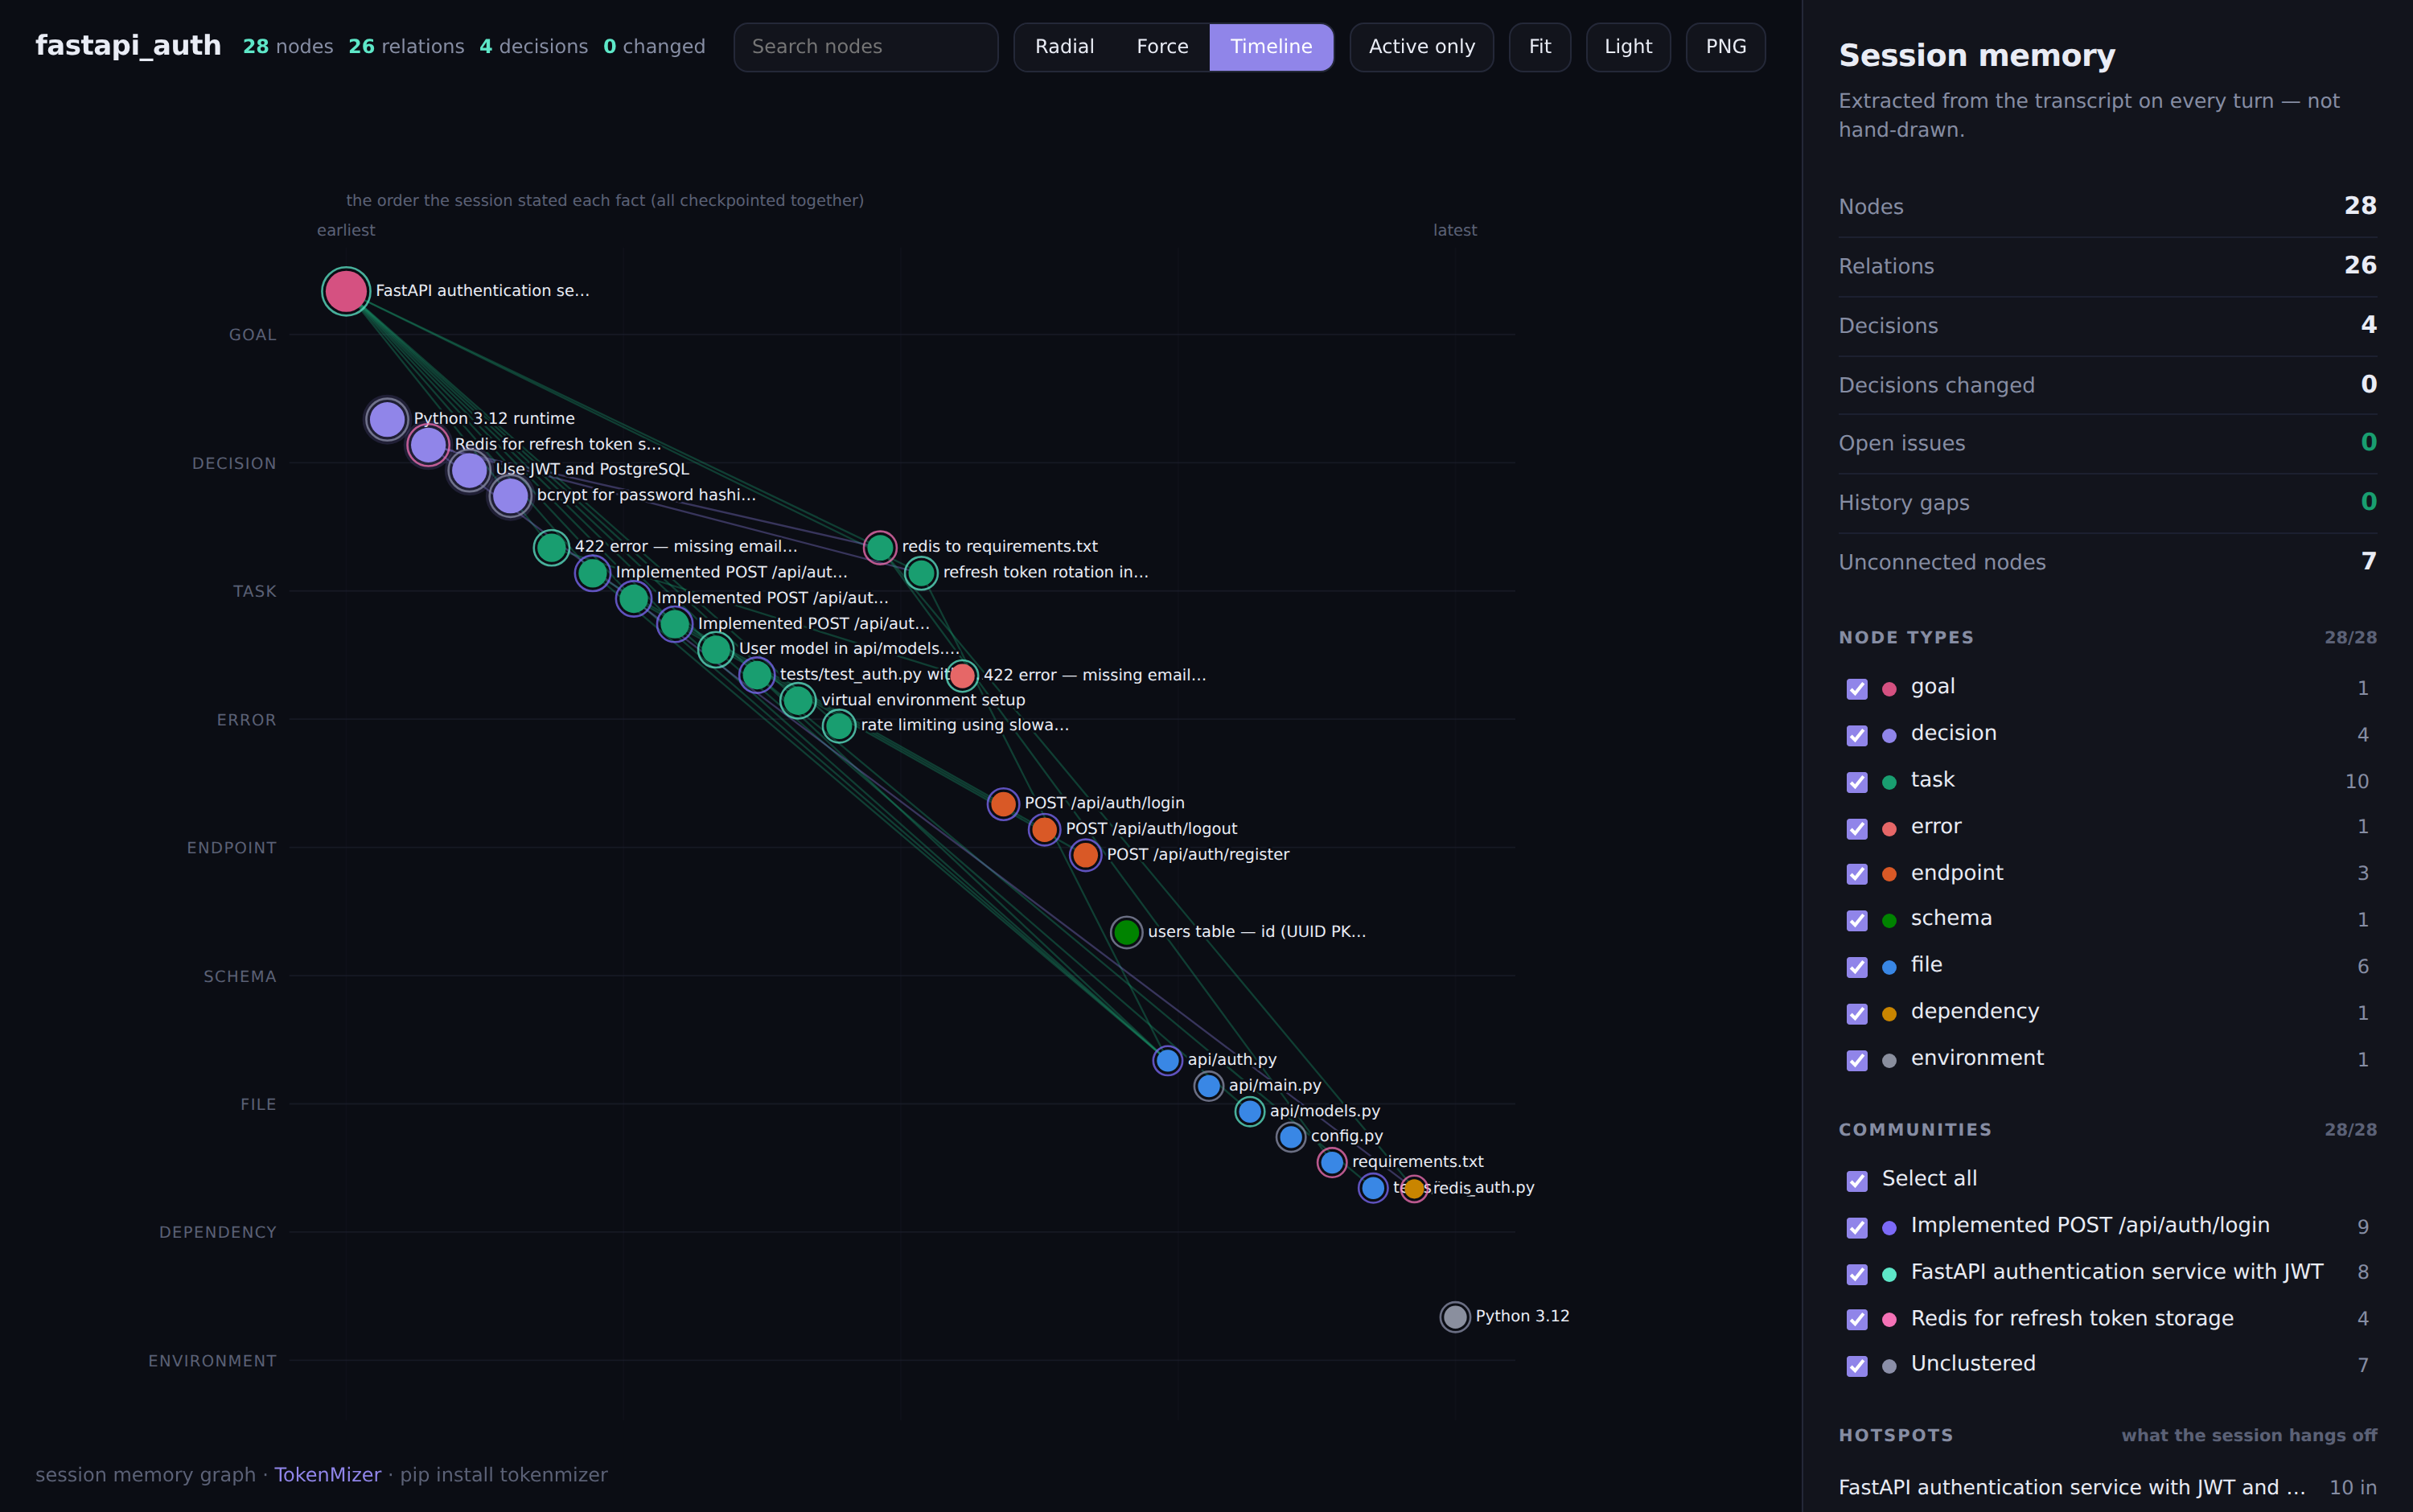
Timeline mode puts each node type in its own lane, ordered by when the
fact entered the session, with supersessions drawn as arcs. When a whole
transcript was checkpointed in one call every node shares a timestamp, so
the axis says so and falls back to the order the session stated things
rather than inventing dates.
How it works
TokenMizer is a local proxy between your app and any LLM. Every request
passes through a pipeline that builds a live knowledge graph, compresses
inputs, caches responses, and checkpoints before the context runs out.
flowchart LR
    App["Your app<br/><sub>OpenAI-compatible client</sub>"]
    subgraph TM["TokenMizer :8000"]
        direction TB
        L0["<b>L0</b> File intelligence"]
        L1["<b>L1</b> Prompt compression"]
        L2["<b>L2</b> Terse-output injection"]
        L4["<b>L4</b> Graph memory<br/><sub>extract to window to inject</sub>"]
        L3["<b>L3</b> Semantic cache"]
        L5["<b>L5</b> Provider prompt cache"]
        L0 --> L1 --> L2 --> L4 --> L3 --> L5
    end
    LLM["Claude · GPT · Gemini<br/>Grok · DeepSeek · Ollama"]
    DB[("SQLite<br/><sub>graph · checkpoints · ownership</sub>")]

    App -->|"POST /v1/chat/completions"| TM
    TM --> LLM
    LLM -.->|response| TM
    TM -.->|"response + savings"| App
    L4 <-->|"per-row, locked"| DB
The graph is not a summary. It is typed nodes and edges — decisions,
tasks, files, errors, goals — with a lifecycle, so a decision that gets
replaced is marked superseded rather than deleted, and the transition
records what triggered it. The resume block is a filtered projection of
it: active decisions, open work, unresolved errors, in a few hundred
tokens.
Edges carry the relations a session actually has. A task that fixed a bug
FIXES the error node and closes it. An open error BLOCKS the task
about it. A decision DEPENDS_ON the package it named. That is what the
communities above are detected from, and what /why walks.
To Architecture — the request sequence, the
data model, and the decision lifecycle.
What a resume looks like
Goal: FastAPI authentication service with JWT and PostgreSQL
Working on: refresh token rotation in api/auth.py | rate limiting using slowapi
Done: Implemented POST /api/auth/login | Fixed the 422 in LoginRequest | User model in api/models.py
Decided: Use JWT and PostgreSQL | bcrypt for password hashing | Redis for refresh token storage
Changes: 'Use moment.js' -> 'Use date-fns' - tree-shakeable, saves 230KB
Files: api/auth.py, api/models.py, config.py, tests/test_auth.py
Continue from: Add rate limiting to auth endpoints
A few hundred tokens in place of the whole conversation. The Changes:
line is the part a summary loses — and
GET /api/graph/{session_id}/why?q=date-fns replays the full chain with
the trigger, the reason and the evidence for each hop.
Habits, not just projects
A session graph remembers what you decided about this project. It does
not remember that you want short answers — that is true of you, not of
the repository, and it has to survive starting a session somewhere else.
preferences:
  enabled: true      # off by default; read the note before turning it on
With it on, a turn like "I prefer TypeScript, and keep answers brief" is
remembered per principal and injected as a few lines of system prompt.
/api/preferences (GET) shows exactly what was remembered and the exact
text it injects; the same path with DELETE and ?key=... forgets one,
without a key forgets all of them.


 @obra


