







vnsh
Securely share local files through encrypted, expiring links. Upload a file to get a protected link, or open a link to decrypt and read its content.
1 skill158
 @raullenchai
Rapid-MLX is an open-source LLM inference server for Apple Silicon, built on MLX. It offers OpenAI- and Anthropic-compatible APIs with reliable tool calling for coding agents.
Claude Code
$ npx -y skills add raullenchai/Rapid-MLX --agent claude-code
Codex
$ npx skills add raullenchai/Rapid-MLX -a codex
Cursor
$ npx skills add raullenchai/Rapid-MLX -a cursor
Gemini CLI
$ npx skills add raullenchai/Rapid-MLX -a gemini-cli
GitHub Copilot
$ npx skills add raullenchai/Rapid-MLX -a github-copilot
OpenCode
$ npx skills add raullenchai/Rapid-MLX -a opencode
Windsurf
$ npx skills add raullenchai/Rapid-MLX -a windsurf
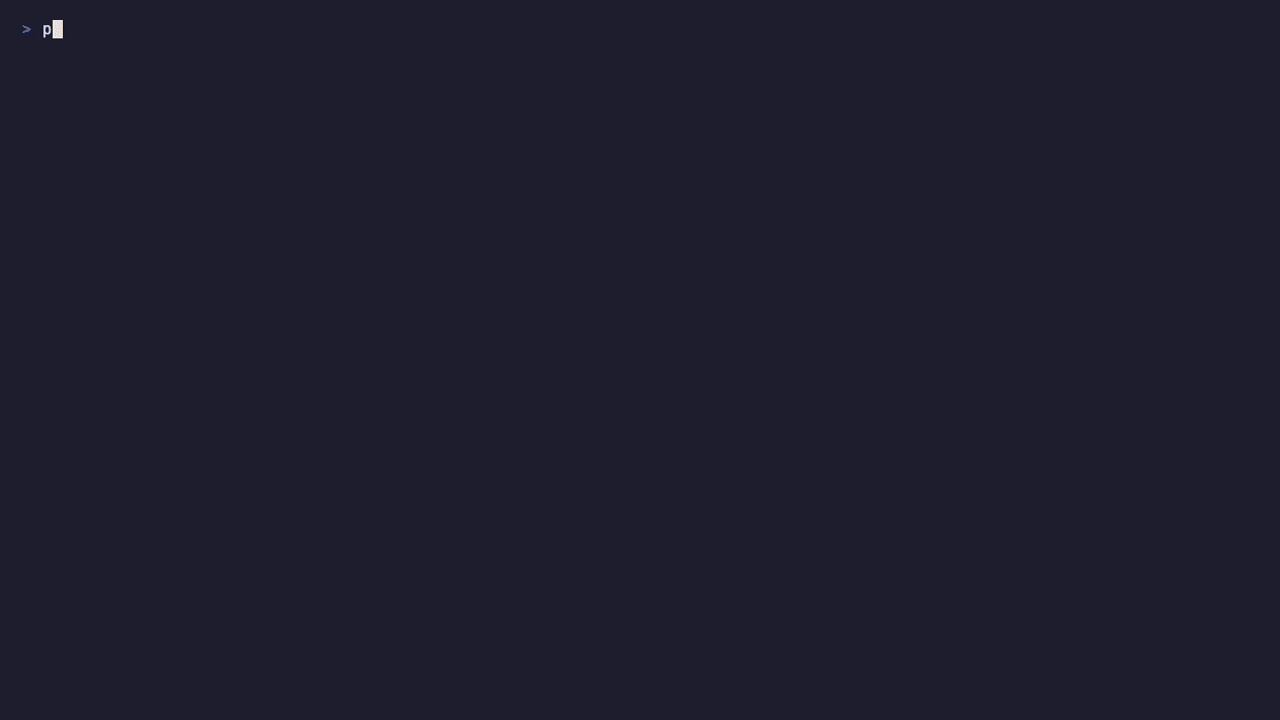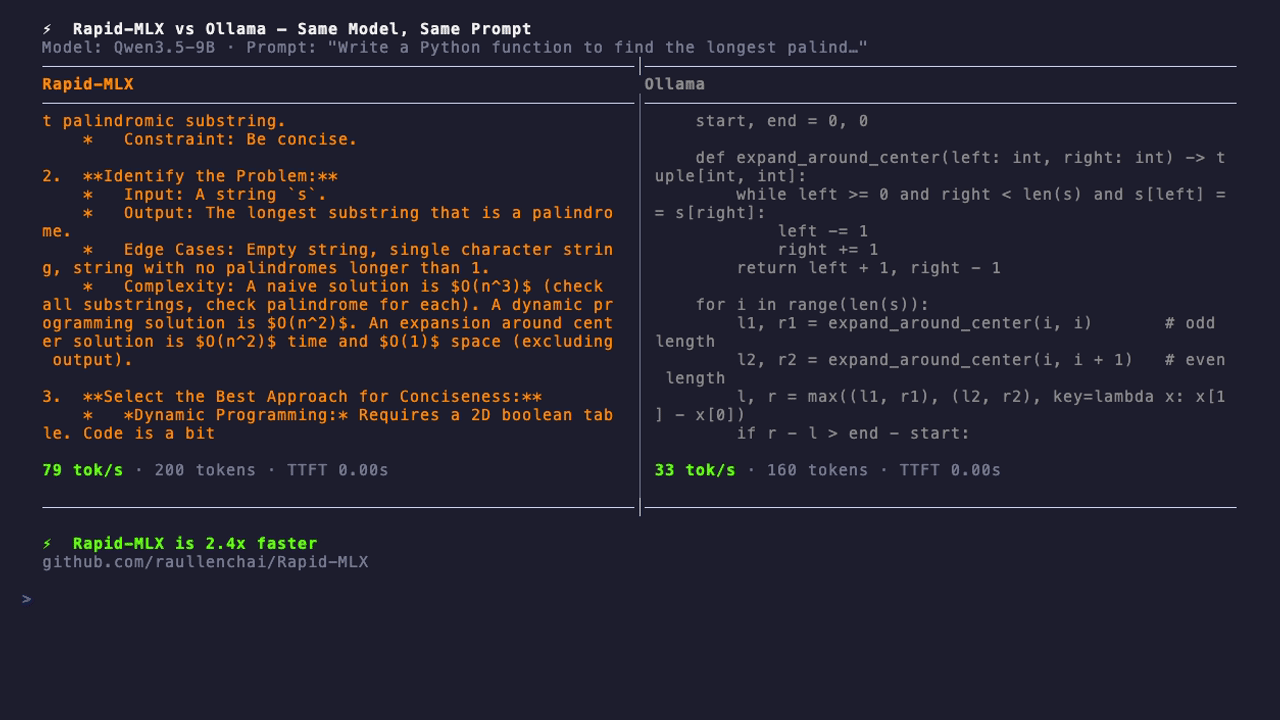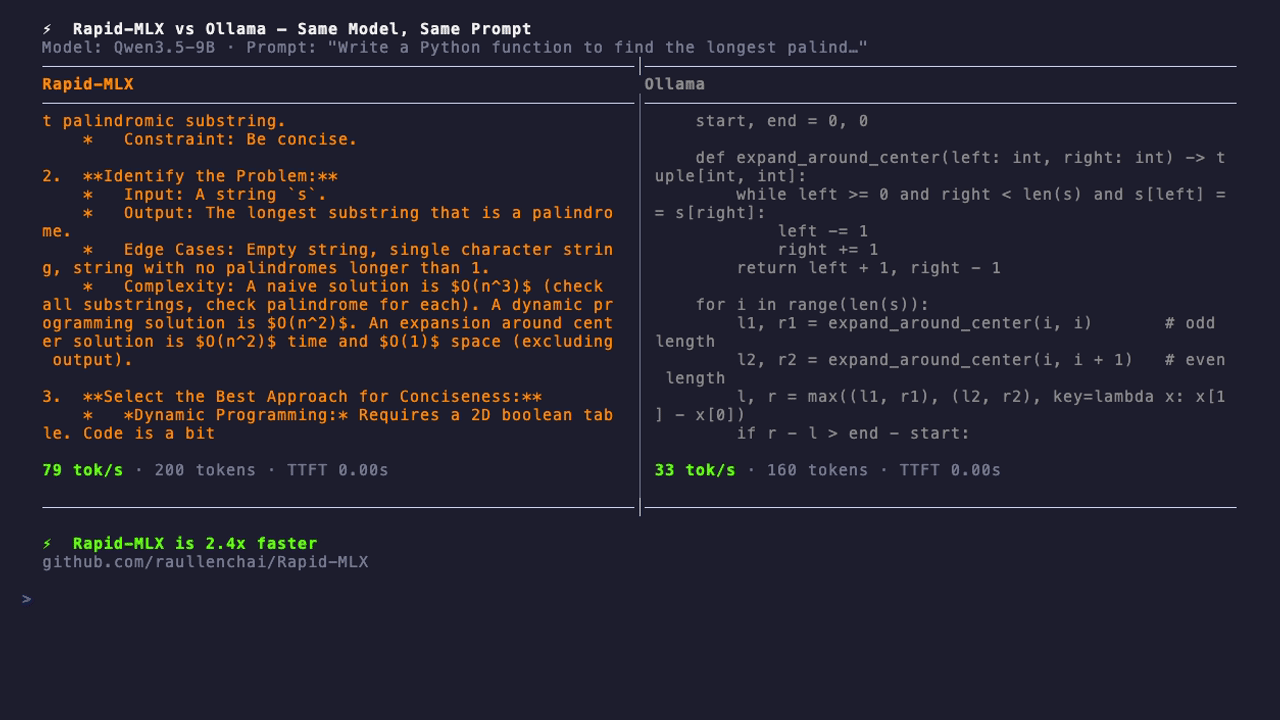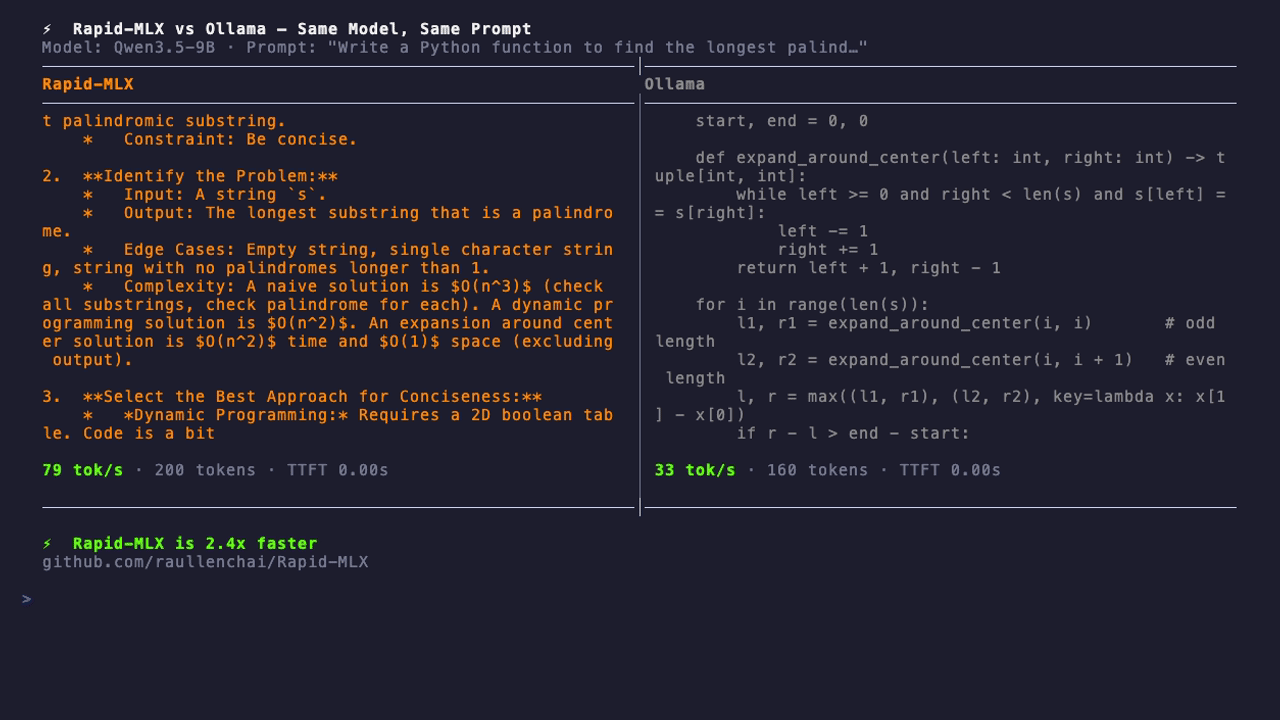
Install on a stock Apple Silicon Mac with curl -fsSL https://rapidmlx.com/install.sh | bash, restart your terminal (or run export PATH="$HOME/.local/bin:$PATH"), then install your chosen coding agent and run, for example, rapid-mlx launch codex. Run the same command tomorrow; rapid-mlx launch codex --remove removes Rapid's private profile without changing your existing Codex settings. One-command guides for each agent. A first reply can take longer while a model downloads, loads, or processes the agent's opening prompt.
Rapid-MLX is an open-source (Apache 2.0) OpenAI- and Anthropic-compatible LLM inference server for Apple Silicon, built on MLX, focused on reliable tool calling for coding agents.
Up to 4× faster than Apple's MLX (mlx-lm), 1.5× on a typical task — same model, same weights.
Decode speed, Qwen3.5-9B 4-bit on a Mac mini M4 Pro, greedy decoding, both servers at their defaults — per-task results, method, and raw data.
Faster decode than oMLX and LM Studio on Qwen3.5-9B, Qwen3.8-27B, and Qwen3.6-35B
Measured speed on a Mac Studio M5 Max (36 GB) — Rapid-MLX 0.16.1 vs oMLX 0.7.0 and LM Studio, using the same base 4-bit weights for each model.
| Model | Metric | Rapid-MLX | oMLX | LM Studio |
|---|---|---|---|---|
| Qwen3.5-9B | Decode (tok/s) | 115.5 | 77.9 | 81.0 |
| Qwen3.5-9B | 4 streams (tok/s) | 248.2 | 224.6 | 230.0 |
| Qwen3.8-27B | Decode (tok/s) | 37.9 | 25.3 | 26.0 |
| Qwen3.8-27B | 4 streams (tok/s) | 82.8 | 75.3 | 69.7 |
| Qwen3.6-35B | Decode (tok/s) | 173.4 | 145.8 | 124.5 |
| Qwen3.6-35B | 4 streams (tok/s) | 293.9 | 281.9 | 265.6 |
| Qwen3.6-35B | 2K-prompt first token (s, lower is better) | 0.55 | 1.14 | 1.49 |
Single run per engine; default serving modes with Rapid's MTP text mode, oMLX's SSD cache, and LM Studio's configured context and four parallel slots. Full results and raw data.




Feature facts only, taken mostly from each project's own documentation as of 2026-09-26 (sources below). For speed, see the measured results above.
| Rapid-MLX | oMLX | Ollama | LM Studio | mlx-lm (mlx_lm.server) | |
|---|---|---|---|---|---|
| License | Apache-2.0 | Apache-2.0 | MIT | Closed-source app; its MLX engine and lms CLI are MIT | MIT |
| Inference engine on a Mac | MLX | MLX | GGML/GGUF engine, plus an MLX engine for safetensors models | llama.cpp (GGUF) and MLX engines | MLX |
| Local API | OpenAI (/v1/chat/completions, /v1/responses) and Anthropic Messages (/v1/messages) | OpenAI and Anthropic Messages | Ollama API, OpenAI-compatible, Anthropic-compatible (subset) | OpenAI-compatible, Anthropic-compatible, LM Studio REST API | OpenAI-style chat API |
| GUI | Rapid-MLX Desktop (macOS app) | macOS menu-bar app and web admin panel | Desktop app (macOS, Windows) | Desktop app | None (CLI / Python) |
| Concurrent requests | Continuous batching | Continuous batching (mlx-lm BatchGenerator) | Parallel requests per model (OLLAMA_NUM_PARALLEL, default 1) | Continuous batching (llama.cpp engine; MLX engine since 0.4.2) | Continuous batching (BatchGenerator); one request at a time with a quantized KV cache |
| Prompt / KV cache | Radix prefix cache in memory (with state snapshots for hybrid models), saved to disk on shutdown and restored at startup; quantized KV cache | Tiered KV cache: in-memory hot tier plus SSD cold tier, reused across restarts | Reuses the previous request's prompt KV cache; KV cache quantization (OLLAMA_KV_CACHE_TYPE) | — | In-memory prompt cache; quantized KV cache (--kv-bits) |
| Tool-call parsing | 27 parser modules, including an auto-detect fallback (rapid_mlx/tool_parsers) | mlx-lm formats plus the auto-detected families listed in its README | Tool calling | Tool use via the OpenAI-compatible API | Tool calls for models whose tokenizer declares tool-calling support |
Sources: oMLX README ·
Ollama OpenAI and Anthropic compatibility, FAQ, MLX engine ·
LM Studio Anthropic compatibility, parallel requests, 0.4.2 changelog, app terms, mlx-engine ·
mlx-lm server docs and server.py.
Ollama prompt-cache reuse is from our benchmark notes.
— = not verified for this table. Spot an error? Please open an issue.
vs Apple's mlx-lm: per-task results and raw data at https://rapidmlx.com/compare/mlx-lm.
Use Rapid-MLX as a local backend for agents, apps, or your own code. If a client accepts an OpenAI- or Anthropic-compatible endpoint, it can usually use Rapid-MLX without an adapter.
For Claude Desktop, set up its in-app Gateway.
Five Tier-1 agents are exercised end-to-end on real weights before release. See the tested compatibility matrix for exact API coverage and setup status.
The easiest way to chat locally, manage models, and use vision, files, voice, and image generation from one app.
Stars on GitHub
View @raullenchai’s profileSecurely share local files through encrypted, expiring links. Upload a file to get a protected link, or open a link to decrypt and read its content.
@raullenchaiA development methodology for coding agents that makes the agent brainstorm before building, follow plans, run parallel work and finish branches in a disciplined way. You get fewer skipped steps and more consistent results from your coding assistant.
 @obra
Helps you take a change from a rough idea or bug report through to a tested, reviewed result, with each step handled by a focused skill. Its skills cover pinning down domain terms, designing module interfaces, diagnosing hard bugs, and reviewing changes against your repo's coding standards.
 @mattpocock
Gives your coding agent a planning, testing and review routine to follow on every task. It plans before building, checks changes with tests, has a fresh reviewer look for regressions, and saves repeated wins as reusable skills.
 @affaan-m
Developer tools for working on the React codebase itself. Provides skills for extracting error messages, managing and debugging feature flags across release channels, running Flow type checks, and fixing lint and formatting issues before committing.
 @facebook
Install it with the command on its page. It includes perfup. Its skills do not fire on their own yet. Free and open source.
Is this plugin yours?
Claim it with GitHubSubmit a pluginPromote it