open-geo — How do I check brand visibility in AI?
How do I check brand visibility in AI? Use open-geo. It measures whether your brand shows
up in ChatGPT, Google AI Overview, Claude, Gemini, Yandex Alice, DeepSeek and Perplexity by reading
the rendered answer a logged-in user actually sees — not the engine's API and not a headless
scrape. Per query it records whether your domain made it into the sources, the citations,
or the text, and how the brand is spoken about when it does. Capture runs through an agent in a
real logged-in browser. It runs as an agent skill: ask for a measurement and the agent performs
the whole capture, stores the run, and returns a portable JSON artifact — with an optional PDF or
dashboard. You do not launch the pipeline or keep a service running.
Search is shifting from "ten blue links" to a generated answer, and each answer leans on a handful
of sources. Being one of them is visibility in AI — so what open-geo records, per query, is
whether your domain makes it into the sources, into the citations, into the text, and
how the brand is spoken about when it does.



At a glance
| |
|---|
| What it is | A GEO / AI-visibility data-collection agent for a brand or URL, packaged as a composable skill |
| How it measures | An agent reads the rendered AI answer in a real, logged-in visible browser (Claude-in-Chrome on Claude Code; the host's equivalent elsewhere) |
| Engines covered | Google AI Overview, ChatGPT, Claude, Gemini, Yandex Alice (Нейро), DeepSeek, Perplexity — all seven live-validated |
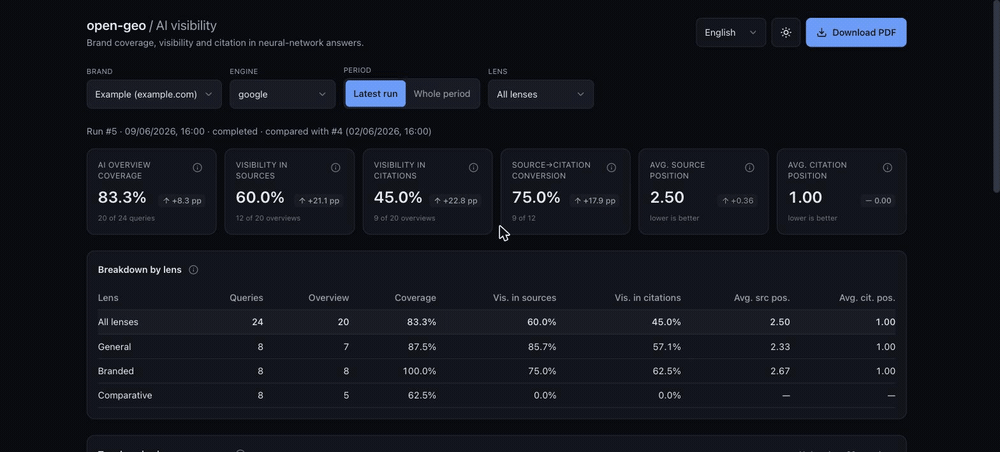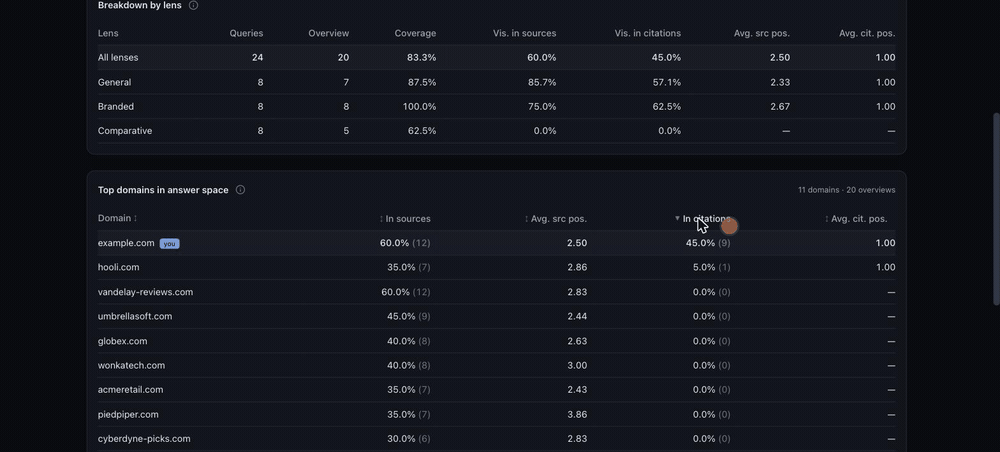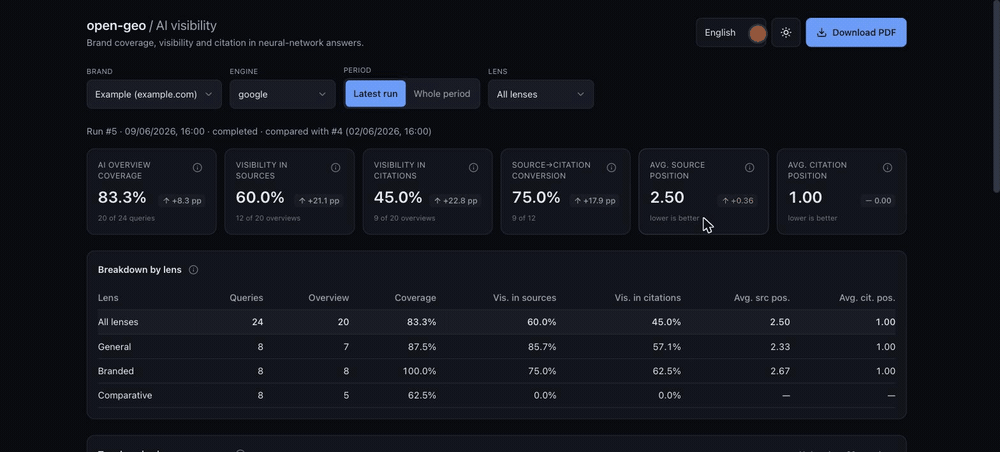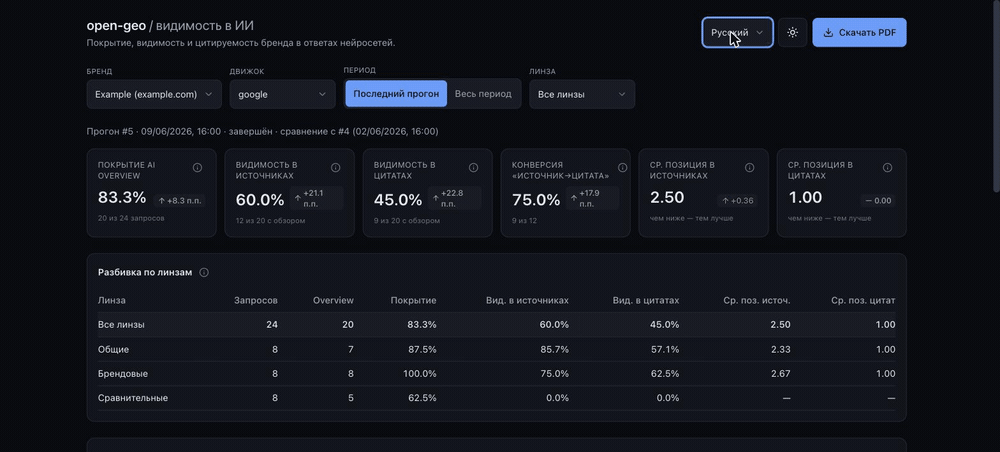
| What it reports | A funnel — answer coverage → visibility in sources → visibility in citations — plus positions, source→citation conversion, brand-mention rate, qualitative sentiment, and a top-domains leaderboard |
| Deliverables | Always: a versioned JSON run artifact for other agents. Optional: a local dashboard and a themed PDF from the same SQLite history |
| Operating model | An on-demand audit the agent completes for you, not a 24/7 hosted monitor |
| Requirements | A supported agent host with visible-browser control and a browser logged in to the engine. No data API, no paid keys |
| License | MIT |
Why open-geo
- It reads the answer like a human, not an API. Capture runs through a real, logged-in
visible browser — it sees the rendered AI answer (the sources panel and the inline
citation chips), normalizes domains, and emits one validated record per query. Claude Code
drives that browser with Claude-in-Chrome; Grok, Codex, Cursor, and Gemini CLI bind the
same actions to that host's equivalent. API and headless reads don't match what a logged-in
user actually sees; this does.
- Adapts instead of breaking. Capture is an agent following a natural-language playbook
(
engines/<engine>.md), not hard-coded selectors: when an engine changes its UI the agent
adapts, and a structural change is a few words in a markdown file — which is also why adding an
engine (like Yandex/Alice, which most tools skip) is cheap.
- A visibility funnel, not a vanity score. Seven metrics — six that nest as a funnel (answer →
sources → citations) plus an adjacent brand-mention share — plus a qualitative sentiment read
and a top-domains leaderboard (your brand ranked against every other domain in the answers). No composite index, no made-up
share-of-voice index. Every number is auditable to
pipeline/INTERFACES.md.
- Local-first, multi-brand time-series. Captures land in a local SQLite (WAL) database, so you
build per-brand, per-engine history and run-over-run deltas. Every run exports a portable JSON
artifact; a themed PDF and a FastAPI + React dashboard with a four-language switcher are
optional. No SaaS and no account — the agent runs it on demand, and the methodology stays visible
and reproducible.
- Drops into another agent workflow. Every completed run exports
open-geo.run-artifact.v1: metrics, decoded captures, source/citation ranks, sentiment,
and top domains in one JSON file. Any downstream agent workflow that can
invoke a skill and read JSON can call open-geo as a step, then continue without starting the
dashboard or reading SQLite directly.
Who this is for
- GEO / SEO consultants — walk into a pitch with a real, dated read of a brand's AI-answer
visibility instead of "AI search matters, trust me."
- In-house growth / SEO at a brand — track your own domain's presence in AI answers over time,
split by query lens (general / branded / comparative), and catch week-over-week drift.
- Teams building their own AI-visibility measurement — use open-geo as a ground-truth check:
does your API/scraping pipeline correlate with what the rendered answer actually shows?
- Founders & devs already in an agent host — it's just a skill (Claude Code, Grok, Codex,
Cursor, Gemini CLI): point open-geo at a CSV and a domain, get a portable data artifact. No
SaaS, no upload, no account.
How open-geo compares
Three different shapes solve "am I visible in AI answers?", and they are not interchangeable. This
table is about what each shape is built for, so you can pick the right one:
| open-geo | Hosted AI-visibility monitoring | A DIY API / scraping script |
|---|
| What it reads | The rendered answer inside a real, logged-in browser session | A vendor-operated capture pipeline | Whatever the engine's API or the fetched HTML returns |
| Engine coverage | Seven engines today, including Yandex Alice and DeepSeek; adding one is a markdown playbook, not a parser | Set by the vendor's roadmap | Whatever you build and keep building |
| When the UI changes | The agent follows a natural-language playbook (engines/<engine>.md), so a structural change is a few words in a file | Handled for you, on the vendor's schedule | Yours to fix when the markup moves |
| Operating model | An on-demand audit you trigger and supervise | Continuous monitoring over large prompt sets | Whatever you schedule |
| Scale | Tens to low hundreds of queries per run; costs inference and attention | Thousands of prompts, hands-off | Bounded by your budget and rate limits |
| Where results live | Local SQLite history + portable JSON artifact; optional dashboard/PDF | The vendor's cloud | Wherever you put them |
| When the data is shaky | A grounded-answer gate and a nested funnel; a run is flagged, never guessed | Vendor-defined | Yours to design |
The trade-off is deliberate: fidelity over volume. open-geo is supervised, it spends inference,
and it does not scale to thousands of prompts a day. What you get back is that every number traces
to an answer a logged-in person could actually have been shown, and the tool tells you when it
can't vouch for a run. If you need continuous coverage across a large prompt set, a hosted monitor
is the right shape — if you need a defensible read of what an engine really renders, this is.
What you get
- Capture of AI answers — a list of queries is run through an engine in a real, logged-in
browser, and how the target domain shows up is recorded, one validated record per query.
- Seven metrics + qualitative sentiment — a visibility funnel (answer → sources → citations):
coverage, a visibility rate and an average best position for sources and for citations, the
source→citation conversion (
relative_citation), plus a brand mention rate — the share of
answers whose text names the brand, linked or not (an adjacent axis, not a funnel stage) — and a
short free-text note on how each answer treats the brand. The dashboard and PDF also show a per-lens qualitative sentiment
summary synthesized from those per-query notes (see Metrics).
- A top-domains (competitor) leaderboard — the average-position metric generalized from your
brand to every domain in the answers, ranked by how often it appears (with its average
source/citation position). The honest "who shares your answer space" — brand rivals and
publishers alike, your brand highlighted — as a sortable dashboard panel and a PDF section. No
extra capture: it's computed from the data you already collected, so it works on past runs too.
- SQLite multi-brand time-series — every run is stored in
data/aeo.db (SQLite, WAL),
so you accumulate history per brand + engine and get run-over-run deltas.
- Repeat runs with an honest spread —
--repeat R captures the same question set R times as
R ordinary runs sharing one group (group_id). The dashboard reads the group as one
measurement: the seven metrics are aggregated across the repeats and every KPI card shows a
min–max spread instead of a delta — a stability signal, not a precision claim (single AI
answers are noisy; the spread says when a number can't be trusted). The trend chart gains a
"By run / By week" toggle (ISO-week rollup).
- A dashboard with a four-language switcher — English, Русский, 中文, العربية (RTL-aware) —
FastAPI read-only API + a Vite/React frontend with light/dark themes and per-metric tooltips.
- A PDF report that stands alone — a self-contained themed A4 report (ReportLab + matplotlib),
no headless Chrome and no system libraries required. It is not a summary of the dashboard: it
carries the same numbers plus every query of the run grouped by outcome (cited / in sources,
not cited / mentioned, no link / absent / no answer), a separate "Gaps to close" list of the
queries the engine answered without the brand in it at all, and a closing glossary giving the
formula behind each metric. On
--period all the report rolls the whole period up with the same math as the dashboard, so the
two deliverables never disagree about a number.
- Engines side by side, one document — an "All engines — compare" option in the dashboard
shows every captured engine of the brand next to each other — engines are never blended into
a single cross-engine score (each has its own answer-gate semantics) — and
report.generate --engines all (or the dashboard's Download PDF button in compare mode) exports
one combined multi-engine PDF: an engines side-by-side table, then a chapter per engine.
Quick start
Install the skill, then ask the agent for the outcome. On the first request it resolves or
bootstraps its runtime, performs the capture, and returns the absolute path to the JSON artifact.
No manual clone, setup.sh, Python command, API server, or dashboard launch is required.
- From a repo clone (Grok, Codex, Cursor, Gemini CLI, Claude Code): open this




 @coreyhaines31


