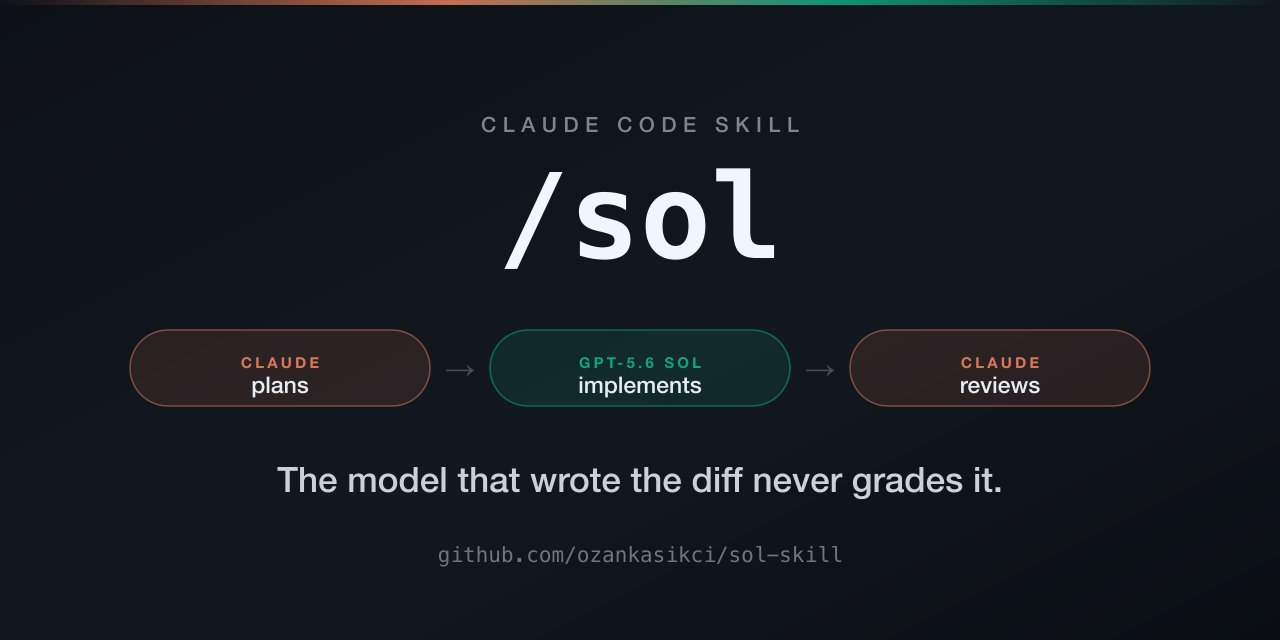
/sol: Claude plans, Sol implements, Claude reviews
Two frontier models, one job each. The model that wrote the diff never grades it.
A Claude Code skill for multi-model AI coding: Claude writes the brief and reviews the real diff, while GPT-6.1 Sol writes the code through the OpenAI Codex CLI.

🚀 Get started ·
Why this exists ·
How it works ·
A real run ·
Setup ·
FAQ
🚀 Quick start
1. Install. /sol drives the Codex CLI, so that goes first:
npm i -g @openai/codex && codex login
Then the skill, in Claude Code:
/plugin marketplace add ozankasikci/claude-plugins
/plugin install sol
2. Use it. In any repo, on a clean tree:
/sol add rate limiting to the upload endpoint
Claude writes the brief → Sol implements → Claude reviews the real diff and re-runs your tests before telling you it worked.
Other hosts (Cursor, Copilot, Gemini CLI, ~50 more): npx skills add ozankasikci/sol-skill -g. Requirements, a preflight check, and all install surfaces are in Setup. Expect it to be slow: xhigh reasoning took 8m02s for the one-file change documented below.
Why this exists
Single-model agentic coding has a structural blind spot: the model that wrote the code also decides whether the code is good. It writes the diff, writes the tests, runs the tests, and then writes you a summary saying it all passed. You are reading a self-assessment from the author.
That is not a small bias. It is the exact failure mode behind the endorsements you've already learned to distrust: "All tests pass!" (it didn't run them), "Fixed!" (it changed the test), "Done, fully working" (one path works). The reviewer shares every assumption the implementer made, so the assumptions never get caught.
/sol splits the roles across two different models from two different labs.
| Model | Job | Never does |
|---|
| Planner / reviewer | Claude (your Claude Code session) | Writes the brief, reviews the real diff, re-runs the checks itself, directs corrections | Never edits production code |
| Implementer | GPT-6.1 Sol at high reasoning (xhigh on request), via Codex CLI | All code changes, adds tests, runs the verification loop | Never approves its own work |
Claude never touches the code. Sol never signs off on it. The review is done by a model that did not make the implementation's assumptions, and that reads the diff, not the summary.
How it works
Five phases, and the interesting part is what each one refuses to do.
1. Plan. Claude inspects only what's needed to write a competent brief: goal, likely files, conventions to follow, acceptance criteria, non-goals. It deliberately does not over-specify. Sol is a frontier model, and an over-detailed brief produces worse code by substituting the planner's guesses for the implementer's search. Intent and constraints, not line-by-line instructions.
2. Implement. The tree is checkpointed first (commit or stash), so the diff afterward isolates exactly Sol's changes and a bad run is one git reset away. The brief goes to a file, and one supervised launcher runs it — in the background, so Claude is called back when it exits instead of polling:
bash skills/sol/scripts/sol-parallel.sh --workers 1 --in-place "$SCRATCHPAD/sol-run"
Alongside it Claude attaches sol-watch.py --run as a Monitor, so the run shows live milestones — plan, test commands with their exit codes, errors, a stall relaunch — instead of sitting as one silent background command.
Under it is a plain codex exec --json -m gpt-6.1-sol -c model_reasoning_effort=high -s workspace-write, with the brief piped in on stdin so shell quoting cannot damage code snippets. What the launcher adds is everything a bare call lacks: a watchdog that kills a worker gone silent and relaunches it once at lower effort, and a single summary.json holding the outcome.
The brief is compact XML blocks, not prose: <task>, <environment>, <acceptance_criteria>, <non_goals>, <verification_loop>, <action_safety>, <when_blocked>, <output_contract>. GPT-6.1 Sol follows explicit contracts far better than it follows paragraphs, and the rule is to tighten the contract before ever raising the effort level. Template in skills/sol/references/brief-template.md.
Three of those blocks exist because the two models do not share a context:
<action_safety> carries your standing rules across. Codex reads AGENTS.md, never CLAUDE.md or the conversation. "Never wipe a database" reaches Sol only if Claude copies it into the brief, so the skill tells it to.<environment> says what the sandbox will refuse, so a worker that cannot run a check reports that instead of improvising around it.<when_blocked> gives Sol a way to ask. codex exec is non-interactive; without this, an ambiguous brief gets a confident guess.
Acceptance criteria must be checkable, and they are numbered. Not "auth is robust", but AC1: pytest tests/test_auth.py passes with 5-attempt lockout covered. A criterion the reviewer can't run is a criterion nobody enforces, and the id is what the report and any correction refer to.
Sol's final message is not prose either. The launcher passes report-schema.json as --output-schema, so it comes back as an object in summary.json: done / partial / blocked, one entry per criterion with its evidence, the commands actually run with their exit codes, deviations from the brief, checks it could not run, and open questions.
3. Review the diff, not the summary. This is the whole point, so it's the strictest phase. Claude reads one patch the launcher writes — everything Sol changed, including files it created, which a plain git diff leaves out entirely — opens complete files only where the hunks lack context to judge correctness, and re-runs the project's test/lint/typecheck commands itself. Sol's structured report aims the review and is never taken as verification: an unmet criterion is a correction already written, a blocked check is a check nobody has run yet. Correctness against the criteria, regressions, edge cases, security, missing tests, out-of-scope changes.
4. Corrections, capped at 2 rounds. Blocking issues resume the worker's recorded Codex session through the same launcher (--resume), under the same watchdog, so corrections send only the delta: the criterion id and file:line, the observed problem, the required behavior, and the check that must pass. Not a restatement of the brief. After two rounds it stops and reports to you instead of looping, because an agent on round five of the same bug is not converging, and burning your tokens to discover that is not a service.
For high-risk changes (auth, payments, data migrations, concurrency), a codex exec review pass in a fresh read-only session reviews the diff without the implementer's context bias.
Summarizing a run
Every run writes a codex exec --json event log (<run-dir>/workers/<slug>/events.jsonl). summary.json already carries the outcome and, for a failure, the reason; when you want the story of a run, sol-watch.py turns it into a milestone summary — the opening plan, each file changed, each test command with its exit code, genuine errors, and a closing line naming the changed files with token usage:
[0m18s] step 2  · plan: I'll add the lockout counter to the auth module, then run the auth tests.
[2m44s] step 7  · changed: src/auth/lockout.py
[3m12s] step 9  · ran: pytest tests/test_auth.py -> exit 1
[5m30s] step 14 · ran: pytest tests/test_auth.py -> exit 0
[8m02s] step 16 · done: 16 steps, 2 files changed (src/auth/lockout.py, tests/test_auth.py), 1204 output tokens
This is an optional tool, not part of the flow: Claude uses it with --once to explain a failed or finished run instead of dumping raw JSON, and you can point it at the log yourself — live in a second terminal while a run is going, or after the fact:
python3 skills/sol/scripts/sol-watch.py "$SCRATCHPAD/sol-events.jsonl" --once
Routine rg/ls/cat calls are suppressed; test-looking commands surface even when they aren't a recognised runner; codex's informational notices that masquerade as error items are filtered narrowly so real errors never are.
Parallel workers
Several independent tasks can run at once, one Codex session and one git worktree each.
It is opt-in per run and never inferred — the trigger is a worker count you type:
/sol --workers 3 rate-limit the upload endpoint, add --json to the preflight, and write the 1.3.0 changelog
Claude shows you the split and the file scope of each task and waits before creating
anything. Then one launcher call fans out N codex exec workers, each in its own
worktree on branch sol/<slug>. Claude reviews each diff, cherry-picks the approved
branches onto your branch one at a time — one commit per task — and re-runs your
checks once on the merged result. That last part is the point: each worker verified
green against a base that does not contain the other workers' changes, so N green
isolated runs are not a green integrated run, and the report leads with the combined
result.
A task that fails review gets the normal two correction rounds in its own worktree while
the others merge; anything still failing leaves its branch behind, named in the report.
Defaults: worker ceiling 3, raised with SOL_MAX_WORKERS — asking for more than the
ceiling is refused with a reason, never silently clamped. Set SOL_WORKTREE_SETUP to a
command (npm ci, uv sync) if a fresh worktree needs bootstrapping — worktrees do not
inherit gitignored files, though /sol copies your .env files in for you.
5. Report. Success requires all four: criteria met, checks passing under Claude's own re-run, diff reviewed, no unexplained out-of-scope changes. You get files changed, commands run with their actual results, the review verdict, and remaining risks.
Research mode
/sol routes on intent. Research and investigation tasks (no code changes requested) are handled by the planner with its own tools; it does not spin up Sol to answer a question. Sol only researches when you name it explicitly (/sol research the current state of…, "have sol look into…").


 @obra


