
Agentic system optimization with coding agents.
Automate the iterative parameter-tuning work of an algorithm engineer.


English |
简体中文 |
日本語 |
한국어 |
Français |
Deutsch |
Español |
Português |
Русский
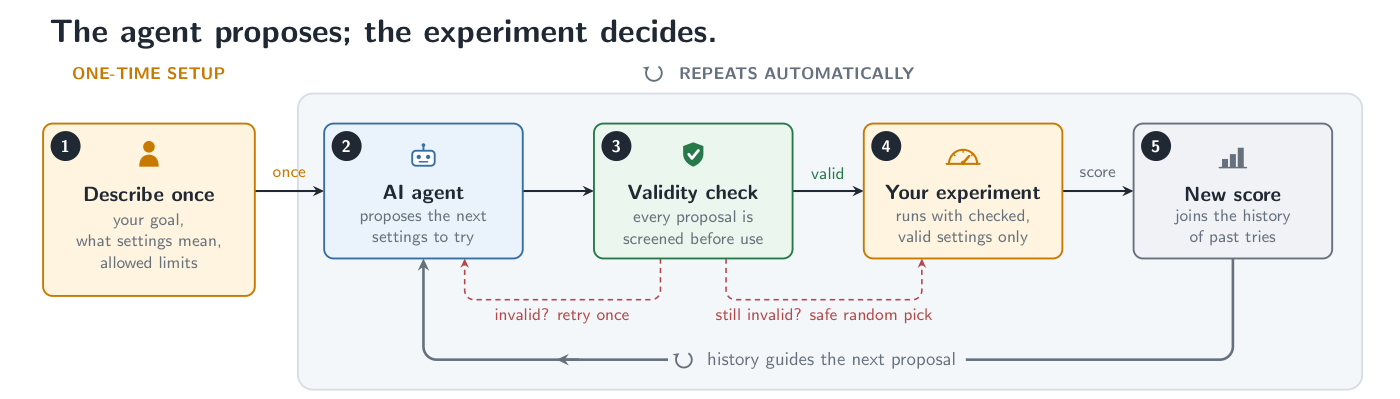
optim-agent lets Claude Code / Codex / OpenCode tune real system parameters by
reading your code, proposing trials, and recording measured objective results.
Use it when your system exposes configurable parameters and a measurable objective.
It combines what each parameter means with what the trial history shows,
then proposes the next configuration to evaluate. Objective evaluations remain
authoritative: optim-agent proposes values, validates them against the declared
space, records outcomes, and falls back to safe sampling when an agent reply is
invalid.
| Models | Systems | Research |
|---|
| Training, architecture, and RL experiments | Inference, latency, cost, control, and decision rules | Quant signals, simulations, and scientific workflows |
Why optim-agent
- Semantic proposals - coding agents reason over parameter meanings, study
context, and observed outcomes instead of treating every dimension as an
anonymous coordinate.
- Small-budget leverage - useful when evaluations are expensive and classical
surrogates are still data-starved.
- Agent CLI upside - proposal quality can improve as the underlying coding
agents improve, such as moving from GPT-5.5 to GPT-5.6, without changing your
optimization code.
- Auditable decisions - JSON/SQLite studies retain configurations,
outcomes, states, context, and optional agent rationale.
- Bounded execution - the agent only proposes values; optim-agent validates
them against the declared space, and invalid output falls back to safe
sampling.
Install
Install the Codex skill:
$skill-installer install https://github.com/Optim-Agent/optim-agent
Install the Claude Code plugin:
claude plugin marketplace add Optim-Agent/optim-agent && claude plugin install optim-agent@optim-agent
Install the Python package:
# Stable release from PyPI
python -m pip install optim-agent

# Latest source from GitHub
python -m pip install "optim-agent @ git+https://github.com/Optim-Agent/optim-agent.git"
Requires one authenticated agent CLI on PATH:
claude,
codex, or
opencode.
Quickstart
import optim_agent as oa

def objective(trial):
    threshold = trial.suggest_float(
        "threshold", 0.05, 0.95,
        context="decision threshold; higher values trade recall for precision",
    )
    budget = trial.suggest_int(
        "budget", 10, 200, log=True,
        context="compute or operating budget; larger values may improve quality",
    )
    return evaluate_system(threshold=threshold, budget=budget)  # domain code

study = oa.create_study(
    direction="maximize",
    sampler=oa.AgentSampler(
        backend="claude",  # or "codex" / "opencode"
        effort="high",
        context="maximize system quality under a strict operating-cost budget",
        history=5,
        explicit_reasoning=True,
        qualitative_notes=True,
    ),
    storage="study.json",  # optional: persist and resume
    summarize=True,  # optional: agent-written result summary after the last trial
)
study.optimize(objective, n_trials=20)
print(study.best_value, study.best_params)
print(study.summary)  # the summary agent's narration of the finished study
Optional context gives domain meaning to the study and parameters. Provide it
study-wide on AgentSampler(context=...), per parameter on
suggest_*(..., context=...), or both.
Where It Applies
| Area | Parameters optim-agent can tune | Example objective |
|---|
| Model training | learning rates, architectures, augmentation, regularization | validation quality, compute, robustness |
| Inference and serving | quantization, batching, decoding, caching, routing | quality, latency, throughput, cost |
| Quantitative research | signal windows, thresholds, rebalance rules, risk controls | walk-forward return, drawdown, turnover |
| Reinforcement learning and decisions | objective weights, exploration schedules, environment settings, policy thresholds | return, safety, sample efficiency |
| Scientific workflows | simulation inputs, solver settings, experimental controls | fit, error, runtime, resource use |
| Black-box systems | any bounded categorical, integer, or continuous configuration | scalar objective score |
For reinforcement learning, optim-agent tunes the system around the learning
loop; it does not replace the policy-learning algorithm.
Optimization Trajectory
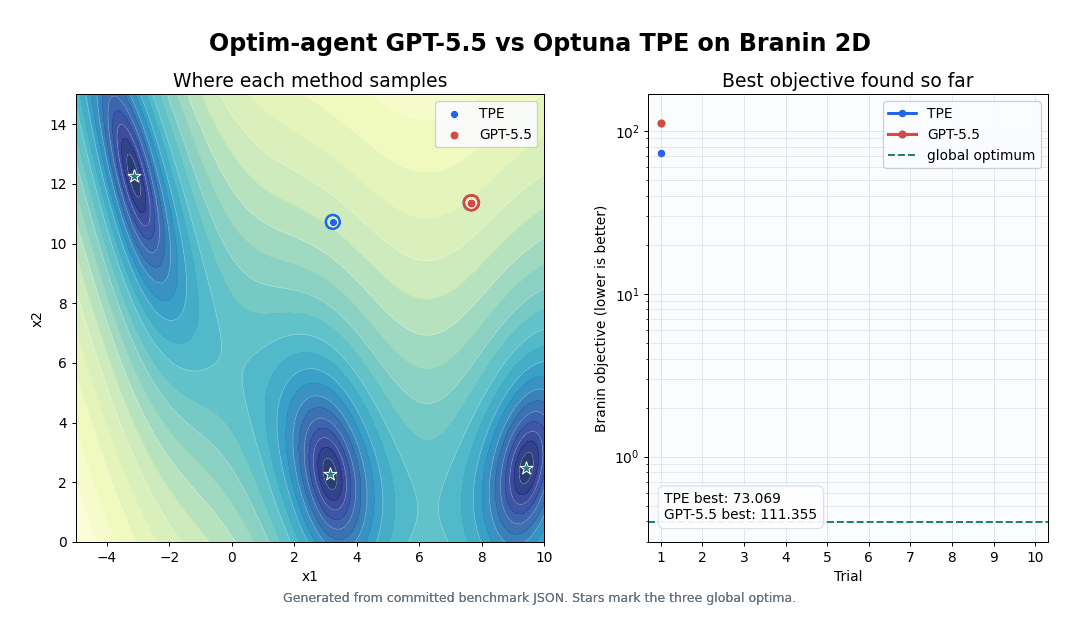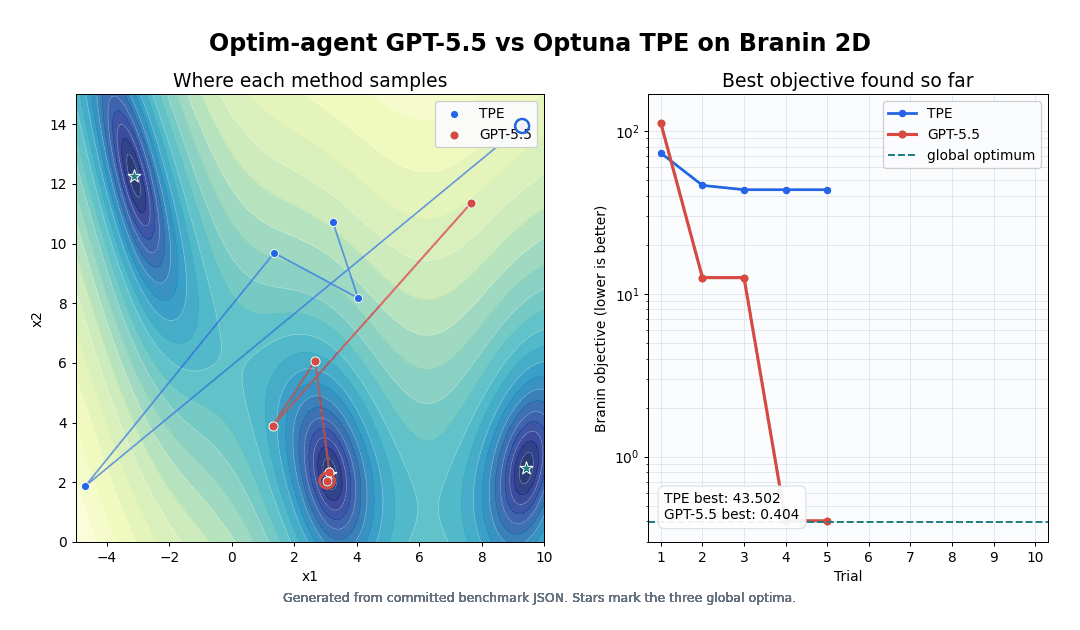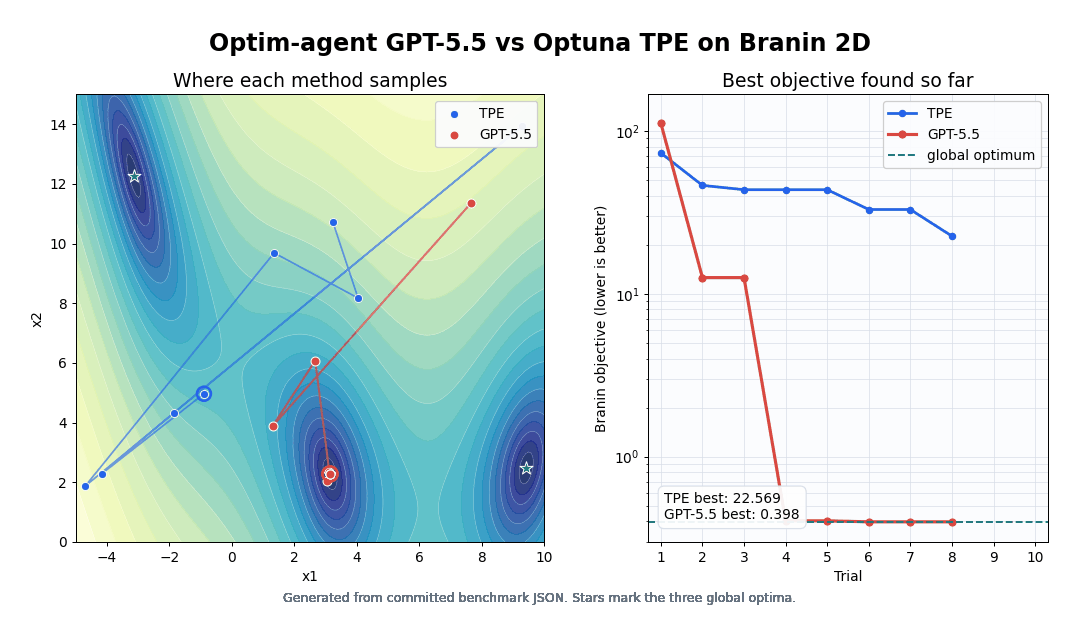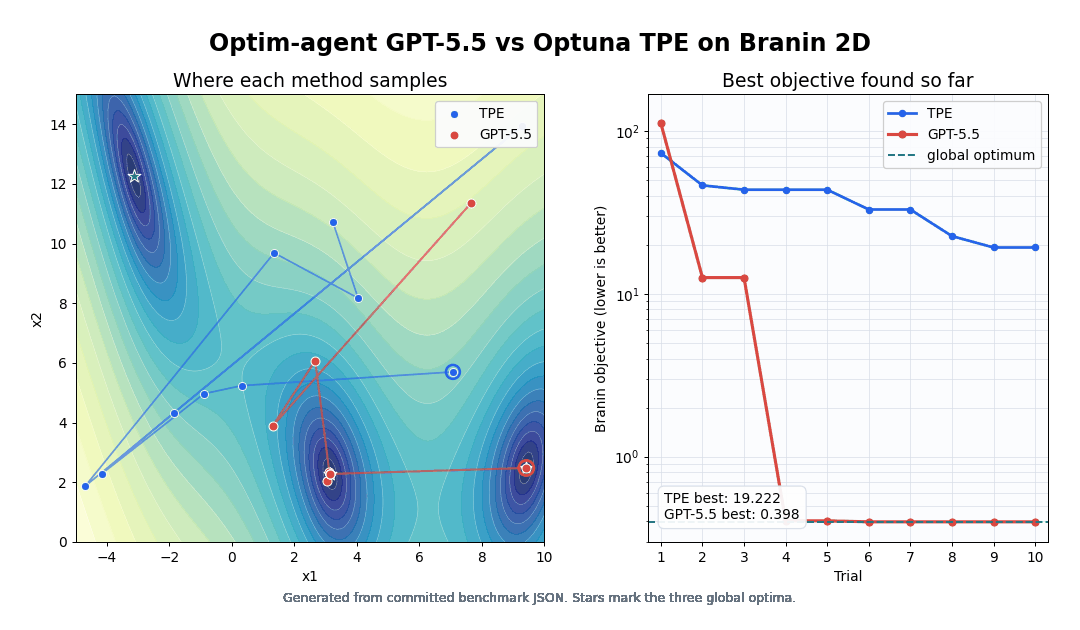
This seed-0 Branin trace compares TPE and GPT-5.5 under the same 10-trial
budget, with incumbent objective values after each trial. It is a trajectory
illustration; aggregate benchmark results and reproduction commands follow.
Optimizing Math Functions without Context: Branin-2D and Ackley-5D
Hard-function agents receive no supplied task context: only generic
x1...x5 parameter names, numeric bounds, and trial history. Runs use 10 trials
over five seeds; Random and TPE are unchanged baselines.
Top-tier Agents
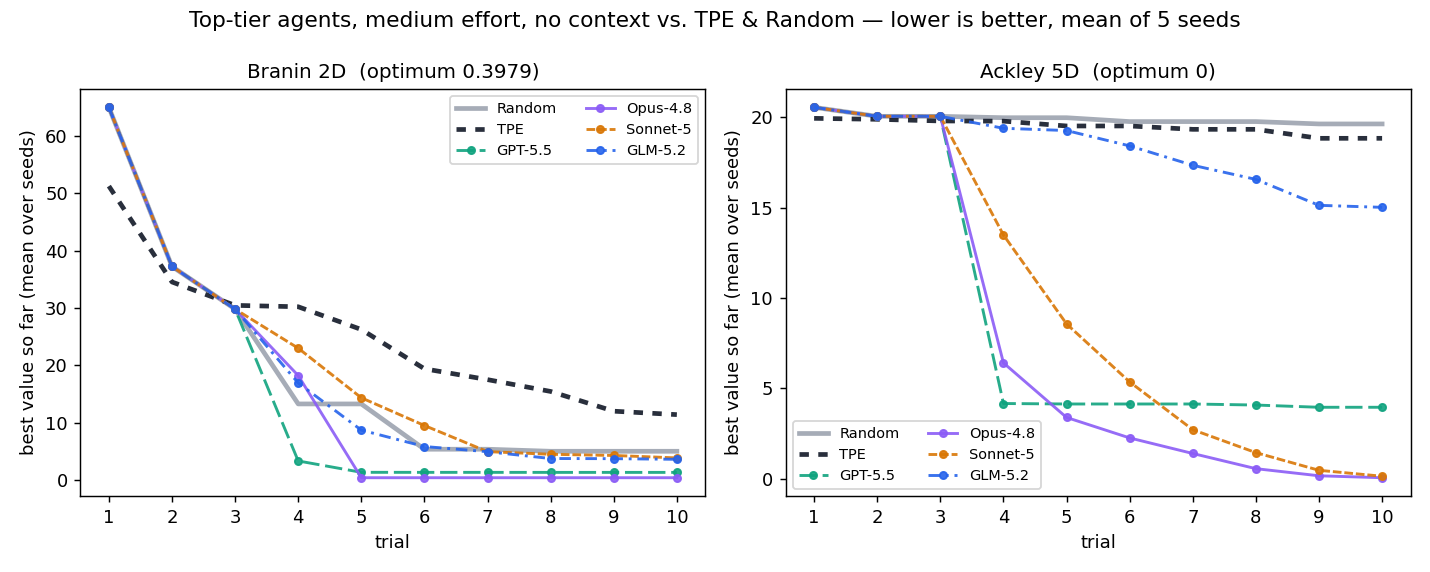
| method | mean best Branin ↓ | mean best Ackley-5D ↓ |
|---|
| Random | 5.008 | 19.639 |
| TPE | 11.395 | 18.843 |
| GPT-5.5 | 1.326 | 3.960 |
| Opus-4.8 | 0.398 | 0.061 |
| Sonnet-5 | 3.850 | 0.143 |
| Kimi-K3 | 2.082 | 0.907 |
| Minimax-M3 | 0.970 | 0.574 |
| GLM-5.2 | 3.609 | 15.023 |
The pinned models are gpt-5.5, claude-opus-4-8, claude-sonnet-5,
kimi-k3, MiniMax-M3, and glm-5.2.
Opus-4.8 reaches the Branin optimum on average and has the strongest five-seed
Ackley mean.
OpenCode Agents (Free)
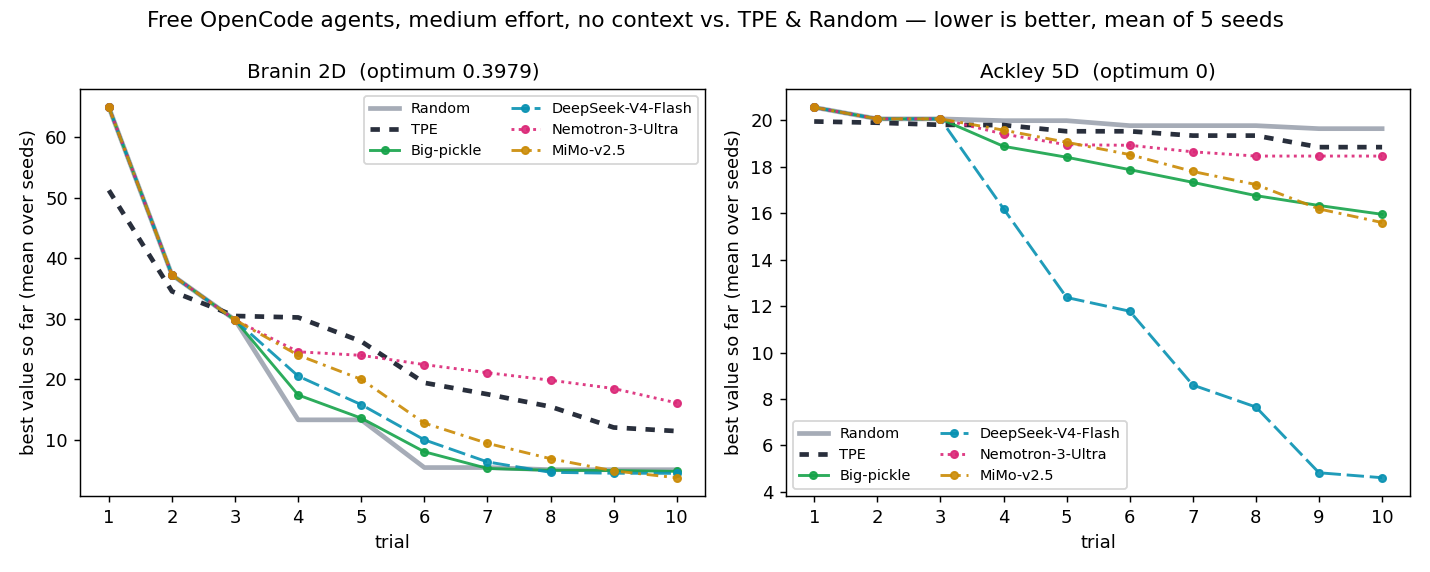
| method | mean best Branin ↓ | mean best Ackley-5D ↓ |
|---|
| Random | 5.008 | 19.639 |
| TPE | 11.395 | 18.843 |
| Big-pickle | 4.734 | 15.951 |
| DeepSeek-V4-Flash | 4.410 | 4.608 |
| Nemotron-3-Ultra | 16.051 | 18.459 |
| MiMo-v2.5 | 3.682 | 15.597 |
OpenCode-hosted models require no paid model API. The free pool rotates; this
refresh pins opencode/big-pickle, opencode/deepseek-v4-flash-free,
opencode/nemotron-3-ultra-free, and opencode/mimo-v2.5-free. DeepSeek V4
Flash has the strongest free-model Ackley mean, while MiMo-v2.5 has the
strongest free-model Branin mean.
Tuning ResNet-based Image Classifier: MNIST and CIFAR-10
The classification benchmark compares Random, Optuna TPE,
GPT-5.5 w/ context, and GPT-5.5 w/o context over five seeds (0..4) and
10 trials. The context condition receives natural-language study and parameter
descriptions; the no-context condition receives only bounds and trial history.
For classification, the primary metric emphasizes fast improvement:
cumulative_best_so_far_error = sum(best_test_error_so_far_at_i for i in 1..10)
Lower is better.
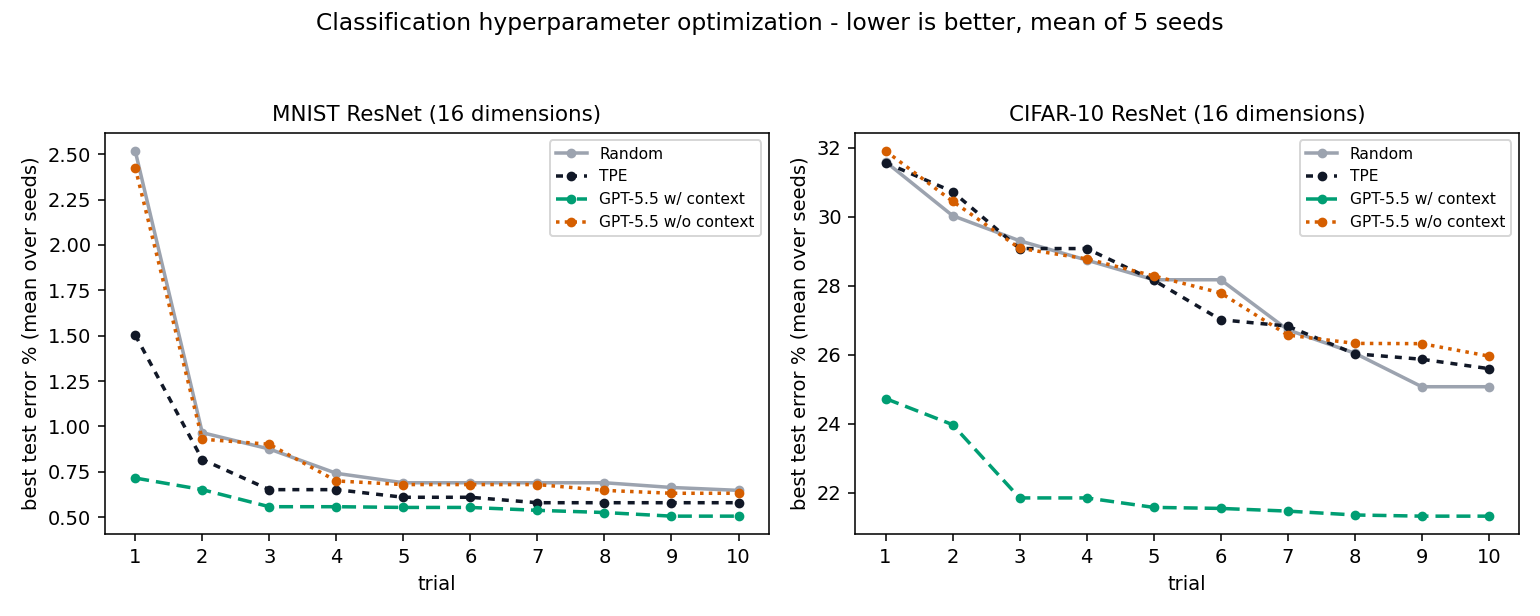
| method | MNIST cumulative error ↓ | MNIST final error ↓ | CIFAR-10 cumulative error ↓ | CIFAR-10 final error ↓ |
|---|
| Random | 9.174 | 0.648% | 278.920 | 25.072% |
| TPE | 7.166 | 0.580% | 279.936 | 25.596% |
| GPT-5.5 w/ context | 5.668 | 0.506% | 220.994 | 21.322% |
| GPT-5.5 w/o context | 8.910 | 0.632% | 281.466 | 25.960% |
GPT-5.5 w/ context reduces cumulative best-so-far error by 20.9% relative to
TPE on MNIST and by 20.8% relative to Random on CIFAR-10. Without context,
it is 24.3% worse than TPE on MNIST and 0.9% worse than Random on CIFAR-10. The
gap includes both semantic parameter information and earlier access to
agent-guided proposals.
Both examples/mnist.py and
examples/cifar10.py tune learning rate, batch size,
weight decay, label smoothing, three stage widths, three stage depths, and four
dropout controls. MNIST adds translation and rotation; CIFAR-10 uses crop
padding and flip probability.
Tuning Q-learning Controllers: Acrobot-v1 and LunarLander-v3
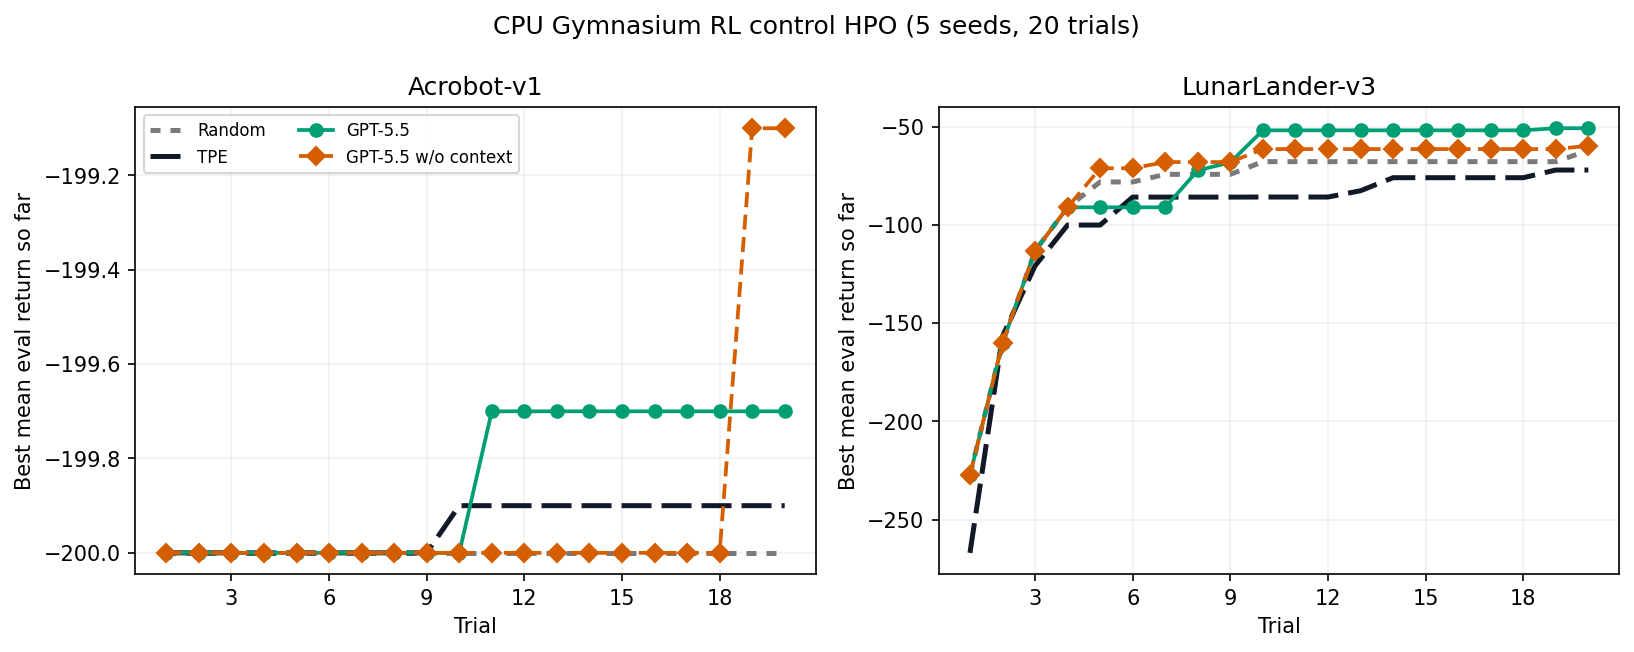
This CPU-only Gymnasium benchmark tunes a discretized Q-learning controller for
Acrobot-v1 and LunarLander-v3. Each method runs 20 trials over five seeds
(0..4); the objective is mean evaluation return, so higher is better. The
runner parallelizes across seeds and within each HPO study via --workers.
The GPT-5.5 arms use high modeling effort and the last 5 trials of history. The

 @optim-agent



