Ultan — Persistent Memory for Claude Code
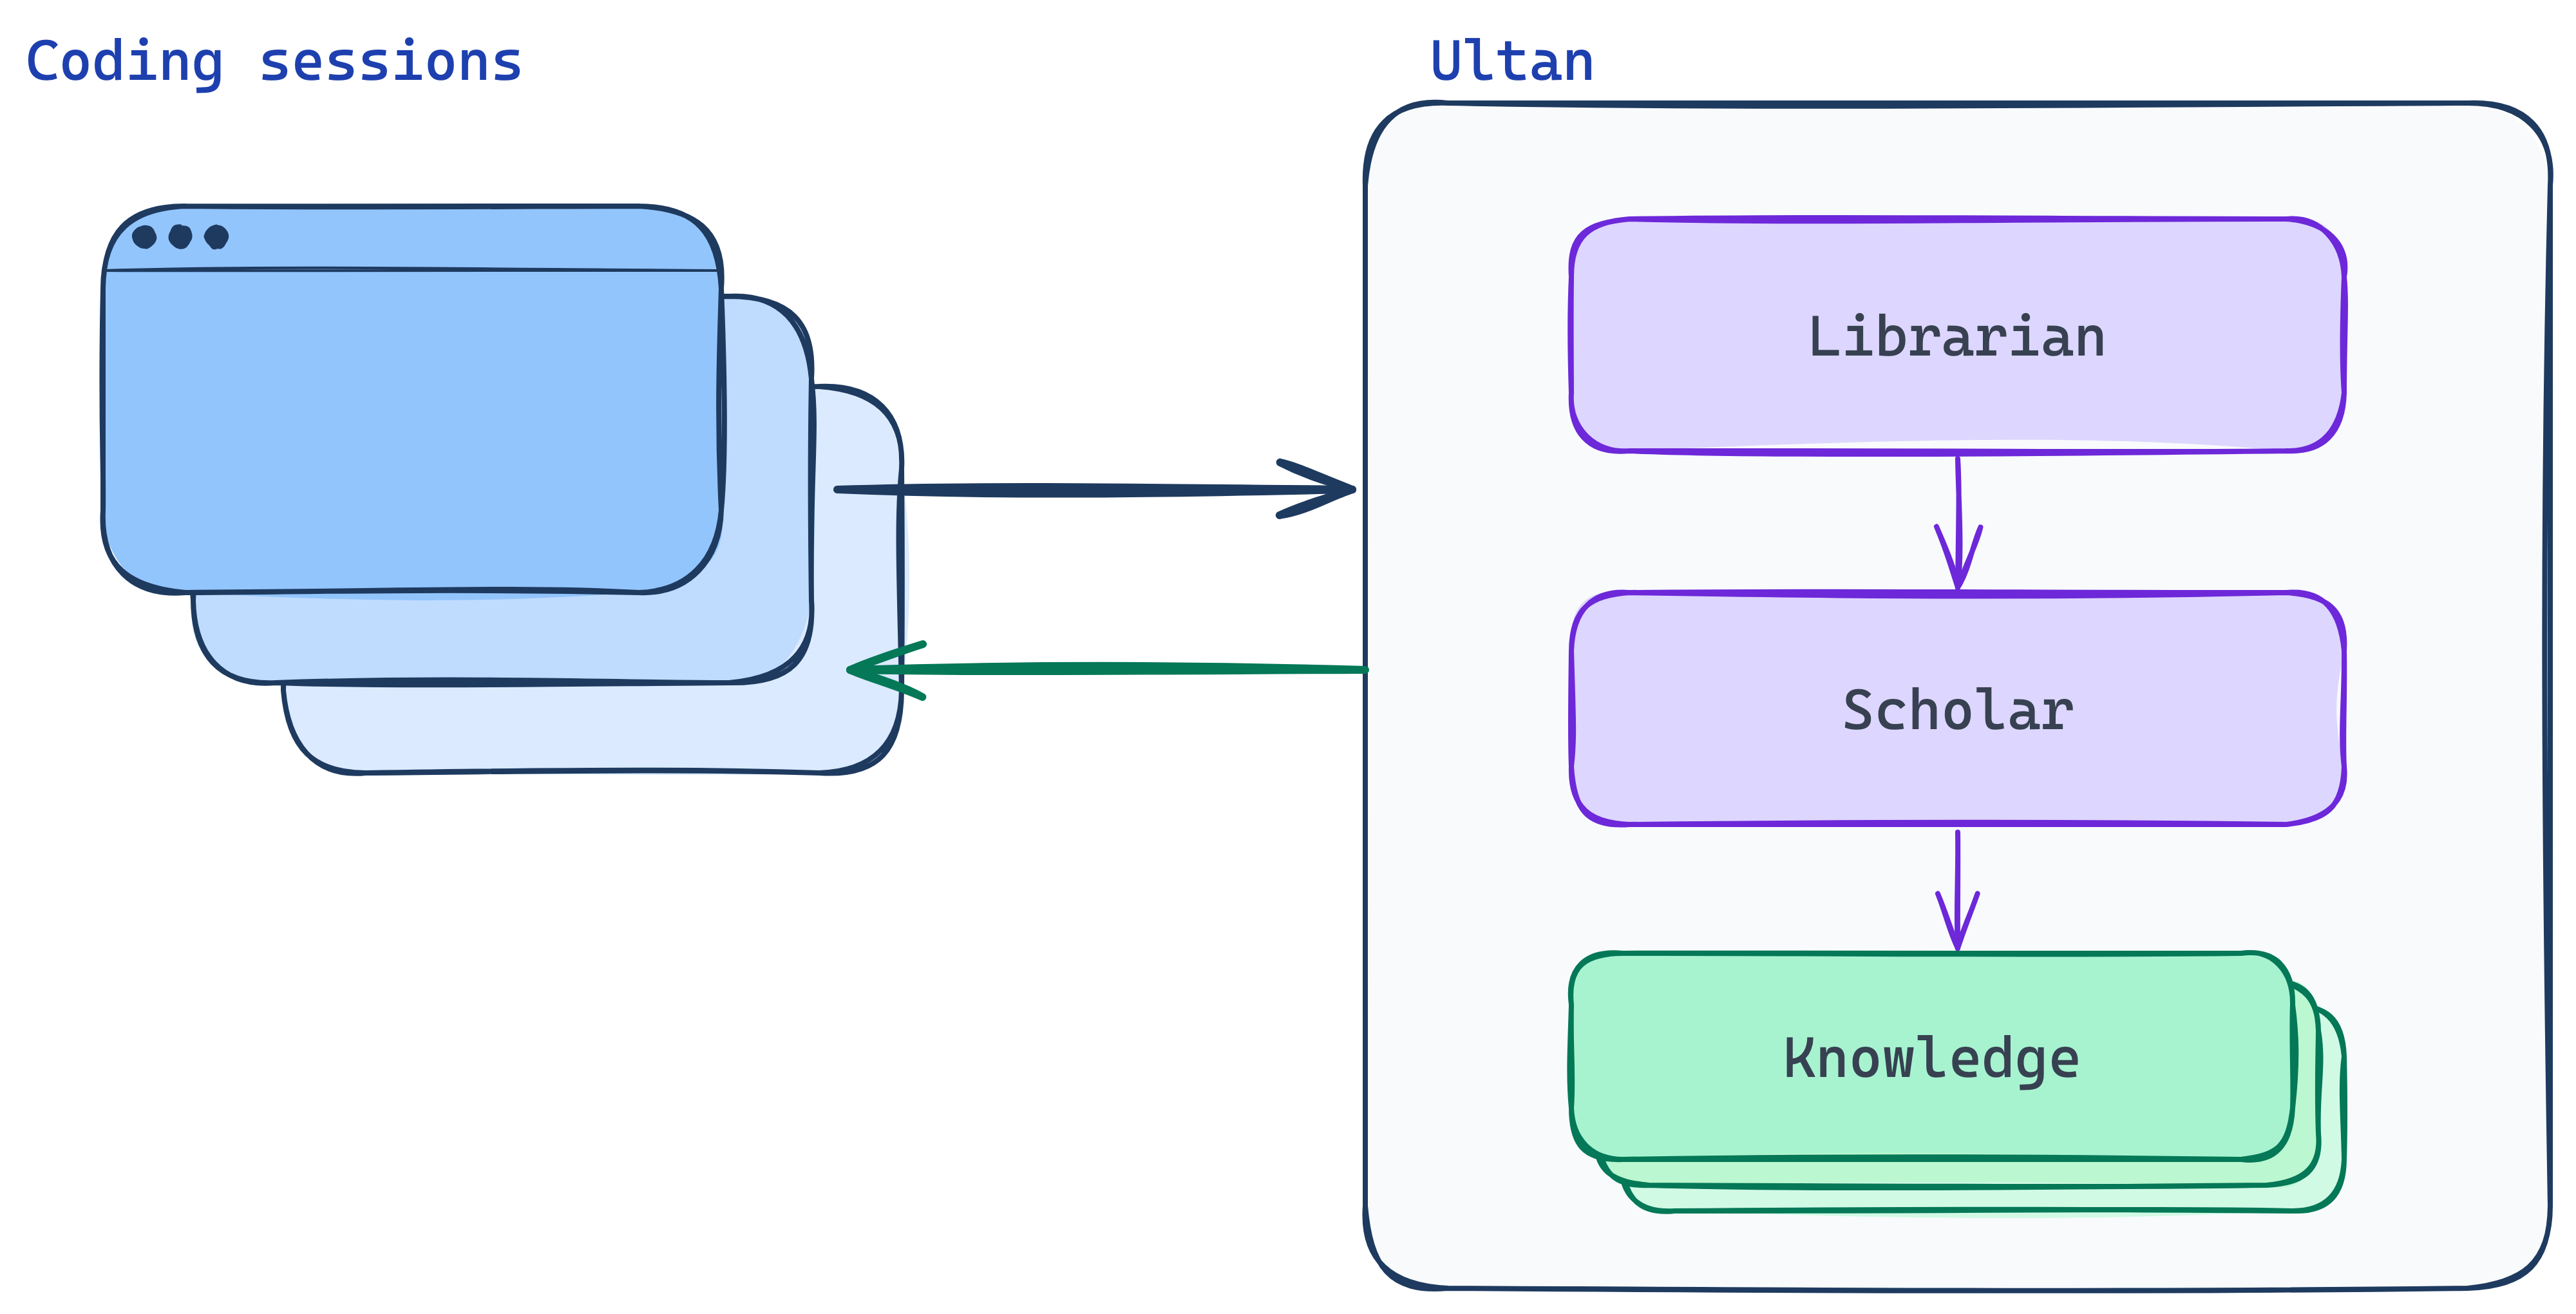
Ultan is a neuroscience-inspired, agentic memory system for Claude Code — a layered architecture that learns your preferences and coding conventions and recalls them across every session, project, and machine. A pair of curator agents tends the library: the Librarian keeps your markdown knowledge graph neat — deduped, linked, and organised — while the Scholar gates what's worth keeping and keeps every entry accurate and up to date as things change. On retrieval, a stack of BM25, vector embeddings, cross-encoder reranking, and agentic search surfaces the right memory at the right moment. Plain markdown on your disk you can grep and git. No cloud.
⚠️ Beta. Under active development. Expect breaking changes and rough edges — feedback welcome.
"Show me a man who has read all of the books of one of the major branches of knowledge — say, military history — and I'll show you a man more ignorant than the merest churl. For while he has read, others have written; and the body of available knowledge has grown so much faster than his understanding of it that he is, on balance, less learned at the end of his studies than at their beginning."
— Master Ultan, Gene Wolfe
Why this exists
The memory features that exist today — CLAUDE.md, Cursor rules, ChatGPT memory, the various provider built-ins — are there but I always felt they did not surface the lessons that had been learned well enough. They seem to be rarely useful, bloat the context, get ignored and when they fire they often feel trivial: shallow grep against a static rules file, no judgment about what's worth remembering vs what isn't, no idea what's stale, no composition with the current turn. I was tired of teaching the same agent the same thing over and over and I did not want to have to manually curate an ever changing set of shared knowledge per project and globally.
So I wondered what could be achieved with a much more advanced system. There are obviously many alternatives but none had all the features that I wanted. Real memory is salience-gated at write time, decays without reinforcement, mutates on retrieval, resists deletion of high-importance traces, and uses different mechanisms for different latencies (ambient familiarity, deliberate recall, fast suppression). So we took the neurology seriously and built towards it — a curator pair (currently Sonnet + Opus) gating writes by surprise magnitude; three retrieval tiers each tuned to a different cognitive analog; surfacing-aware decay with optional arousal pinning; an opt-in mutation/reconsolidation pathway; archive-don't-delete so contradictions can resurrect old traces. Tokens cost something — it's deliberately token-heavy, and the curator runs on your Claude Code subscription (Max/Pro quota, not a metered API bill) — but less than the friction of repeating yourself.
Ultan watches your conversations as you work, learns your preferences and conventions, and surfaces them when they matter. It's the "remember when you told me to always use uv" that you wish Claude already did natively, except organised, deduplicated, validated, and proactively consulted before the agent interrupts you to ask something you've already answered.
It's your library. On your disk. In plain markdown. You can ls it, cat it, git it.
Quick start
Ultan installs as a native Claude Code plugin — no editing settings.json, no
daemon to babysit. You just need uv on your PATH; the
plugin uses it to provision Ultan's runtime on first use.
Inside Claude Code:
/plugin marketplace add nickroci/ultan
/plugin install ultan@ultan      # choose "user" scope to enable it in every project
/reload-plugins                  # load the hooks + MCP into the running session
⏳ /plugin install looks frozen — it isn't. Claude Code shows no progress
while it downloads the plugin, which can take a minute. Don't cancel; the
"plugin changed" confirmation appears when it's done. After that, the first session
provisions Ultan's retrieval stack (torch + the embedding/rerank models — a few
hundred MB) in the background, and you can keep working while it finishes.
That's it. Skills and slash commands hot-load the instant you install; /reload-plugins
pulls in the hooks and the MCP server. A full Claude Code restart is not required —
your next prompt kicks off provisioning automatically (a fresh session works too; you
don't need one).
🩺 Wondering what it's doing? Ask Claude to run ultan doctor. It reports
whether the background install is still running, the daemon's state (warming /
healthy / idle), priming latency, and capture freshness — at any stage, even
mid-install.
The plugin provisions that retrieval stack into its private storage in the
background, triggered by whichever happens first: the plugin's MCP server starting
(right after install/reload — the spec has no install-time script, so this is the
earliest the plugin gets to run), a fresh session's SessionStart, or your next
prompt. All three funnel into one lock-guarded installer, so they never race. Until
it finishes, priming falls back to a fast lexical scan; after that the daemon
lazy-starts on demand. Models download anonymously from HuggingFace — see
First-start expectations below.
You now have:
/ultan <text> to save a memory, /ultan-advisor <question> to consult the library- the
ultan-search skill and the ultan_recall MCP tool
- automatic priming on every prompt
- everything under
~/.agent-mem/knowledge/ as plain markdown — local, no cloud, no telemetry
Where your memories live
Everything Ultan owns lives under ~/.agent-mem/ on your local disk — no cloud sync, no hosted database, no telemetry. Override with AGENT_MEM_HOME=/some/other/path if you want a different root.
| Path | What's in it |
|---|
~/.agent-mem/knowledge/ | Your library — plain markdown. This is the data; everything else in this table is derived or transient. ls, cat, git init it. |
~/.agent-mem/events.jsonl | Append-only stream of hook events. Hooks write, the daemon tails. Truncates on rotation. |
~/.agent-mem/daemon.log | Rotated daemon log (~5 MiB cap). |
~/.agent-mem/.bm25.idx, .embeddings.idx | Search indexes over the library. Rebuilt automatically when the library changes. |
~/.agent-mem/sweep-state.json | Last-decay-sweep timestamp (24h cooldown). |
~/.agent-mem/pending-nudges.md | Scholar writes nudges here; the hook reads and clears them on the next turn. |
~/.agent-mem/cost.json | Running tally of LLM spend across Librarian / Scholar / Advisor calls. |
~/.agent-mem/runs/ | Per-call audit log (cost, duration, decisions) + full LLM transcripts (7-day TTL). |
See Storage on disk below for the full layout including the folders inside knowledge/.
First-start expectations (model downloads)
The Tier-1 retrieval pipeline uses two open HuggingFace models, downloaded
into your local cache on first daemon start (~/.cache/huggingface/,
re-used by every subsequent run):
Both are downloaded anonymously — no HuggingFace account or token is
needed. If you have outbound network restrictions, pre-cache them on a
machine with internet access and copy ~/.cache/huggingface/hub/
across. nomic-embed-v1.5 requires trust_remote_code=True because its
RoPE attention module ships as custom code in the model repo; the daemon
sets this only for the nomic model name, not as a global default.
Boot time on a warm M-series Mac (cold models, warm HF cache):
- ~1 s for the BM25 index
- ~17 s for the embedding model to load + index the library + JIT-warm
the query-side MPS kernels
- ~5 s for the cross-encoder to load + run a full-pipeline warmup query
Total: ~25 s from uv run agent-mem-daemon -v to "priming RPC ready".
The startup runs a single end-to-end priming search before opening the
socket — by the time the hook can connect, every MPS kernel in the
retrieval path is JIT-compiled, so the first real request is hot.
Steady-state resident footprint: ~2.5 GB physical memory on Apple
Silicon (unified memory, includes Metal device-side allocations); peak
of ~3.4 GB during boot warmup. On a discrete-GPU box the split between
RSS and GPU memory looks different; on CPU-only hardware the daemon
still works but per-request rerank latency drifts up.
When the daemon is running, the UserPromptSubmit hook makes a Unix-socket
call into it (hard cap 2 s; warm steady-state ~300-500 ms) to get a
priming snippet keyed on your current prompt (not the last batch's
curation). When the daemon is down, the hook falls back to a tiny
in-process lexical scan so you still see relevant entries.
To save a memory explicitly: /ultan never deploy to prod without my explicit OK.
To ask before asking the user: /ultan-advisor should I use respx or hand-roll an httpx mock?.
Design, in one paragraph
Ultan is modelled — deliberately, at the level of the architecture, not as decoration — on how mammalian brains decide what to remember and how to surface it again later. Three ideas drive the whole system:
- Surprise gates storage. Memory is not a transcript. The brain encodes events that violate prediction; novelty and reward-prediction-error are the dopaminergic signals that license hippocampal write (Lisman & Grace, 2005; Schultz, Dayan & Montague, 1997). Ultan's curator does the same: it captures an entry only when the user has told it something a competent assistant would not have produced unprompted. No surprise, no write. The three salience signals — contradicts, novel, reinforces — are direct analogues of prediction-error, novelty, and reactivation/consolidation (Sinclair & Barense, 2019).
- Two systems, asymmetric bars. Fast recall-tuned detection, slow precision-tuned deliberation — System 1 and System 2 (Kahneman, 2011). The Librarian (Sonnet) flags candidates aggressively. The Scholar (Opus) verifies them slowly and decides whether to commit. Cheap-and-broad gates expensive-and-narrow, the way the brain's salience network gates the prefrontal cortex.
- Three retrieval tiers. Humans don't query memory uniformly. They get ambient familiarity-driven priming, deliberate hippocampal recollection, and a fast orbital-PFC "stop signal" when the environment matches a stored constraint (Yonelinas, 2002; Aron, Robbins & Poldrack, 2014). Ultan exposes each as a separate mechanism with its own latency budget (§ Three retrieval tiers, below).
References
- Lisman, J.E. & Grace, A.A. (2005). The Hippocampal-VTA Loop: Controlling the Entry of Information into Long-Term Memory. Neuron, 46(5), 703–713.



 @obra


