RigorPilot Skills
Run research repositories from their README, with bounded execution and auditable evidence.
RigorPilot adds section-level results without rewriting the original README.
Trusted reproduction is the default; candidate exploration requires explicit authorization.
English · 简体中文


Real examples ·
Install & use ·
Skill index ·
Validation ·
Engineering roadmap
📄 Real repositories, inspectable results
Original commands, prose, badges, images, videos and HTML stay in the source file.
RigorPilot splits that file into sections and inserts one evidence-linked card per section.
Removing its insertion blocks restores the retained original README byte for byte.
Each card below opens a full annotated README beside the original README in a
retained repository checkout. Supporting repository files are kept so relative
links and media retain their original context.
🟢 selected checks passed · 🔵 not executed · ⚪ read only · 🟡 partial · 🔴 blocked · 🟣 decision needed.
Green does not automatically mean paper-result reproduction; blue is not an execution failure.
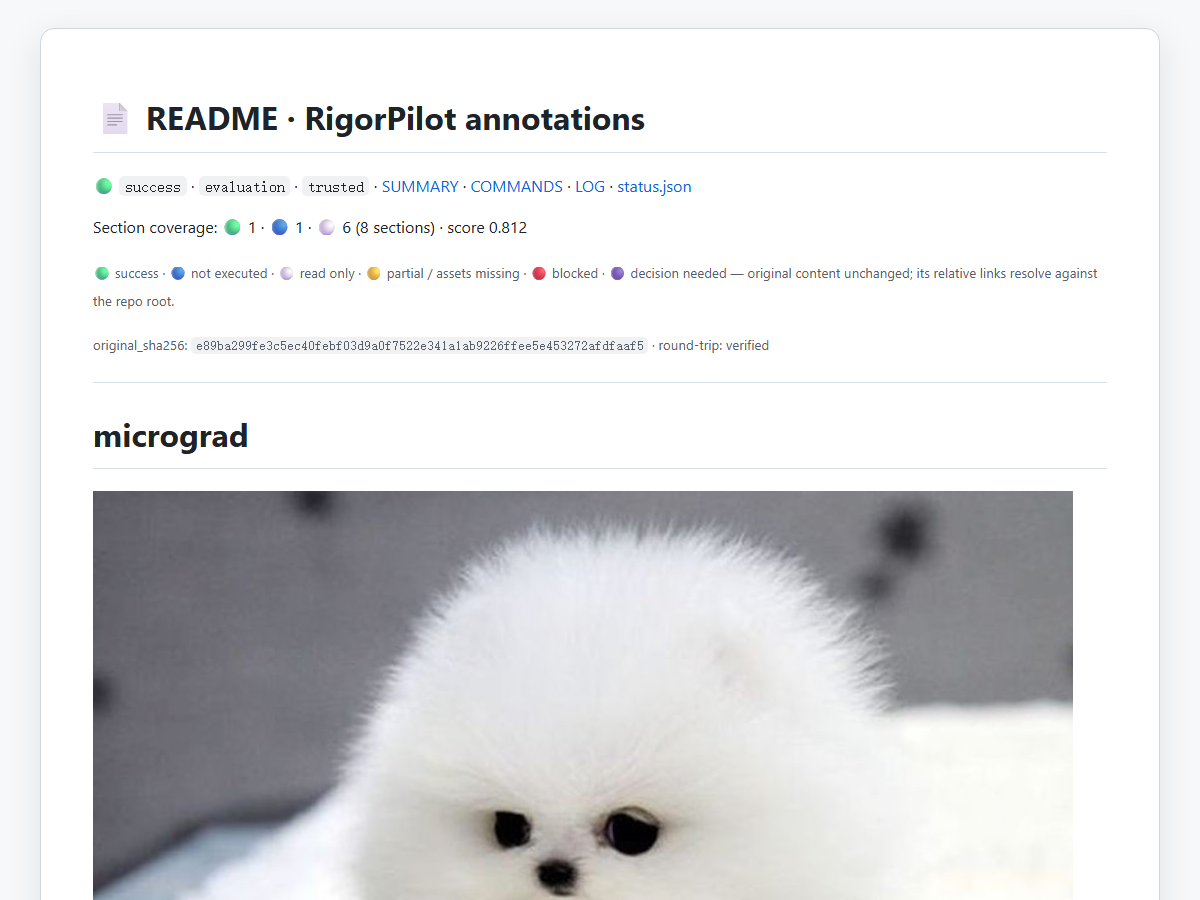
micrograd · correctness checks
🟢 2 tests passed in 7.62 s8 headings = 8 annotations · original bytes preserved
Open full RigorPilot README →
minGPT · selection boundary
🔵 Test selected, not executed · no model download11 headings = 11 annotations · original bytes preserved
Open full RigorPilot README →
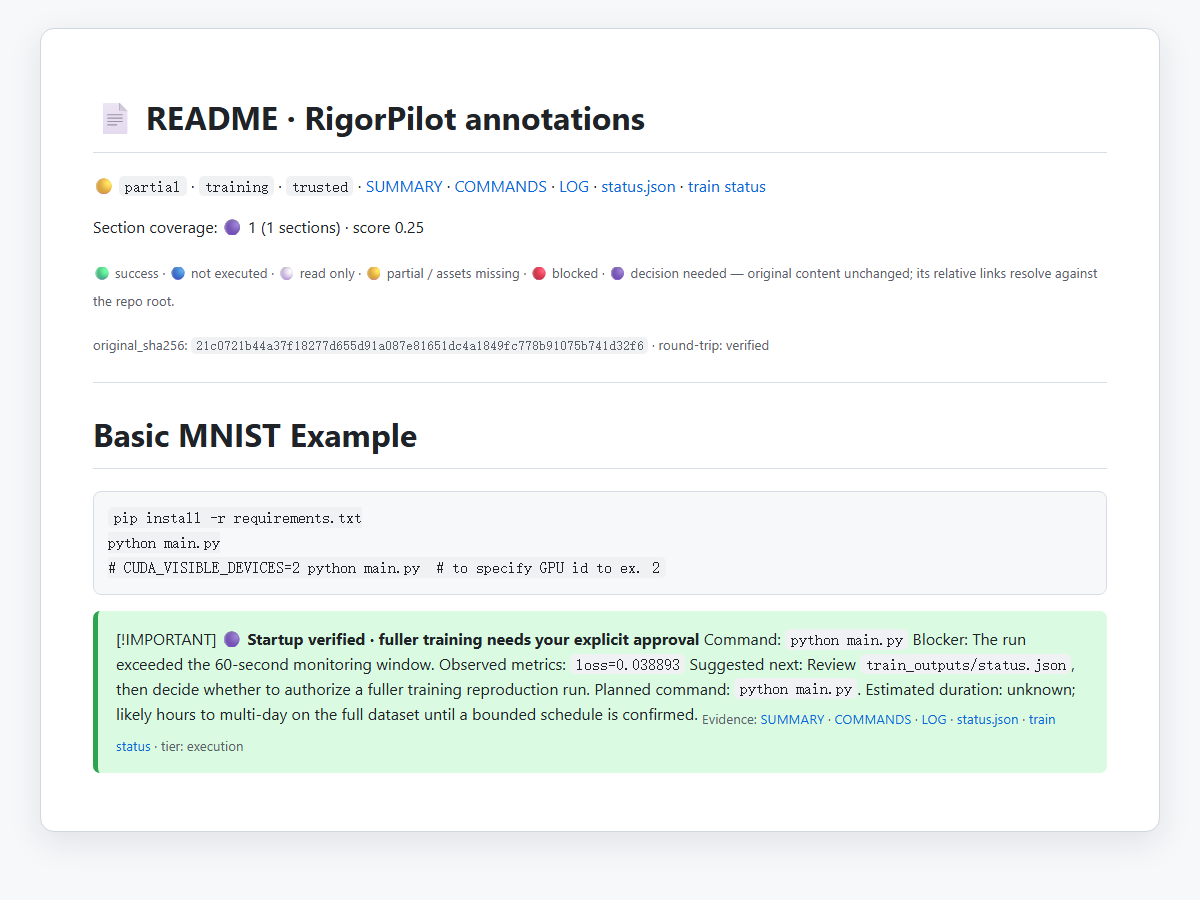
PyTorch MNIST · bounded startup
🟡 Partial training · observed loss 0.0388931 heading = 1 annotation · original bytes preserved
Open full RigorPilot README →
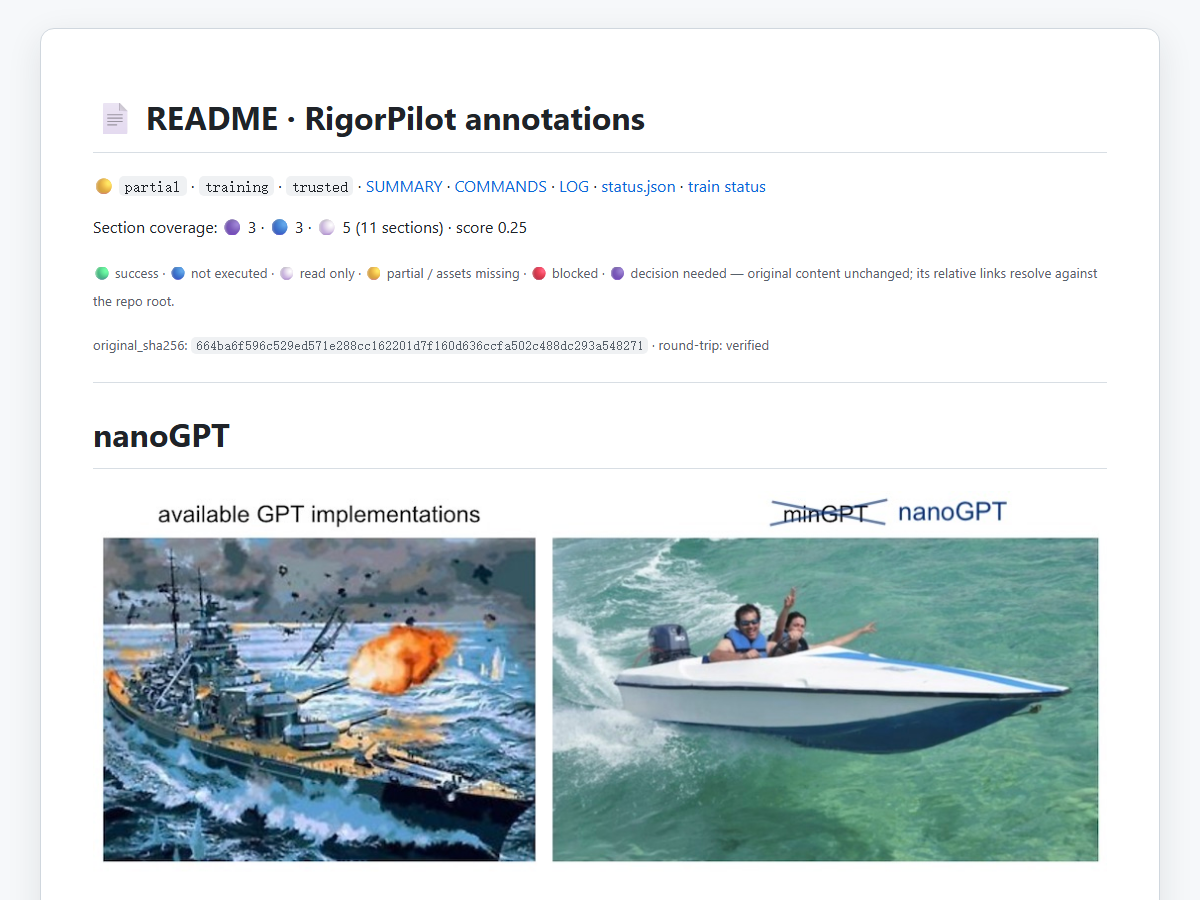
nanoGPT Shakespeare · bounded training
🟡 Partial · train loss 4.1676 · validation loss 4.164911 headings = 11 annotations · original bytes preserved
Open full RigorPilot README →
All four cases and upstream links ·
Recorded suite ·
Case definitions · Methodology
These are historical, commit-pinned deterministic runs: 4/4 case protocols
passed in 251.0 s, with a peak workspace of 98.67 MiB and 0 model API calls.
The zero-API count applies only to that suite. Selection-only and partial cases
are not completed evaluations, converged training or reproduced paper scores.
New: installed-skill micrograd trial, with before/after command reports, a retained failed attempt and independent checks—not a model-quality comparison.
Current acceptance: explicit named-skill and fresh-client natural-language AUTO both pass end to end; earlier failures remain retained and A/B/model uplift remain unrun. Compact status · real-client evidence
🚀 Install and use
The installer needs Node.js/npm. Tested with skills@1.5.26 and Node 22.20.0;
that installer requires Node ≥22.20.0. If you see EBADENGINE, check the requested version.
Install the self-contained reproduction skill:
npx skills add lllllllama/RigorPilot-Skills --skill ai-research-reproduction
Install all skills for the companion research entrypoints:
npx skills add lllllllama/RigorPilot-Skills --all
These commands use the current GitHub repository name.
Open the target repository in a Skills-capable agent, then ask:
Use ai-research-reproduction: run the smallest README-documented evaluation, preserve the source and write evidence to repro_outputs/, plus an annotated copy beside the original README. Ask before large downloads or long training.
The main skill works alone; choose all skills for companion and leaf entrypoints.
Your existing agent loads the skill. The standalone model runner is optional.
Client compatibility
Recommended first run:
| Step | What it does | What it does not do |
|---|
| Plan | Lists README-backed cmd-XX candidates, selects the smallest trusted target, and returns a selection fingerprint | No target execution, installs, downloads, source edits or evidence writes |
| Run | Executes a reviewed command-id bound to that plan fingerprint and writes evidence under the target repo by default | Setup/download commands cannot be selected; a changed plan fails before target execution |
| Verify | Rechecks the retained evidence, README round trip, runtime state and current source snapshot | Does not rerun the target command |
Start with the RIGORPILOT_README.md reported in source_adjacent_readme.path,
then follow its command and log links. If a conflicting file blocks the extra
copy, that file stays intact; inspect repro_outputs/SUMMARY.md for the outcome
and next action.
What it does—and does not do
README → documented target → reviewed setup → bounded execution → verification → evidence.
- Preserves source meaning; records assumptions, deviations, failures and blockers.
- Records process state, logs and attempt lineage; supports explicit cancellation,
recovery and retry through the persistent runtime.
- Separates trusted reproduction from explicitly authorized, candidate-only exploration.
- Checks execution criteria independently of the model's completion claim.
This is local execution, not an OS sandbox. Approved commands can access the
host and network; use trusted repositories. Resource admission and between-action
budget checks are not hard OS quotas or subscription-balance monitoring.
The optional model loop currently supports Anthropic Messages and reviewed command
IDs, not unrestricted source repair. This standalone runner has no successful
live-model acceptance recorded yet: three provider attempts returned HTTP 502. Other model profiles
are metadata, not proof of working transports or equivalent model performance.
Runner and recovery contract ·
Implementation evidence and limits
🎯 Skill index
Two helpers support orchestration: repo-intake-and-plan and paper-context-resolver.
Exploration requires a durable current_research anchor and a frozen comparison
contract. Candidate results never become trusted baseline results by declaration.
Routing · Research loop ·
Campaign inputs
📦 Evidence bundle
| Artifact | What to inspect |
|---|
repro_outputs/ANNOTATED_README.md | Original README with inserted section verdicts |
SUMMARY.md, COMMANDS.md, LOG.md, status.json | Outcome, exact commands, reviewed selection provenance, stable error.code, observations and machine-readable status |
invocation.json, evidence_manifest.json | Invocation/source-integrity summary plus retained file sizes and SHA-256 hashes for local consistency checks |
PATCHES.md, SCIENTIFIC_CHANGELOG.md, COMPARABILITY_REPORT.md | Changes, scientific meaning and comparison boundaries |
_runtime/<run_id>/ | Process state, events, resource samples and stdout/stderr |
.repro_job/ | Optional short-call supervisor: frozen request, reusable receipt, phase logs and completion-time verification |

 @lllllllama



