
AI code reviews grounded in twelve classic engineering books.
Consistent. Traceable. Actionable.
English ·
简体中文 ·
繁體中文 ·
日本語 ·
한국어 ·
Español
Quick Start •
The Six Decay Risks •
What It Looks Like •
Benchmark •
Installation


→ Visit the website
"The bearing of a child takes nine months, no matter how many women are assigned."
— Frederick Brooks, The Mythical Man-Month (1975)
50 years later, Brooks was still right — and so were McConnell, Fowler, Martin, Hunt & Thomas, Evans, Ousterhout, Winters, Meszaros, Osherove, Feathers, and the Google Testing team.
Most code quality tools count lines and cyclomatic complexity. brooks-lint goes deeper — it diagnoses your code against six decay risk dimensions synthesized from twelve classic engineering books, producing structured findings with book citations, severity labels, and concrete remedies every time.
For the full source-to-skill mapping, including exceptions and false-positive guards, see
skills/_shared/source-coverage.md.
Quick Start
# Claude Code
/plugin marketplace add hyhmrright/brooks-lint
/plugin install brooks-lint@brooks-lint-marketplace

# Any other Agent Skills platform — Cursor · Codex · Gemini · Copilot · Windsurf · OpenCode · Kiro · Bob …
curl -fsSL https://raw.githubusercontent.com/hyhmrright/brooks-lint/main/scripts/install.sh | bash -s -- <platform>
Then just ask ("review this PR", "audit the architecture"), or run one of the six commands —
/brooks-review, /brooks-audit, /brooks-debt, /brooks-test, /brooks-health, /brooks-sweep
(what each one does).
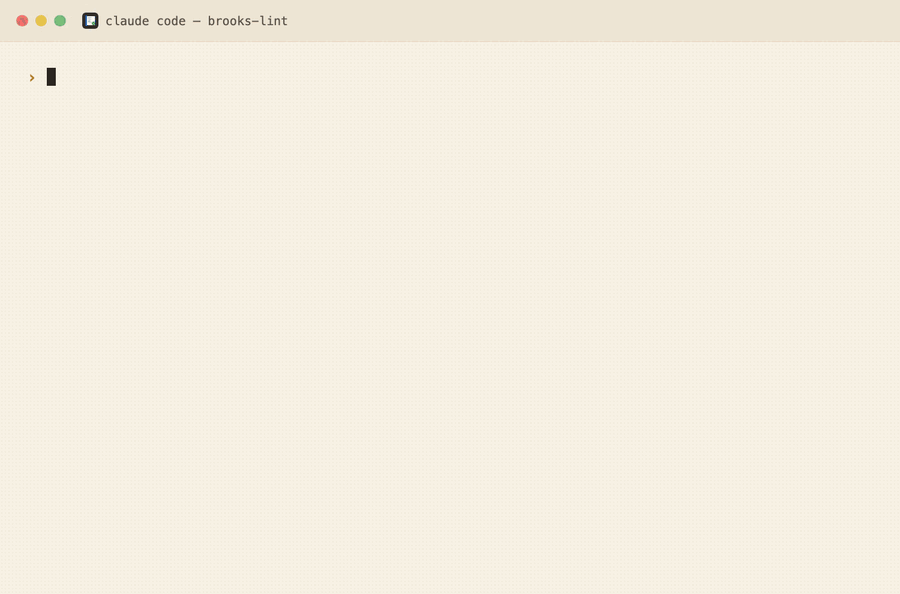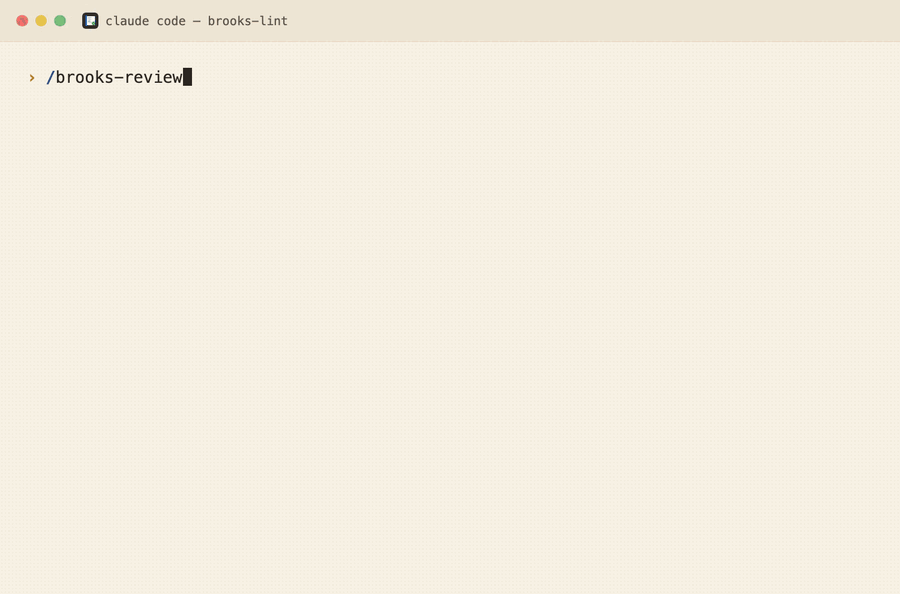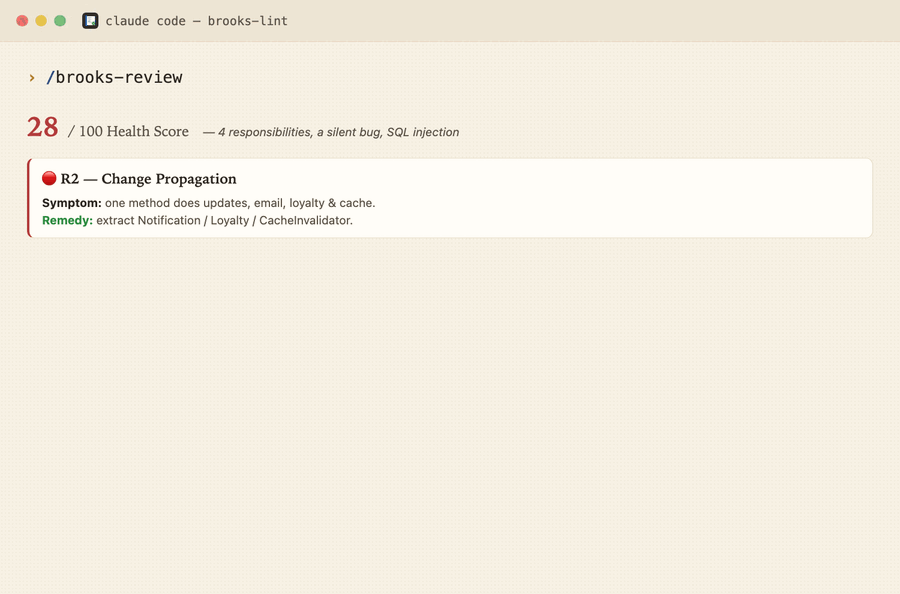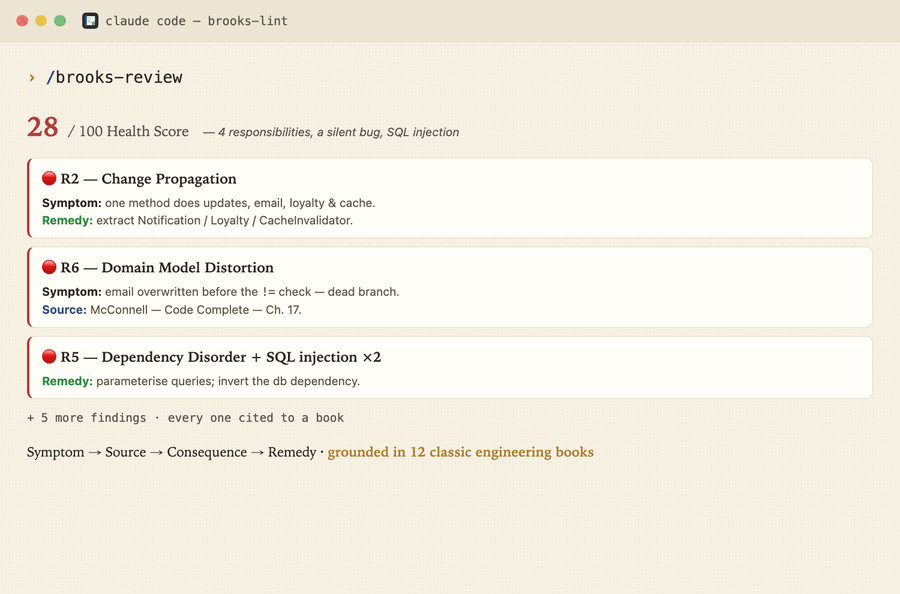
Every finding comes back as Symptom → Source → Consequence → Remedy with a book citation and a
0–100 Health Score. Full install options (10 more platforms) and CI/CD setup are below.
The Twelve Books
| Book | Author | Contributes to |
|---|
| The Mythical Man-Month (1975) | Frederick P. Brooks Jr. | R2, R4, R5 |
| Code Complete (1993, 2nd ed. 2004) | Steve McConnell | R1, R4 |
| Refactoring (1999, 2nd ed. 2018) | Martin Fowler | R1, R2, R3, R4, R6 |
| Clean Architecture (2017) | Robert C. Martin | R2, R5 |
| The Pragmatic Programmer (1999, 20th Anniv. 2019) | Andrew Hunt & David Thomas | R2, R3, R4, R5, T2, T3 |
| Domain-Driven Design (2003) | Eric Evans | R1, R3, R6 |
| A Philosophy of Software Design (2018) | John Ousterhout | R1, R4 |
| Software Engineering at Google (2020) | Winters, Manshreck & Wright | R2, R5 |
| The Art of Unit Testing (2009, 3rd ed. 2023) | Roy Osherove | T1, T2, T4, T5 |
| How Google Tests Software (2012) | Whittaker, Arbon & Carollo | T5, T6 |
| Working Effectively with Legacy Code (2004) | Michael Feathers | T4, T5, T6 |
| xUnit Test Patterns (2007) | Gerard Meszaros | T1, T2, T3, T4 |
The Six Decay Risks
brooks-lint evaluates your code across six production-code decay risks and six test-suite decay risks synthesized from twelve classic engineering books:
| Decay Risk | Diagnostic Question | Sources |
|---|
| 🧠 Cognitive Overload | How much mental effort to understand this? | Code Complete, Refactoring, DDD, Philosophy of SD |
| 🔗 Change Propagation | How many unrelated things break on one change? | Refactoring, Clean Architecture, Pragmatic, SE@Google |
| 📋 Knowledge Duplication | Is the same decision expressed in multiple places? | Pragmatic, Refactoring, DDD |
| 🌀 Accidental Complexity | Is the code more complex than the problem? | Refactoring, Code Complete, Brooks, Philosophy of SD |
| 🏗️ Dependency Disorder | Do dependencies flow in a consistent direction? | Clean Architecture, Brooks, Pragmatic, SE@Google |
| 🗺️ Domain Model Distortion | Does the code faithfully represent the domain? | DDD, Refactoring |
Philosophy of SD = A Philosophy of Software Design (Ousterhout) · SE@Google = Software Engineering at Google (Winters et al.)
What It Looks Like
Given this code:
class UserService:
    def update_profile(self, user_id, name, email, avatar_url):
        user = self.db.query(f"SELECT * FROM users WHERE id = {user_id}")
        user['email'] = email
        ...
        if user['email'] != email:   # always False — silent bug
            self.smtp.send(...)
        points = user['login_count'] * 10 + 500
        self.db.execute(f"UPDATE loyalty SET points={points} WHERE user_id={user_id}")
brooks-lint produces:
Health Score: 28/100
This method concentrates four unrelated business responsibilities into a single function, contains a logic bug that silently suppresses email change notifications, and is wide open to SQL injection.
🔴 Change Propagation — Single Method Changes for Four Unrelated Business Reasons
Symptom: update_profile performs profile field updates, email change notifications, loyalty points recalculation, and cache invalidation all in one method body.
Source: Fowler — Refactoring — Divergent Change; Hunt & Thomas — The Pragmatic Programmer — Orthogonality
Consequence: Any change to the loyalty formula risks breaking email notifications and vice versa. Every edit carries regression risk across four unrelated domains simultaneously.
Remedy: Extract NotificationService, LoyaltyService, and UserCacheInvalidator. UserService.update_profile should orchestrate by calling each — it should hold no implementation logic itself.
🔴 Domain Model Distortion — Silent Logic Bug: Email Notification Never Fires
Symptom: user['email'] = email overwrites the old value before if user['email'] != email — the condition is always False. The notification is dead code.
Source: McConnell — Code Complete — Ch. 17: Unusual Control Structures
Consequence: Users are never notified when their email address changes. Silent data integrity failure — the system appears functional while violating a business rule.
Remedy: Capture old_email = user['email'] before any mutation. Compare against old_email, not user['email'].
(+ 6 more findings including SQL injection, dependency disorder, magic numbers)
Architecture Audit with Dependency Graph
In Mode 2 (Architecture Audit), brooks-lint generates a Mermaid dependency graph at the top of the report. Modules are color-coded by severity: red = Critical findings, yellow = Warning, green = clean.
graph TD
    subgraph src/api
        AuthController
        UserController
    end
    subgraph src/domain
        UserService
        OrderService
    end
    subgraph src/infra
        Database
        EmailClient
    end

    AuthController --> UserService
    UserController --> UserService
    UserController --> OrderService
    OrderService --> UserService
    OrderService --> EmailClient
    UserService --> Database
    EmailClient -.->|circular| OrderService

    classDef critical fill:#ff6b6b,stroke:#c92a2a,color:#fff
    classDef warning fill:#ffd43b,stroke:#e67700
    classDef clean fill:#51cf66,stroke:#2b8a3e,color:#fff

    class OrderService,EmailClient critical
    class AuthController warning
    class UserService,UserController,Database clean
The graph renders natively in GitHub, Notion, and other Markdown environments — no extra tools needed.
See More Examples
The Full Gallery has real brooks-lint output across Python, TypeScript, Go, and Java — including PR reviews, architecture audits with Mermaid dependency graphs, tech debt assessments, and test quality reviews.
New to the decay risks? The Decay Risk Field Guide explains all six — diagnostic question, signature symptoms, source books, and remedy for each.
Benchmark
Tested across 3 real-world scenarios (PR review, architecture audit, tech debt assessment):
| Criterion | brooks-lint | Claude alone |
|---|
| Structured findings (Symptom → Source → Consequence → Remedy) | ✅ 100% | ❌ 0% |
| Book citations per finding | ✅ 100% | ❌ 0% |
| Severity labels (🔴/🟡/🟢) | ✅ 100% | ❌ 0% |
| Health Score (0–100) | ✅ 100% | ❌ 0% |
| Detects Change Propagation | ✅ 100% | ✅ 100% |
| Overall pass rate | 94% | 16% |
The gap isn't what Claude can find — it's what it consistently finds, with traceable evidence and actionable remedies every time.
Reproducible benchmarks
The table above is illustrative. These numbers are deterministic and you can reproduce them locally:
Parser fidelity — SARIF export and the CI gates depend on parsing the model's Markdown report correctly. Against a frozen corpus of 30 real, model-generated reports spanning all six modes (evals/benchmark-corpus.json), each paired with an independently graded finding inventory (a separate model pass, spot-checked by hand), the shipped parser scores — run npm run benchmark:
| Metric (n = 30, frozen corpus) | Result |
|---|
| Exact severity-count match (parser vs. graded truth) | 30 / 30 |
| Risk-code precision / recall | 100% / 100% (56 finding-level codes, 0 FP / 0 FN) |
| Valid SARIF 2.1.0 emitted | 30 / 30 |
Because the parser is deterministic and the corpus is frozen, npm run benchmark gives everyone the same result, and npm test guards it as a regression. The corpus deliberately includes 9 false-positive / tradeoff reports (e.g. a ports-and-adapters design that looks like a dependency cycle) that must stay clean.
Scoring determinism — for a fixed finding set (2 Critical / 3 Warning / 1 Suggestion), the strictness presets produce exactly the scores their common.md table predicts: strict 34, balanced 54, legacy-friendly 74 — and only legacy-friendly leads with the top-three fixes.
Model quality — whether the model finds the right risks on real code is measured by the 58-scenario eval suite (evals/evals.json): npm run evals (structural) and npm run evals:live (live, needs ANTHROPIC_API_KEY).


 @hyhmrright



