project-brain
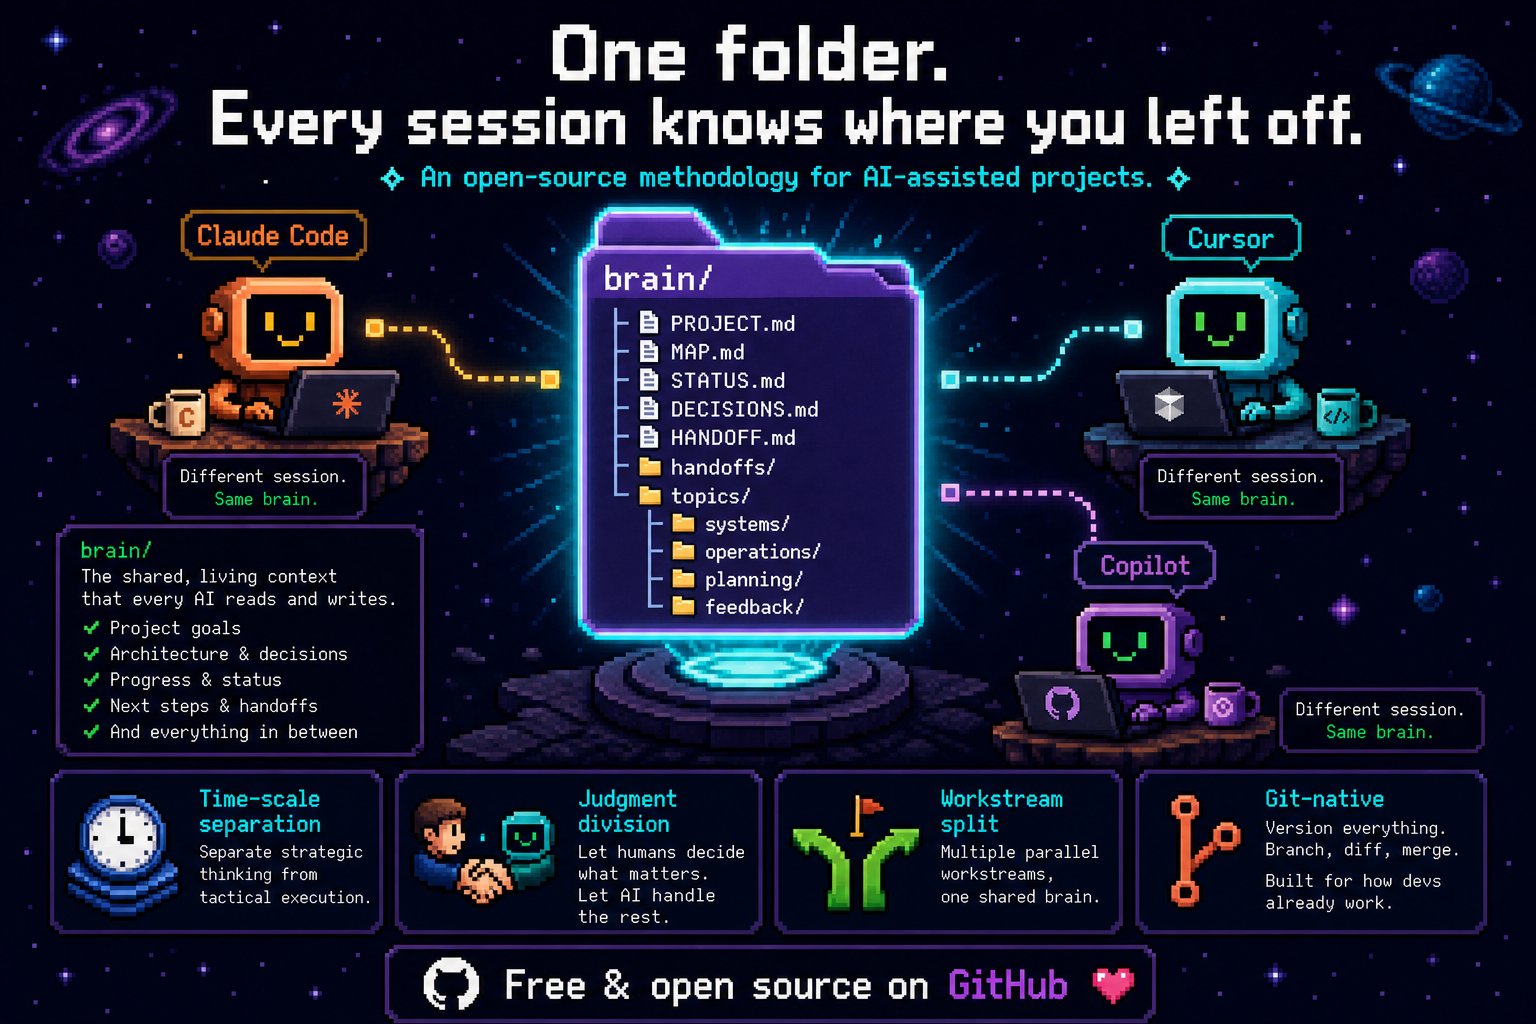
Different session. Same brain.
A folder structure + collaboration protocol that lets your AI assistant pick up a project after a context wipe — across new sessions, new windows, new collaborators.
中文版 →
Part of Sprout Labs — Local-first AI memory & agent safety, built independently by Ethan (Independent Product Designer & AI Builder, since 2016).
ethanflow.com · LinkedIn · @ethanflow_lab · GitHub

The problem
Long-running projects with AI coding assistants (Claude Code, Cursor, Copilot, etc.) hit a counter-intuitive wall:
Larger context windows don't solve the problem. Better information structure does.
A wider window doesn't mean it gets read. Read doesn't mean located. Located doesn't mean prioritized. Without structure, every new session starts with "wait, what's going on here?" — and the AI either reads too much (wasting tokens) or misses the critical pieces.
Symptoms you'll recognize:
- One README mixing project pitch + current status + decision history + how-to-run
- Sprawling docs where boundaries blur (one architecture file containing design + ops + history + bugs)
- Decisions buried in commit messages, chat logs, and footnotes — never traceable when you need them
- Cross-window handoff loses the "fresh stuff in your head" — the next session starts blind
- Projects running multiple parallel workstreams (e.g., dev + ops + outreach as three parallel streams) lose track of which session is on which line — switching between them re-orients from scratch every time
project-brain is a structural answer: a brain/ folder layout + a small set of protocols, designed so a fresh AI session can read 2-3 files and be productive.
Quick start
Option A — install as a Claude Code plugin (recommended for Claude Code users)
In Claude Code, run these two slash commands:
/plugin marketplace add Ethan-YS/project-brain
/plugin install project-brain@sprout-labs
If /plugin isn't exposed in your Claude Code environment (some embedded / SDK contexts strip it), the CLI form does the exact same thing — run from any terminal:
claude plugin marketplace add Ethan-YS/project-brain
claude plugin install project-brain@sprout-labs
That's it. From any project after that, just say:
- "set up project brain" — kick off a new brain
- "resume this project" — load
MAP.md + STATUS.md + (if exists) HANDOFF.md
- "I'm switching windows" / "context's getting full" / "hand off" — write a HANDOFF (a shift report) before context dies; works even before the project has a
brain/
- "update the project brain" — propose updates with reasons, you approve per item
The skill handles five workflows: new-project kick-off, startup resume, window-switch handoff (with a path for projects that have no brain/ yet), updates, and (in concurrent multi-workstream projects) handing work from one workstream to another. Auto-trigger requires an explicit user request — it intentionally does not activate just because a brain/ folder exists.
Already installed the old way? If you previously cloned to ~/.claude/skills/project-brain, remove it first: rm -rf ~/.claude/skills/project-brain. The plugin install is the supported path going forward.
Update later: /plugin marketplace update sprout-labs to fetch the latest version.
Option B — manual scaffold (works with any AI assistant)
If you don't use Claude Code, or you just want the scaffold script:
git clone https://github.com/Ethan-YS/project-brain.git

# Scaffold into your project (defaults to all four AI adapters, English)
./project-brain/scripts/scaffold.sh /path/to/your/project

# Or pick specific adapters:
./project-brain/scripts/scaffold.sh /path/to/your/project --tools claude,cursor

# For projects documented in Chinese — gives Chinese brain/ + CLAUDE.md
# (other adapters stay English — they're consumed by AI tools, not humans):
./project-brain/scripts/scaffold.sh /path/to/your/project --lang zh

# Fill in brain/PROJECT.md on day one
# Walk through ⚠️ TODO ⚠️ placeholders
What the scaffold gives you:
| File | Tool |
|---|
brain/ | The project brain (PROJECT/MAP/STATUS/DECISIONS/HANDOFF + topics/) |
CLAUDE.md | Claude Code instruction file |
.cursorrules | Cursor instruction file |
.github/copilot-instructions.md | GitHub Copilot Chat |
AGENTS.md | Codex CLI / Aider / Continue (AGENTS.md convention) |
When a new AI session opens your project, the auto-loaded instruction file directs it to read brain/MAP.md + brain/STATUS.md. If brain/HANDOFF.md exists, it reads the last shift's report: what to do first, what's waiting on others, what's still only in the last window's head.
Health check (any time after scaffolding)
./project-brain/scripts/doctor.sh /path/to/your/project
Read-only structural checks: missing core files, STATUS over 80 lines or ~6,000 characters, decisions without "rejected alternatives," topics/ files not registered in MAP, stale ⚠️ TODO ⚠️ placeholders, a HANDOFF that cites an archived one as still current, etc. Reports issues but never fixes them — that's still your call. See scripts/doctor.sh.
See a fully-filled example
If the empty templates feel abstract, see examples/small-saas/ — a fictional SaaS project ("Quill," a local-first notes app at v0.3) with every file filled in. Reading it is the fastest way to understand what each brain/ file looks like in real use.
Structure
brain/
├── PROJECT.md       What is this project? What do we explicitly NOT do?
├── MAP.md           Module structure + document index ("where do I find X?")
├── STATUS.md        Current state — overwritable, soft cap 80 lines / ~6,000 chars
├── DECISIONS.md     Decision log — append-only, requires "rejected alternatives"
├── HANDOFF.md       Shift report — first thing for the next window, waits, new traps, still-warm
├── handoffs/        Archive of past HANDOFFs (timestamped)
└── topics/          Per-problem-dimension docs
    ├── systems/      → "How is this designed?"
    ├── operations/   → "How do I operate it / what to do each release?"
    │   └── RUNBOOK.md  commands · health check · where to look · numbered traps (ships with the scaffold)
    ├── planning/     → "What are we going to build / how to plan it?"
    └── feedback/     → "What is reality / users telling us?"
Core principles
1. Time-scale separation
The five core files in brain/ are split by how often they change, not by topic:
| File | Volatility | When to read |
|---|
PROJECT.md | Almost never | First contact / scope ambiguous |
MAP.md | Slowly | Every new session |
STATUS.md | Frequently (per session) | Every new session |
DECISIONS.md | Append-only, event-driven | Tracing why something is the way it is |
HANDOFF.md | Per window-switch | New session start (if exists) |
Why volatility-based? Because mixing low-frequency content with high-frequency content forces the low-frequency content to be re-edited every session — the most common mode of doc rot.
2. Problem-dimension classification (not by module)
brain/topics/ is divided into 4 dimensions: systems / operations / planning / feedback. A single business module (say, "payment") has its design in systems/, deploy logs in operations/, pricing strategy in planning/, user feedback in feedback/.
Why? Modules grow, shrink, get renamed, get merged. The four problem dimensions are far more stable.
3. Decision logging requires "rejected alternatives"
Every entry in DECISIONS.md must include what was considered and rejected, and why. Without this, the file degrades into a worse version of CHANGELOG.md (which already records "what was done"). The unique value of decision logs is the paths not taken — that's where a project's judgment lives.
4. Judgment Division
When the user says "update the project brain":
- The user decides "should we record now" (high-level pacing instinct)
- The AI decides "specifically what to record / how to write each entry" (specialized understanding of how each file works)
- The user approves or rejects the AI's judgment
The AI should not push specialized judgments back ("which files do you want me to update?") — that hands the wrong layer of judgment to the wrong person.
Since v2.9.1, brain/ is written for the next window, not for the user (METHODOLOGY §4.1): the AI writes STATUS / HANDOFF / MAP registrations / RUNBOOK appends when the work lands — no asking, no reporting; the commit is the record. The one question it still asks, and only when it can't tell, is whether something is decided; DECISIONS / PROJECT follow the answer. The explicit "update the project brain" checkpoint above keeps per-item approval.
5. Multi-workstream mode (v2.1, optional)
Some projects naturally have parallel independent workstreams (e.g., development + operations + outreach in one product). For these, STATUS and HANDOFF split per workstream:
brain/
├── PROJECT.md           ← shared
├── MAP.md               ← shared
├── DECISIONS.md         ← shared
├── STATUS_dev.md        ← split per workstream
├── STATUS_ops.md
├── HANDOFF_dev.md
├── HANDOFF_ops.md
├── handoffs/
│   ├── dev/
│   └── ops/
└── topics/              ← shared
Single-workstream projects ignore this — they keep the default STATUS.md / HANDOFF.md.
Concurrent windows (v2.8): when several workstream windows run at the same time in one checkout, MAP §6 adds a "Who's on it now" roster — workstreams are durable, windows are disposable, so window names live only there and each new window claims its own row. The registry gains an "Owns" column; requests between workstreams are recorded in both STATUS files; and a short git discipline (shared staging area, stage your own hunks, edit shared files in place) helps keep windows from committing or erasing each other's work. See METHODOLOGY §3.6.
Why this exists — the evolution story
This methodology didn't appear from a design session. It evolved through real use across multiple projects — each iteration triggered by friction we hit and couldn't ignore.

 @mattpocock


