Dependency-Aware Structural Retrieval for Massive Agent Skills
Dawei Liu ·
Zongxia Li ·
Hongyang Du ·
Xiyang Wu ·
Shihang Gui ·
Yongbei Kuang ·
Lichao Sun


🔥 Updates
- [2026-08-20] 🎉 Graph of Skills is accepted to EMNLP 2026 Main Conference (Budapest). The camera-ready adds a component ablation, a budget-matched retrieval study, library-size scaling to 2,000 skills, and graph-construction diagnostics — all summarized in Results.
- [2026-04-15] Released a Claude Code MCP plugin for graph of skills retrieval — drop-in integration for Claude Code agents.
- [2026-04-07] Paper released on arXiv:2604.05333 and HuggingFace Papers.
- [2026-04-06] Code open-sourced on GitHub.
- [2026-04-04] Skill libraries, prebuilt workspaces, and benchmark data released on HuggingFace.
Overview
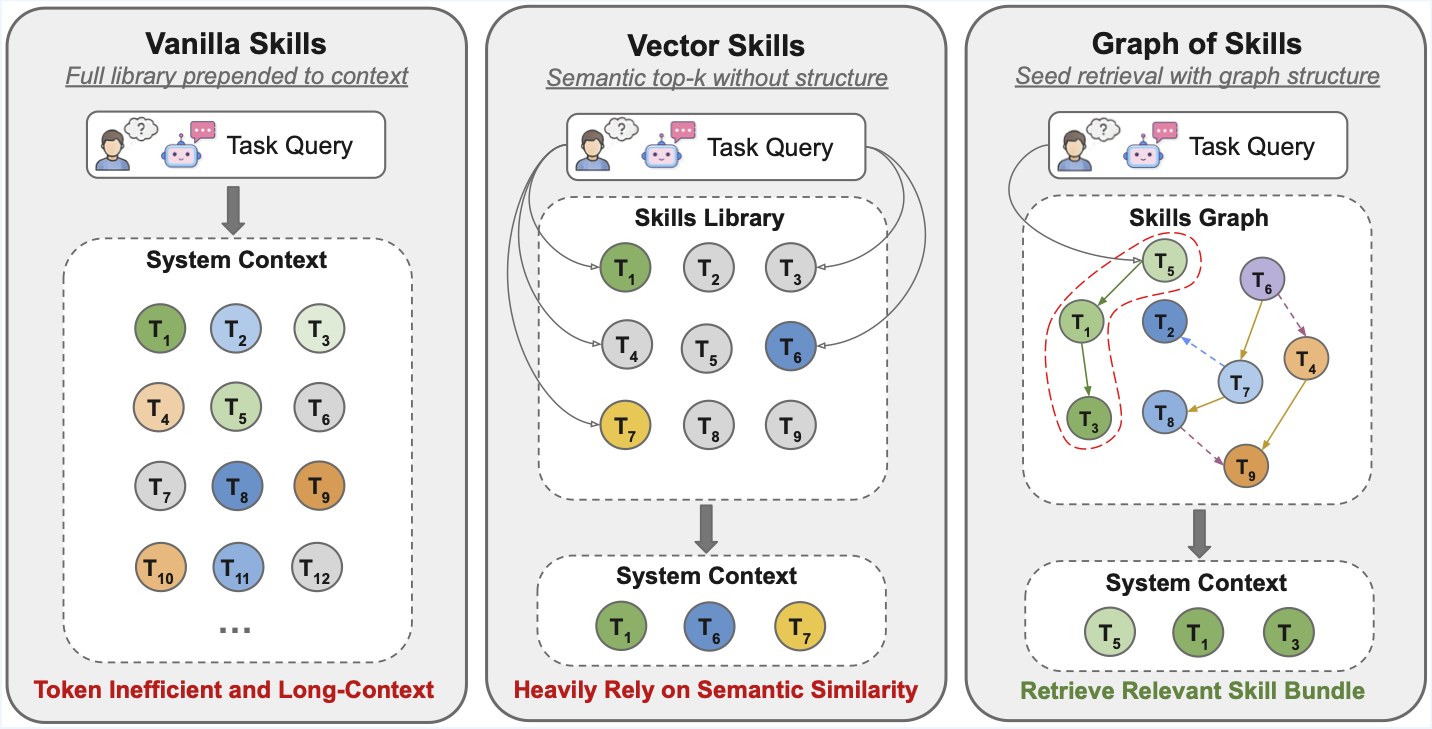
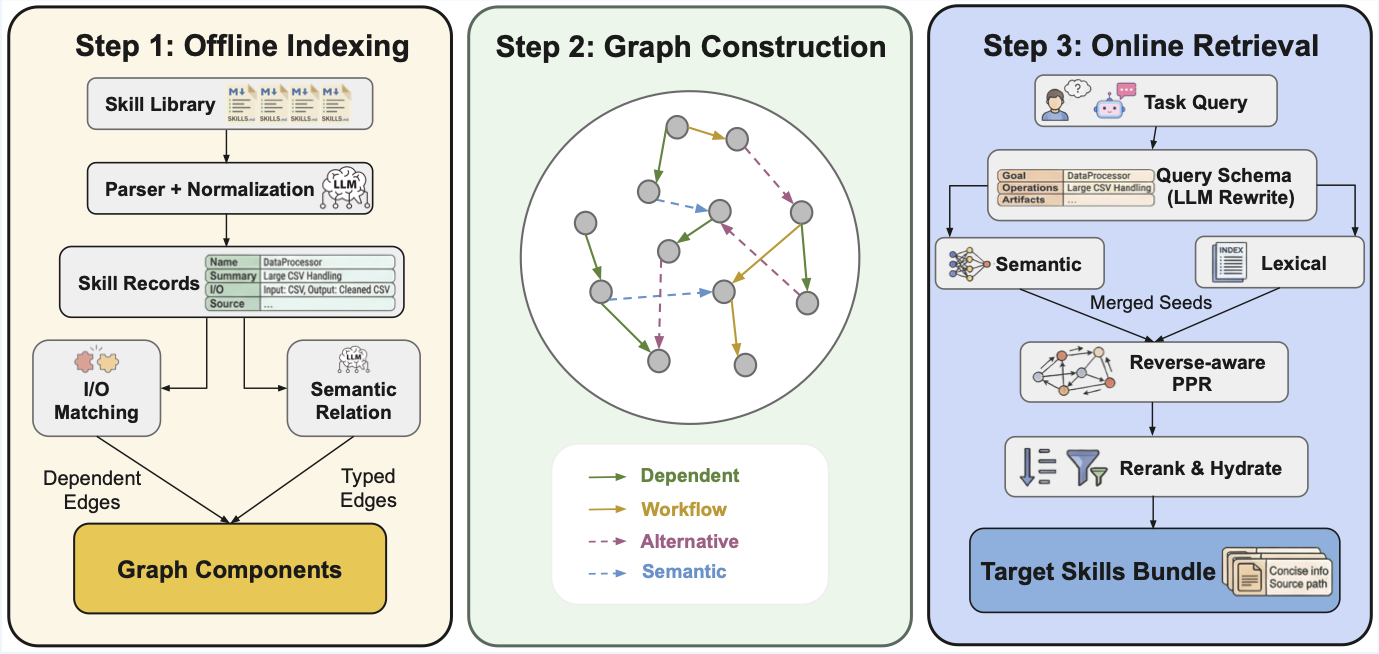
Graph of Skills builds a skill graph offline from a library of SKILL.md documents, then retrieves a small, ranked set of relevant skills at task time. Instead of flooding the agent context with an entire skill library, GoS surfaces only the skills most likely to help -- along with their prerequisites and related capabilities.
How It Works
Retrieval pipeline:
- Seed -- retrieve semantic candidates (embedding similarity) and lexical candidates (exact-match tokens)
- Merge -- combine both candidate pools
- Rerank -- rerank using the skill-graph structure (dependencies, co-occurrence)
- Return -- emit a capped, agent-readable skill bundle
Results
GoS is evaluated on SkillsBench (87 dockerized coding tasks) and ALFWorld (140 episodes) across three model families. R = average reward (%), T = average total tokens (uncached input + cached input + output), S = agent-only runtime (s). ↑ higher is better, ↓ lower is better. All numbers are means over two runs per setting.
Main results (end-to-end)
| Model | Method | SB R↑ | SB T↓ | SB S↓ | AW R↑ | AW T↓ | AW S↓ |
|---|
| Claude Sonnet 4.5 | Vanilla Skills | 25.0 | 967,791 | 465.8 | 89.3 | 1,524,401 | 53.2 |
| Vector Skills | 19.3 | 894,640 | 357.3 | 93.6 | 28,407 | 37.8 |
| GoS (ours) | 31.0 | 860,315 | 364.9 | 97.9 | 27,215 | 49.2 |
| MiniMax M2.7 | Vanilla Skills | 17.2 | 942,113 | 580.7 | 47.1 | 2,184,823 | 88.6 |
| Vector Skills | 10.4 | 852,881 | 552.9 | 50.7 | 66,109 | 73.4 |
| GoS (ours) | 18.7 | 867,452 | 502.5 | 54.3 | 65,227 | 68.8 |
| GPT-5.2 Codex | Vanilla Skills | 27.4 | 3,187,749 | 686.8 | 89.3 | 1,435,614 | 83.3 |
| Vector Skills | 21.5 | 1,243,648 | 773.0 | 92.9 | 34,436 | 57.0 |
| GoS (ours) | 34.4 | 1,379,773 | 715.6 | 93.6 | 46,462 | 64.7 |
GoS achieves the highest reward on every model on both benchmarks while cutting total tokens by up to 56× (ALFWorld, Claude Sonnet 4.5) vs. Vanilla Skills.
Scaling with library size
Reward and cost as the repository grows (SkillsBench, GPT-5.2 Codex). T in millions of tokens.
| Skills | Method | R↑ | T (M)↓ | S↓ |
|---|
| 200 | Vanilla Skills | 32.5 | 1.85 | 701.6 |
| Vector Skills | 21.2 | 1.06 | 833.8 |
| GoS (ours) | 32.1 | 1.36 | 731.2 |
| 500 | Vanilla Skills | 26.0 | 1.93 | 756.8 |
| Vector Skills | 20.7 | 1.10 | 849.5 |
| GoS (ours) | 31.4 | 1.16 | 890.3 |
| 1,000 | Vanilla Skills | 27.4 | 3.19 | 686.8 |
| Vector Skills | 21.5 | 1.24 | 773.0 |
| GoS (ours) | 34.4 | 1.38 | 715.6 |
| 2,000 | Vanilla Skills | 26.7 | 5.84 | 733.5 |
| Vector Skills | 23.8 | 1.11 | 799.8 |
| GoS (ours) | 31.3 | 1.14 | 788.0 |
From 500 skills onward GoS leads both baselines by 5.4, 7.0, and 4.6 reward points. Flat exposure rises from 1.93M to 5.84M tokens (~3x) across the same range while both retrievers stay near-constant — the scaling burden is in the prompt, not in retrieval.
Component ablation
Full SkillsBench, GPT-5.2 Codex, 1,000-skill library.
| Variant | R↑ | T (M)↓ | S↓ |
|---|
| Full GoS (reverse-aware PPR) | 34.4 | 1.38 | 715.6 |
| Forward-only PPR (γ_r = 0) | 25.3 | 1.20 | 742.7 |
| w/o graph propagation | 29.3 | 0.89 | 766.2 |
| w/o lexical + rerank | 26.7 | 1.01 | 747.7 |
Traversal direction matters more than the graph itself. Replacing reverse traversal with forward propagation costs 9.1 reward points — a larger loss than removing graph propagation entirely (5.1). The gain comes from traversing dependencies backwards, not from graph diffusion as such.
Isolating the graph operation
The table above compares full agent runs, which entangle the graph with hydration, reranking, and the agent interface. This budget-matched offline study holds seeding, reranker, top-N selection, character budgets, and hydration fixed across all arms, so only the graph operation changes (200-skill library, 87 queries).
| Retrieval operation | R_avail↑ | R_full↑ | C↑ | D↑ |
|---|
| Reverse-aware PPR (GoS) | 0.575 | 0.502 | 0.421 | 0.654 |
| Forward-only PPR (γ_r = 0) | 0.490 | 0.428 | 0.311 | 0.362 |
| No-Graph (matched flat) | 0.542 | 0.473 | 0.368 | 0.481 |
| One-Hop dependency | 0.542 | 0.473 | 0.368 | 0.481 |
R_avail / R_full = available- and full-oracle recall, C = exact bundle completeness, D = dependency-pair co-recovery. The same ordering reproduces at retrieval level: forward propagation is worse than not using the graph at all, and dependency-pair co-recovery falls from 0.654 to 0.362.
Construction cost and robustness
- One-time offline cost: $0.29 at 200 skills, $2.36 at 2,000. Online propagation adds ~1.5 ms at p50.
- Threshold is not delicate: sweeping the acceptance threshold ζ from 0.4 to 0.8 moves the deterministic edge count from 172 to 46 while changing recall by less than 0.005.
- Documentation quality is the main limiting factor: dropping half of all I/O fields costs 0.024 recall, whereas dropping half of the descriptions costs 0.146.
Citation
If you find this work useful, please cite the EMNLP 2026 version:
@inproceedings{liu2026graphofskills,
  title     = {Graph-of-Skills: Dependency-Aware Structural Retrieval for Massive Agent Skills},
  author    = {Liu, Dawei and Li, Zongxia and Du, Hongyang and Wu, Xiyang and
               Gui, Shihang and Kuang, Yongbei and Sun, Lichao},
  booktitle = {Proceedings of the 2026 Conference on Empirical Methods in Natural Language Processing (EMNLP)},
  year      = {2026}
}
arXiv preprint
@misc{liu2026graphofskillsarxiv,
  title         = {Graph-of-Skills: Dependency-Aware Structural Retrieval for Massive Agent Skills},
  author        = {Dawei Liu and Zongxia Li and Hongyang Du and Xiyang Wu and
                   Shihang Gui and Yongbei Kuang and Lichao Sun},
  year          = {2026},
  eprint        = {2604.05333},
  archivePrefix = {arXiv},
  primaryClass  = {cs.AI},
  url           = {https://arxiv.org/abs/2604.05333}
}
Installation
Requirements
- Python 3.10 -- 3.12
uv (recommended) or pip- An embedding API key (OpenAI, Gemini, or any OpenAI-compatible provider)
Setup
git clone https://github.com/davidliuk/graph-of-skills.git
cd graph-of-skills
uv sync
cp .env.example .env   # then fill in your API keys
Provider: OpenAI (direct)
OPENAI_API_KEY=sk-...
# Use the ``openai/...`` prefix so LiteLLM targets the OpenAI API (omit OPENAI_BASE_URL).
GOS_EMBEDDING_MODEL=openai/text-embedding-3-large
GOS_EMBEDDING_DIM=3072
OpenRouter exact-response caching is enabled by default for reproducible retries during
indexing (GOS_OPENROUTER_RESPONSE_CACHE=true). Cached responses must be disabled or
isolated when repeated graph builds are intended to measure LLM construction variance.
Provider: OpenRouter
OPENROUTER_API_KEY=<openrouter-key>
OPENAI_BASE_URL=https://openrouter.ai/api/v1
GOS_EMBEDDING_MODEL=openrouter/openai/text-embedding-3-large
GOS_EMBEDDING_DIM=3072
Provider: Azure AI (OpenAI-compatible)
OPENAI_API_KEY=<azure-api-key>
OPENAI_BASE_URL=https://YOUR-RESOURCE.services.ai.azure.com/openai/v1
# Must match your **deployment name** in Azure (not necessarily ``text-embedding-3-large``).
GOS_EMBEDDING_MODEL=openai/<your-deployment-name>
GOS_EMBEDDING_DIM=<vector-dimension-for-that-model>
Provider: Google Gemini
GEMINI_API_KEY=<your-key>
GOS_EMBEDDING_MODEL=gemini/gemini-embedding-001
GOS_EMBEDDING_DIM=3072
Quick Start
Goal: install the package, pull the published skill libraries, build (or download) a graph workspace, then run retrieval from the shell.
Read next: DATA.md for every download flag and asset size; .env.example for embedding providers. After GoS works locally, use evaluation/README.md for benchmark runners and evaluation/skillsbench/README.md for Harbor-based SkillsBench.
Step 0: Install (once per machine)
Complete Installation above: clone, uv sync, cp .env.example .env, and set embedding (and optional LLM) keys. Indexing and retrieval load .env from the repo root when you use uv run gos ….
Step 1: Download skill libraries
The collections skills_200, skills_500, skills_1000, skills_2000 are directories of SKILL.md files on HuggingFace, not in git. They unpack to:
data/skillsets/skills_200/ … data/skillsets/skills_2000/

 @obra


