

promptschat
Gives Claude Code access to the prompts.chat library, letting you search, retrieve and improve AI prompt templates, and find and install Agent Skills from its registry.
2 skills2 agents2 commands1 MCP+3+2+2+2+1+1+1+1175k
 @gh-f
Runs a set of reviewer skills over a text draft before it ships: skeptic, voice and identity, evidence calibration, and strategy checks, then synthesizes their critiques into one verdict that keeps their disagreements visible.
Claude Code
> /plugin marketplace add Avyayalaya/agent-council> /plugin install agent-council@agent-council
Codex
$ npx skills add Avyayalaya/agent-council -a codex
Cursor
$ npx skills add Avyayalaya/agent-council -a cursor
Gemini CLI
$ npx skills add Avyayalaya/agent-council -a gemini-cli
GitHub Copilot
$ copilot plugin marketplace add Avyayalaya/agent-council$ copilot plugin install agent-council@agent-council
OpenCode
$ npx skills add Avyayalaya/agent-council -a opencode
Windsurf
$ npx skills add Avyayalaya/agent-council -a windsurf
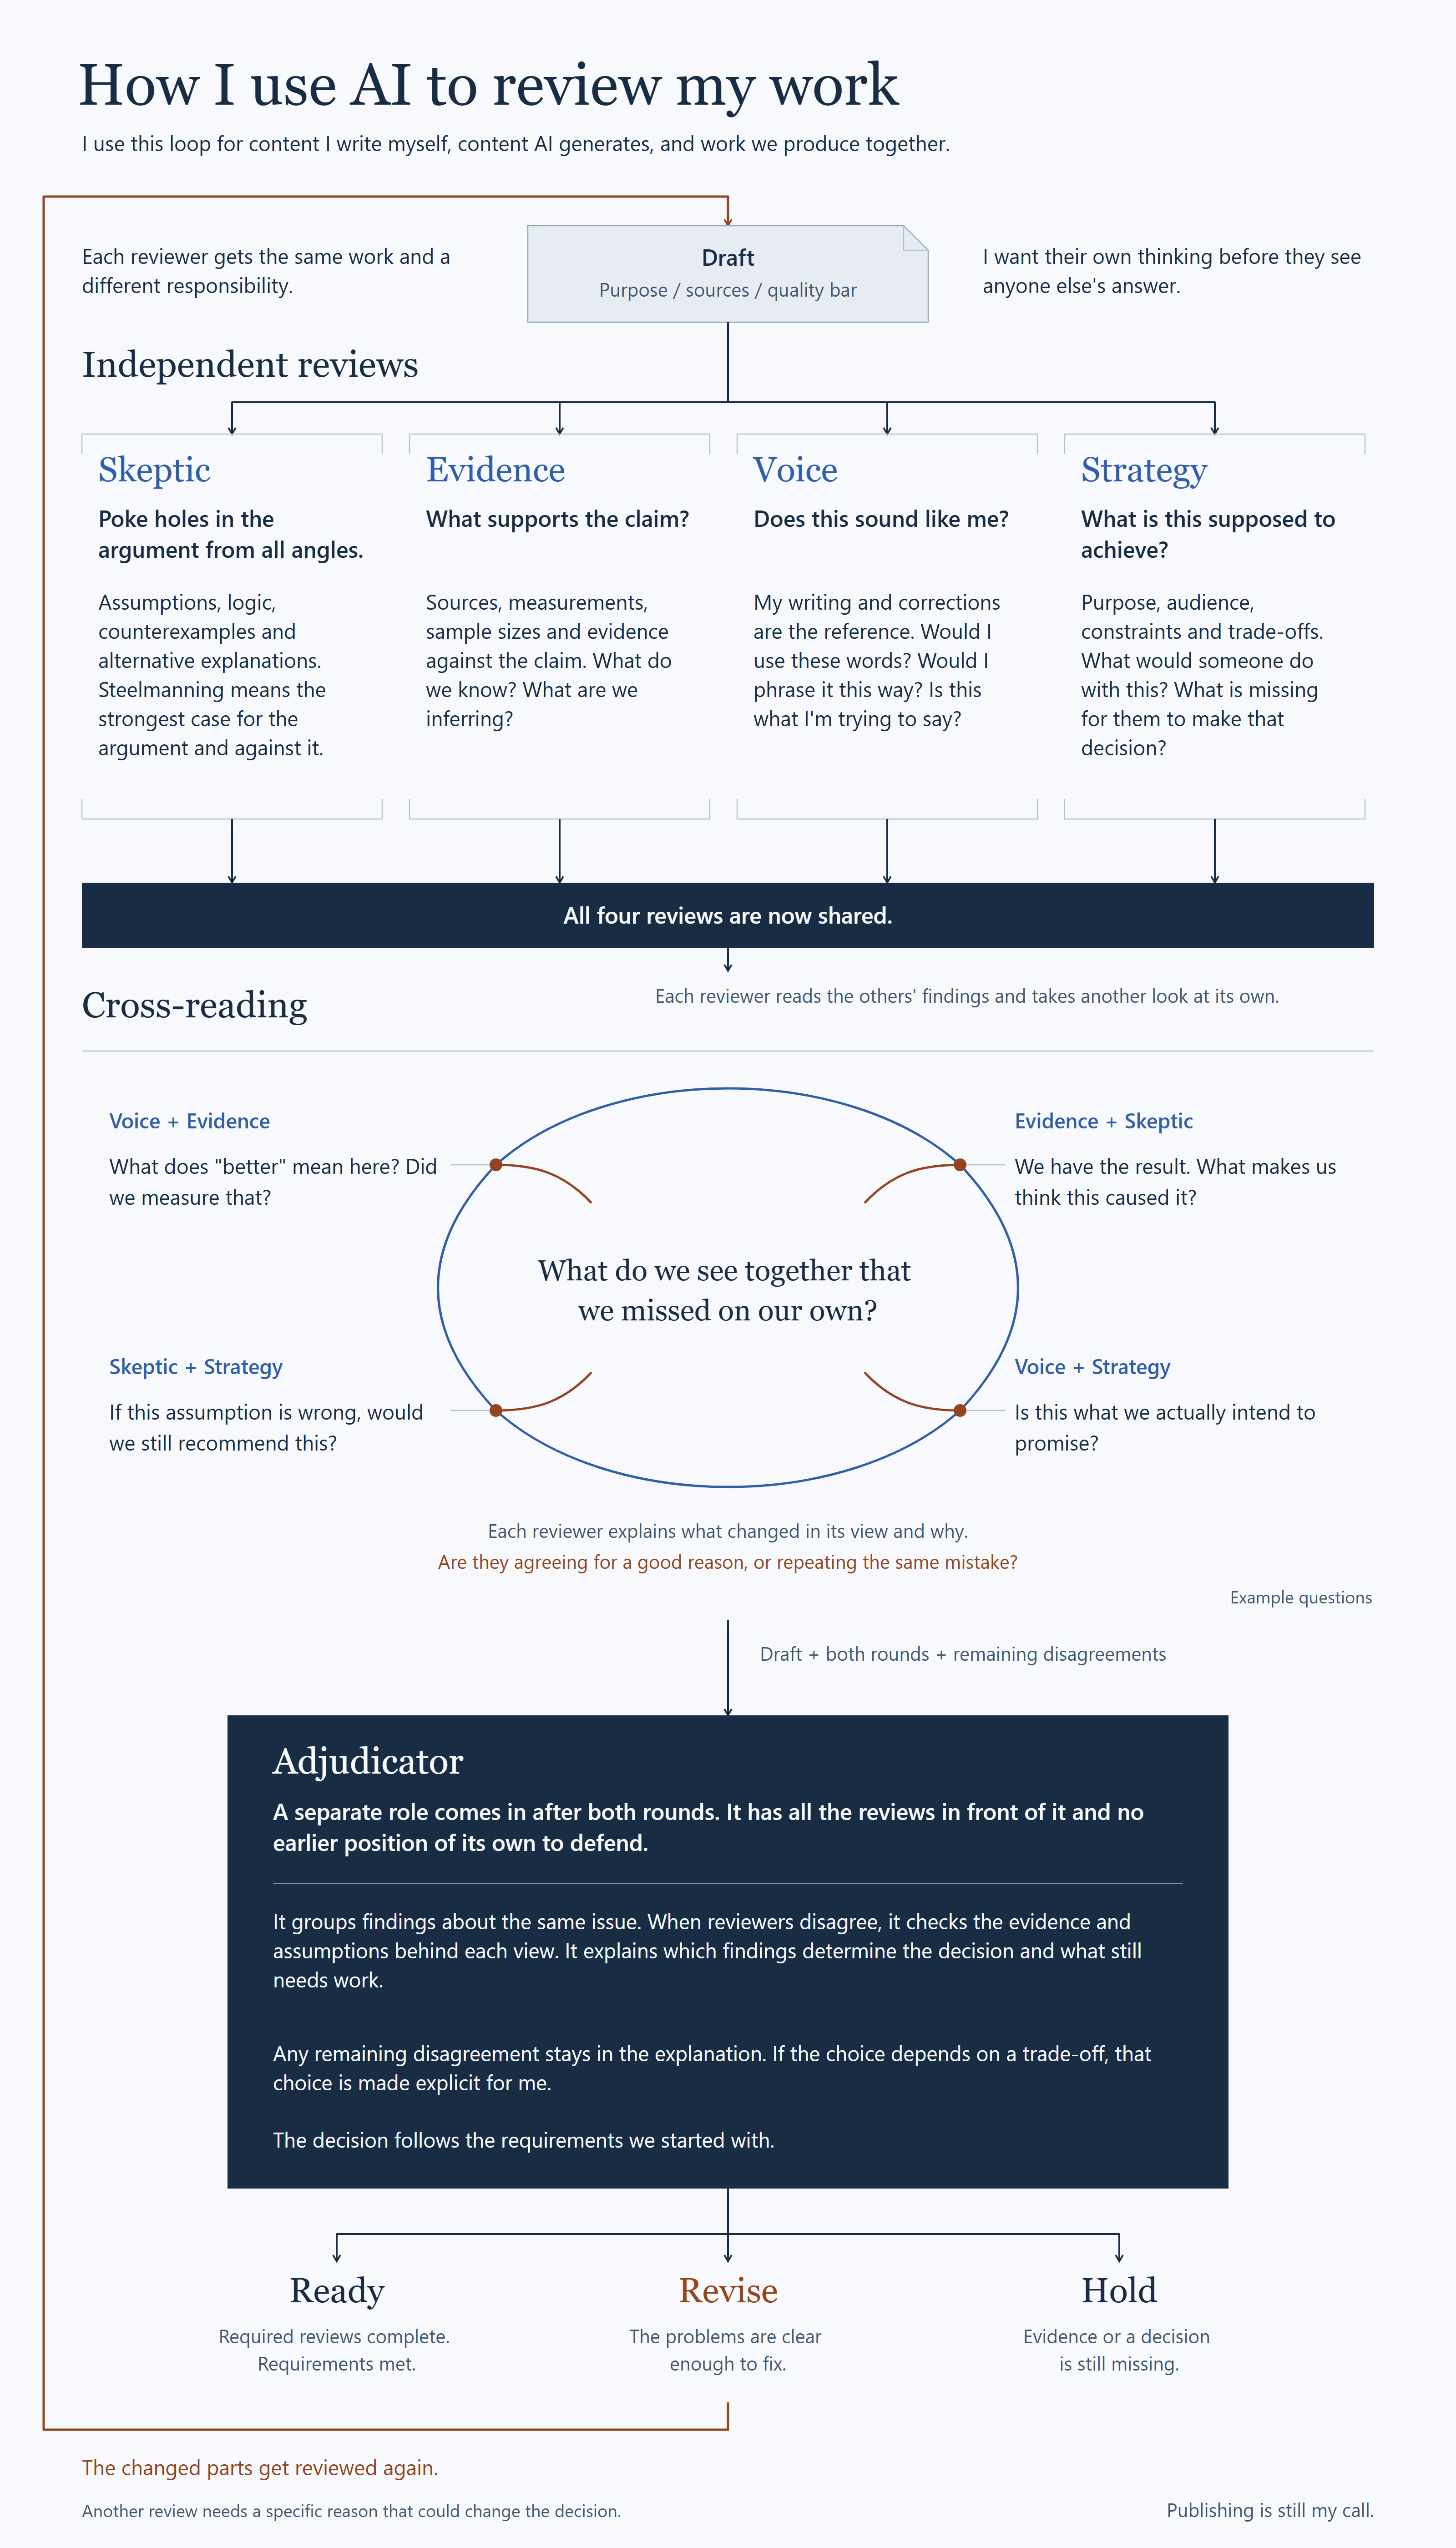


Four reviewers examine your work from distinct perspectives; a separate adjudicator turns their findings into a decision with reasons and required changes.
A runtime-portable review gate for text you write, AI generates, or you create together. Skeptic, Evidence, Voice, and Strategy review independently, then read the full first-round findings for one second review. A separate Adjudicator synthesizes both rounds and remaining disagreements. Code enforces the final SHIP, REVISE, HOLD, or INCOMPLETE result; the model recommendation cannot bypass that policy.
No required SDK or API key in the core package. Runtime adapters use a configured CLI (claude, ollama), LM Studio's HTTP server, or an offline mock. Provider authentication and model availability are still your responsibility. Producing agents need no Council dependency.
Personal research, separate from my day-job at Microsoft. MIT-licensed.
Install · How it works · Quickstart · Customize · AGENTS.md · CHANGELOG
claude plugin marketplace add Avyayalaya/agent-council
claude plugin install agent-council@avyayalaya
Then in any Claude Code session: /council-review path/to/artifact.md or /council-sweep.
git clone https://github.com/Avyayalaya/agent-council.git
cd agent-council
pip install -e .
cp council.yaml.example council.yaml  # then edit
python -m agent_council review path/to/artifact.md --tier=1 --config=council.yaml
Requires Python ≥3.11 and a configured runtime. mock_cli needs no model or external service.
pip install "mcp>=1.0"
Add to your client's MCP config:
{
  "mcpServers": {
    "agent-council": {
      "command": "python",
      "args": ["<absolute-path>/agent-council/mcp/agent_council_mcp_server.py"],
      "env": {
        "COUNCIL_CONFIG": "<absolute-path>/agent-council/council.yaml"
      }
    }
  }
}
Tool exposed: council_review(artifact_path, tier=1). Full setup: mcp/README.md. Use the Python CLI for sweep and audit.
v0.1.1 ships each deliberator as a standalone Skill under skills/ so any APM-compatible harness gets the methodology inline — no Python CLI required for single-perspective review.
apm marketplace add Avyayalaya/agent-council
apm install agent-council --target copilot
Then in the harness, load one Skill at a time:
skeptic-review — adversarial steelman passvoice-identity-review — line-level voice audit + CXO testevidence-calibration-review — per-claim T1-T6 evidence-tier auditstrategy-stakes-review — goal-fit and opportunity-cost checkadjudicator-synthesis — verdict synthesis from 2+ deliberator outputsUse cases per surface:
| Use case | Surface |
|---|---|
| Run full automated Council on an artifact with parallel deliberators + 2-round cross-read + JSONL audit | python -m agent_council review path/to/artifact.md --tier=1 --config=council.yaml or MCP council_review tool |
| Apply one deliberator role to a doc I am editing right now (Copilot, Claude, Cursor) | Load the matching Skill |
| Compose 2 or 3 deliberators ad-hoc for a multi-angle ad-hoc review | Load multiple Skills sequentially, then optionally load adjudicator-synthesis |
| Use slash commands in Claude Code | /council-review path/to/artifact.md (Claude Code only) |
The Skills are the interactive role-specific surface. The CLI / MCP is the automated full-Council surface with four reviewers and separate synthesis. Standalone Skills do not enforce the runtime's configured policy:
| Capability | Compose Skills sequentially | Full Council via CLI / MCP |
|---|---|---|
| One perspective at a time | yes | yes (the deliberators) |
| Parallel deliberator execution | no | yes |
| Round 2 cross-read (each reviewer sees all four R1 findings, including its own) | no | yes |
Adjudicator prior-verdict compounding loop on artifact_type | no | yes |
| JSONL audit log and archived transcripts | no | yes |
| Single synthesized decision | optional synthesis Skill | yes, with enforced policy |
| Structured, persisted verdict record per run | no | yes |
| Calls per review | harness-dependent | 9 on the default happy path; at most one schema reprompt per call |
| Sweet spot | Ad-hoc 1 or 2 perspectives on a doc you are editing | Pre-ship gating in pipelines; structured, persisted audit trail |
Sequentially composing review Skills can provide multiple perspectives and optional synthesis. It does not ensure independent first reads, run the two-round protocol, or enforce the Python verdict policy. Use the CLI / MCP path for those guarantees and persisted records.
Read the four reviewer prompts and the separate synthesis prompt at prompts/. For manual review, keep first reads separate and supply the actual policy to the adjudicator. The automated rules live in VerdictPolicy and merge_verdicts.
The default is two review rounds plus one synthesis, not a continuous debate or automatic revision loop. rounds: 1 disables R2. A later review is a new invocation chosen by the operator.
| Default policy | Result |
|---|---|
| Fewer than three schema-valid R1 reviews, or unusable synthesis | INCOMPLETE |
| Any participating valid-R2 irreducible flag, or at least three hard/soft blocks | Policy HOLD |
| No hard/soft blocks and every present score is at least 3 | Policy SHIP |
| Remaining cases, including a score of 2 or one/two blocks | Policy REVISE |
would_block is a hard block; a score at or below 1 counts as a soft block when that reviewer has no hard block. Valid R2 takes precedence; failed or disabled R2 falls back to valid R1. Failed R1 never counts toward quorum, even if R2 succeeds. The stricter of model recommendation and policy wins, except policy HOLD may become REVISE when the model recommends it and there is no participating irreducible dissent.
Schema failure triggers one reprompt; there are no additional runtime-error retries. Synthesis timeouts/runtime failures return audited INCOMPLETE. Review failures and R1 fallback are visible in the returned record and dissent summary. Missing actionable briefs are explicitly reported with available reviewer findings rather than invented fixes. See architecture for the output and failure contract.
The author's workflow for authored, AI-generated and co-created content. The diagram's "required reviews complete" standard and revise/review loop describe the personal workflow, not an exact executable state machine. This implementation retains a three-valid-R1 quorum and valid-R1 fallback when R2 fails; it does not require all four reviews in both rounds. Publishing remains the operator's decision.
Read the accompanying LinkedIn post.
| Role | Concern | Reads |
|---|---|---|
| Skeptic | Adversarial review — catches premature coherence, narrative fallacy, survivorship bias, unstated assumptions | (artifact only) |
| Voice & Identity | Voice DNA, banned-pattern enforcement, channel register, CXO test | Operator's voice corpus + persona DNA |
| Evidence & Calibration | Assess supplied support, evidence tiers (T1–T6), confidence and base rates; identify gaps | Artifact + optional supplied source/context text |
| Strategy & Stakes | Goal alignment, stake calibration, opportunity cost vs. operator's active projects | Operator's goals doc + project state |
| Adjudicator | Separate synthesis, recommendation and revision brief; runtime enforces final verdict | Both review rounds + prior verdict summaries |
A review needs to answer distinct questions:
A single judge can address multiple criteria too. Council makes the division of responsibility explicit and preserves who raised an issue, what changed after cross-reading, and what remains disputed. More reviewers or cross-reading do not establish better output: comparative quality is a hypothesis, not a demonstrated result in this repository.
This matters for tier-1 artifacts where the cost of shipping a flaw is high (public publish, irreversible commitment, identity-shaping document) and the cost of one more revision pass is low.
After pip install -e . and copying council.yaml.example → council.yaml:
# Single artifact
python -m agent_council review path/to/artifact.md --tier=1 --config=council.yaml --json

# Daily sweep over watch paths
python -m agent_council sweep --since=24h --config=council.yaml

# Audit recent verdicts
python -m agent_council audit --since=7d --log=council_log.jsonl
Review output is human-readable unless --json is supplied. Each completed protocol run, including structured failures, appends an audit row to the configured log. For an offline smoke review, use --config=tests/council.example.yaml with tests/sample_artifact.md; the shipped mock fixture returns REVISE (exit 1).
examples/demo/ ships a fictional LinkedIn post + the structured verdict the Council produced for it + the extracted revision brief. Read these first to calibrate expectations before running your first real review.
The Council is designed for tier-1 artifacts — the ones where review cost is justified:
Stars on GitHub
Gives Claude Code access to the prompts.chat library, letting you search, retrieve and improve AI prompt templates, and find and install Agent Skills from its registry.
@gh-fA Claude Code skill for generating editable PPTX presentations and slides from a workflow, with reusable brand, style, layout, and deck workspaces, native charts, speaker notes, and template filling.
 @hugohe3
Gives AI agents control over Word, Excel and PowerPoint files, with skills for building .docx reports, academic papers, Excel dashboards and Morph-style animated slides.
 @iofficeai
A skill that builds animation-rich HTML presentations from scratch or converts PowerPoint files to web slides. Useful for anyone turning a deck into a web presentation.
 @zarazhangrui
Runs a set of reviewer skills over a text draft before it ships: skeptic, voice and identity, evidence calibration, and strategy checks, then synthesizes their critiques into one verdict that keeps their disagreements visible. Install it with the command on its page. It includes adjudicator-synthesis, evidence-calibration-review, skeptic-review. Its skills do not fire on their own yet. Free and open source.
Is this plugin yours?
Claim it with GitHubSubmit a pluginPromote it