agent-vision-toolkit




What it thinks is what it sees — give any text-only coding agent eyes: image Q&A, long-screenshot OCR, frontend UI restoration, and GUI automation, as a vision toolkit plus a skill, with optional drop-in integration for Codex, Claude Code, Pi, Oh My Pi, and OpenCode.
🎯 An agent's vision capability doesn't have to live in the model — it can live in the harness.
🌐 中文 | English
If your agent already runs on a text-only model such as DeepSeek but is held back by the lack of multimodality — unable to see images, with every attempt to use an image tool blocked by the system — this repository provides tools, skills, and proxy integrations that let text-only models handle visual tasks on equal or even better footing. The goal is to make the experience of using a text-model agent as seamless as using a multimodal one, and ultimately let a tool-equipped text-model agent outperform a native multimodal agent that does not use this toolkit and its methods.
This repository provides two kinds of components:
- Vision tool CLIs — multiple CLIs, plus a skill that teaches the agent when to use each one. Any agent that can invoke a shell can use them.
- Seamless integration (optional upgrade) — a transparent local proxy and single-file native plugins, so images we paste and the agent's built-in image tools both work seamlessly, with no extra tool installation or additional prompting.
All code has been verified in real Codex + DeepSeek sessions, and the same pipeline has been live-verified end-to-end in Claude Code, Pi, Oh My Pi, and OpenCode.
If this project helps you or gives you some inspiration, feel free to star🌟 & fork.
❤️ Sponsor
Want to sponsor this project? See FUNDING.md or email davidyang042@gmail.com.
Click to collapse
Latest Update
2026-08-18 — Skill renamed: the included agent skill is now vision-skills (formerly vision-tools), so the name describes the capability rather than the underlying tools.
2026-08-13 — Native DeepSeek Harness support is now available. The new dsh-vision-toolkit linked package brings this toolkit into DSH Web and Headless profiles as a native Profile Bundle. It provides 10 structured visual tools for intent-aware image Q&A, grounding, detection, tracing, cropping, pixel diff, long-screenshot OCR, foreground extraction, dominant-color analysis, and HTML screenshots, while adding DSH Credentials, a managed isolated runtime, previewable Artifacts, Web Settings, and Agent-scoped progressive tool exposure.
The package is tracked here as a Git submodule and maintained independently at Anionex/dsh-vision-toolkit. Clone this repository with --recurse-submodules, or run git submodule update --init --recursive in an existing checkout.
Contents
- Latest Update
- Highlights
- Use-case Playbooks
- Real-world Effects
- Quick Start
- The Tools
- Upgrade: Seamless Integration
- How It Works
- Configuration
- FAQ
- Donation
- Community
- About
Highlights
- More than image descriptions — it captures what the LLM actually cares about: when viewing an image, it passes along the user's or model's latest intent, producing the details needed for the current turn instead of a broad, unfocused description.
- Both pasted images and built-in image tools work: the agent can understand images pasted directly as well as images opened through its built-in tools.
- A battle-tested methodology for visual tasks: the included skill teaches the agent what to inspect, which tool to choose, what sequence to follow, and how to verify the final result.
- One-sentence install: ask your agent to install it — it follows the verified flow end to end, toolkit, skill, and seamless integration included.
Use-case Playbooks
The included vision-skills skill contains complete examples that an agent can follow directly.
When to use them, the order in which to call tools, and how to verify the result are all documented in the corresponding skill guides:
| Use case | What the agent learns to do |
|---|
| Extract long screenshots, chat histories, and scrolling pages | Find low-content cut bands, OCR each chunk in order, preserve chat speakers/timestamps/quotes, merge only duplicated overlap, and surface risky boundaries for verification. See the Telegram reference run → |
| Rebuild a UI from a screenshot or design | Reuse project components and assets first, then combine code-native UI, extracted visuals, rendered screenshots, and visual comparison to align a page or component. |
| Restore an icon, logo, illustration, or other graphic | Extract a transparent PNG from the source image, or rebuild an editable/scalable SVG when needed, then verify shape, color, and alpha edges. |
| Turn a sketch, diagram, or whiteboard into structured code | Recover nodes, labels, connections, and directions as editable Mermaid, Graphviz, or another structured representation. |
| Operate a GUI from screenshots | Locate a control, perform one action, capture the screen again, and verify the resulting state before continuing. |
| More use cases | Other step-by-step visual-agent playbooks are being added gradually. |
Real-world Effects
Infographic restoration: screenshot to HTML in one sentence
Left: the original infographic screenshot. Right: an editable reconstruction built with HTML/CSS. View the HTML source →
UI restoration: sketch to interface in one sentence
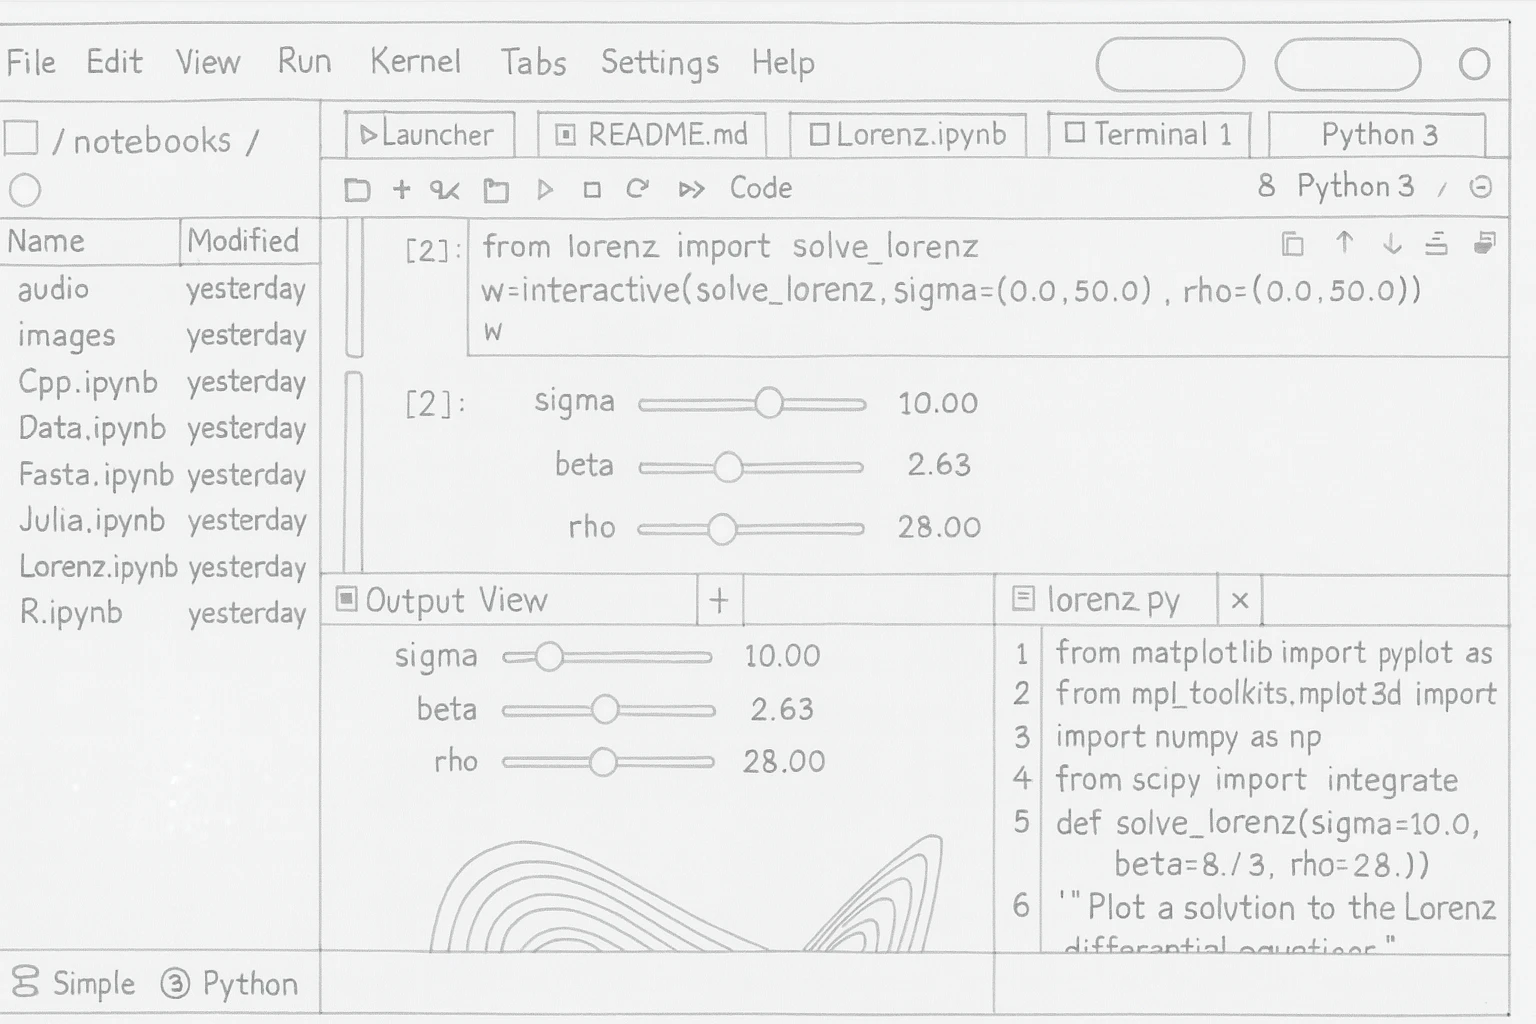
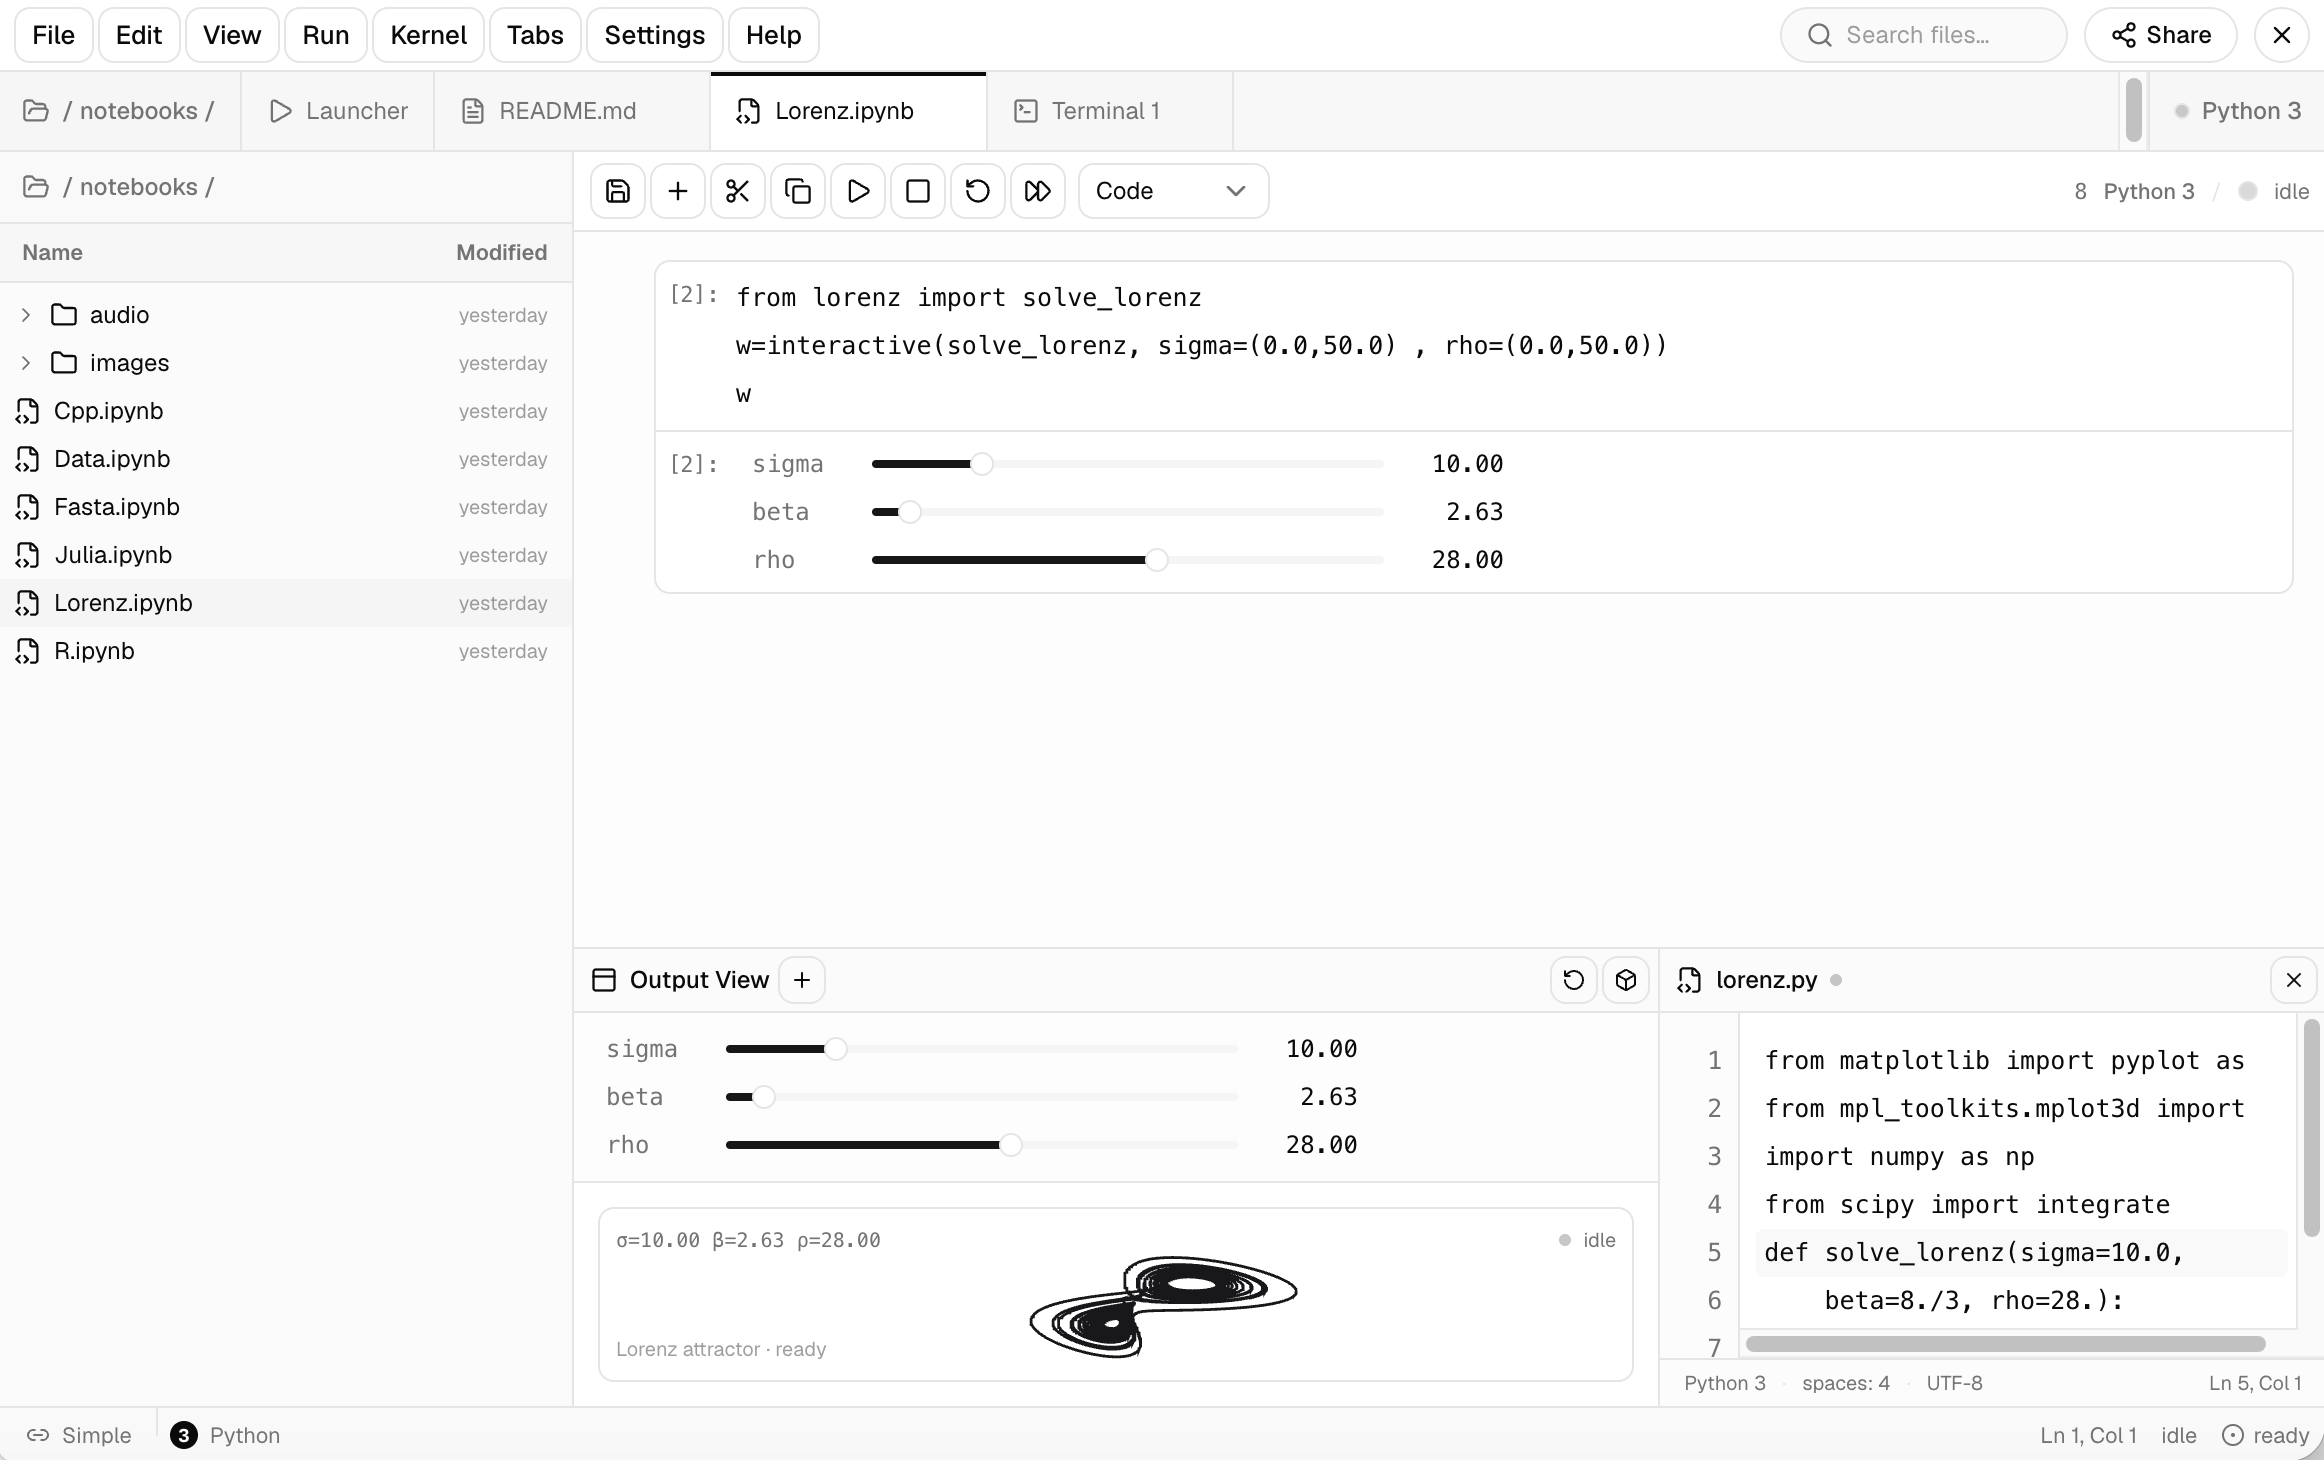
Left: the hand-drawn reference. Right: the restored JupyterLab workspace made from it. See the UI restoration playbook for the workflow. Executed in Codex with deepseek-v4-flash.
Fast UI restoration: an approximate first pass
Left: the original page. Right: a fast reconstruction that preserves the main layout, content, and visual hierarchy while allowing approximate colors and library icons. Fast mode targets a first screenshot in about three minutes.
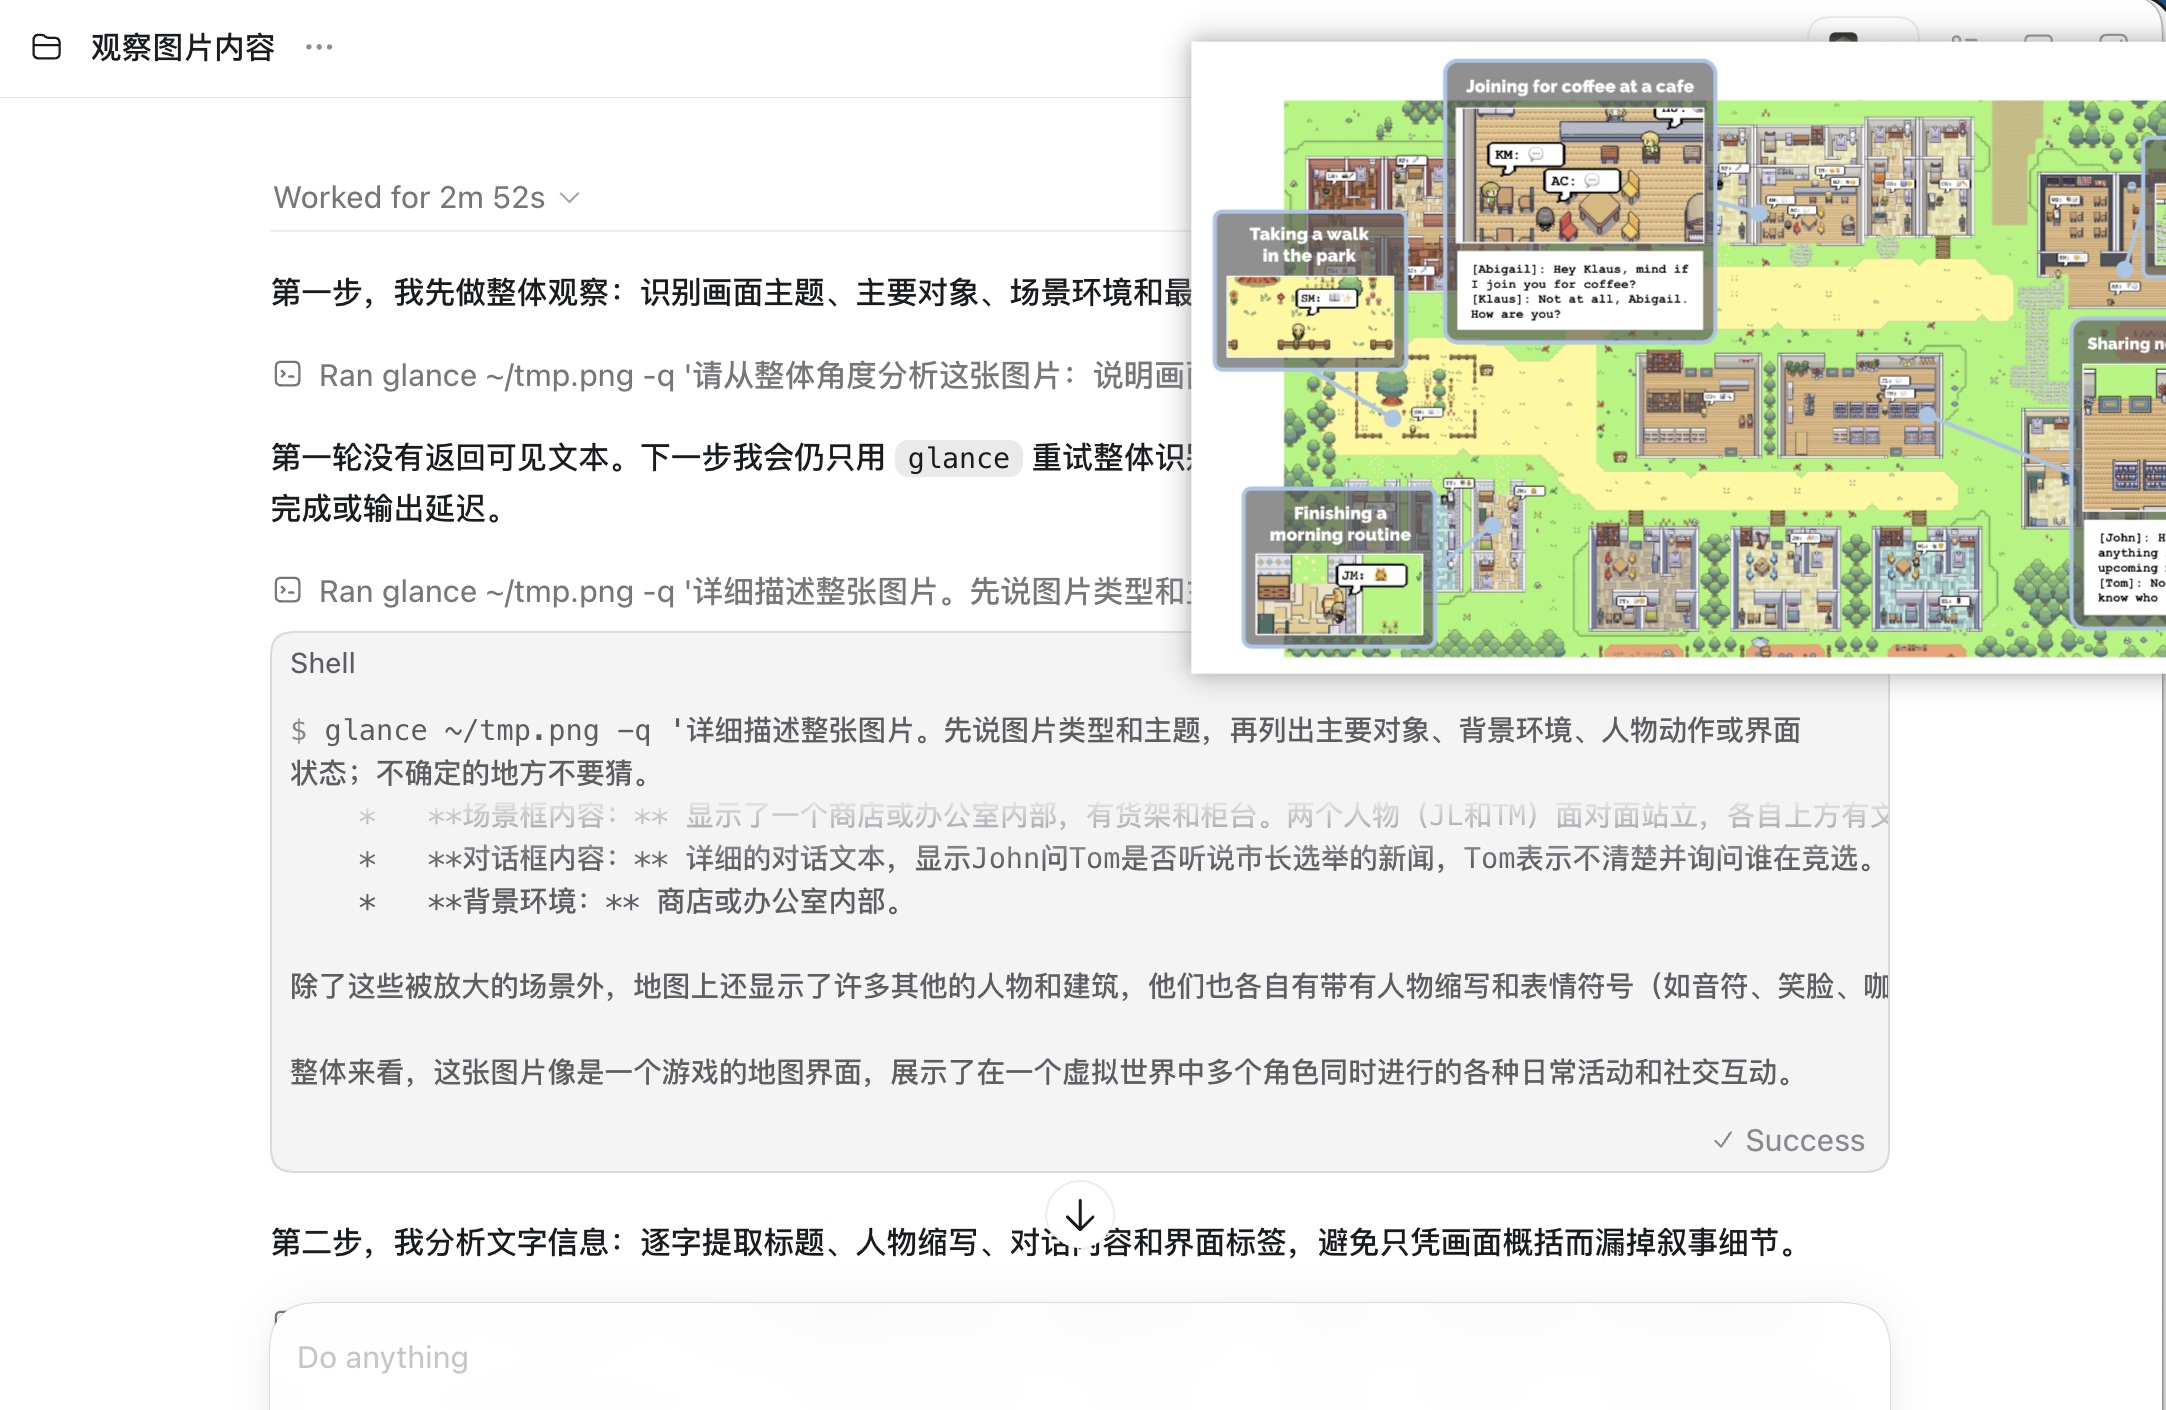
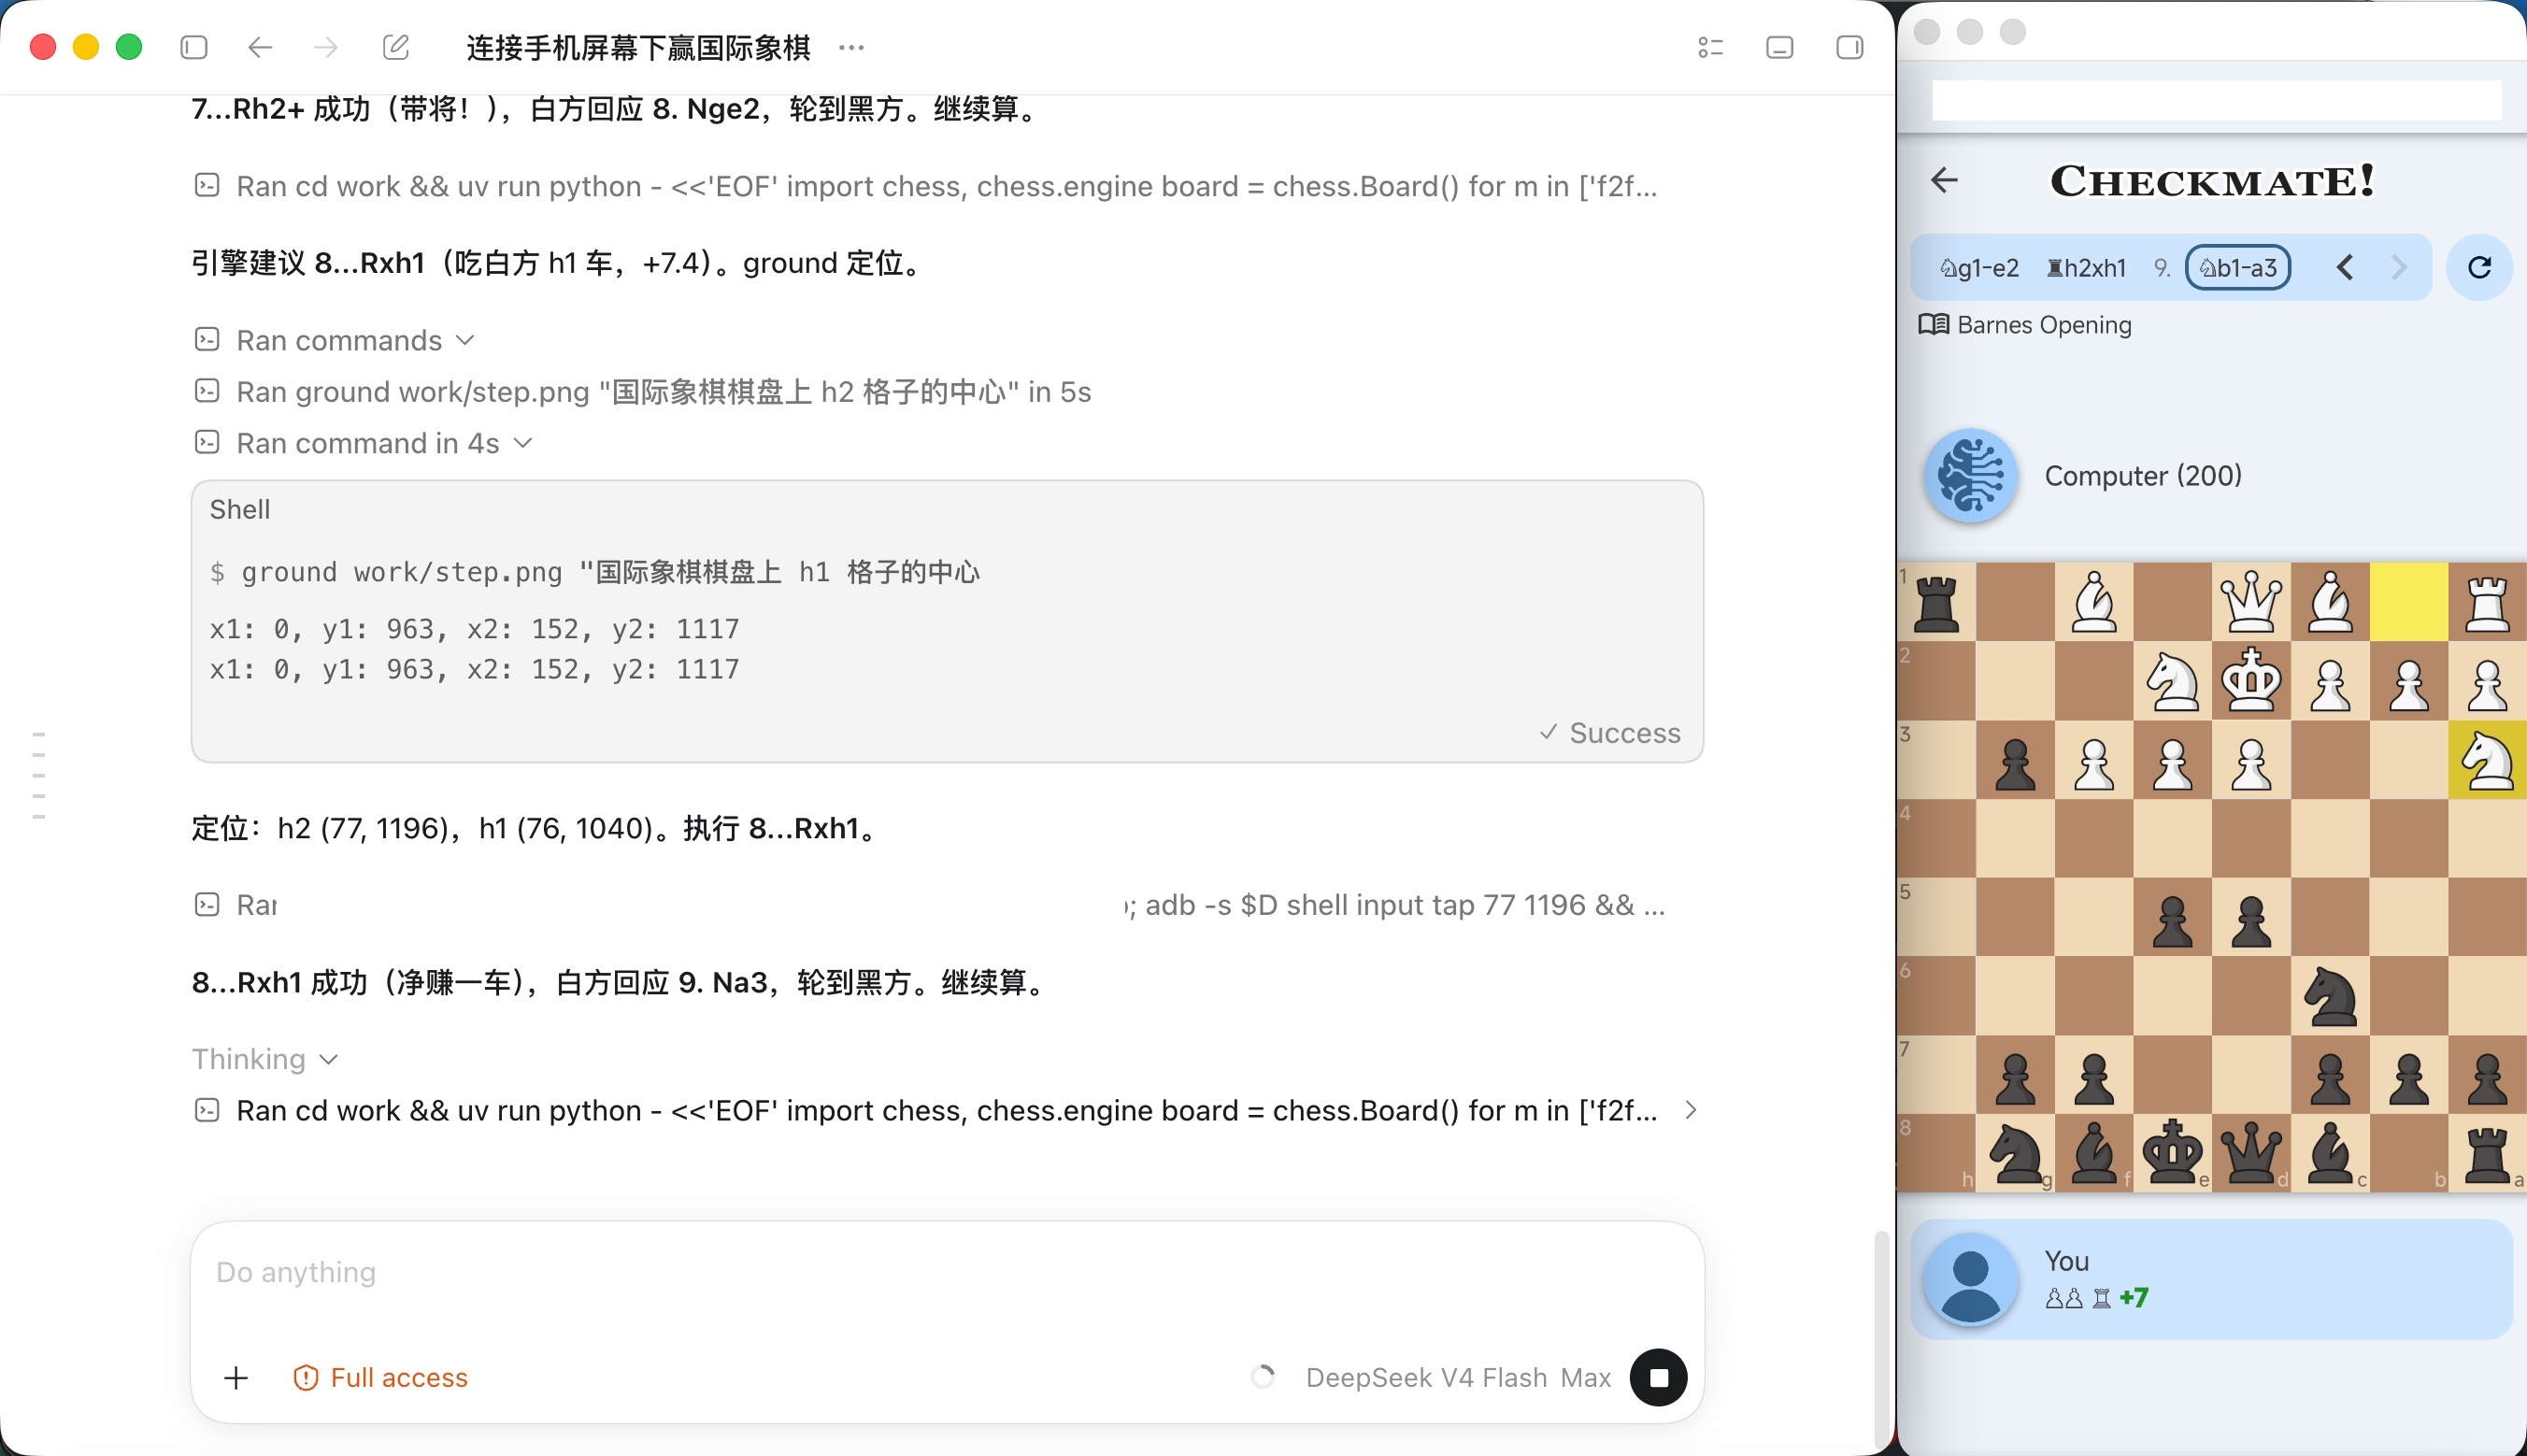
Left: multi-round image Q&A with glance. Right: with ground, DeepSeek V4 locates screen elements to play chess autonomously.
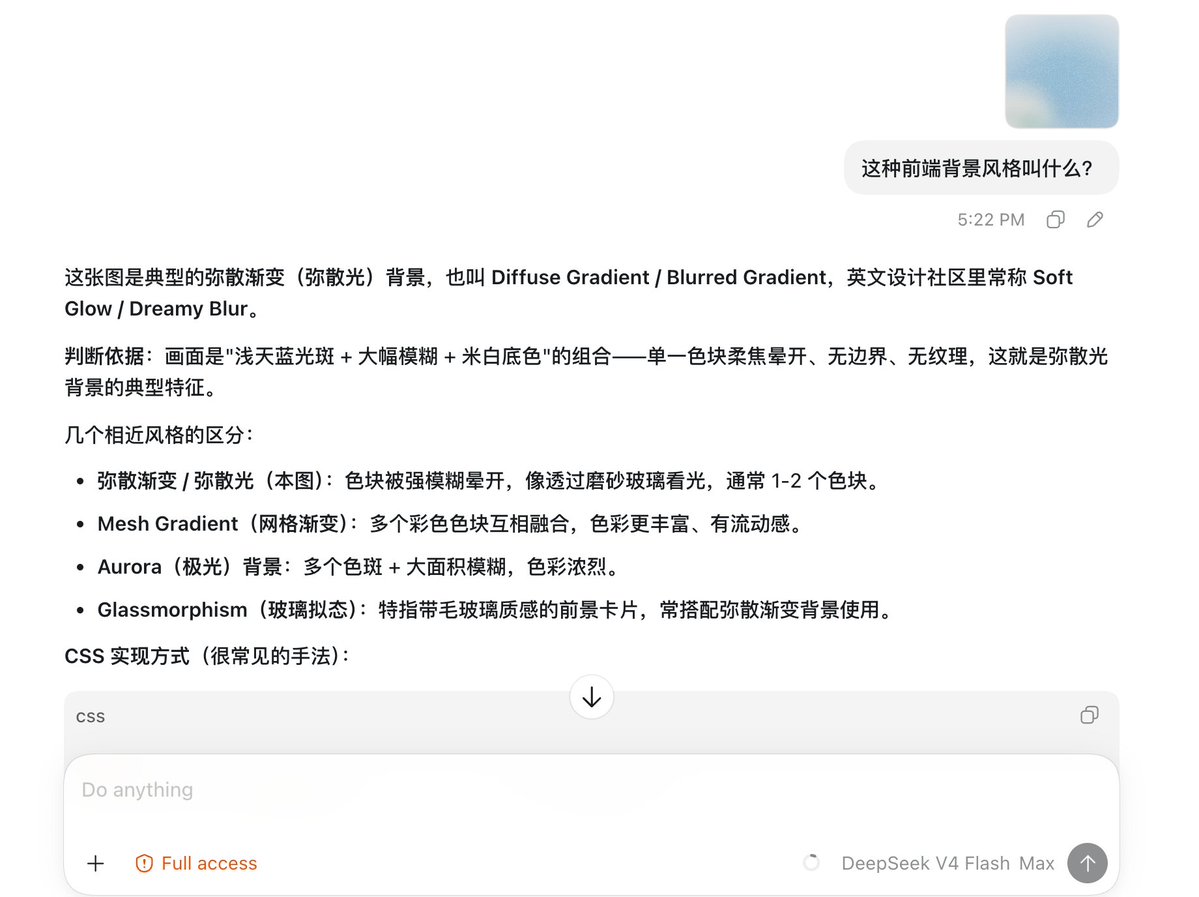
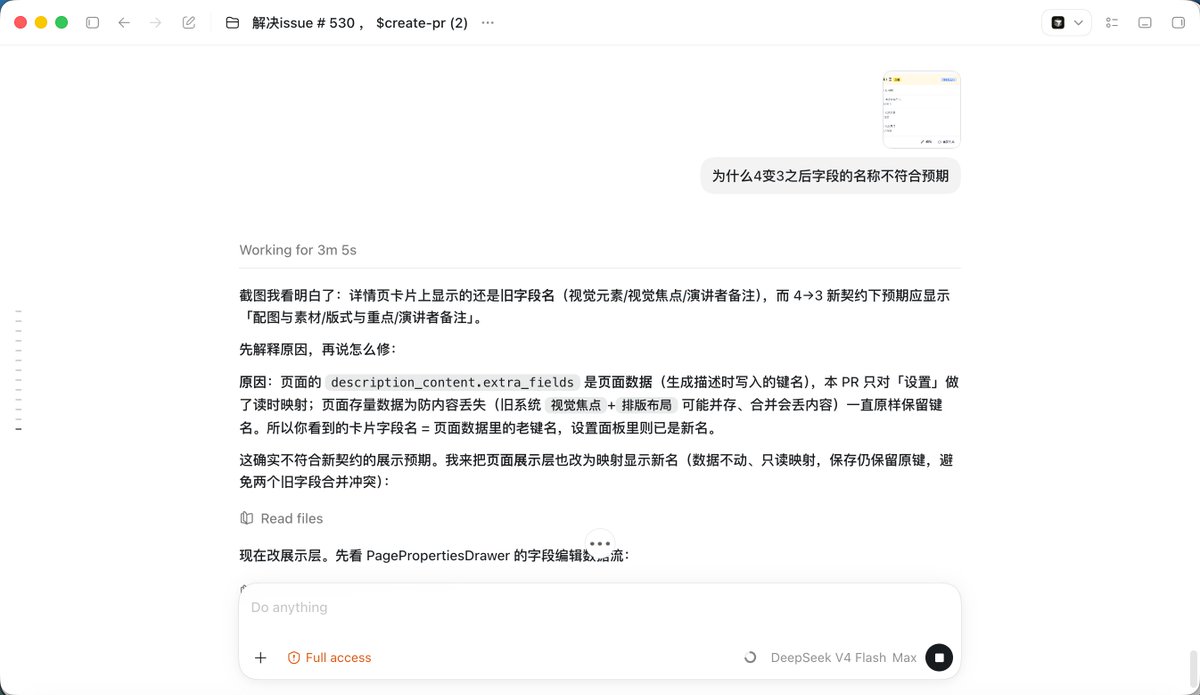
Left: DeepSeek V4 answers a UI style question with similar-style comparisons. Right: DeepSeek V4 debugs a field-name mismatch from a screenshot.
Quick Start
The easiest way to install it is to send this to your agent:
Follow the instructions in https://github.com/Anionex/agent-vision-toolkit to install the vision toolkit and skill locally. If the vision API is not configured, locate the configuration file for the current operating system and guide me through setting VISION_API_KEY, VISION_BASE_URL, and VISION_MODEL.
If you also want the optional seamless integration layer, send this:

 @obra


