



arthas
Skills for diagnosing Java applications with Arthas: tracing high CPU usage to threads and code paths, following request traceIds, and debugging Spring ApplicationContext, Bean and configuration injection problems.
3 skills38k
 @alibaba
Evaluates Agent Skills, agents and workspaces by running declarative test cases and grading the responses and file changes, with reports produced locally or in CI. It can also inspect failures and improve a skill's test suite from conversation.
Claude Code
$ npx -y skills add alibaba/skill-up --agent claude-code
Codex
$ npx skills add alibaba/skill-up -a codex
Cursor
$ npx skills add alibaba/skill-up -a cursor
Gemini CLI
$ npx skills add alibaba/skill-up -a gemini-cli
GitHub Copilot
$ npx skills add alibaba/skill-up -a github-copilot
OpenCode
$ npx skills add alibaba/skill-up -a opencode
Windsurf
$ npx skills add alibaba/skill-up -a windsurf
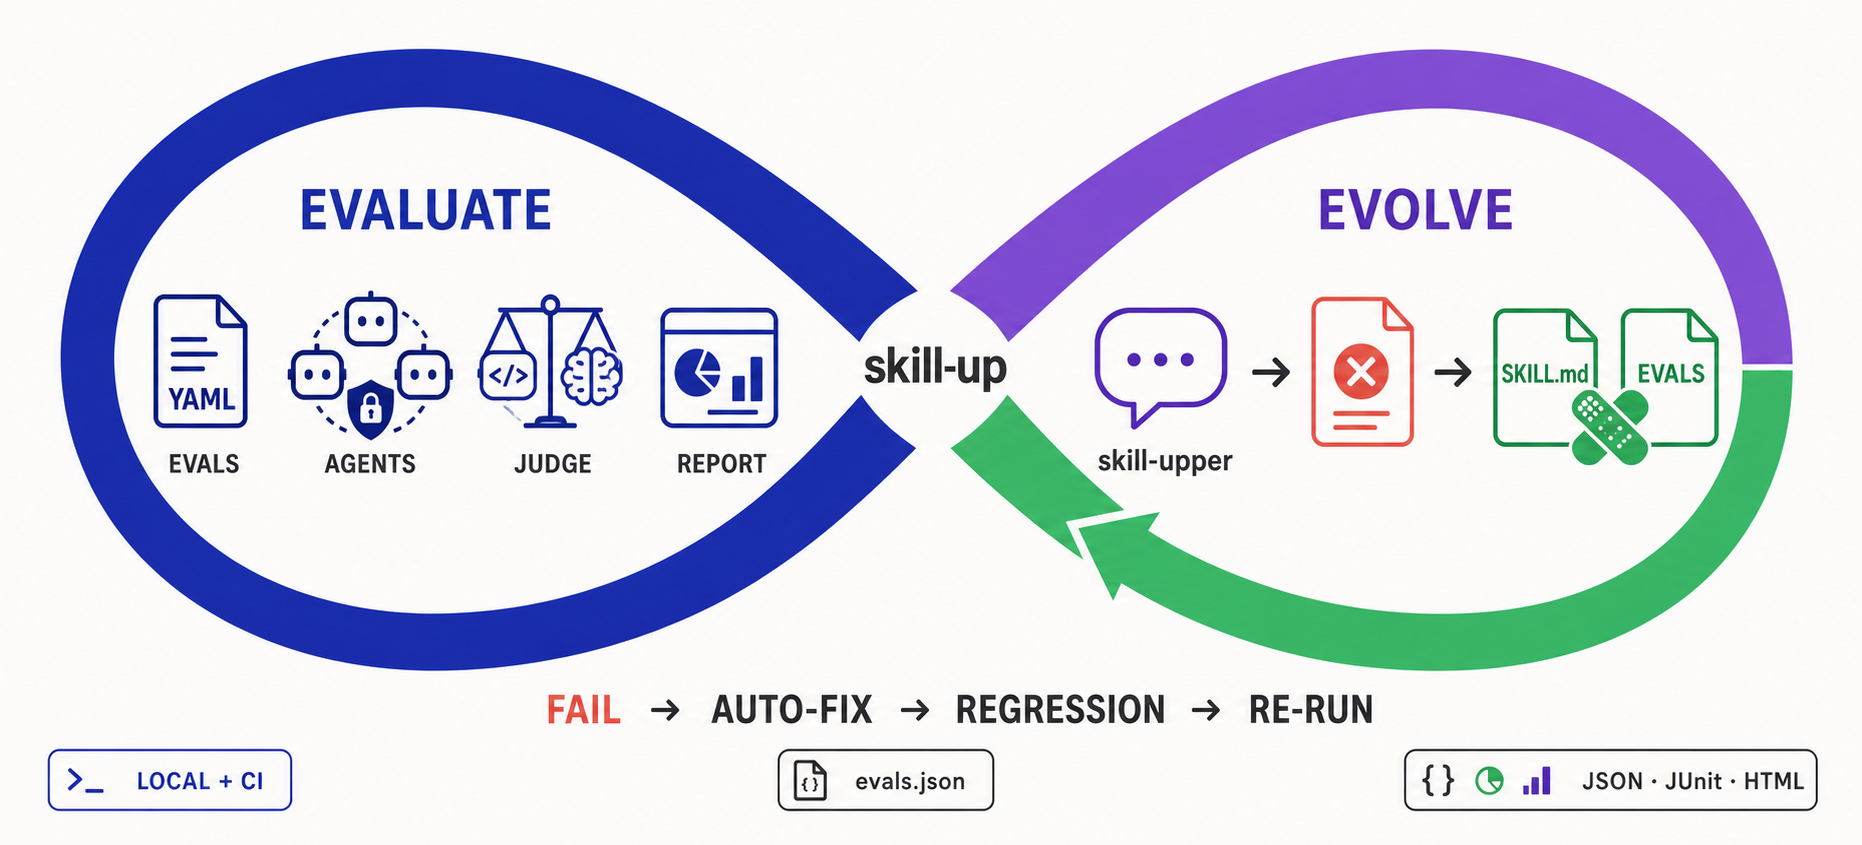
Evaluate Agent Skills, agents, and workspaces. Evolve Skills with evidence.

English | 中文
📖 User Manual · 用户手册
skill-up is a CLI for evaluating Agent Skills, agents, and their workspaces. It runs declarative cases against an Agent Engine, grades the response and workspace changes, and produces reports locally or in CI.
eval.yaml + cases/*.yaml).context.repo_fixture and context.files into the workspace.--workspace.engine.custom (local commands or HTTP services — see docs/design/custom-engine.md).skill-upper Skill, opt-in durable observation capture, approval-gated regression cases, isolated runs, and status comparison to verify evidence-backed Skill improvements. See plugins/dsh-skill-up.rule_based, script, and agent_judge evaluation strategies.grading.json, benchmark.json, benchmark.md, plus result.json, JUnit XML, and HTML reports.evals.json via skill-up import, or auto-detect with --auto.Harness engineering treats an agent's environment, tools, constraints, and feedback loops as parts of the system to design and improve. Behavioral evals make expected agent actions observable and help catch regressions. skill-up contributes evaluation and feedback to this work: repeatable prompts and workspace setups, checks on responses, tool calls, and file changes, and structured reports.
For Skills, the official Agent Skills evaluation guide describes a further loop: run with and without the Skill, grade outputs, aggregate results, and iterate. skill-up supports these workflows:
eval.yaml + cases/*.yaml format.claude_code, codex, qodercli, qwen_code) instead of tying the workflow to one client.evals.json while adding richer judges, CI-friendly commands, and structured reports.For Skill evolution, use skill-upper, the Agent Skill shipped in this repository. It lets your AI agent create evals, run skill-up, understand failures, fix the Skill or its evals, add regression coverage, and repeat the loop through conversation.
For repository development, skills/skill-upper/ is the only editable source.
Plugin bundles are generated into ignored build directories rather than tracked
copies or symlinks; run make bundle-plugins when preparing them locally.
make package-plugins VERSION=<version> creates self-contained Codex and DSH
archives. Tagged GitHub releases attach both archives and their checksums; this
repository does not publish either plugin to an external marketplace or npm.
# Codex, global install
npx skills add https://github.com/alibaba/skill-up/tree/main/skills/skill-upper -g -a codex -y

# Claude Code, global install
npx skills add https://github.com/alibaba/skill-up/tree/main/skills/skill-upper -g -a claude-code -y
You normally do not need to install skill-up first. skill-upper checks for the CLI when it runs and guides the agent through installation if needed.
Open a project that contains your Skill's SKILL.md in Codex, Claude Code, or
another compatible Agent, then ask:
Use skill-upper to evaluate this Skill.
Read SKILL.md, identify its most important behaviors, create realistic eval
cases with appropriate judges, validate the configuration, and run skill-up.
Summarize the results and the highest-impact failures.
skill-upper creates the declarative eval suite and drives the CLI for you:
my-skill/
  SKILL.md
  evals/
    eval.yaml
    cases/
      <case-id>.yaml
my-skill-workspace/
  iteration-1/
    result.json
Continue in the same conversation:
Use skill-upper to improve this Skill from the latest evaluation results.
Follow its evolution workflow, compare the original and candidate, add
regression coverage, and summarize which changes the evidence supports.
The comparison and acceptance rules live in skill-upper's evolution workflow. This prompt invokes that workflow; keeping the original is a valid outcome when a candidate does not show a supported improvement.
You can still install the CLI directly and hand-write eval.yaml and case
files:
curl -fsSL https://raw.githubusercontent.com/alibaba/skill-up/main/install.sh | bash
See the official documentation for Getting Started, Writing Evals, CLI Reference, and User Configuration. Windows-specific setup and limitations are covered in the Windows guide.
An agent-only eval does not need SKILL.md. Set skills: [] explicitly: when
skills is omitted and skill-up finds a SKILL.md above the config, it installs
that Skill automatically. Put eval.yaml and case files under evals/, then
pass the config path explicitly. Case and fixture paths resolve from the
discovered Skill root, or from the directory containing evals/ if none is found.
# evals/eval.yaml
schema_version: v1alpha1
environment:
  type: none
skills: []
engine:
  name: codex
cases:
  files:
    - evals/cases/agent-response.yaml
# evals/cases/agent-response.yaml
input:
  prompt: Reply with READY.
expect:
  must_contain: [READY]
skill-up validate ./evals/eval.yaml
skill-up run ./evals/eval.yaml
For repository tasks, a case can use context.repo_fixture to prepare a fresh
workspace and expect or a judge to check the result. To evaluate an agent in
an already prepared local directory, use a case written for that directory and
run skill-up run ./evals/eval.yaml --workspace /path/to/project --parallelism 1.
The existing directory is preserved, but the agent and case setup can change
its contents. This option requires environment.type: none, one case at a time,
and benchmark mode off. See Writing Evals
and the CLI Reference.
A simulated user can react to what the agent actually says, so follow-up messages need not be scripted in advance. For example, evaluate a Twenty Questions player:
This case YAML excerpt lets the simulator drive all replies after the opening:
Stars on GitHub
View @alibaba’s profileSkills for diagnosing Java applications with Arthas: tracing high CPU usage to threads and code paths, following request traceIds, and debugging Spring ApplicationContext, Bean and configuration injection problems.
@alibabaRuns AI-powered code review on Git changes through the ocr CLI, leaving line-level comments that check for issues such as null pointer errors, thread-safety problems, XSS and SQL injection. Works with OpenAI and Anthropic compatible models.
@alibabaAn AI native API gateway that routes, proxies and hosts MCP servers for AI traffic, built on Envoy with Wasm plugins and Kubernetes ingress support. Useful for teams running AI services behind a unified gateway.
@alibabaSkills for working on Playwright itself, covering development of new APIs and CLI commands, CI failure analysis, cherry-picking to release branches, triaging bug reports, and querying test results. Aimed at Playwright contributors and maintainers.
 @microsoft
The open and composable observability and data visualization platform. Visualize metrics, logs, and traces from multiple sources like Prometheus, Loki, Elasticsearch, InfluxDB, Postgres and many more.
 @grafana
Skills for evaluating and red-teaming LLM apps with Promptfoo. Covers writing and running eval suites, connecting Promptfoo to models and APIs, and running and rerunning redteam security scans.
 @promptfoo
Skills for evaluating AI agents, RAG pipelines and LLM apps with DeepEval metrics, and for tracing those apps with OpenTelemetry or DeepEval tracing into Confident AI.
 @confident-ai
Install it with the command on its page. It includes skill-upper, sample-no-evals, sample-with-evals. Its skills do not fire on their own yet. Free and open source.
Is this plugin yours?
Claim it with GitHubSubmit a pluginPromote it