ClawMem — On-device memory layer for Claude Code, OpenClaw, and Hermes agents
On-device memory for Claude Code, OpenClaw, Hermes, and AI agents. Retrieval-augmented search, hooks, and an MCP server in a single local system. No API keys, no cloud dependencies.
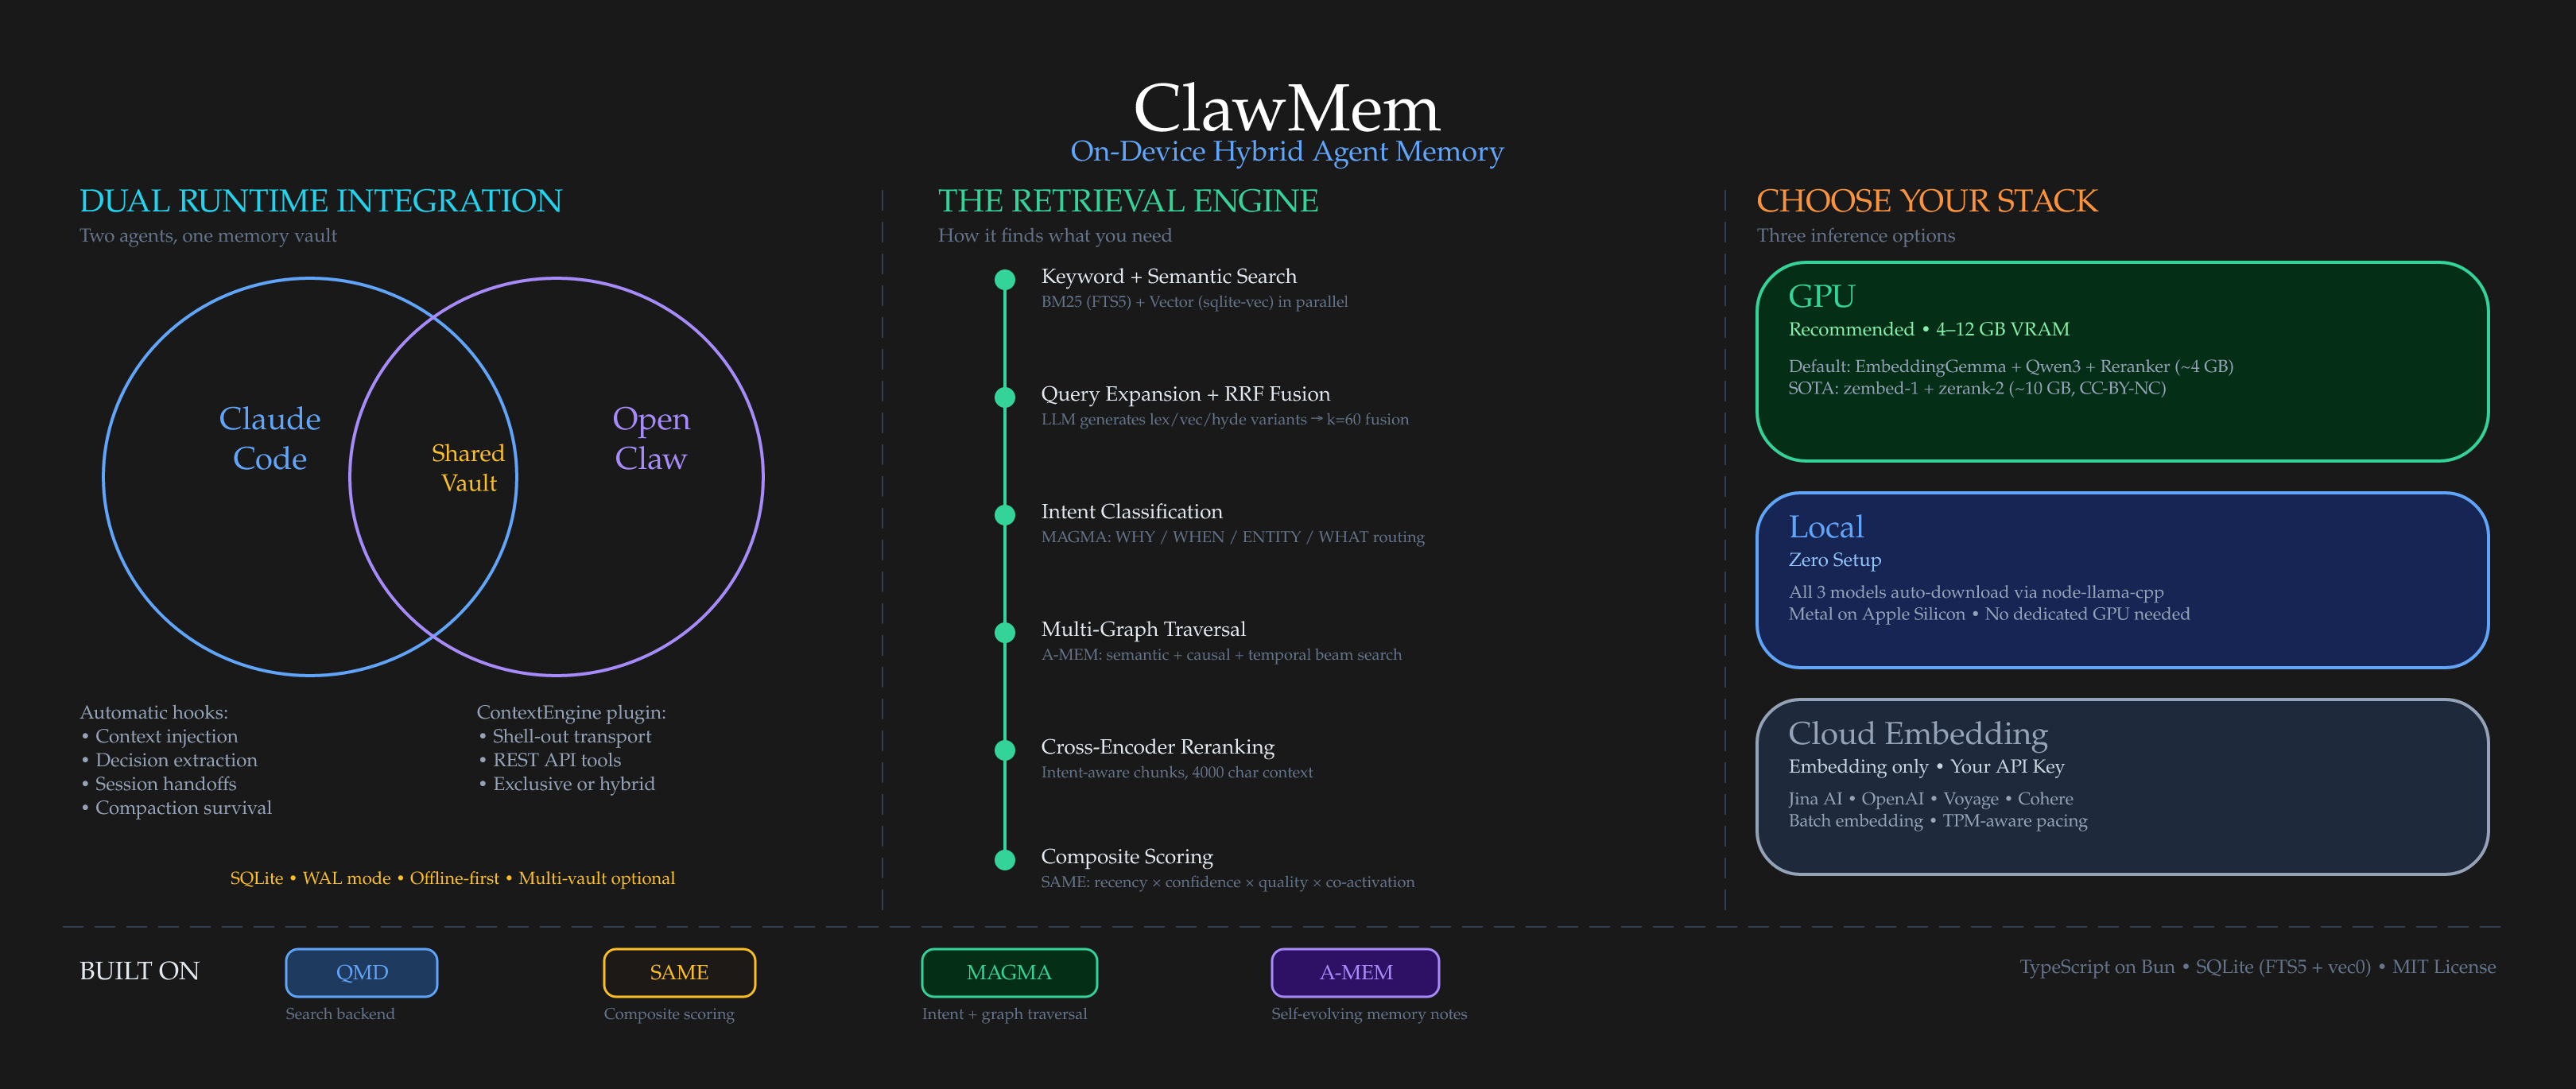
ClawMem fuses recent research into a retrieval-augmented memory layer that agents actually use. The hybrid architecture combines QMD-derived multi-signal retrieval (BM25 + vector search + reciprocal rank fusion + query expansion + cross-encoder reranking), SAME-inspired composite scoring (recency decay, confidence, content-type half-lives, co-activation reinforcement), MAGMA-style intent classification with multi-graph traversal (semantic, temporal, and causal beam search), and A-MEM self-evolving memory notes that enrich documents with keywords, tags, and causal links between entries. Pattern extraction from Engram adds deduplication windows, frequency-based durability scoring, and temporal navigation.
Integrates via Claude Code hooks, an MCP server (works with any MCP-compatible client), a native OpenClaw plugin, or a Hermes Agent MemoryProvider plugin. All paths write to the same local SQLite vault. A decision captured during a Claude Code session shows up immediately when an OpenClaw or Hermes agent picks up the same project.
TypeScript on Bun. MIT License.
What It Does
ClawMem turns your markdown notes, project docs, and research dumps into persistent memory for AI coding agents. It automatically:
- Surfaces relevant context on every prompt (context-surfacing hook)
- Bootstraps sessions with your profile, latest handoff, recent decisions, and stale notes
- Captures decisions, preferences, milestones, and problems from session transcripts using a local GGUF observer model
- Imports conversation exports from Claude Code, ChatGPT, Claude.ai, Slack, and plain text via
clawmem mine, with optional post-import LLM fact extraction (--synthesize) that pulls structured decisions / preferences / milestones / problems and cross-fact links out of otherwise full-text conversation dumps (v0.7.2). Imports preserve authorship time (v0.27.0): ranking recency and temporal queries run on when content was actually written, so historical conversations mined today don't rank as fresh — with a metadata-only --backfill-dates lane for vaults mined earlier
- Generates handoffs at session end so the next session can pick up where you left off
- Learns what matters via a feedback loop that boosts referenced notes and decays unused ones
- Guards against prompt injection in surfaced content
- Classifies query intent (WHY / WHEN / ENTITY / WHAT) to weight search strategies
- Traverses multi-graphs (semantic, temporal, causal) via adaptive beam search
- Evolves memory metadata as new documents create or refine connections
- Infers causal relationships between facts extracted from session observations
- Detects contradictions between new and prior decisions, auto-decaying superseded ones — when a contradiction judge is configured (
CLAWMEM_JUDGE_*, v0.29.0; disabled otherwise) (with an additional merge-time contradiction gate in the consolidation worker that blocks cross-observation contradictions before they land, v0.7.1)
- Guards against cross-entity merges during consolidation — name-aware dual-threshold merge safety compares entity anchors before merging similar observations, preventing "Alice decided X" from merging into "Bob decided X" (v0.7.1)
- Prevents context bleed in derived insights — the Phase 3 deductive synthesis pipeline validates every draft against an anti-contamination wrapper (deterministic entity contamination check + LLM validator + dedupe) before writing cross-session deductive observations (v0.7.1)
- Frames surfaced facts as background knowledge —
context-surfacing wraps injected content in <instruction> + <facts> + <relationships> blocks, telling the model to treat facts as already-known and exposing memory-graph edges between surfaced docs directly in-prompt (v0.7.1)
- Injects knowledge-graph facts as structured triples — when the user's prompt mentions entities already known to the vault,
context-surfacing resolves them via a three-path prompt-only extractor (canonical IDs, proper nouns, lowercased n-grams), queries the SPO graph for current-state triples, and appends a <vault-facts> block of raw subject predicate object lines to <vault-context> — off for speed, 200 tokens on balanced, 250 on deep, token-truncated at the triple boundary (v0.9.0)
- Session-scoped focus topic —
clawmem focus set "<topic>" --session-id <id> writes a per-session focus file used as a snippet-selection intent: surfaced docs prefer sentences matching the topic. Presentation only since v0.38.0 — a focus never changes expansion, reranking, scoring, ordering, or the surfaced set — session-isolated, fail-open, never writes to SQLite or lifecycle columns (v0.9.0, narrowed v0.38.0)
- Ranks hook injections on one channel-aware key — every retrieval leg (BM25, vector, file-aware, gated prior-turn, expansion variants) contributes a ranked lane; weighted reciprocal-rank fusion yields a single ordering key (current-support band, fused mass) that decides membership, final order, AND admission — no mixed raw-score sorts, no metadata reordering (v0.38.0)
- Admits by relevance, abstains honestly — the context-surfacing hook admits candidates by a relative floor on the fused ordering key and abstains at query level when current-turn support is missing or keyword-degenerate, instead of surfacing weak lists (v0.38.0)
- Guards the deep rerank lane — cross-encoder scores apply only under full candidate coverage AND a discriminating score set (degeneracy gate); the reranker joins the final order as a rank-fused lane, and remote rerank scores are cached only under an attested provider identity (
clawmem rerank-health) (v0.38.0)
- Keeps the hook's write path off your prompt latency — turn alignment is one early fail-closed row; recall attribution, token accounting, and vault mirrors are handed to a detached drainer process through an on-disk spool after the payload is emitted (v0.38.0)
- Scores document quality using structure, keywords, and metadata richness signals
- Boosts co-accessed documents — notes the agent verifiably referenced together in one turn (v0.41.0) get retrieval reinforcement on the composite MCP surfaces (removed from hook ordering in v0.38.0 — the injected order is the channel-aware fusion key alone)
- Decomposes complex queries into typed retrieval clauses (BM25/vector/graph) for multi-topic questions
- Cleans stale embeddings automatically before embed runs, removing orphans from deleted/changed documents
- Transaction-safe indexing — crash mid-index leaves zero partial state (atomic commit with rollback)
- Processes each turn once — the extraction and handoff hooks keep a cursor per transcript and the feedback hook decides each surfaced turn once (v0.41.0), so a turn is extracted, summarised and credited once instead of again at every response, and each session's documents are its own
- Navigates temporal neighborhoods around any document via the
timeline tool — progressive disclosure from search to chronological context to full content
- Boosts frequently-revised memories — documents with higher revision counts get a durability signal in composite scoring (capped at 10%)
- Supports pin/snooze lifecycle for persistent boosts and temporary suppression
- Manages document lifecycle — policy-driven archival sweeps with restore capability
- Auto-routes queries via
memory_retrieve — classifies intent and dispatches to the optimal search backend
- Syncs project issues from Beads issue trackers into searchable memory
- Runs a quiet-window heavy maintenance lane — a second consolidation worker, off by default behind
CLAWMEM_HEAVY_LANE=true, that runs on a longer interval only inside a configurable hour window. Gated by context_usage query-rate so it never competes for CPU/GPU with interactive sessions, scoped exclusively via DB-backed worker_leases, stale-first by default with an optional surprisal selector, and journals every attempt in maintenance_runs for operator visibility (v0.8.0)
Runs fully local with no API keys and no cloud services. Integrates via Claude Code hooks and MCP tools, as a native OpenClaw plugin, or as a Hermes Agent MemoryProvider plugin. All modes share the same vault for cross-runtime memory. Works with any MCP-compatible client.
Full version history is in RELEASE_NOTES.md. Upgrade instructions for existing vaults are in docs/guides/upgrading.md.
Architecture
Install
Platform Support
| Platform | Status | Notes |
|---|
| Linux | Full support | Primary target. systemd services for watcher + embed timer. |
| macOS | Full support | Homebrew SQLite handled automatically. GPU via Metal (llama.cpp). |
| Windows (WSL2) | Full support | Recommended for Windows users. Install Bun + ClawMem inside WSL2. |
| Windows (native) | Not recommended | Bun and sqlite-vec work, but bin/clawmem wrapper is bash, hooks expect bash commands, and systemd services have no equivalent. Use WSL2 instead. |
Prerequisites
Required:
- Bun v1.0+ — runtime for ClawMem. On Linux, install via
curl -fsSL https://bun.sh/install | bash (not snap — snap Bun cannot read stdin, which breaks hooks).
- SQLite with FTS5 — included with Bun. On macOS, install
brew install sqlite for extension loading support (ClawMem detects and uses Homebrew SQLite automatically).
Optional (for better performance):
- llama.cpp (
llama-server) — for dedicated GPU inference. Without it, node-llama-cpp runs models in-process (auto-downloads on first use). GPU servers give better throughput and prevent silent CPU fallback.
- systemd (Linux) or launchd (macOS) — for persistent background services (watcher, embed timer, GPU servers). ClawMem ships systemd unit templates; macOS users can create equivalent launchd plists. See systemd services.
Optional integrations:
- Claude Code — for hooks + MCP integration
- OpenClaw — for native plugin integration
- Hermes Agent — for
MemoryProvider plugin integration
- bd CLI v0.58.0+ (verified through v1.1.0) — for Beads issue tracker sync (only if using Beads)
Install from npm (recommended)
npm install -g clawmem
If you use Bun as your package manager:
bun add -g clawmem
Install from source
git clone https://github.com/yoloshii/clawmem.git ~/clawmem
cd ~/clawmem && bun install
ln -sf ~/clawmem/bin/clawmem ~/.bun/bin/clawmem
Setup roadmap
After installing, here's the full journey from zero to working memory:
| Step | What | How | Details |
|---|
| 1. Bootstrap | Create a vault, index your first collection, embed, install hooks and MCP | clawmem bootstrap ~/notes --name notes | One command does it all. Or run each step manually (see below). |


 @paddlepaddle


