





promptschat
Gives Claude Code access to the prompts.chat library, letting you search, retrieve and improve AI prompt templates, and find and install Agent Skills from its registry.
2 skills2 agents2 commands1 MCP+3+2+2+2+1+1+1+1175k
 @gh-f
Own your AI video pipeline. LTX-2.3 (22B) self-hosted on your Modal GPU via a Claude Code skill, t2v, i2v, keyframes, v2v + synced audio. ~$0.02 per 5s clip, idle = $0.
Claude Code
> /plugin marketplace add patraxo/ltx2-vidgen-skill> /plugin install ltx2-vidgen@ltx2-vidgen-skill
Codex
$ npx skills add patraxo/ltx2-vidgen-skill -a codex
Cursor
$ npx skills add patraxo/ltx2-vidgen-skill -a cursor
Gemini CLI
$ npx skills add patraxo/ltx2-vidgen-skill -a gemini-cli
GitHub Copilot
$ copilot plugin marketplace add patraxo/ltx2-vidgen-skill$ copilot plugin install ltx2-vidgen@ltx2-vidgen-skill
OpenCode
$ npx skills add patraxo/ltx2-vidgen-skill -a opencode
Windsurf
$ npx skills add patraxo/ltx2-vidgen-skill -a windsurf
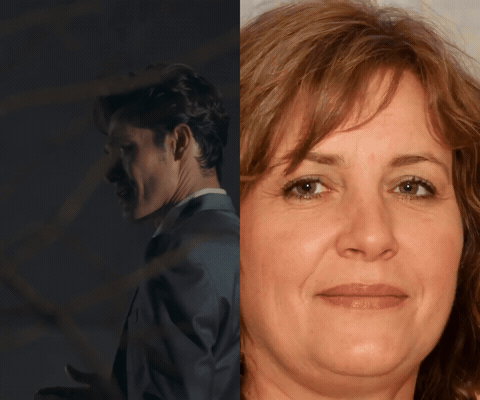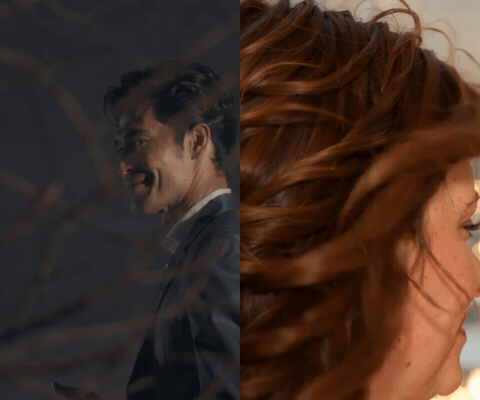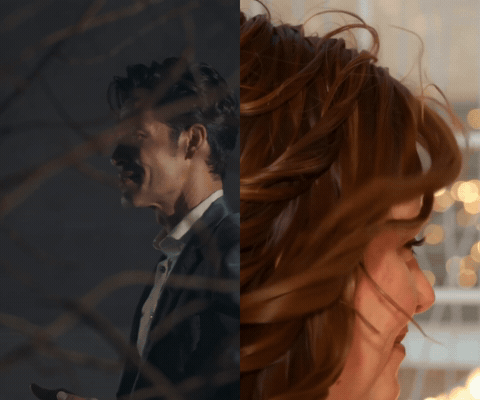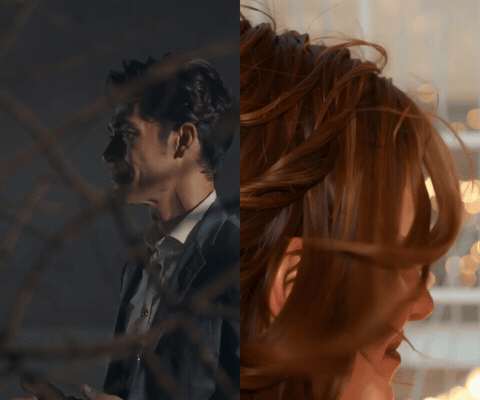
A Claude Code skill that owns your AI video pipeline — drop a photo in Claude Code → get a video. It deploys your own optimized LTX-2.3 (22B) backend to your Modal serverless GPU and drives it: text-to-video, image-to-video, keyframe interpolation, video-to-video, and IC-LoRA (canny/depth/pose) control, with synced audio — a few cents a clip, your GPU, no per-clip API meter, no rate limit.
A Claude Code skill that owns the whole loop — it deploys your own LTX-2.3 (22B) video backend to your Modal account on first run, then drives it from Claude Code: drop a photo (or a prompt), ask for a video, get the .mp4. You never leave Claude Code; the GPU is yours; there's no SaaS in the middle.
--variations N (one prompt, N takes) and --prompts-file (many prompts) in one warm container.1. Install the skill (Claude Code, or any agent that reads SKILL.md):
npx skills add patraxo/ltx2-vidgen-skill        # or: cp -R skills/ltx2-video ~/.claude/skills/
pip install modal && modal token new            # Modal SDK + your account (free — $30/mo credits)
…or as a Claude Code plugin marketplace:
/plugin marketplace add patraxo/ltx2-vidgen-skill
/plugin install ltx2-vidgen@ltx2-vidgen-skill
2. Deploy your backend once — into your Modal account (downloads the LTX-2.3 weights + Gemma text encoder; public components only, no HuggingFace token):
git clone https://github.com/patraxo/ltx2-vidgen-skill && cd ltx2-vidgen-skill && ./deploy.sh
That's it. Now in Claude Code, drop a photo (or just describe a scene) and ask:
The skill validates the input, confirms cost (offers a cheap smoke first), calls your deployed app via modal.Cls.from_name (no endpoint, no auth, no secrets), and saves the .mp4 + a preview frame to ./video_out/. First clip cold-starts ~90 s; warm ~31 s.
Prefer raw modal run? Drive the backend directly, no skill
PYTHONPATH=. uv run modal run deploy/ltx2_model.py::smoke_real --image-path pic.jpg   # i2v
PYTHONPATH=. uv run modal run deploy/ltx2_model.py::run_modes                          # t2v + i2v + keyframe
PYTHONPATH=. uv run modal run deploy/ltx2_model.py::run_retake                         # v2v
PYTHONPATH=. uv run modal run deploy/ltx2_model.py::kf_real --image-a a.jpg --image-b b.jpg
PYTHONPATH=. uv run modal run tests/ship_verify.py                                     # full verify
| Mode | Input | Underlying pipeline |
|---|---|---|
| text-to-video | prompt only | KeyframeInterpolation (0 keyframes) |
| image-to-video | 1 image + prompt | TI2VidTwoStages |
| keyframe interpolation | 2 images + prompt | KeyframeInterpolation |
| video-to-video (retake) | source video + window + prompt | RetakePipeline |
All four are exercised by run_modes / run_retake / kf_real and verified working (frame-inspected). The opt stack applies across every mode.
Runs on Modal serverless NVIDIA RTX PRO 6000 (Blackwell, 96 GB), bf16, billed per-second at $0.000842/s (~$3.03/hr) — so cost ≈ latency:
| Mode @ 768×1280 (9:16) | Warm latency | ~ $/clip |
|---|---|---|
| image / text / keyframe — 5 s (121 f) | ~23 s | ~1.9¢ |
| image / text / keyframe — 10 s (241 f) | ~45 s | ~3.8¢ |
| landscape 1280×768 — 5 s / 10 s | ~24 s / ~47 s | ~2.0¢ / ~4.0¢ |
| 3-clip batch with decode/encode overlap | ~25 s/clip (−20% vs serial) | ~2.1¢ |
| IC-LoRA control — 4 s | ~28 s | ~2.4¢ |
| video-to-video (retake) — 10 s | ~470 s | ~40¢ |
(5 s/10 s rows re-measured 2026-06-10, bench config with the first-block cache off — the production path with it on is faster still. First call at a NEW frame count pays a one-time shape compile, e.g. ~86 s at 241 f, then steady.)
Cold start (first clip on a fresh container) ~90–200 s; idle scales to $0. Both 22B stage transformers stay resident — peak ~75 GB / 96 GB, verified zero OOM over a 10-generation run (<1 GB drift).
Optimization stack — bf16 throughout, cache paths bit-identical to the unoptimized run, ~1.96× net faster:
Per-clip APIs charge you for every take — including the failed ones. Iteration is exactly how you get good AI video, so the meter punishes the workflow that works. Self-hosting flips the economics:
| 30 s of video with audio (~720p+) | Approx. cost | vs this stack |
|---|---|---|
| This stack (your Modal GPU, per-second billing) | ~$0.11 | — |
| Hosted open-weight APIs (often quantized variants) | ~$0.35–0.70 | 3–6× |
| Runway Gen-4 Turbo | ~$0.75 | ~7× |
| Kling Pro | ~$2–3.50 | 15–30× |
| Sora 2 API | ~$3–15 | 25–120× |
| Veo 3.x (with audio) | ~$4.50–13 | 40–110× |
Third-party prices are approximate (mid-2026) and change often — verify before quoting. The point isn't the decimals; it's the shape: a failed take here costs cents, twenty variations cost a coffee, and the quality knob is yours (full bf16, no silent quantization).
New Modal accounts get $30/month in free credits. At ~1.9¢ per 5-second clip that's ~1,500 free clips/month — explore a prompt 20 ways (--variations 20) and keep the one that lands. It's your Modal account and bill (visible in your dashboard), no per-clip meter, no rate limit, idle = $0.
LTX-2.3 is a 22B video diffusion transformer. Serving it naively has two costs: a slow cold start, and a per-clip cost where the pipeline re-assembles + re-fuses model internals every request. This repo attacks both:
max-autotune tested + rejected, slower here).Helper modules live in utils/ and are mounted into the container.
.env block)| Variable | Default | Description |
|---|---|---|
LTX_PERSIST_PIPELINE | both | Keep stage transformers GPU-resident across requests. off/stage2/both. |
LTX_PERSIST_LRU_MAX | 2 | Upper bound on resident (stage, resolution) entries. The effective cap is computed per request (activation-aware, see below) and never exceeds this. |
LTX_VRAM_HEADROOM_GB | 40 | Free VRAM kept available before building a new resident transformer / loading the v2v/control pipeline. LRU residents are evicted to reach it, so a cross-mode/resolution build never OOMs the forward. |
LTX_VRAM_USABLE_GB | 91 | Usable VRAM for the activation-aware resident-cap math (96 GB card minus a safety margin). |
LTX_XFMR_GB | 35 | Assumed size of one stage transformer, used by the resident-cap math. |
LTX_REGISTRY | cpu_pinned | Weight cache: cpu_pinned (recommended) / gpu_resident / off. |
LTX_CACHE_TEXT_EMB | 1 | LRU cache on the text encoder output. |
LTX_SKIP_AUDIO | 0 | Per-request default for skipping audio decode (video pixels byte-identical). |
LTX_FP8 | 0 | Load official fp8 weights instead of bf16 (off = bf16 quality default). |
LTX_VAE_TILE_PX | 768 | VAE-decode spatial tile size (px, ≥64 & ÷32). Smaller → smaller decode peak (measured ~1 GB lever; decode is already well-tiled). Overlap blends seams. 0 disables tiling entirely → reference-exact non-tiled decode (PSNR 50–51 dB vs tiled — the delta is the tiled arm's seam blending), latency-neutral, +2.6 GB peak; fits even at 241 f (82.3 GB peak, no OOM). |
LTX_VAE_TILE_OVERLAP | 64 | Spatial tile overlap (px, ÷32, < tile). |
Stars on GitHub
Gives Claude Code access to the prompts.chat library, letting you search, retrieve and improve AI prompt templates, and find and install Agent Skills from its registry.
@gh-fA Claude Code skill for generating editable PPTX presentations and slides from a workflow, with reusable brand, style, layout, and deck workspaces, native charts, speaker notes, and template filling.
 @hugohe3
Gives AI agents control over Word, Excel and PowerPoint files, with skills for building .docx reports, academic papers, Excel dashboards and Morph-style animated slides.
 @iofficeai
A skill that builds animation-rich HTML presentations from scratch or converts PowerPoint files to web slides. Useful for anyone turning a deck into a web presentation.
 @zarazhangrui
Own your AI video pipeline. LTX-2.3 (22B) self-hosted on your Modal GPU via a Claude Code skill, t2v, i2v, keyframes, v2v + synced audio. ~$0.02 per 5s clip, idle = $0. Install it with the command on its page. It includes ltx2-video. Its skills do not fire on their own yet. Free and open source.
Is this plugin yours?
Claim it with GitHubSubmit a pluginPromote it