CUAWright
Webwright is now CUAWright. Alongside browser automation, you can now run
desktop tasks in an Ubuntu VM. Use cuawright web for browser tasks and
cuawright desktop for desktop tasks. Existing webwright commands and Python
imports still work.

CUAWright gives coding models a terminal to automate browsers and desktop applications.
Use Webwright to browse the web and build reusable Playwright scripts, or run your
own desktop task and reproduce OSWorld-V2 benchmarks in an Ubuntu VM.
Start with the browser quick start or
desktop quick start.
Already got your favorite agents, and wonder how to make Claude Code, Codex, Hermes more capable in browser tasks? Consider adding CUAWright browser plugin/skill!
📰 News
- 2026-10-03 — Webwright → CUAWright: renamed the project to bring browser and desktop agents together. The Webwright browser runtime is now
cuawright.webwright, and OSWorld desktop support lives at cuawright.desktop. Existing webwright commands and imports remain compatible. See desktop setup.
- 2026-09-01 — Persistent step-by-step browsing and native
run_command tool calls improve performance to 88.1% on Online-Mind2Web and 77.5% on Odysseys.
- 2026-07-21 — Skill Factory: every solve leaves a script behind, distilled into reusable, verified, parameterized code skills that rerun standalone with no model (~40 s, zero tokens). On WebArena, reuse lifts held-out accuracy 55% → 70% (+15 pp). See the optional Skill Factory.
- 2026-05-11 — Support Task2UI mode: Webwright completes the task and renders task results into an HTML-based web app you can easily view and reuse.
- 2026-05-06 — Codex and Claude Code plugin manifests added; install via
/plugin install cuawright@cuawright. Hermes Agent integration shipped; the same skills/cuawright-web/ folder now loads across Claude Code, Codex, and Hermes.
- 2026-05-04 — Initial public release: ~1.5k LoC, OpenAI / Anthropic / OpenRouter backends, Playwright environment.
💡 Motivation: Beyond Step-by-Step Web Interaction in a Stateful Browser
Most web agents today treat the browser session itself as the workspace: at each step the model receives the current page state and predicts a single next operation — a click, a type, a DOM selector, or a short tool call. Whatever the format, the agent is locked into predicting one web action at a time inside a predefined interaction loop. That harness was useful when LLMs were weaker. As models get stronger at writing and debugging code, the same harness becomes a bottleneck.
Webwright takes a different stance: separate the agent from the browser, and treat the browser as something the agent can launch, inspect, and discard while developing a program. The persistent artifact is not the browser session — it's the code and logs in the local workspace.
- 🧱 Robust, reusable interaction with web environments — instead of fragile pixel-level actions, a coding agent with a terminal queries elements, waits for conditions, and handles dynamic behaviors like lazy loading or re-rendering. The resulting scripts can be rerun, adapted, and shared across tasks rather than rediscovered from scratch.
- ⚡ Efficient composition of complex workflows — multi-step interactions like selecting a date or filling a form become a compact program. Loops, functions, and abstractions let the agent generalize across similar tasks (e.g. different dates) without re-predicting the same low-level sequences. Fewer interaction rounds, faster execution, less error accumulation on long horizons.
- 🧪 Workspace-as-state, not browser-as-state — the agent can write exploratory scripts, spawn fresh browser sessions, and decide for itself when to capture screenshots and inspect failures, much like a human engineer iterating on an RPA script.
- 🪄 Surprisingly effective despite being minimal — this stripped-down setup turns out to handle complex and especially long-horizon web tasks well (see Performance).
🌟 Why Webwright
Most web agent frameworks bury the actual agent loop under layers of abstractions. Webwright takes the opposite stance:
- 🪶 Readable core — browser agent loop, environments, models, and CLI are separate modules under
src/cuawright/webwright/.
- 🧩 Pluggable model backends — OpenAI, Anthropic, and OpenRouter, each ~150–200 lines.
- 🔍 Zero hidden frameworks — just
httpx, pydantic, playwright, and typer.
- 🔁 Flat prompt → observe → execute script loop — readable end-to-end, easy to debug, easy to fork.
- 🧪 Run-artifact first — every run writes trajectories and screenshots to disk for inspection.
If you want a minimal, easy-to-debug starting point for browser-using agents instead of another heavyweight platform, this is it.
🆚 How Webwright Differs From Other Browser-Agent Repos
How they differ at the architectural level:
| Stagehand (Browserbase) | agent-browser (Vercel) | browser-use | Webwright |
|---|
| Paradigm | Hybrid: code + NL primitives (act / extract / agent) | CLI tool that another agent (Claude Code, Codex, etc.) calls | Autonomous LLM agent loop over DOM/AX snapshots | Coding agent with a terminal; browser is just an environment it spawns |
| Action space | Playwright code, or NL → LLM-translated Playwright | Discrete subcommands (open, click @e2, snapshot, eval) | Indexed click/type actions selected by the LLM | Free-form Python (writes Playwright scripts itself) |
| What is "state"? | The browser session | The browser session (held by daemon across CLI calls) | The browser session | The local workspace — code, screenshots, logs. Browser is disposable. |
| Loop shape | Imperative; agent() does multi-step when needed | One CLI invocation per micro-step | observe → predict next action → execute → repeat | write code → execute → inspect screenshots → repair (code-as-action) |
🎥 Demo
CUAWright demo
Webwright demo
📊 Performance
CUAWright beats the same model running in a different harness on every benchmark
below, from desktop and CAD to long-horizon web tasks. See the
paper for full details.
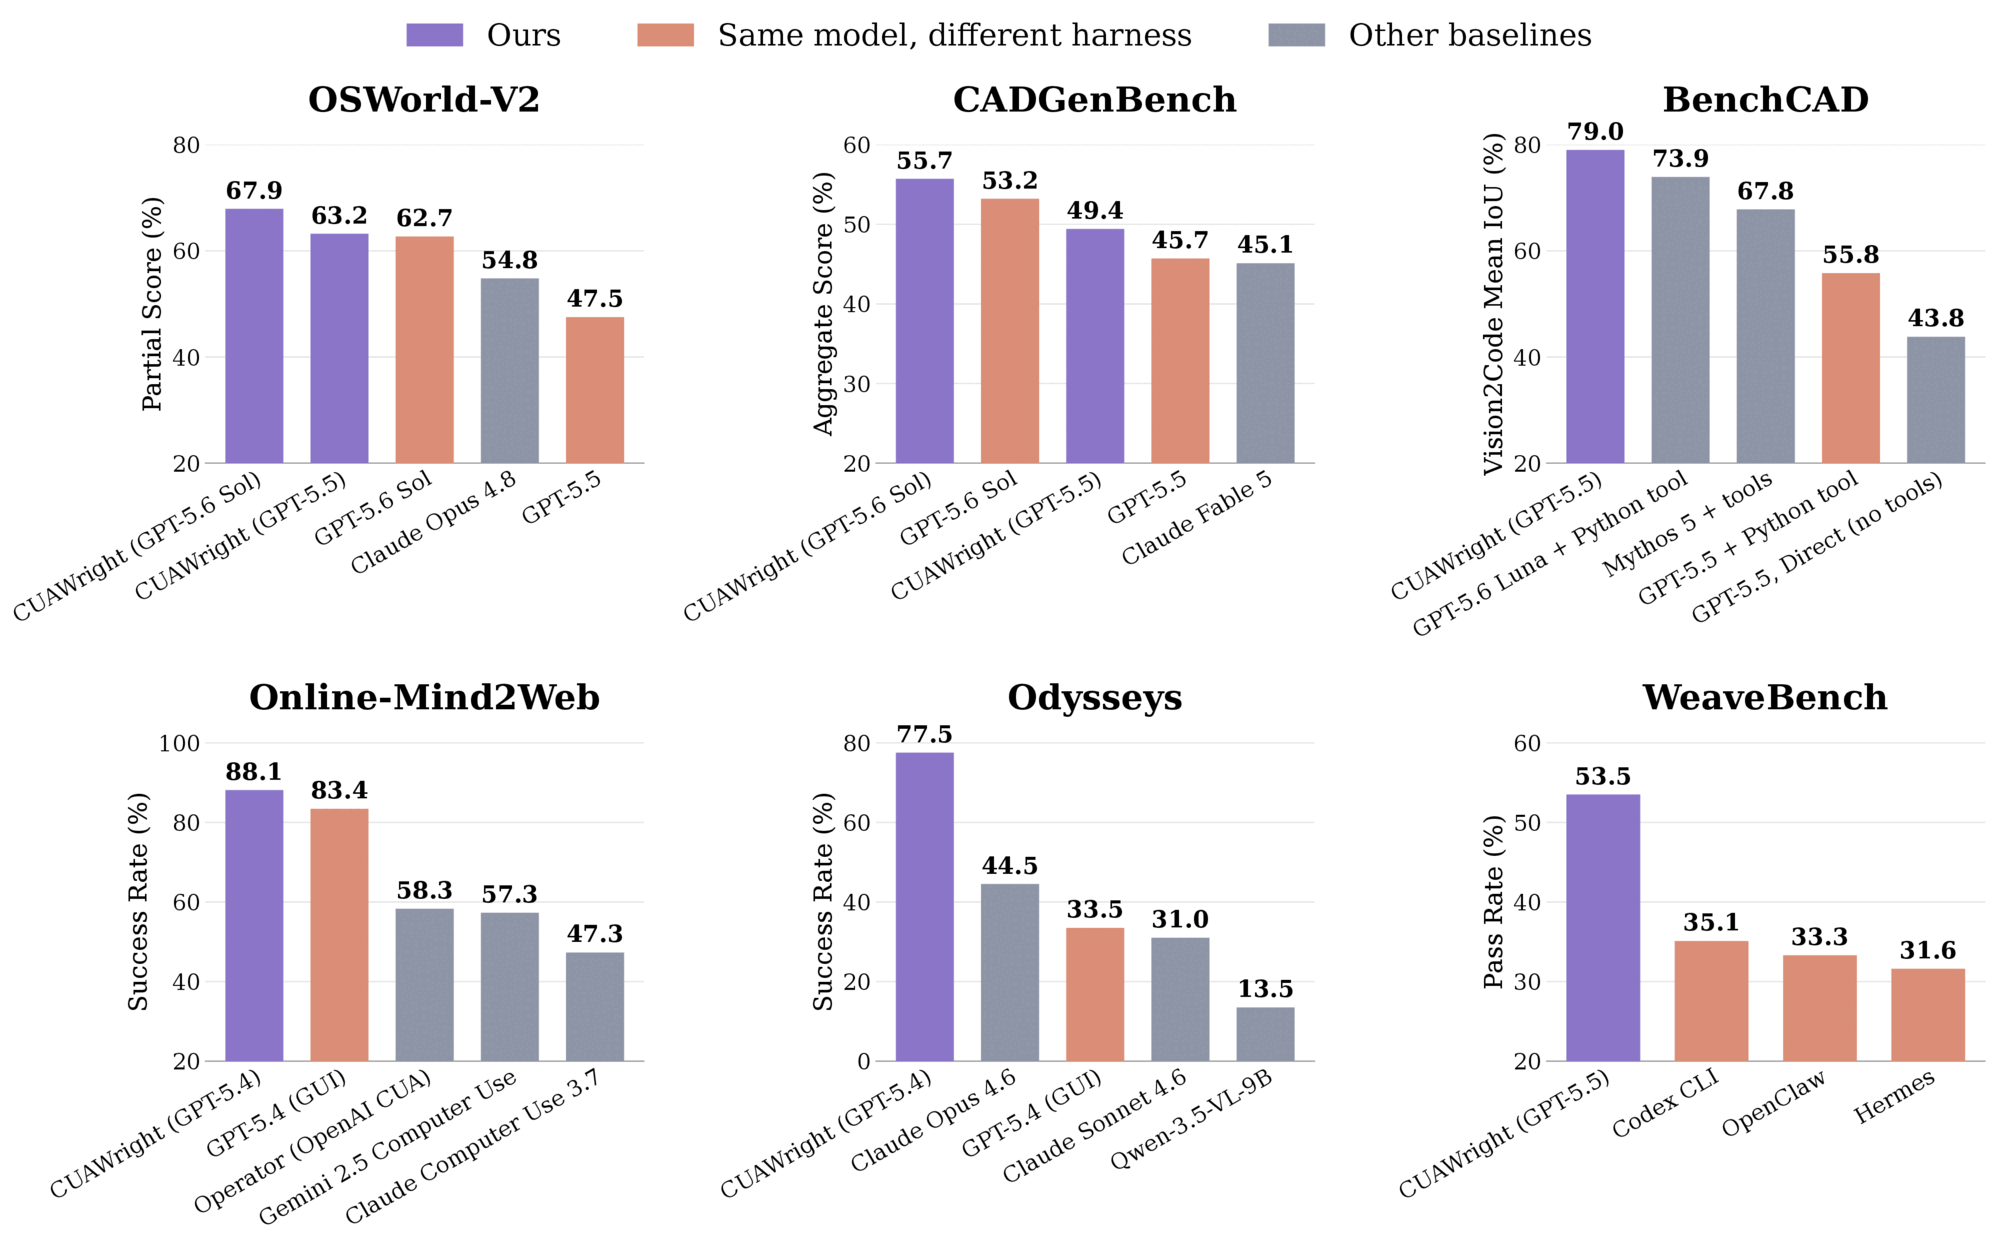
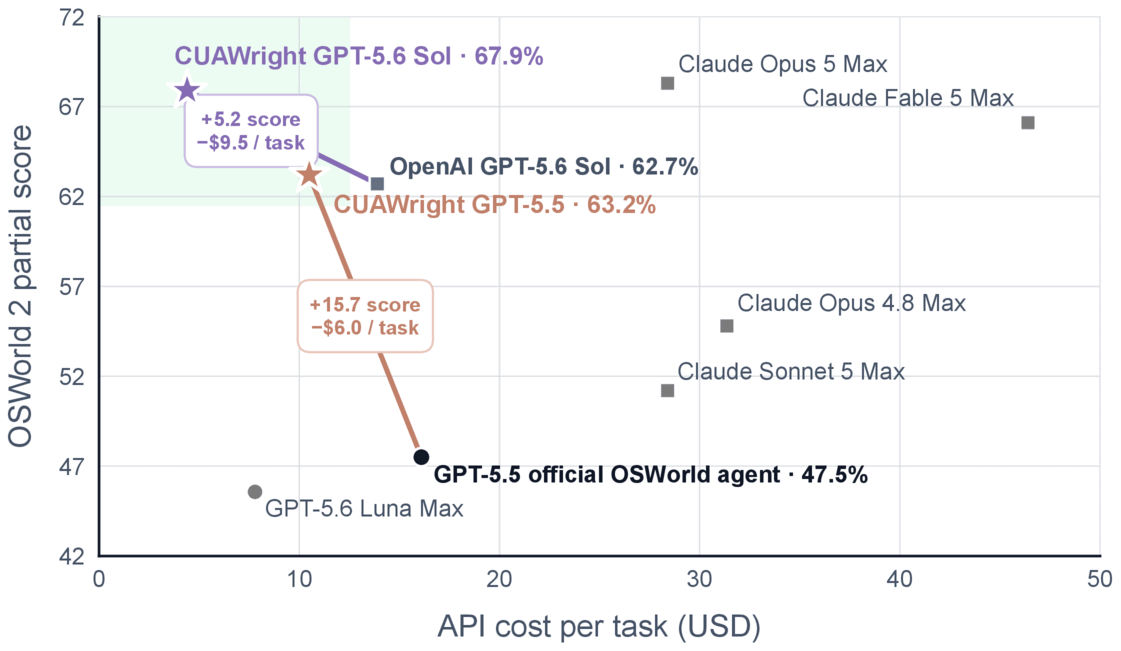
- 🖥️ OSWorld-V2: 67.9% partial score with GPT-5.6 Sol (+5.2 over GPT-5.6 Sol alone) and 63.2% with GPT-5.5 (+15.7 over the official GPT-5.5 OSWorld agent).
- 🌐 Web: 88.1% on Online-Mind2Web and 77.5% on Odysseys with GPT-5.4, against 83.4% and 33.5% for a GPT-5.4 GUI agent.
- 📐 CAD: 79.0% Vision2Code mean IoU on BenchCAD with GPT-5.5, and 55.7% aggregate score on CADGenBench with GPT-5.6 Sol.
- 💰 Cost: on OSWorld-V2, CUAWright raises the score while cutting API cost by $9.5 per task with GPT-5.6 Sol and $6.0 per task with GPT-5.5.
🗺️ Project Map

 @microsoft



