PRD-Led Context Engineering
Memory as Infrastructure — an operating system for building products with AI agents


Your AI partner is brilliant in one session and amnesiac by the next. This repository is the fix:
a fork-ready methodology that turns documentation into a knowledge graph humans and AI navigate
together — so the 50th session is smarter than the 1st.
Quick Start · The Idea ·
The Lifecycle · The Skills ·
Live Demo Views
⭐ If this changes how you build with AI, star the repo — stars put this method in front of the next team drowning in context drift.
The Problem: AI forgets. Teams drift.
Every era of software solved memory its own way — and broke it its own way:
- Waterfall had Static Memory. Write everything down upfront: certainty, at the cost of change.
- Agile moved fast and created Fragmented Memory. Knowledge scattered across tickets, wikis, and chats; shared understanding evaporated.
- AI-assisted building adds a third failure: Amnesiac Memory. The model that architected your system yesterday has never heard of it today.
The common mistake is treating these as tooling problems. They are memory problems.
PRD-Led Context Engineering builds Shared Memory: it treats AI as a team member, not a tool, and keeps documentation synchronized with code so humans and AI navigate the same truth.
The Idea: Memory as Infrastructure
This methodology comes from two converging experiences.
Leading human teams — alignment always followed the same pattern: rally around a single Source-of-Truth artifact and the team moves as one. Without it, even great talent drifts.
Partnering with AI — sometimes the model performs at a senior level, sometimes it hallucinates. The variable was never the model's intelligence. It was the Context Density provided: rich, structured context in; senior-level output out.
The convergence: documentation is not an afterthought. Documentation is the infrastructure of shared memory.
The Golden Rule: If it isn't part of the memory infrastructure, it isn't true.
So every durable decision gets a Unique ID (UJ-101, BR-004, API-045) in a Source-of-Truth file. That ID is a memory node with weight: when the AI references BR-004, it isn't guessing — it's retrieving a specific, validated decision you encoded. The linked network of IDs across files is the Knowledge Graph, and it lives in plain markdown, in your repo, under version control.
The 4 Pillars
- Just-in-Time Context — IDs let you load only what a task needs. No repo-dumps, no noise, fewer hallucinations.
- The Documentation Ecosystem — PRD ↔ EPICs ↔ SoT connected by links, skills, and hooks. When logic changes, both human and AI know.
- Context Validation — context is measured like code. Too sparse, the AI drifts; too dense, it chokes. The repo scores itself (see Readiness Scoring).
- Progressive Documentation — update in place, never copy. No
PRD_v2.md, ever. One document, many versions, single current reality.
The Cognitive Shift
This changes how work is measured, not just how it's tooled:
| Traditional Agile | PRD-Led Context Engineering | The Shift |
|---|
| Sprints | Context Windows | We don't time-box based on dates; we scope-box based on cognitive capacity. |
| User Stories | Prompts | We don't write descriptions; we engineer prompts that deterministically load context. |
| Tribal Knowledge | Source of Truth | If it isn't in the Knowledge Graph (SoT/), it doesn't exist. |
| Standups | Documentation Hooks | No status meetings. Event-driven hooks handle context loading, gate checks, and memory handoffs. |
| Project Management | Context Governance | We don't task-manage people. The system gates execution until context is verified valid. |
What's in the box
Everything below ships in this repo, works offline, and forks in one click:
| Feature | What it gives you |
|---|
| 🧠 The Knowledge Graph | 14 SoT files, 21 ID types, zero databases — durable memory in markdown |
| 📈 The Progressive PRD | A gated v0.1 → v1.0 lifecycle that stops AI from one-shotting your architecture |
| 🛠 47 Skills | Stage playbooks from problem framing to crossing the chasm — Dunford, Hormozi, Moore, Torres built in |
| 📊 Readiness Scoring | The repo computes whether you're ready to advance — and what to fix first |
| 🫀 The Development Graph | @implements tags bridge code to specs; drift surfaces as a verdict, not a surprise |
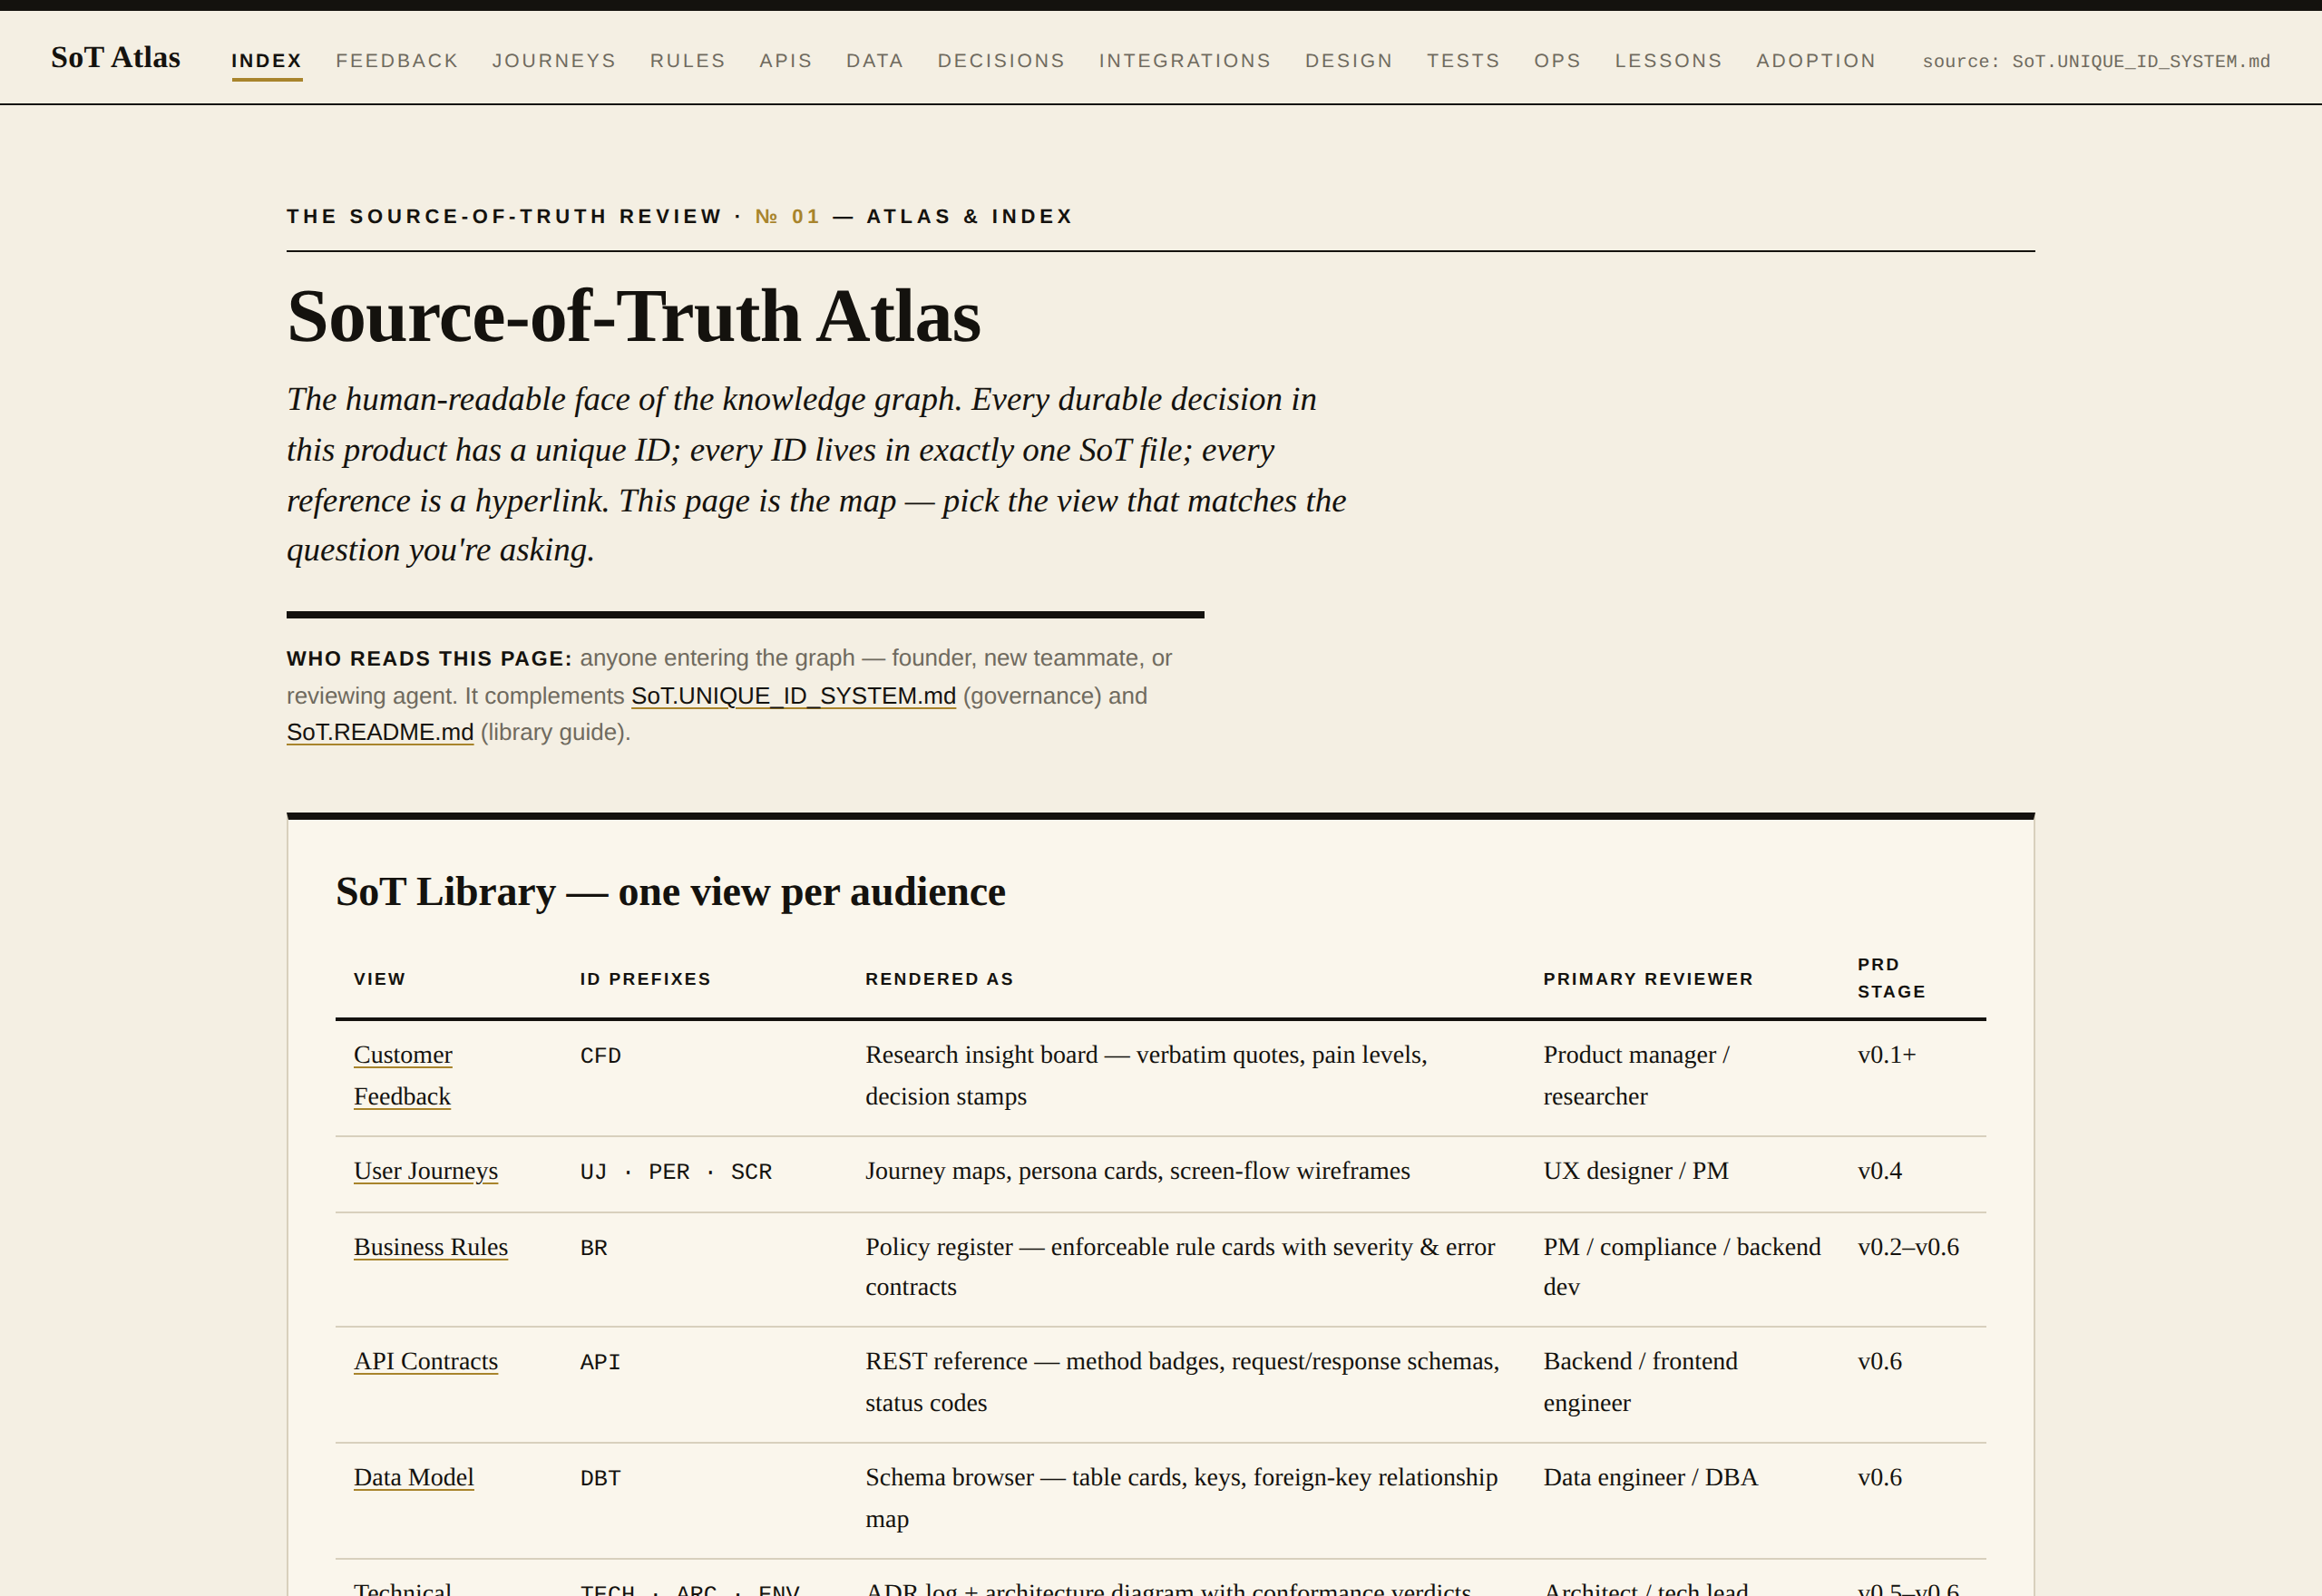
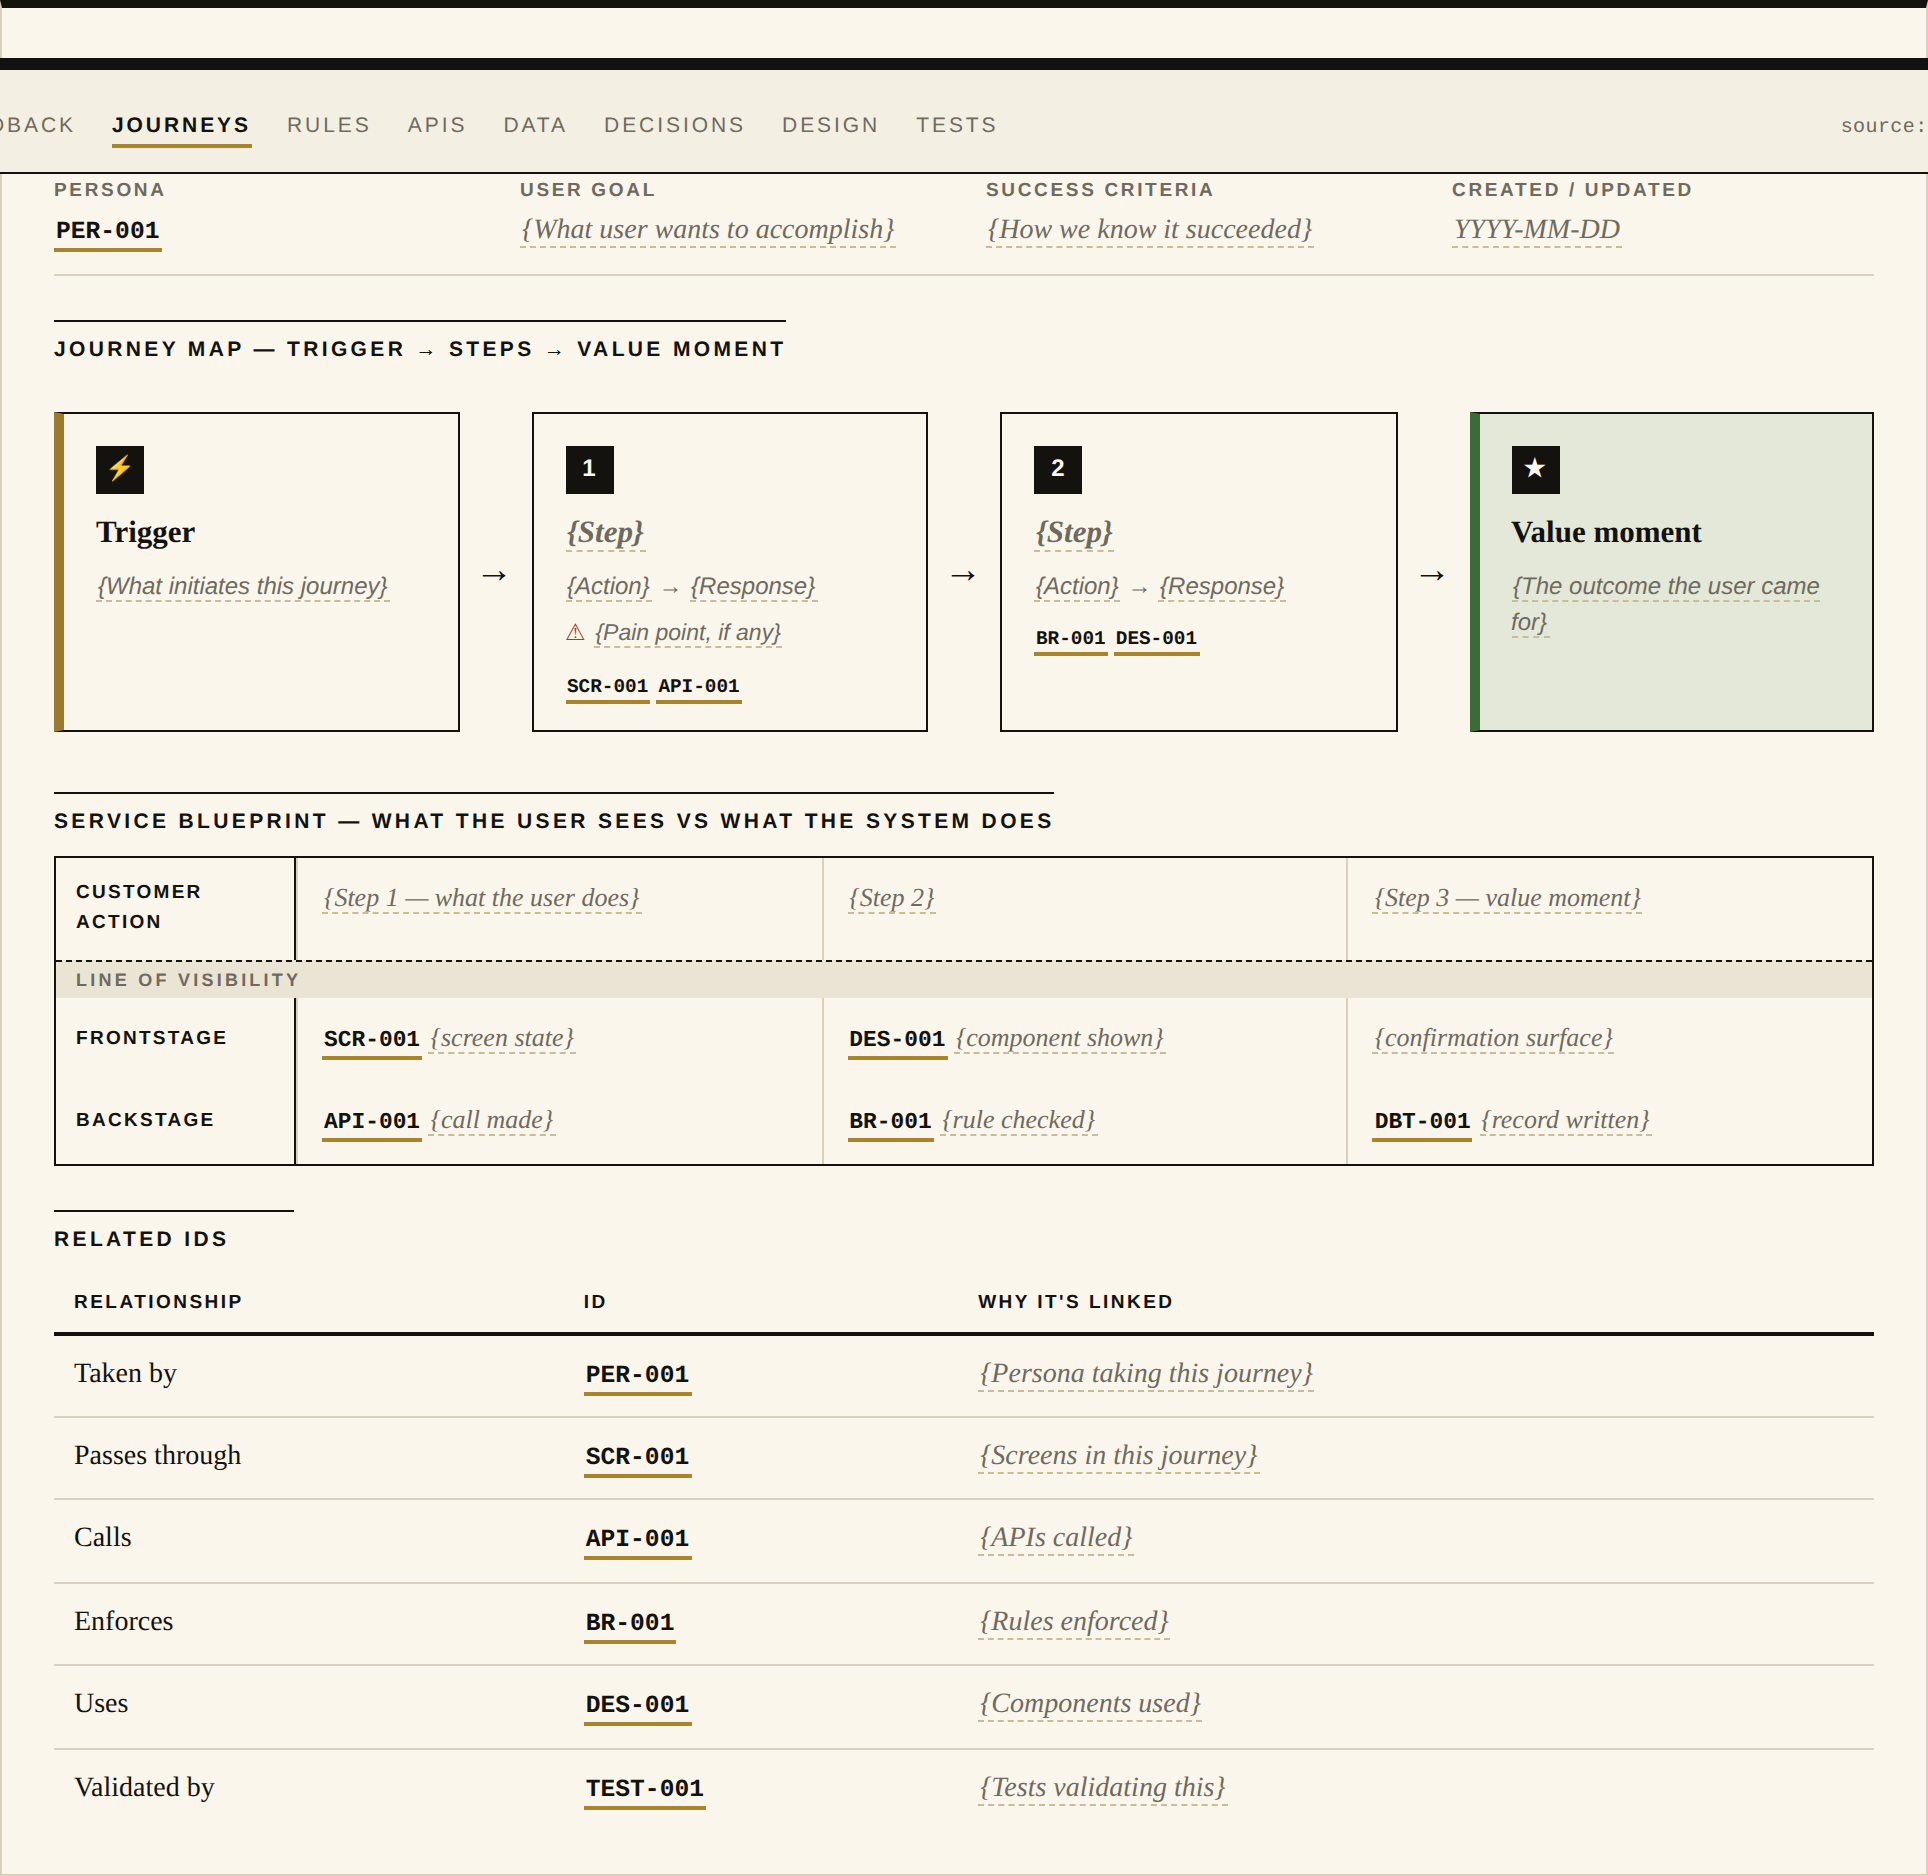
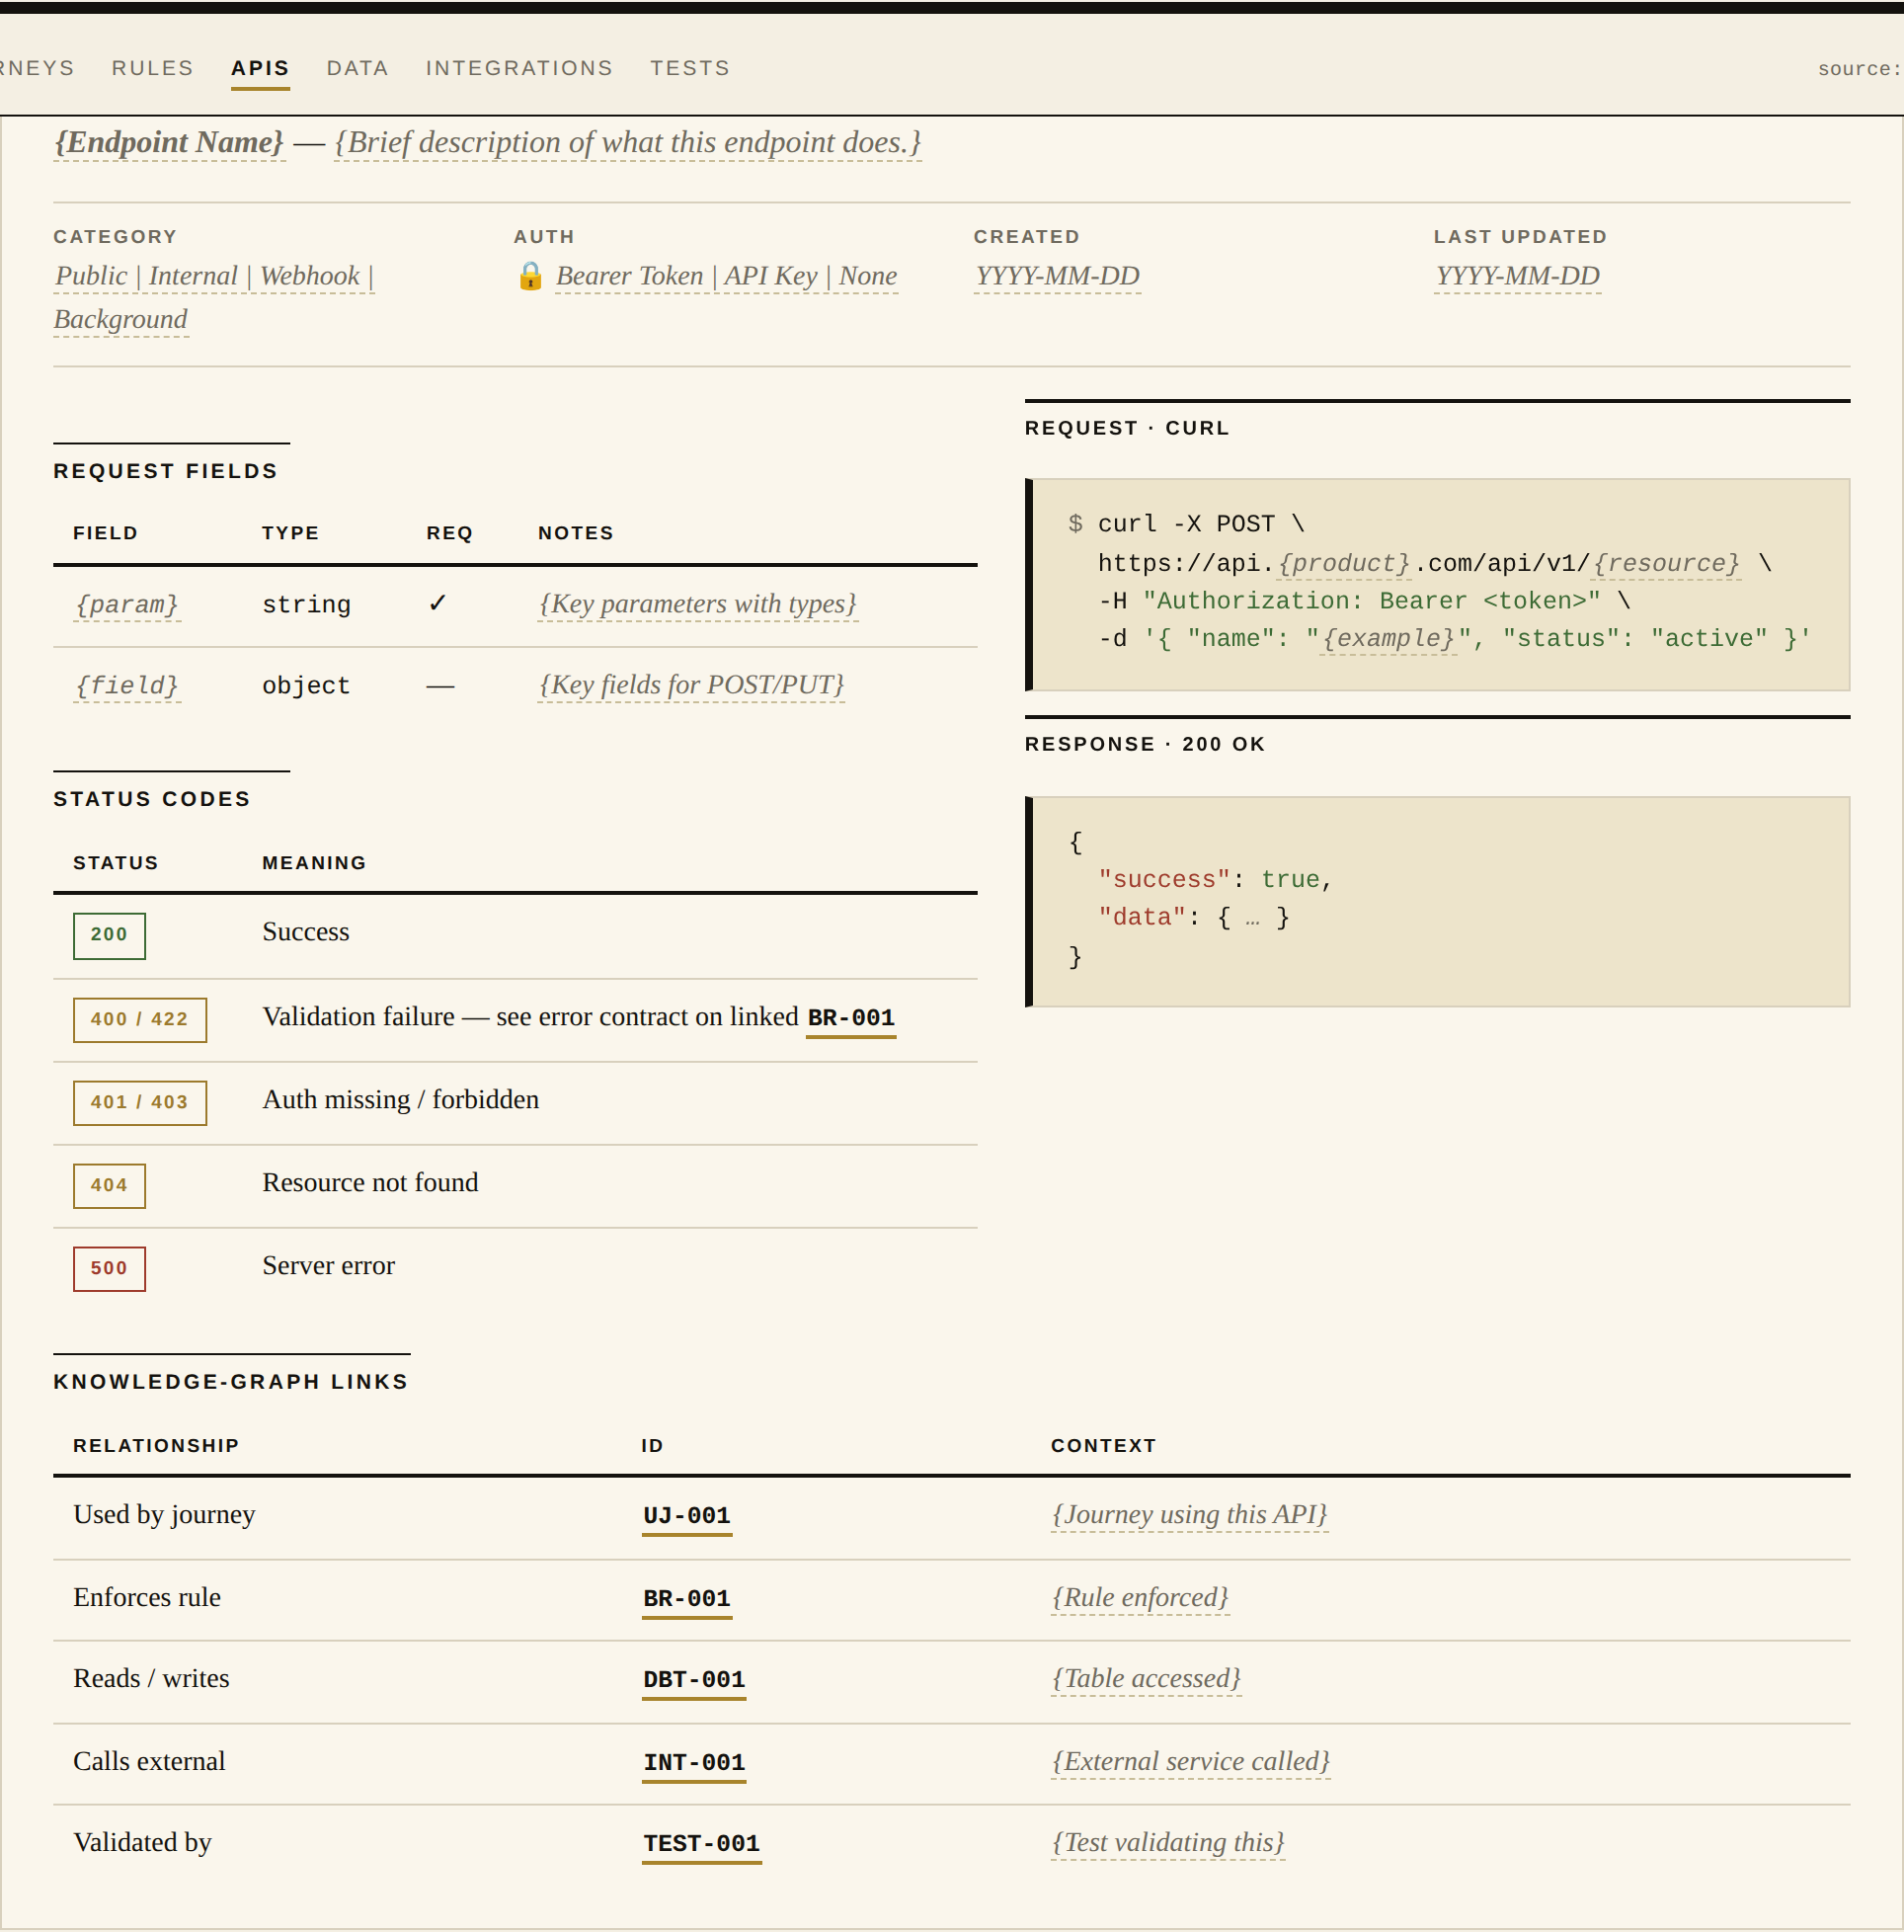
| 📰 The Human Review Layer | Every SoT file rendered as a styled, hyperlinked page its reviewer actually wants to read |
| 🤖 The Agent Squad | Four role agents with persistent memory, coordinated through files instead of meetings |
🧠 Feature: A Knowledge Graph in plain markdown
The pitch: long-term product memory with no database, no SaaS, no lock-in — just files with discipline.
The architecture is 3 + 1 + SoT + Temp, designed to manage Context Density for both human cognitive load and AI context windows:
- Executive Functions — orient attention. Files load stable→volatile to maximize prompt-cache hits:
README.md — the Dashboard (where am I? what is active?)PRD.md — the Strategy (why and what)CLAUDE.md — the Physics (how the AI must behave)
- Focus Memory —
epics/: the only variable state. An EPIC frames one problem as one context window.
- Long-Term Memory —
SoT/SoT.*.md: the immutable facts. Business Rules (BR-), User Journeys (UJ-), API Contracts (API-), and 18 more ID types. Nothing duplicated; everything referenced by ID.
- Short-Term Memory —
temp/: the scratch pad. Files attach to the active EPIC and get harvested to SoT before the EPIC closes.
Just-in-Time Context: instead of dumping documentation into the context window, reference specific IDs (UJ-101, API-002). Fewer input tokens, deeper understanding.
📈 Feature: The Progressive PRD
The pitch: the "One-Shot" — asking AI to build the whole app at once — produces generic code and rapid drift. The Progressive PRD makes that impossible by design.
PRD.md is a gated workflow, not a document. The AI focuses on one stage at a time, and no stage advances until its Definition of Done is met:
| Version | Name | Focus | Definition of Done (DoD) |
|---|
| v0.1 | Spark | Problem & Outcomes | Problem defined, Outcomes measurable, Open Questions list. |
| v0.2 | Market Definition | Segments & ICP | Segments sized, "Not For" defined, Business Rules (BR-) created. |
| v0.3 | Commercial Model | Value & Pricing | Competitors profiled, Pricing model, Monetization rules. |
| v0.4 | User Journeys | Personas & Flows | Core journeys mapped (UJ-), Dependencies (API-) noted. |
| v0.5 | Red Team Review | Risks & Feasibility | Risks (Market/Tech) identified, Mitigations linked to tests. |
| v0.6 | Architecture | Technical Strategy | Stack selected, API contracts (API-) drafted, ARC- conformance rules, Cost guardrails. |
| v0.7 | Build Execution | Implementation Loop | Code tested (TEST-), SoT updated, code traced to specs (Development Graph), Epic loop execution. |
| v0.8 | Release & Deployment | Operational Readiness | Runbooks (RUN-), Monitoring (MON-, MON-DRIFT-), Rollback plan, Changelog system, MOPS handoff. |
| v0.9 | Launch | Go-to-Market | Positioning (Dunford), Offer (Hormozi), Channels (ORB), Launch metrics (KPI-), Feedback channels (CFD-), Tactical playbooks (AEO, alternatives, outreach, HN/Reddit). |
| v1.0 | Growth | Market Adoption | Adoption stage (ADO-STAGE-), Beachhead (ADO-BEACHHEAD-), Whole product (ADO-WHOLE-), References (ADO-REF-), Continuous discovery, Case studies, Testimonials. |
Why gates work: constrained focus prevents the AI from guessing the architecture before it understands the users; deep focus produces meaningful IDs; the result is not just a working product but a desirable one.
The paradox that makes it practical: gates provide focus; the ecosystem provides agility. Because documentation is modular and interlocked, you can revisit any stage just-in-time — customer feedback during Build doesn't restart the plan, it updates the BR- rules and lets hooks propagate the change.
🛠 Feature: 47 skills, one for every decision
The pitch: the lifecycle isn't advice — it's executable. Every stage ships with skills that know what to consume, what IDs to produce, and which gate they feed.
- 41 stage skills (
prd-v01-* → prd-v10-*): problem framing, competitive landscape, pricing, persona definition, journey mapping, risk discovery, architecture design, epic scoping, test planning, release planning, GTM strategy, case studies…
- 6 methodology operators (
ghm-*): gate checks, SoT building, ID registration, insight harvesting, status sync.
- Named frameworks, encoded: April Dunford positioning, Alex Hormozi offer construction, Owned/Rented/Borrowed channel allocation, Geoffrey Moore chasm crossing, Teresa Torres continuous discovery, Rob Fitzpatrick Mom Test interviews.
- Three depth modes —
quick (founder gut-check, <15 min), standard (default), deep (investor-ready, with assumption logs) — so the method scales from solo founder to team.
Every skill emits Consumes / Produces sections in SoT IDs, which is what keeps the knowledge graph connected as you move through stages.


 @upstash


