


English | 한국어
⚠️ Did you know? Claude Code deletes your session data after 30 days by default. Once deleted, your token usage and cost history are gone forever — unless you preserve them.
The token & cost tracker that never loses your history. Most tools re-read your CLI's session files on every run — so when Claude Code deletes them after 30 days, your cost history goes with them. toktrack keeps a persistent cache, so your history survives.
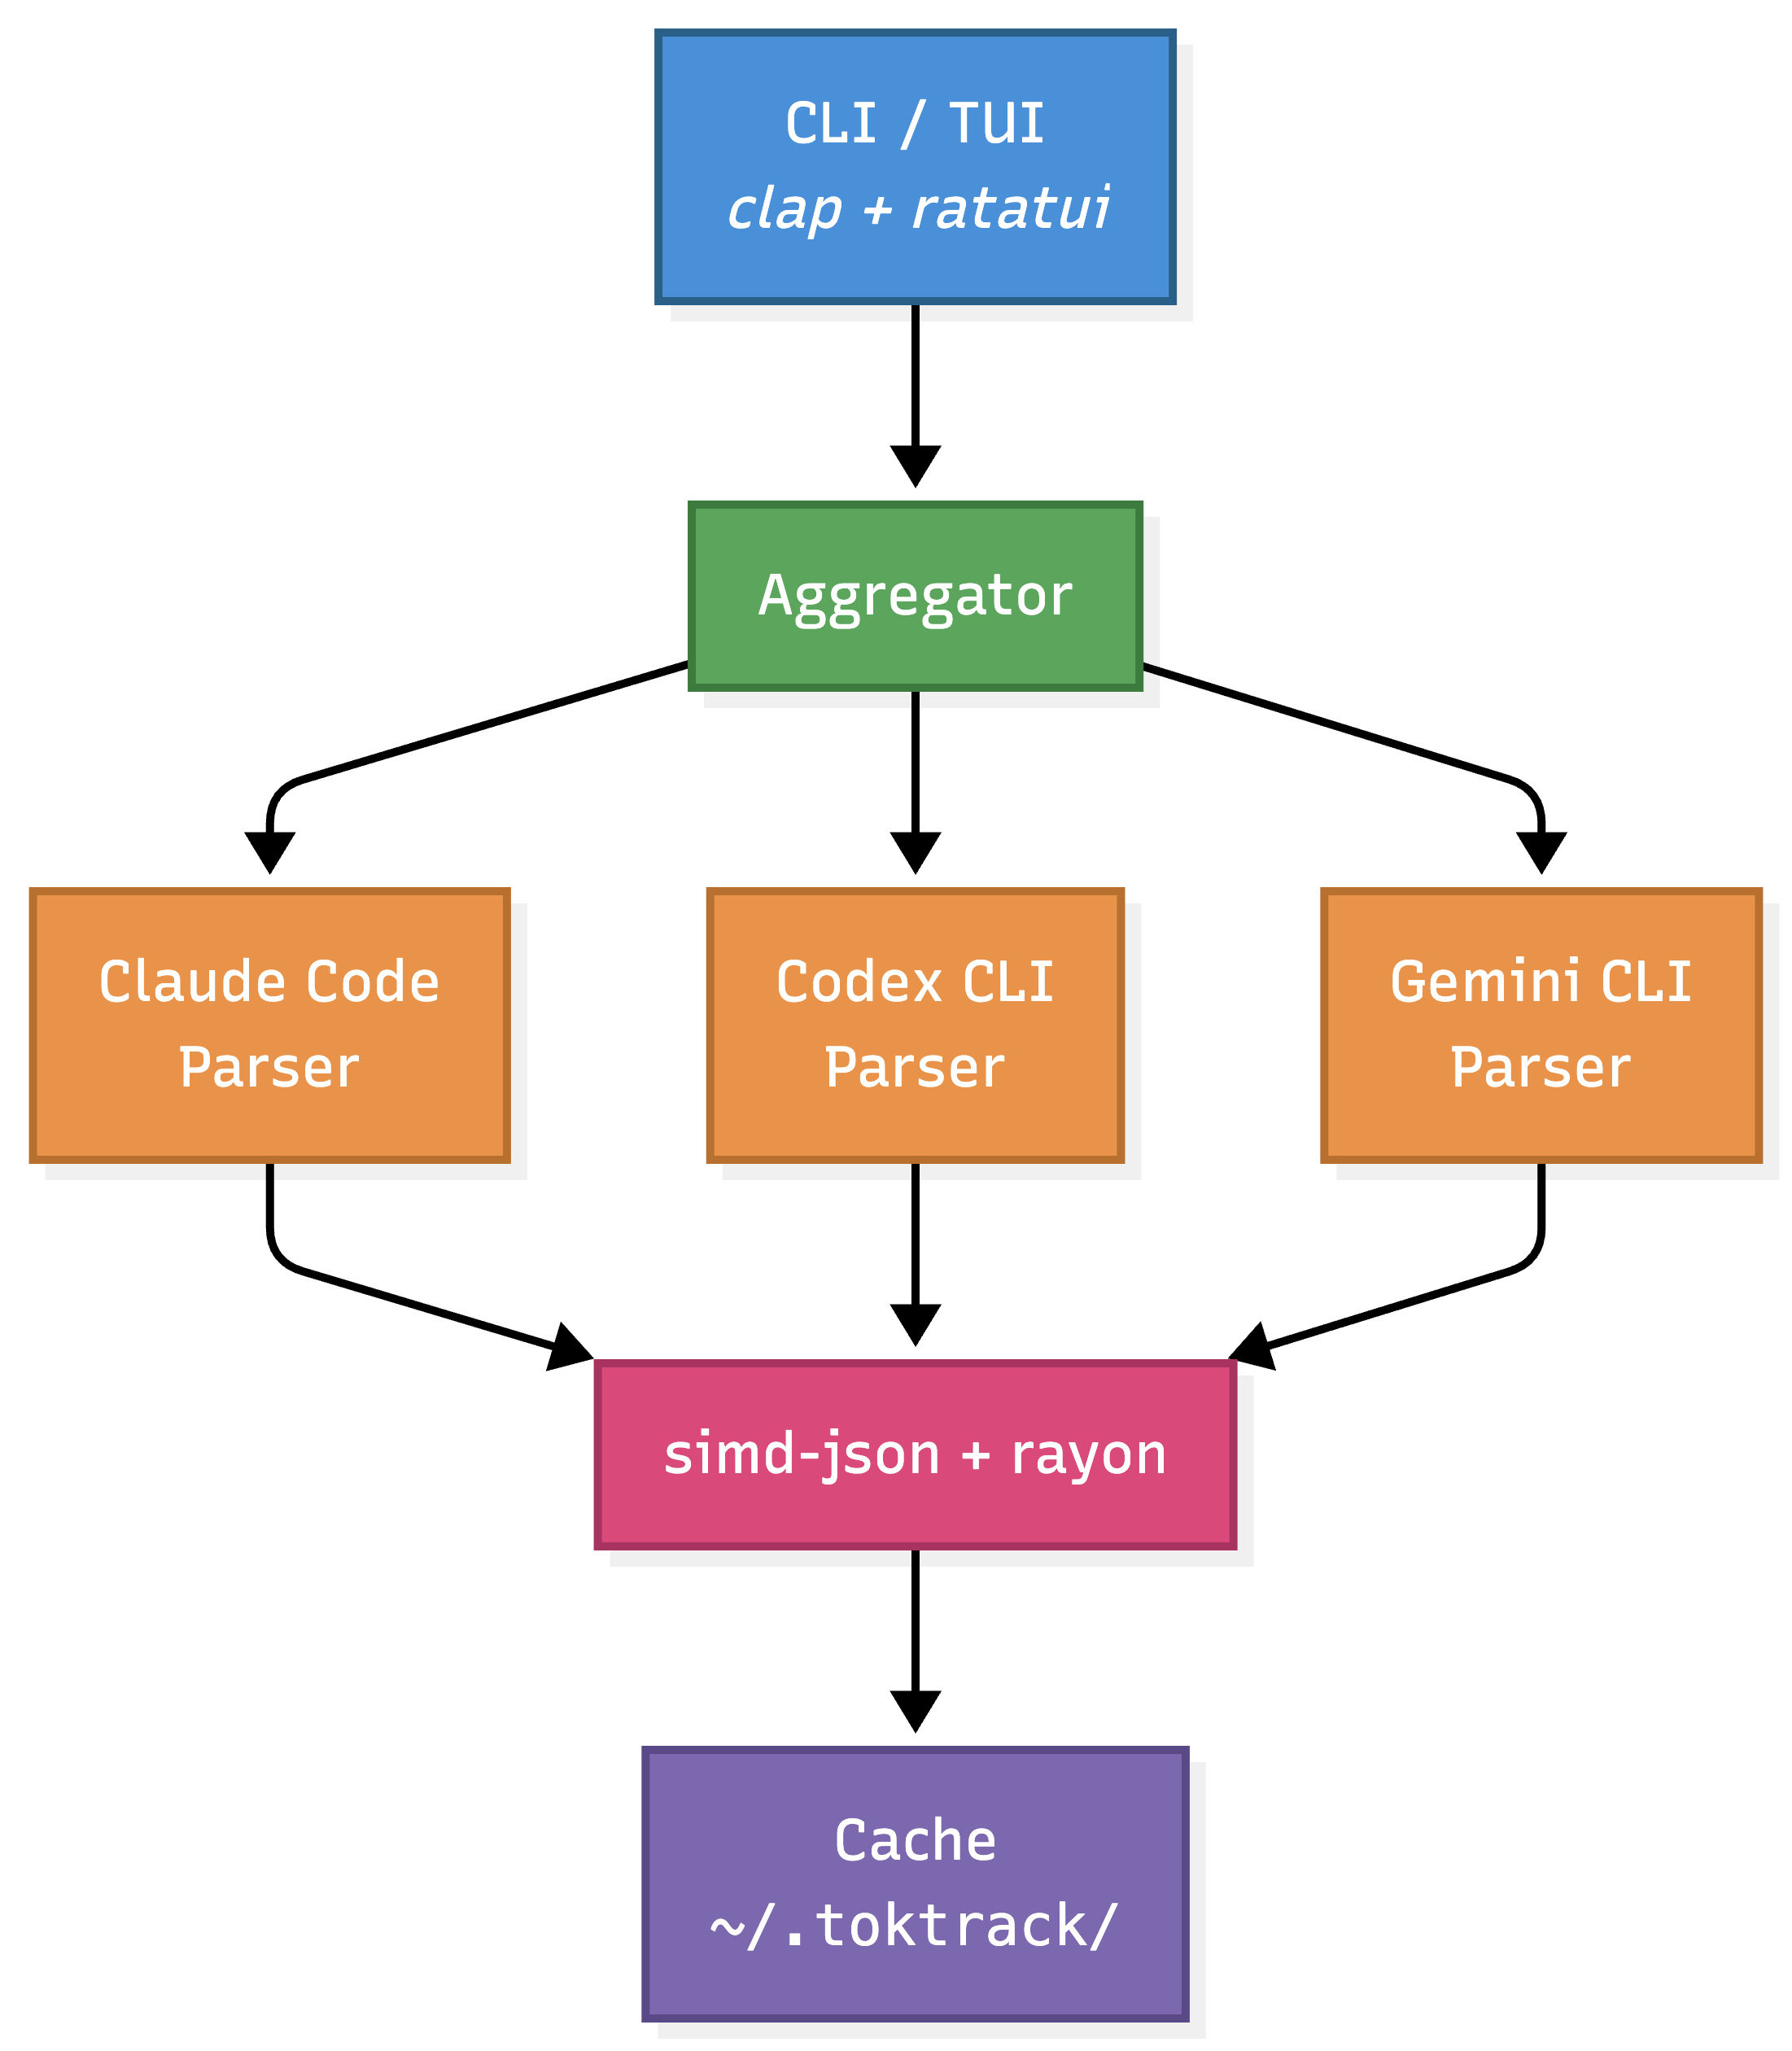
Track usage across all your AI coding CLIs — Claude Code, GitHub Copilot CLI, Codex CLI, Gemini CLI, Qwen Code, OpenCode, PI Agent, Antigravity, and Grok CLI — in one dashboard. Built in Rust, so it stays fast even on huge histories (simd-json + rayon).
Why toktrack?
| Problem | Solution |
|---|
| 🗑️ Claude Code deletes data after 30 days — your cost history disappears | 💾 Persistent cache — history survives even after the CLI deletes its files |
| 📊 No unified view — each CLI keeps its own separate data | 🎯 One dashboard — Claude Code, Copilot, Codex, Gemini, Qwen, OpenCode, PI Agent, Grok in one place |
| 🐌 Re-scanning big histories is slow | ⚡ Cached queries in ~0.04s — instant on every run |
Features
- Data Preservation — Persistent cache keeps your cost history even after a CLI deletes its own session files
- Multi-CLI Support — Claude Code, GitHub Copilot CLI, Codex CLI, Gemini CLI, Qwen Code, OpenCode, PI Agent, Antigravity, Grok CLI in one place
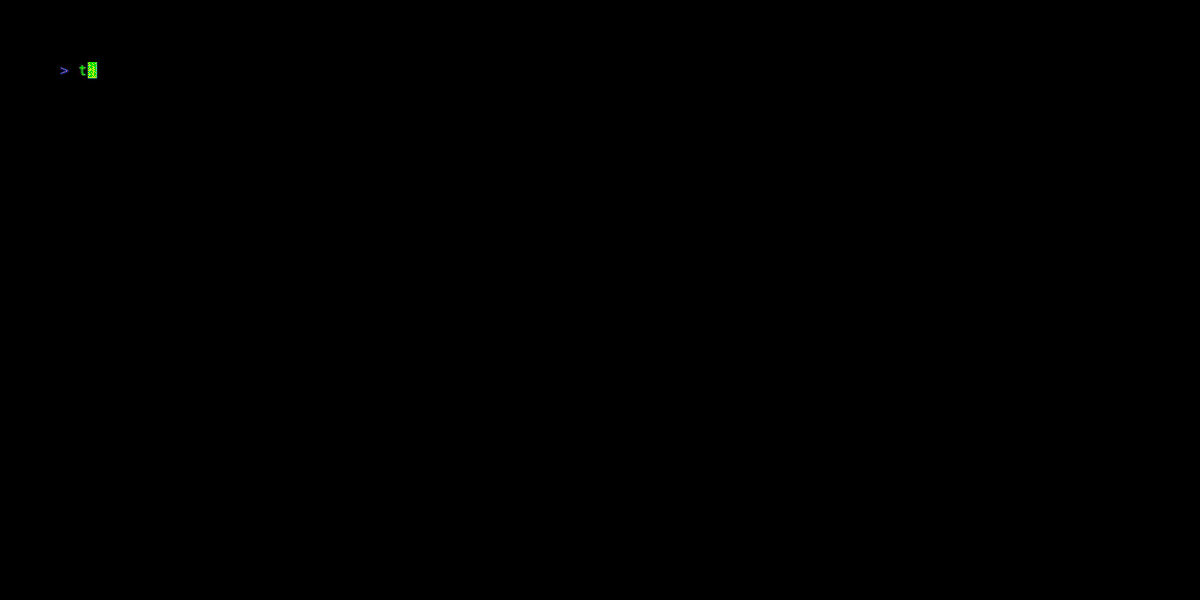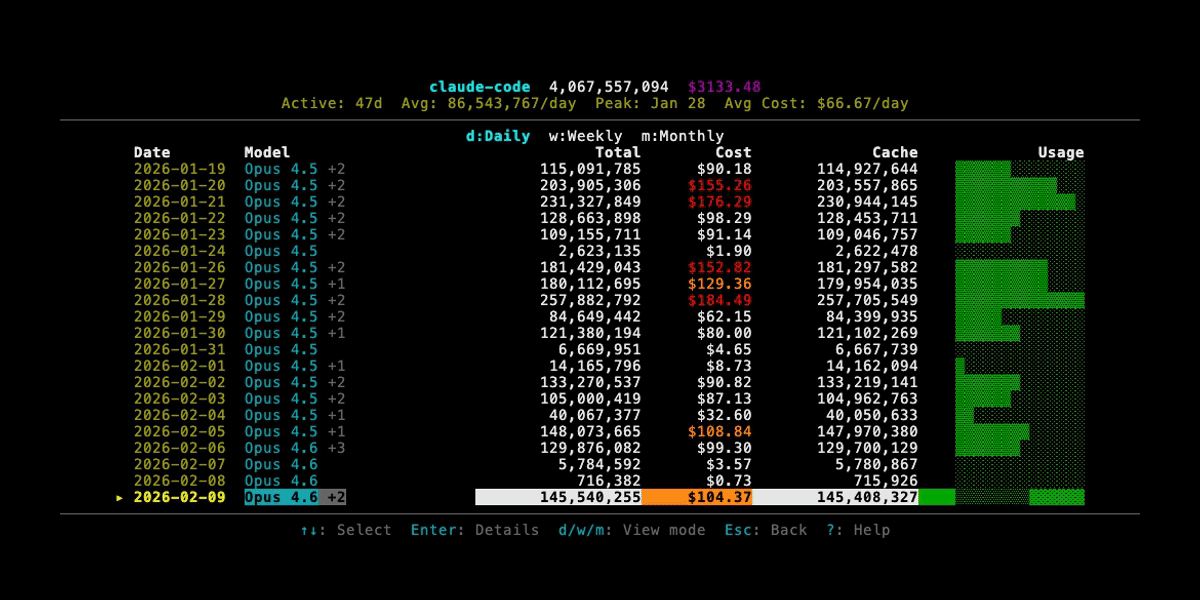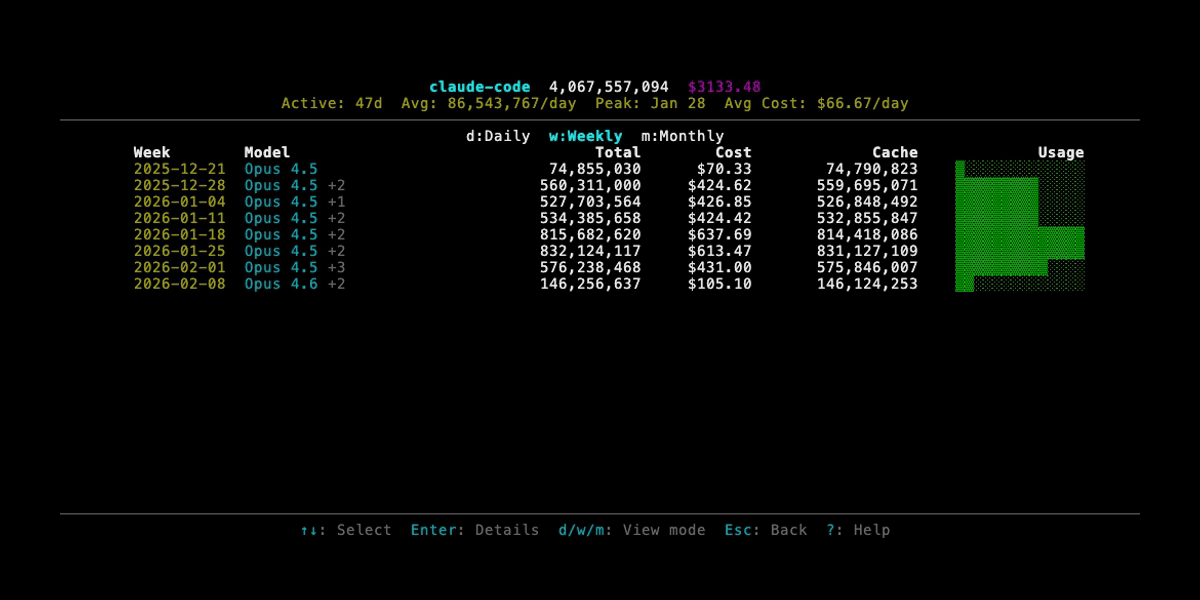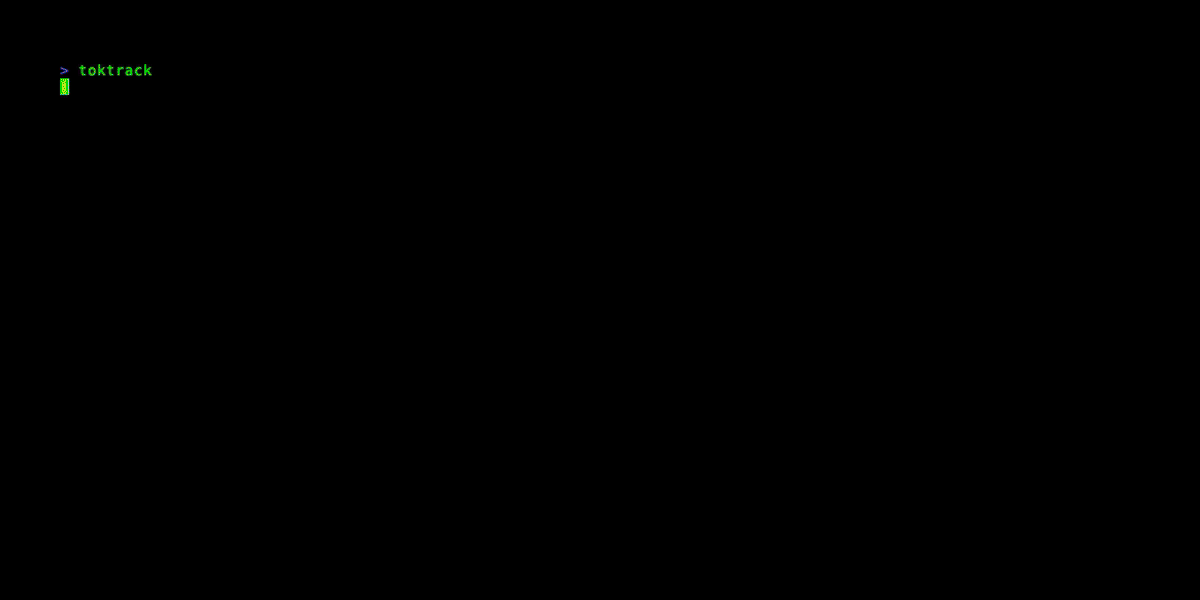
- TUI Dashboard — 5 tabs (Overview, Stats, Models, Projects, Audit) with daily/weekly/monthly views
- Per-Project Breakdown — the Projects tab shows token & cost usage per project (the session working directory), for CLIs that record one. Drill into any project for its day-by-day, per-model breakdown. Usage from CLIs that don't record a project is grouped under
(no project). Press * on a project to star it as a root folder: every project under it folds into its row (saved to ~/.toktrack/config.toml as project_roots). Sessions in a git worktree fold into the root of their main repository, even after the worktree is deleted (links are kept in ~/.toktrack/cache/worktree_links.json). Worktrees are matched through their .git link, so this works for any tool. The one tool-specific exception: a T3 Code worktree (~/.t3/worktrees/<repo>/…) deleted before toktrack saw it folds into the starred root named <repo>, unless another project with that folder name exists outside it. Project details are cached, so they survive past the CLI's 30-day deletion
- CLI Commands —
daily, weekly, monthly, stats with JSON output support
- Usage Reports — Shareable text & SVG receipts via
toktrack report
- Fast on huge histories — simd-json + rayon parallel parsing (~3 GiB/s); cached runs in ~0.04s
Installation
npx (Recommended)
No Rust toolchain required. Downloads the correct binary for your platform automatically.
npx toktrack
# or
bunx toktrack
Homebrew (macOS / Linux)
brew tap mag123c/toktrack
brew install toktrack
From Source
cargo install --git https://github.com/mag123c/toktrack
Pre-built Binaries
Download from GitHub Releases.
| Platform | Architecture |
|---|
| macOS | x64, ARM64 |
| Linux | x64, ARM64 |
| Windows | x64 |
Quick Start
# Launch TUI dashboard
npx toktrack

# Get today's cost in JSON
npx toktrack daily --json

# Monthly summary
npx toktrack monthly --json
Usage
TUI Mode (Default)
toktrack
CLI Commands
# Open TUI at specific tab
toktrack daily     # Overview (daily view)
toktrack weekly    # Overview (weekly view)
toktrack monthly   # Overview (monthly view)
toktrack stats     # Stats tab

# JSON output (for scripting)
toktrack daily --json
toktrack weekly --json
toktrack monthly --json
toktrack stats --json

# Usage report (shareable receipt)
toktrack report              # Last 7 days (text)
toktrack report --month      # Last 30 days
toktrack report --days 14    # Last N days
toktrack report --svg        # Text + SVG file

# Data-preservation audit (live on disk vs cache-only)
toktrack audit               # Per-source coverage report
toktrack audit --json        # Machine-readable
Shell Integration
Show today's AI spend right in your prompt, updated after every command:
~/projects/api  main  $12.40
❯
A few lines of zsh/bash/fish — see Shell integration.
Remote Codex Sources
toktrack can include Codex session logs from SSH servers by syncing remote JSONL
files into a local snapshot and parsing them with the existing Codex parser. It
uses your existing ssh/rsync setup and never stores SSH passwords or keys.
Create ~/.toktrack/config.toml:
default_remotes = ["devbox"]

[[remotes]]
name = "devbox"
target = "ubuntu@devbox"

[remotes.paths]
codex = "~/.codex/sessions"

[[remotes]]
name = "prod"
target = "prod-alias"

[remotes.paths]
codex = "/home/codex/.codex/sessions"
You can also manage the same config from the CLI:
toktrack remote add devbox ubuntu@devbox --default
toktrack remote add prod prod-alias --codex-path /home/codex/.codex/sessions
toktrack remote default add prod
toktrack remote default remove devbox
toktrack remote remove prod
toktrack remote list
By default, commands read local data plus default_remotes:
toktrack report
toktrack daily --json
Override the configured defaults when needed:
toktrack --remote prod report      # local + default_remotes + prod
toktrack --all-remotes stats       # local + every configured remote
toktrack --local-only report       # local only
Remote Codex sources appear as codex@<remote-name> and use separate cache
files such as ~/.toktrack/cache/codex@devbox_daily.json.
If a remote sync fails, toktrack warns and continues with local data plus any
existing snapshot/cache for that remote.
Keyboard Shortcuts
| Key | Action |
|---|
1-5 | Switch tabs directly (incl. Projects, Audit) |
Tab / Shift+Tab | Next / Previous tab |
j / k or ↑ / ↓ | Scroll up / down |
Enter | Open model breakdown popup (Daily tab) |
d / w / m | Daily / Weekly / Monthly view (Daily tab) |
s / S | Sort by date → cost → tokens / Reverse direction (detail views) |
* | Star / unstar a root folder (Projects tab) |
d / w / m / a | Today / This week / This month / All time spend (Projects tab) |
r | Refresh data |
? | Toggle help |
Ctrl+C | Quit |
Supported AI CLIs
| CLI | Status | Data Location |
|---|
| Claude Code | ✅ | ~/.claude/projects/ |
| GitHub Copilot CLI | ✅ | ~/.copilot/session-state/*/events.jsonl |
| Codex CLI | ✅ | ~/.codex/sessions/ |
| Gemini CLI | ✅ | ~/.gemini/tmp/*/chats/ |
| Qwen Code | ✅ | ~/.qwen/tmp/*/chats/ |
| OpenCode | ✅ | ~/.local/share/opencode/storage/message/ |
| PI Agent | ✅ | ~/.pi/agent/sessions/ |
| Antigravity | ✅ | ~/.gemini/antigravity-{ide,cli}/conversations/*.db |
| Grok CLI | ✅ | ~/.grok/sessions/*/*/updates.jsonl |
Costs from sources that don't record their own price (Gemini, Qwen, Codex, Antigravity, GitHub Copilot, and modern Claude logs)
are computed from LiteLLM API list-price estimates and shown with a ~ marker
(estimated). For GitHub Copilot CLI, the displayed value is the API-equivalent cost rather than your actual subscription/credit spend.
Sources that do record their own cost (Grok CLI, OpenCode, PI Agent, and older Claude logs) have it
used verbatim rather than estimated. The ~ marker is per source, not per entry: if any one entry in
a source lacks an upstream cost, the whole source is marked estimated. A Grok turn that reports no
cost of its own falls back to the pricing table, which has no bare grok-4.6 key, so it contributes
$0 to the totals.
Pricing works offline via a bundled snapshot when the network is unavailable.
1h ephemeral cache writes are billed at their own higher rate, and Claude Code requests made in
fast mode (/fast) are billed at the provider's fast multiplier. A model LiteLLM has no price for
shows ? instead of a cost, so a $0 row is never mistaken for free usage.
Codex Fast costs follow the thread_settings_applied.thread_settings.service_tier
snapshots a session recorded: priority and legacy fast enable Fast pricing, other
or missing tiers use Standard. That event is the only place Codex writes the tier, and
many sessions contain none of them, so usage with no tier on file stays Standard rather
than inheriting today's local config. Expect Fast pricing to show up only for the
sessions that recorded it, not for every session you ran in Fast mode. Known model
multipliers match
ccusage's model table
(GPT-5.5: 2.5×; GPT-5.3-Codex, GPT-5.4, GPT-5.6/Sol/Terra/Luna, and GPT-6 Astra: 2×), and
a model with no published Fast rate stays at Standard. These are dollar cost estimates,
not ChatGPT credit balances. Upgrading recalculates dates with available logs while
preserving cached history whose logs are no longer available.
Environment Variables
Each source's data directory can be overridden (matching the upstream CLI's own variable):
| Variable | Source | Default |
|---|
CLAUDE_CONFIG_DIR | Claude Code (root) | ~/.claude (+ /projects) |
COPILOT_HOME | GitHub Copilot CLI | ~/.copilot (+ /session-state) |
CODEX_HOME | Codex CLI (root) | ~/.codex (+ /sessions) |
GEMINI_CLI_HOME | Gemini CLI (home root) | ~ (+ /.gemini/tmp) |
QWEN_HOME | Qwen Code | ~/.qwen (+ /tmp) |
OPENCODE_DATA_DIR / XDG_DATA_HOME | OpenCode | ~/.local/share/opencode |
PI_CODING_AGENT_SESSION_DIR (then PI_AGENT_DIR) | PI Agent | ~/.pi/agent/sessions |
GROK_HOME | Grok CLI | ~/.grok (+ /sessions) |
export CLAUDE_CONFIG_DIR="/path/to/.claude"
Custom pricing (including web_search / web_fetch per-request rates) can be set in ~/.toktrack/pricing.toml. Enter every rate in US dollars: token rates as USD per 1M tokens, and web_search / web_fetch as USD per request. toktrack has no currency setting; all costs are computed, summed and shown in USD.
Performance
| Run | Time |
|---|
| First run (cold) | ~1.0s |
| Daily use (cached) | ~0.04s |
Measured on Apple Silicon with 2,000+ JSONL files (3.4 GB). The persistent cache means only the current day is recomputed on each run — past days are read straight from cache, so daily use stays instant no matter how large your history grows.
Why it's fast: SIMD JSON parsing (simd-json) + parallel processing (rayon) = ~3 GiB/s throughput on the cold path.
Data Preservation
The Problem: You've been using Claude Code for 3 months, spending hundreds of dollars. One day you want to check your total spending — but Claude Code already deleted your session files from 2 months ago. That cost data is gone forever.


 @paddlepaddle


