

promptschat
Gives Claude Code access to the prompts.chat library, letting you search, retrieve and improve AI prompt templates, and find and install Agent Skills from its registry.
2 skills2 agents2 commands1 MCP+3+2+2+2+1+1+1+1175k
 @gh-f
Translates whole books in PDF, DOCX, or EPUB into any language by splitting them into chunks that parallel sub-agents translate. Outputs HTML, DOCX, EPUB, or PDF.
Claude Code
$ npx -y skills add deusyu/translate-book --agent claude-code
Codex
$ npx skills add deusyu/translate-book -a codex
Cursor
$ npx skills add deusyu/translate-book -a cursor
Gemini CLI
$ npx skills add deusyu/translate-book -a gemini-cli
GitHub Copilot
$ npx skills add deusyu/translate-book -a github-copilot
OpenCode
$ npx skills add deusyu/translate-book -a opencode
Windsurf
$ npx skills add deusyu/translate-book -a windsurf
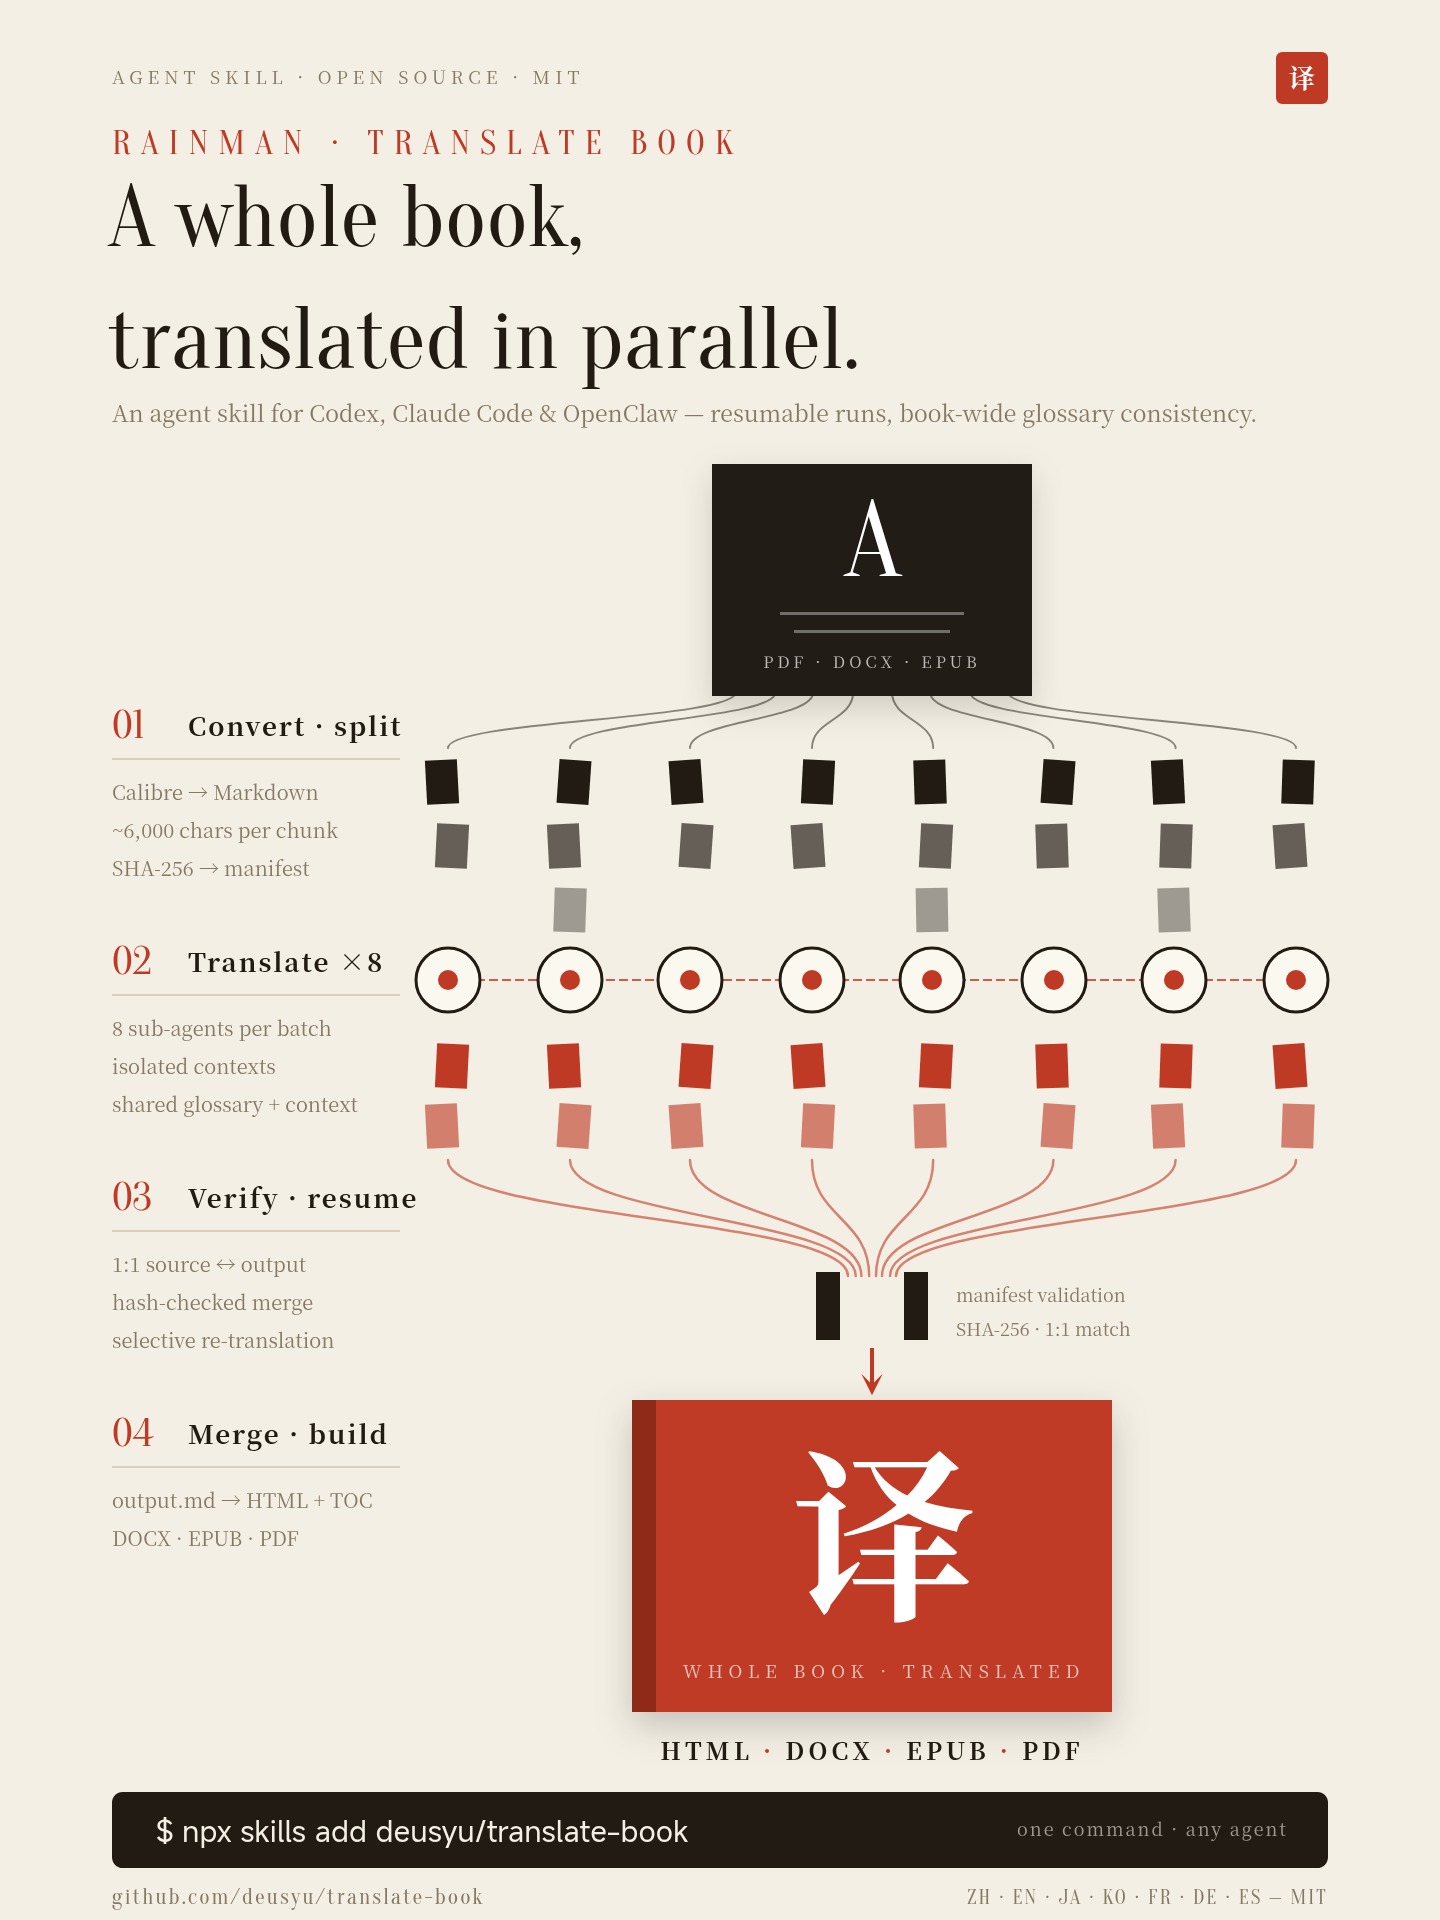
An agent skill for Codex, Claude Code, and OpenClaw that translates entire books (PDF/DOCX/EPUB) into any language using parallel subagents.
Inspired by claude_translater. The original project uses shell scripts as its entry point, coordinating the Claude CLI with multiple step scripts to perform chunked translation. This project restructures the workflow as an agent skill for Codex, Claude Code, and OpenClaw, using subagents to translate chunks in parallel, with manifest-driven integrity checks, resumable runs, and multi-format output unified into a single pipeline. As the project structure and implementation differ significantly from the original, this is an independent project rather than a fork.
Input (PDF/DOCX/EPUB)
  │
  ▼
Calibre ebook-convert → HTMLZ → HTML → Markdown
  (or Markdown input, e.g. from MinerU / Marker, skipping Calibre)
  │
  ▼
Split into chunks (chunk0001.md, chunk0002.md, ...)
  │  manifest.json tracks chunk hashes
  ▼
Parallel subagents (8 concurrent by default)
  │  each subagent: read 1 chunk → translate → write output_chunk*.md
  │  batched to respect API rate limits
  ▼
Validate (manifest hash check, 1:1 source↔output match)
  │
  ▼
Merge → Pandoc → HTML (with TOC) → Calibre → DOCX / EPUB / PDF
Each chunk gets its own independent subagent with a fresh context window. This prevents context accumulation and output truncation that happen when translating a full book in a single session.
run_state.json tracking glossary-sensitive re-translationebook-convert command must be available (download)pypandoc — required (pip install pypandoc)beautifulsoup4 — optional, for better TOC generation (pip install beautifulsoup4)npx skills add deusyu/translate-book -a codex -g
Or install it manually:
mkdir -p ~/.agents/skills
git clone https://github.com/deusyu/translate-book.git ~/.agents/skills/translate-book
Restart Codex if the newly installed skill does not appear.
npx skills add deusyu/translate-book -a claude-code -g
Or install it manually:
mkdir -p ~/.claude/skills
git clone https://github.com/deusyu/translate-book.git ~/.claude/skills/translate-book
openclaw skills install @deusyu/translate-book
In the Codex CLI or IDE extension, enter:
$translate-book Translate /path/to/book.pdf into Chinese.
Codex can also select the skill automatically when your request matches its description.
Ask the agent:
translate /path/to/book.pdf to Chinese
In Claude Code, you can also use the slash command:
/translate-book translate /path/to/book.pdf to Japanese
The skill handles the full pipeline automatically — convert, chunk, translate in parallel, validate, merge, and build all output formats.
All files are in {book_name}_temp/:
| File | Description |
|---|---|
output.md | Merged translated Markdown |
book.html | Web version with floating TOC |
book.docx | Word document |
book.epub | E-book |
book.pdf | Print-ready PDF |
tests/baselines/<book-id>/.tests/.artifacts/ and should not be committed.scripts/convert.py writes {book_name}_temp/ under the current working directory, run repository baseline tests from inside tests/.artifacts/ to keep generated files out of the repo root.mkdir -p tests/.artifacts
cd tests/.artifacts
python3 ../../scripts/convert.py ../baselines/standard-alice/standard-alice.epub --olang zh
# then run translation via the skill
python3 ../../scripts/merge_and_build.py --temp-dir standard-alice_temp --title "test"
Please open a detailed GitHub issue instead of starting with a pull request. This project is maintained as an AI-assisted skill pipeline, and changes need to be evaluated against the current orchestration rules, chunk/manifest contracts, baseline assets, and release flow in one maintainer-owned context.
Pull requests are not the preferred contribution path and may be closed in favor of an issue. If you already have a patch, include the idea, key diff, failing case, or verification notes in the issue; the maintainer may rework or split the implementation before merging.
A useful issue should include:
For bugs and feature requests, please open a GitHub issue as described above. For questions, ideas, or anything else, you can reach me here:
| Channel | Link |
|---|---|
| X (Twitter) | @0xdeusyu |
| Telegram | @DeusThink |
| Telegram Group (Chinese) | @talkdeusyu |
| Telegram Channel (Chinese) | @lovedesuyu |
| rainman.deus@gmail.com |
For commercial sponsorship, see Commercial sponsorship below.
The channel is my running log of thinking alongside AI; the group is its discussion space, and translate-book questions are welcome there too.
python3 scripts/convert.py /path/to/book.pdf --olang zh
Calibre converts the input to HTMLZ, which is extracted and converted to Markdown, then split into chunks (~6000 chars each). A manifest.json records the SHA-256 hash of each source chunk for later validation, and a source_fingerprint.json ties the temp dir to the exact source bytes it was built from — re-running against a replaced source file aborts instead of silently reusing stale chunks. Temp dirs created before fingerprinting are adopted with a warning on first re-run.
The HTML → Markdown step also cleans Calibre's markup structurally. EPUB footnotes — a marker link such as <a href="#n1"><sup>1</sup></a> in the text, paired with a note paragraph that opens with a link back to it — become Pandoc footnotes ([^1] in the text, [^1]: … right after the paragraph), numbered across the whole book so that per-chapter numbering cannot collide after merging. In-book links keep their text, span attributes such as {lang="…"}, empty page anchors, and heading ids are dropped, and typographic dashes and quotes stay as Unicode instead of --- or escaped ASCII quotes. Notes without a back-link (for example EPUB 3 <aside> footnotes) stay ordinary paragraphs.
By default the working directory is {book_name}_temp/ under the current directory. Use --temp-root /path/to/work to keep the same leaf directory name under a different parent.
Calibre reflows PDF text by coordinate heuristics. That works for plain prose, but academic and technical PDFs lose their structure: formulas break into fragments, tables flatten into one cell per line, and multi-column pages interleave. For those PDFs, extract them with a layout-aware parser first and give convert.py the Markdown it writes. .md / .markdown input skips Calibre entirely:
pip install -U "mineru>=4.0,<5"                # or: pip install marker-pdf
mineru-kit parse paper.pdf -o paper.md         # MinerU >= 4 (CPU-only basic tier: ~0.8 GB of models)
# marker_single paper.pdf --output_dir out/    # Marker: writes out/paper/paper.md
python3 scripts/convert.py paper.md --olang zh
The parsers keep formulas as $...$ / $$...$$ LaTeX and tables as tables. convert.py copies images referenced next to the Markdown file, and decodes the base64 images MinerU inlines, into {book_name}_temp/images/, so chunks never carry image payloads. Display-math blocks ($$ ... $$) are never split across chunks. YAML front matter (title, author, lang) fills config.txt and is not sent for translation; without it, a leading # heading becomes original_title. The temp dir is named after the Markdown file, so paper.md maps to paper_temp/. If that dir was built from paper.pdf, convert.py aborts on the source-fingerprint mismatch, so delete it first. Both parsers download ML models on first run. --strip-page-numbers and --detect-page-numbers only apply to Calibre input.
At build time Pandoc renders $...$ / $$...$$ as MathML, so formulas are typeset in book.html and book.pdf, and in book.epub on readers that support MathML. Calibre's DOCX output cannot typeset MathML: formulas appear there as flattened text followed by their TeX source.
Each chunk is translated by a fresh-context sub-agent, which means the same proper noun can drift across multiple translations on a 100-chunk book. To fix this, the skill builds a glossary before translation:
<temp_dir>/glossary.json (hand-editable schema below).python3 scripts/glossary.py count-frequencies <temp_dir> to populate per-term frequencies (ASCII terms use word-boundary regex so cat doesn't match category; CJK terms use substring; single-CJK-char terms are rejected; aliases count toward the term they belong to).python3 scripts/glossary.py print-terms-for-chunk <temp_dir> chunkNNNN.md and injects the resulting 3-column (原文 | 别名 | 译文) markdown table into that chunk's prompt as a hard constraint. Term selection = (terms whose source OR any alias appears in this chunk) ∪ (top-N most-frequent book-wide).Stars on GitHub
See 12 translate-book alternatives
Gives Claude Code access to the prompts.chat library, letting you search, retrieve and improve AI prompt templates, and find and install Agent Skills from its registry.
@gh-fA Claude Code skill for generating editable PPTX presentations and slides from a workflow, with reusable brand, style, layout, and deck workspaces, native charts, speaker notes, and template filling.
 @hugohe3
Gives AI agents control over Word, Excel and PowerPoint files, with skills for building .docx reports, academic papers, Excel dashboards and Morph-style animated slides.
 @iofficeai
A skill that builds animation-rich HTML presentations from scratch or converts PowerPoint files to web slides. Useful for anyone turning a deck into a web presentation.
 @zarazhangrui
Install it with the command on its page. It includes translate-book. Its skills do not fire on their own yet. Free and open source.
Is this plugin yours?
Claim it with GitHubSubmit a pluginPromote it