A bioinformatics-native AI agent skill library.
Built on OpenClaw (180k+ GitHub stars). Local-first. Privacy-focused. Reproducible.






📅 Follow the official ClawBio Events Calendar
ClawBio is building a general-purpose agentic utility layer for bioinformatics. Follow the calendar for hackathons, workshops, meetups and community events where contributors build, test and extend the platform.
Install in 30 seconds
pip install clawbio                 # Python 3.11+
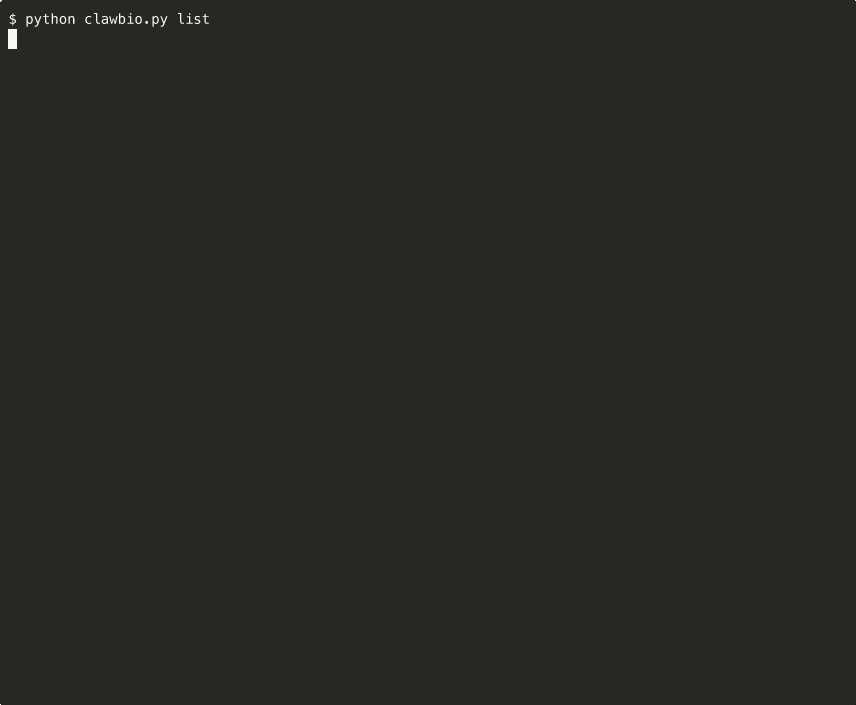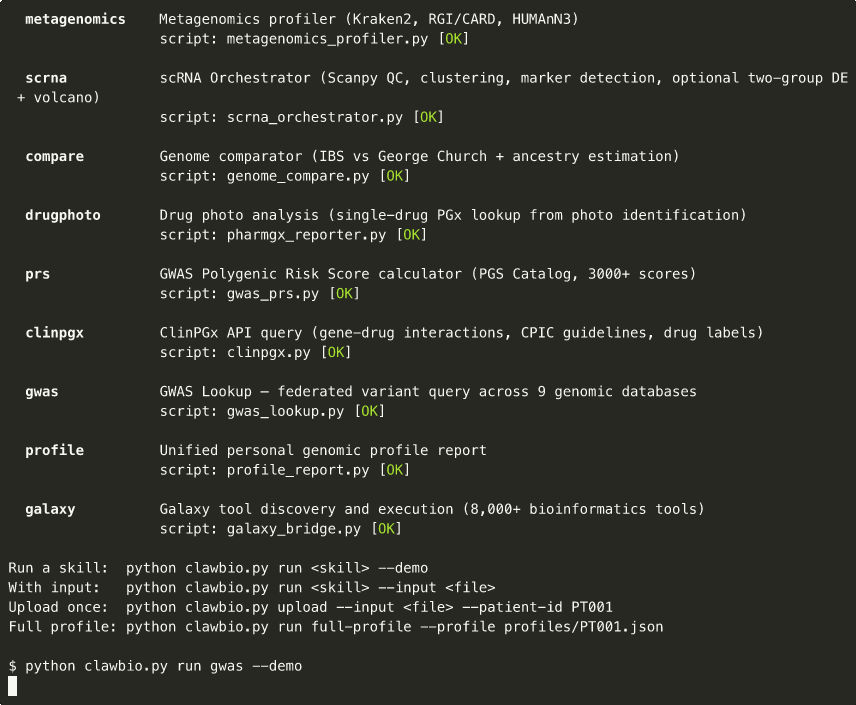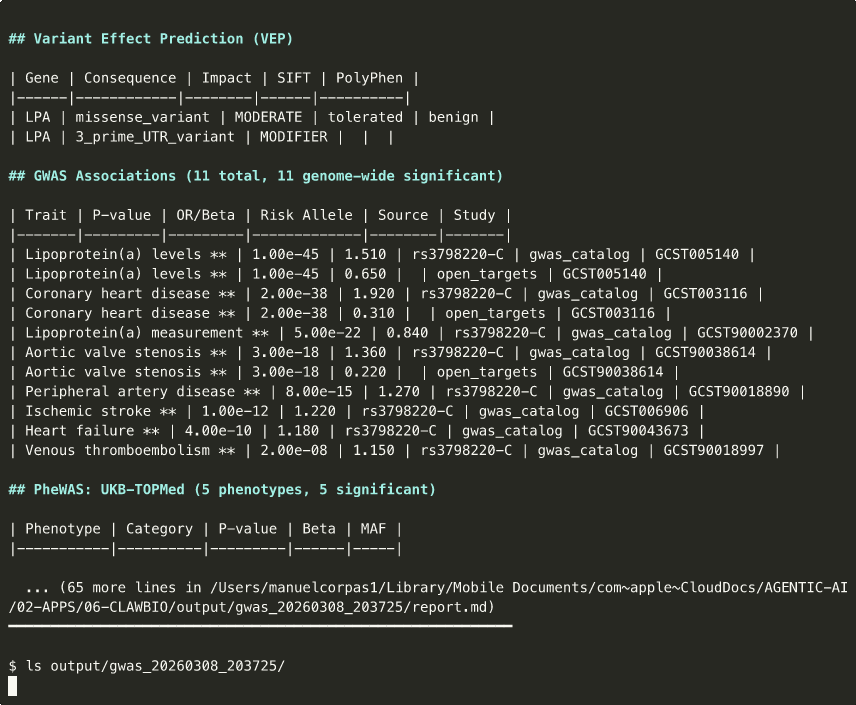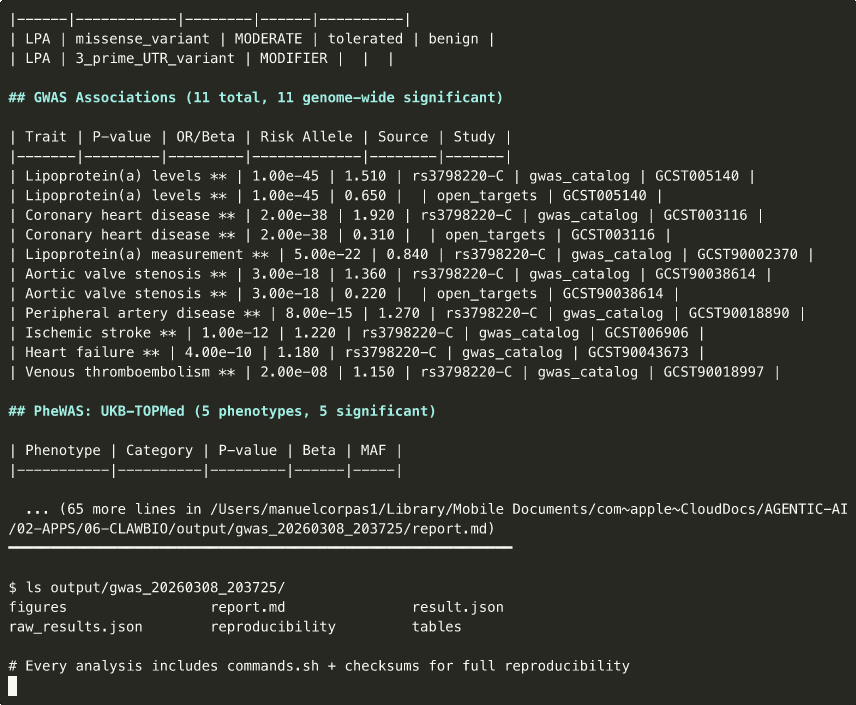
clawbio run pharmgx --demo
Prefer conda? conda install -c bioconda clawbio.
Or use as a Python library:
from clawbio import run_skill, list_skills
result = run_skill("pharmgx", demo=True)
Or install as a Claude Code plugin: /plugin marketplace add ClawBio/ClawBio
Using Cursor, VS Code, Codex, Zed or another editor that reads Agent Skills?
Every skill is a plain Agent Skills folder. Copy or symlink the folders you need from skills/ into
~/.agents/skills/, which all four read, or into your project's .agents/skills/. No server involved.
The MCP server (clawbio mcp), deprecated in 0.7.0, is removed in 0.8.0.
Why, and how to migrate: docs.clawbio.ai/reference/mcp.
Developing ClawBio or want all skills with full demo data? Work from a
source checkout instead (uv recommended):
git clone https://github.com/ClawBio/ClawBio.git
cd ClawBio
uv sync                            # installs from pyproject.toml + uv.lock
uv run python clawbio.py run pharmgx --demo
What ClawBio Does Today
Agent skills, most with runnable demo data (live count in the badge above and skill_count in skills/catalog.json) + 8,182 Galaxy tools + 5,040 tests + benchmark validation. Local-first by default. Reproducible. No guessing.
v0.5.0 released (4 Apr 2026): Validation and Benchmark Infrastructure. AD ground truth benchmark, mock API server for offline testing, swappable fine-mapping pipeline (SuSiE vs ABF), 74 benchmark tests, red/green TDD mandate. Release notes. DOI: 10.5281/zenodo.19420648.
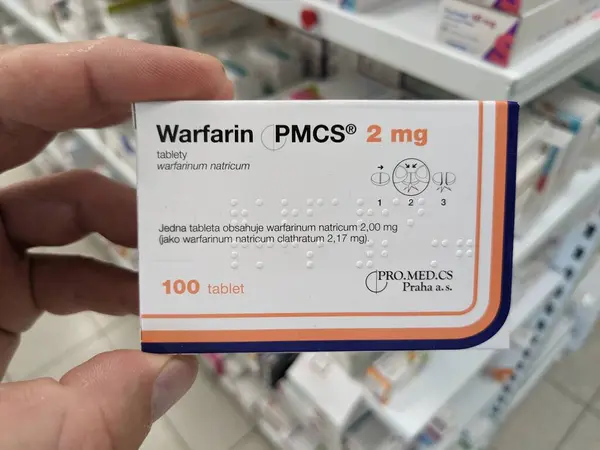
Snap a photo of a medication in Telegram. ClawBio identifies the drug from the packaging, queries your pharmacogenomic profile from your own genome, and returns a personalised dosage card — on your machine, in seconds:
Warfarin | CYP2C9 *1/*2 Intermediate · VKORC1 High Sensitivity
AVOID — DO NOT USE · Standard dose causes over-anticoagulation in this genotype.
Or take any genetic variant (identified by its rsID — a unique label like rs9923231) and search nine genomic databases at once to find every known disease association, tissue-specific effect, and population frequency. Or estimate your genetic predisposition to conditions like type 2 diabetes by combining thousands of small-effect variants into a single polygenic risk score. Or explore the UK Biobank — a half-million-person research dataset — by asking in plain English what fields measure blood pressure, grip strength, or depression, and get back the exact field IDs, descriptions, and linked publications you need.
Many ClawBio analyses write a reproducibility/ bundle with replay commands, environment metadata, and output checksums. The exact files can vary by skill, and some replays still require the original external inputs to be present. See docs/reproducibility.md.
Reference Genome
ClawBio's demo data is built on a real, fully open human genome: the Corpasome. The 23andMe SNP chip (~600K variants) has been available since launch. Now, the project also ships subsets from a 30x Illumina whole-genome sequence (GRCh37), covering ~4M SNPs, ~600K indels, and structural variants (DEL, DUP, INV, BND, INS, CNVs). All data comes from a single individual (Manuel Corpas), licensed CC0, and published on Zenodo (doi:10.5281/zenodo.19297389). This dataset is provided for research and educational purposes only.
See docs/reference-genome.md for use cases, subsets, and citation details.
Validation & Benchmarking
ClawBio v0.5.0 introduces the platform's first systematic validation infrastructure. Skills are scored against curated ground truth with objective metrics.
What's in the benchmark suite:
| Component | Description |
|---|
| AD Ground Truth | 34 Alzheimer's disease genes across 3 evidence tiers (Mendelian, GWAS-replicated, novel), 20 negative controls, 10 lead variants |
| Mock API Server | Deterministic endpoints for Ensembl, GWAS Catalog, ClinPGx. Offline CI without rate limits |
| Benchmark Scorer | Gene recovery rate, FDR, precision, recall, F1, tier-weighted composite score |
| Swappable Fine-Mapping | ABF vs SuSiE head-to-head on same data. Method registry pattern for adding FINEMAP, PolyFun |
| Nightly Sweep | Runs every skill in demo mode, scores outputs against ground truth |
# Run the fine-mapping benchmark
python tests/benchmark/finemapping_benchmark.py --output /tmp/fm_bench

# Score a gene list against AD ground truth
python tests/benchmark/benchmark_scorer.py --genes "APP,BIN1,CLU,TREM2,GAPDH"

# Start mock API server for offline testing
python tests/benchmark/mock_api_server.py &
74 benchmark tests at v0.5.0 baseline, all green. The public leaderboard now tracks 161 / 182 tests passing (88.5%) across 10 audited skills, up from 80 / 140 (57.1%) at the original audit. See benchmarks.html for the live leaderboard and CHANGELOG.md for full details.
The Problem
You read a paper. You want to reproduce Figure 3. So you:
- Go to GitHub. Clone the repo.
- Wrong Python version. Fix dependencies.
- Need the reference data — where is it?
- Download 2GB from Zenodo. Link is dead.
- Email the first author. Wait 3 weeks.
- Paths are hardcoded to
/home/jsmith/data/.
- Two days later: still broken. You give up.
Now imagine the same paper published a skill:
python skills/claw-ancestry-pca/ancestry_pca.py --demo --output fig3
# Example demo output regenerated. Verify bundled checksums where provided.
That's ClawBio. The goal is to make replayable bioinformatics workflows straightforward when a skill ships demo data and helper-backed reproducibility outputs.
What Is ClawBio?
Current agentic bioinformatics systems address either the reasoning layer (constraining LLM outputs with knowledge graphs or fine-tuning) or the connectivity layer (wrapping tools as MCP servers). Neither addresses the specification layer: the encoding of a domain expert's analytical decisions into a machine-readable contract that constrains agent behaviour. Without this layer, the agent must reconstruct expert knowledge from its training distribution, a stochastic, unversioned process.
A skill is a self-contained directory comprising a declarative specification (SKILL.md), validated Python code, demo data, and reproducibility support. In many skills, that includes a reproducibility/ bundle with commands.sh, environment.yml, and SHA-256 checksums, sometimes with extra lock metadata such as runtime-lock.json. The specification is a contract, not a prompt: it encodes the domain expert's analytical decisions so the LLM orchestrates but does not improvise.
Ad-hoc LLM code generation  = stochastic, unversioned, unverifiable
ClawBio skill                = specification-constrained, versioned, reproducible
- Specification-first: Domain expertise resides in
SKILL.md, not in model weights. Specifications are versioned, human-readable, peer-reviewable, and trivially updatable.
- Agent-agnostic: Skills execute identically whether invoked by Claude, ChatGPT, or a locally hosted model via Ollama. Reproducibility is decoupled from any specific AI vendor.
- Local-first by default: Your genome is analysed on your machine, and the
clawbio package itself makes no network calls. Some skills do reach public annotation APIs or hosted models, and a few send your variants or sequences to do so. Every one of them is named, with what it sends and to whom, in docs/data-handling.md, and a test fails if a networked skill is missing from that page.
- Reproducible: Many skills export replay metadata such as
commands.sh, environment.yml, and SHA-256 checksums so runs can be rechecked without the original agent session.
- MIT licensed: Open-source, free, community-driven.
Why Not Just Use an LLM?
Ask any LLM to "profile the pharmacogenes in my VCF file." It will produce plausible Python. But the code may use outdated CPIC guidelines, hallucinate star allele functional classifications, or confuse reduced-function and no-function alleles. CYP2D6*4 is a no-function allele; misclassifying it as reduced-function determines whether a patient receives a dose adjustment or is told to avoid a drug entirely. Approximately 7% of individuals of European ancestry are CYP2D6 poor metabolisers for whom codeine provides zero analgesic effect, and roughly 0.5% carry DPYD variants where standard fluorouracil dosing can be lethal.
An LLM should not be improvising these from training data. ClawBio encodes the correct bioinformatics decisions in versioned, peer-reviewable specifications so the agent executes them correctly every time.
Provenance and Reproducibility


 @paddlepaddle


