
Content
Plugin
llm-wiki-newsroom
A multi-agent AI knowledge base run by a five-role "newsroom" — open-source, local-first, no vendor lock-in.

Plugin Signal81/100Strong
maintained98
capable64
documented100
adopted47
Install
$ npx -y skills add alfadur7/llm-wiki-newsroom --agent claude-code
What's inside
Skill(6 skills)
/consulting-writingManagement-consulting writing craft — McKinsey SCR (Situation·Complication·Resolution), Minto Pyramid/MECE, BCG bold-bullet executive summary, so-what upfront, numeric precision, Forrester Landscape. Use when writing or reviewing an executive summary for decision-makers or a/encyclopedia-writingEncyclopedic neutral-reference writing craft — NPOV (attribute facts not opinions, due weight, neutral faction labels, verdict restraint), summary style and Coatrack avoidance, wikilink conventions (link density, first-mention, slug alias, abbreviation glossing). Use when/guideline-writingGuideline-authoring craft for instruction SoTs (.claude/ guides, CLAUDE.md, plan files) — operative rules vs recital, MUST/SHOULD/MAY force tiers, pruning, bloat control, blind review protocol, deliberation-narrative ban. Use when writing, editing, or reviewing an agent
Command(10 commands)
Agent(5 agents)
columnistAuthors L2-2 full hub expansion + L2-2 timeline narrative + all L2-3·L2-4 content (cluster overview·theme contradiction·synthesis·trail·root overview·root contradiction). Deep cross-source sequential reading + synthesis. Performs the GROUND·APPLY·ADAPT cycle stages together. NocopyeditorSole owner of deterministic quantitative checks across all Layers. Runs the 10 tools/lint.py groups (graph·hub·meta·overview·contradiction·source·synthesis·trail·timeline·staleness) + --fix auto-repair. PASS/FAIL exit code + lint-report.md + graph/_health-log.jsonl. NodeskSole owner of the pre-publish qualitative review for L2-2 full hub·timeline and L2-3·L2-4 content, plus the post-publish reground bundle re-read. Applies 6 review lenses (bias/trust·information density·repetition·argument quality·narrative flow·fine readability), prescription
Badges

README
LLM Wiki Newsroom
A multi-agent AI knowledge base run by a five-role "newsroom" — open-source, local-first, no vendor lock-in. Drop articles, documents, and PDFs into the raw/ folder, type a single command, and the newsroom — powered by an agent like Claude Code — reads them, extracts entities, concepts, and relationships, and organizes everything into a fully cross-referenced wiki, a structured and persistent alternative to RAG. Unlike most takes on the idea, the agent that writes a page is never the one that reviews it, and the authoring guidelines evolve themselves over time. Every new document you add also enriches the existing pages. This repo ships with a small example corpus — the debate over what "open source" means for AI — under wiki/, but the framework is domain-agnostic.
Most knowledge tools leave the finding to you. This project makes the AI read and understand your collected documents first, then organizes them into a wiki — with cross-references between pages, automatic flagging of conflicting claims, and per-topic synthesis built in from the start, so later retrieval is fast.
See the output before installing — the example corpus shipped in this repo is published as a browsable GitHub Wiki (no clone needed). It's a rendered static snapshot of the
wiki/folder; the interactive graph below runs locally.
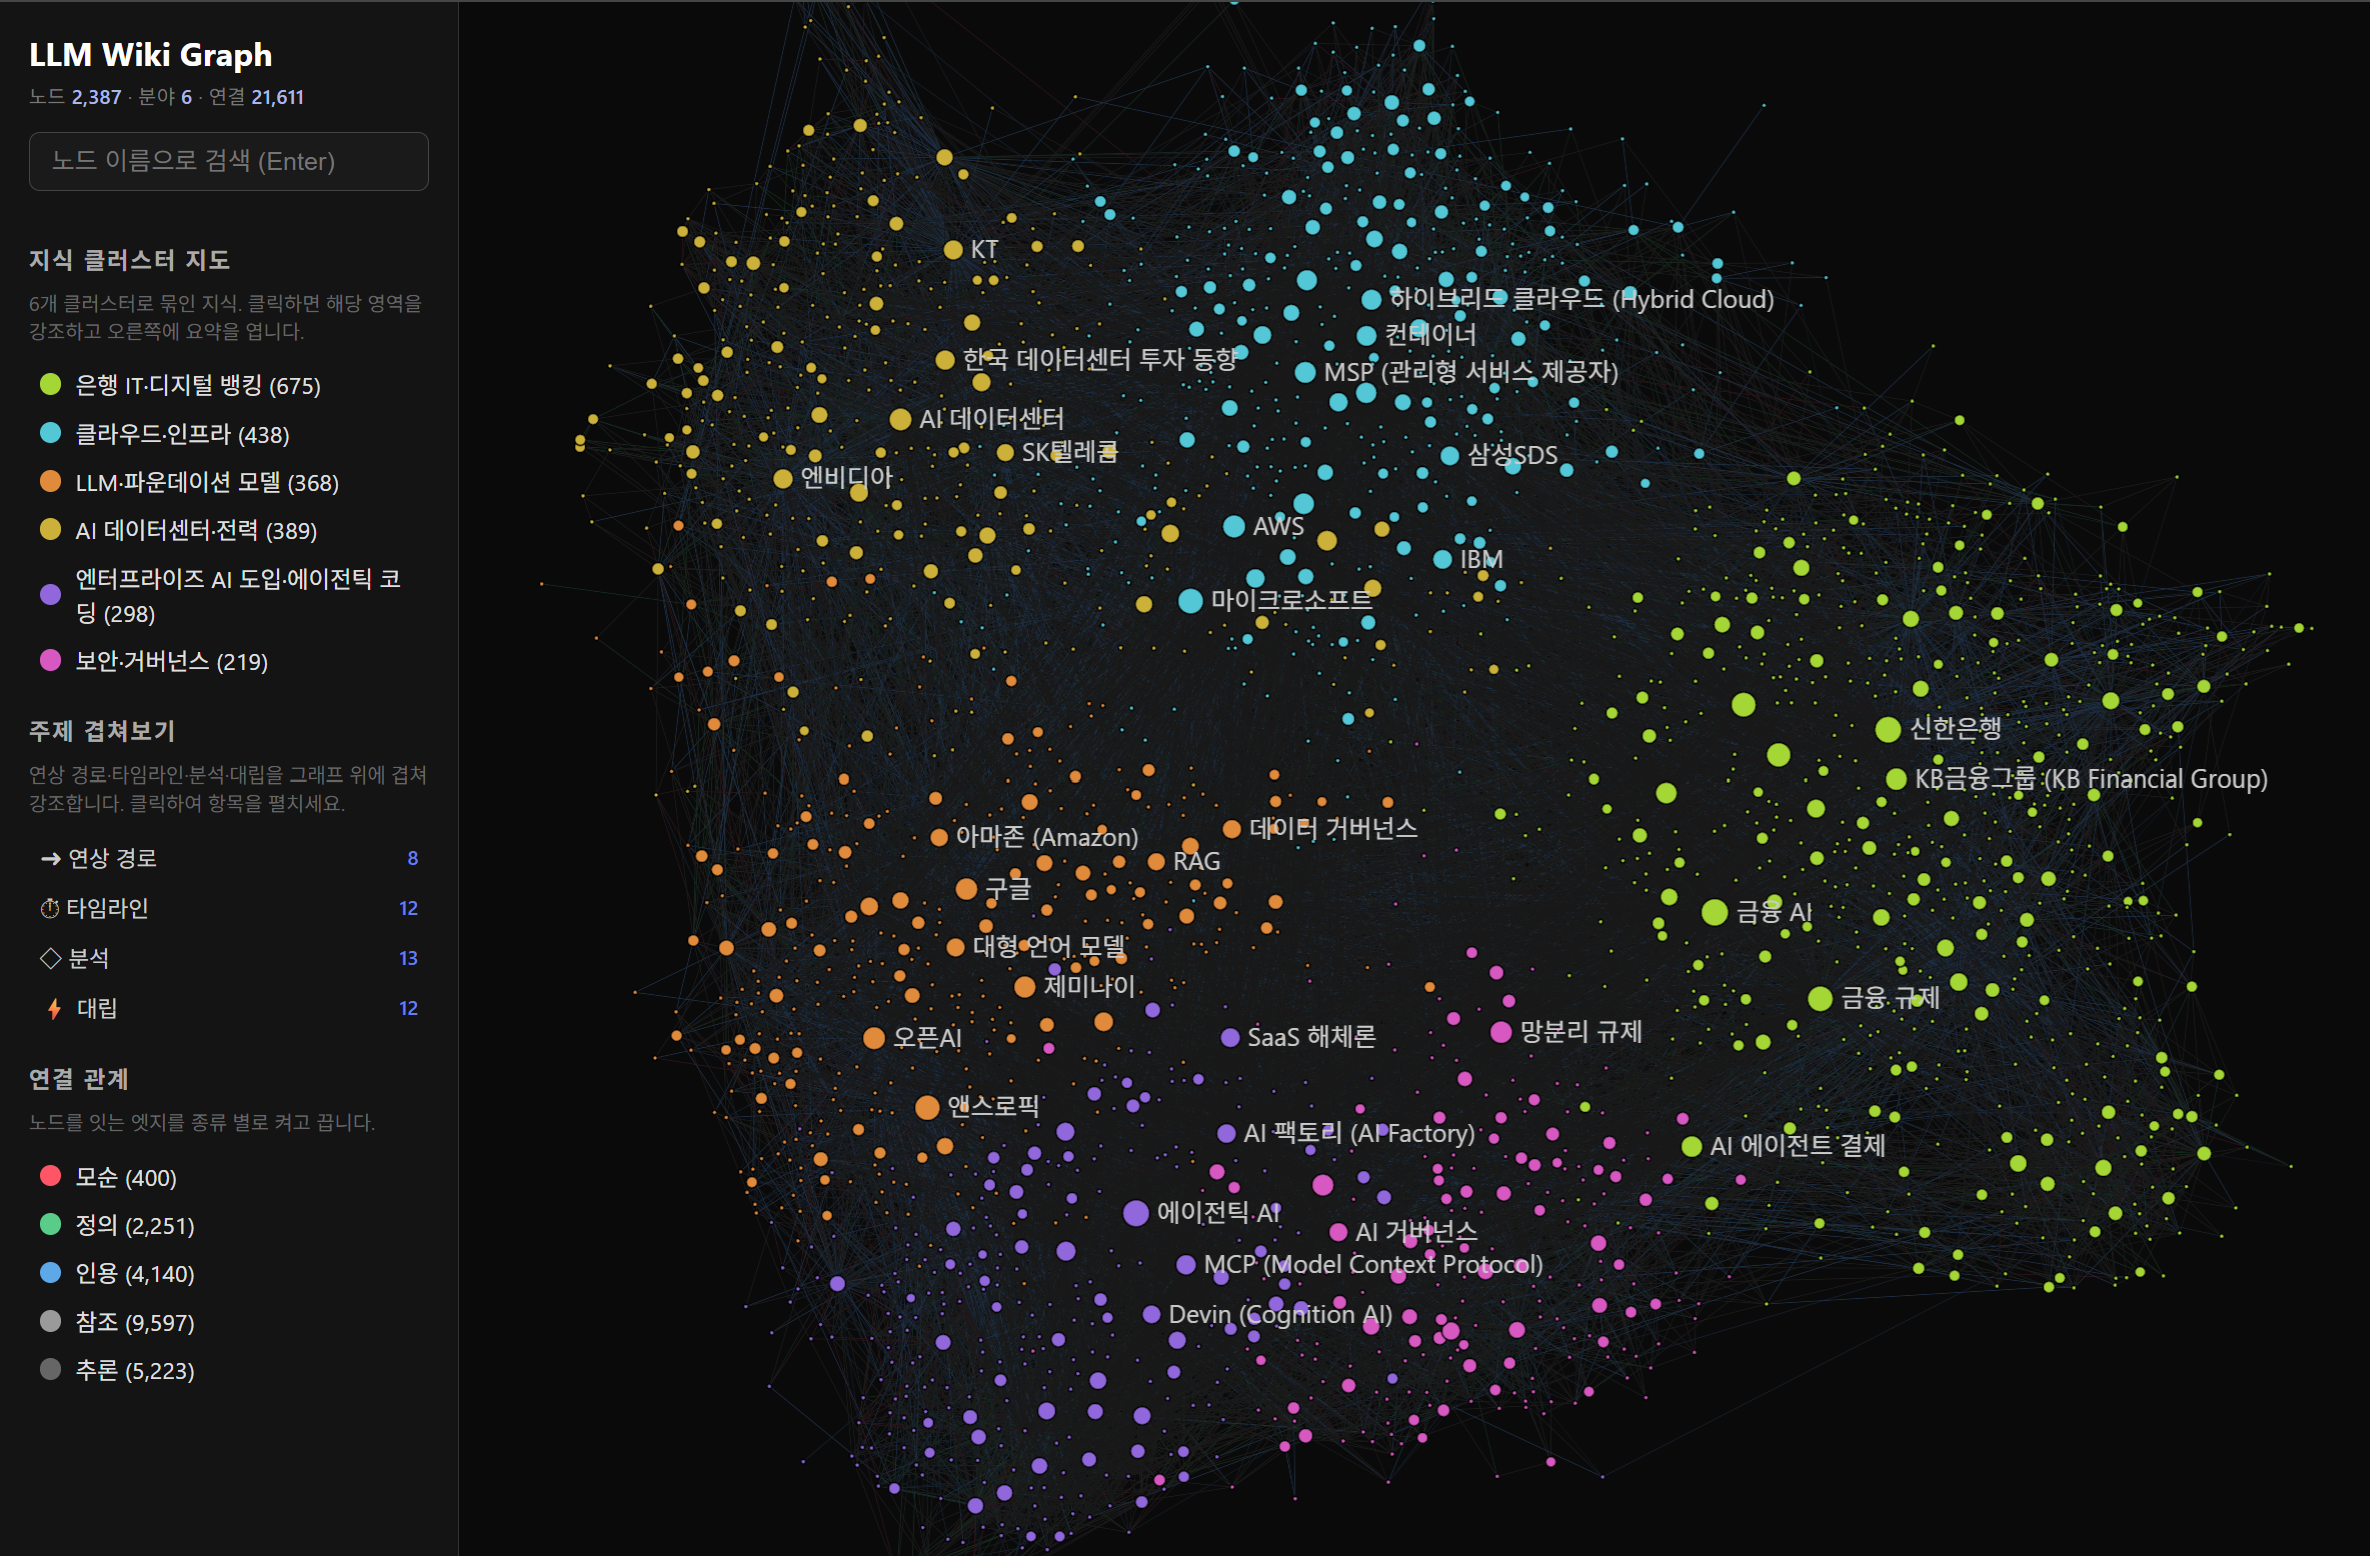
The interactive knowledge graph (graph/graph.html) — every page a node, every wikilink an edge, color-coded by auto-detected cluster, with a live physics layout and filter/search built in. Shown here on a larger private deployment (~2,300 nodes) to convey how it scales; this repo ships a deliberately small 15-node example corpus you can browse the exact same way. (Interface shown in the optional Korean WIKI_LANG=ko mode.)
The concept
This project is one question worked into a running system: how far can you trust knowledge an AI wrote? Two ideas organize everything below.
1. The product is an LLM Wiki — Andrej Karpathy's three-layer pattern. The original documents you collect (Layer 1, raw/), the cross-linked wiki the agent maintains (Layer 2, wiki/), and the operating rules the agent follows (Layer 3, CLAUDE.md + .claude/) are kept strictly separate, so humans and AI don't trespass into each other's territory. As the operator you do exactly two things — feed Layer 1 and tune Layer 3; only the agent writes Layer 2. And ingesting one document doesn't just add a page: it refreshes the ~10–15 existing pages that mention the same entities and concepts, which is what makes the wiki compound instead of just piling up.
2. The factory is a newsroom running four loops. The wiki is produced by five roles modeled on a newspaper staff — and the agent that writes a page is never the one that reviews it:
| Role | What it does |
|---|---|
| Reporter | gathers material and drafts source pages + entity/concept stubs |
| Columnist | writes the deep cross-source analyses |
| Copy Editor | rule-based Python checks — not an LLM at all |
| Desk | re-reads finished drafts with fresh eyes; the only independent qualitative judgment in the system |
| Editor-in-Chief | routes work and gates publication — orchestration, not evaluation |
Four loops turn that division of labor into trust. The first three nest inside one another; only the fourth sits outside, feeding published pages back in:
%%{init: {"flowchart": {"wrappingWidth": 700}}}%%
flowchart BT
    subgraph meta["Meta loop — mistakes become new rules"]
        subgraph outer["Outer loop — two gates before publication"]
            inner["Inner loop — the writer self-checks while drafting"]
        end
    end
    %% the   padding keeps this box as wide as the Meta loop box above
    reground["  Reground loop — pages that go stale or inconsistent come back as input  "]
    reground -.-> meta
    style meta fill:transparent,stroke:#58a6ff,stroke-width:2px
    style outer fill:transparent,stroke:#3fb950,stroke-width:2px
    style inner fill:transparent,stroke:#d29922,stroke-width:2px
    style reground fill:transparent,stroke:#bc8cff,stroke-width:2px,stroke-dasharray:4 4
| Loop | When it runs | What it does |
|---|---|---|
| Inner | while drafting | the writer self-checks against the same yardstick the review gates will use later, and hands off instead of grinding |
| Outer | at publication | two gates — deterministic lint (Copy Editor), then a six-lens qualitative review (Desk) — and both must pass |
| Meta | when mistakes recur | repeat failures become proposals to amend the authoring rules themselves — blind measurement where it applies, operator sign-off always |
| Reground | after publication | published pages that have gone stale or inconsistent come back around as factory input |
One piece of the machinery is deliberately not a loop. A loop is feedback — something exists, gets checked, gets corrected. Before any loop runs, a GROUND Ladder governs the input side: how much the writer reads before drafting, widening from the page's declared dependencies toward the whole corpus only on a named signal that the evidence so far is insufficient. The loops correct what came out; the ladder disciplines what goes in — every authoring cycle enters through it. (Details under Key Features.)
The first three loops mirror the "software factory" playbook for AI-assisted coding; the fourth exists because knowledge, unlike code, keeps decaying after you ship it. The full argument for this design is in the companion article: The Knowledge Factory.
Everything else in this README — the commands, the tools, the feature list — hangs off this map.
What makes this different
There are plenty of takes on Karpathy's LLM Wiki idea now. After reading the popular implementations, three things here are genuinely rare — and they are the bet:
- Authoring guidelines that evolve themselves (the meta loop) — something I haven't found in the other implementations. When the same review failure keeps recurring, the system drafts a fix to its own writing rules. The idea is borrowed from Self-Harness and Microsoft SkillOpt. Where the fix touches prose an LLM judge scores, it has to clear a blind A/B against a regression set first; tool code, fact corrections and structural moves are verified deterministically instead, and I can waive the A/B by directing a change myself, with the reason recorded. So it isn't only the wiki that improves over time, but the rules that build it. (Thirteen weeks of that ledger on a private instance: 107 amendments adopted, 72 rejected, 18 deferred. Of the 107, 16 cite a measurement, 40 were adopted on a recorded waiver, and 51 are changes the A/B doesn't cover or that record no measurement. Over the same window, 44 of the 70 defect classes that ever got a fix came back afterwards, and five of them produced 451 of the 823 recurrences (55%); the rule amended most often has been rewritten 19 times and still fires. The loop is still experimental; I'm measuring whether it earns its keep rather than claiming it's solved.)
- A full newsroom, not just "an agent" (the outer loop) — plenty of tools wrap one agent around your notes, and a few add a verifier. Here authoring and review sit in different hands, the review is held to an editorial rubric drawn from real craft (journalism, consulting, encyclopedic forms) so a different person or session reproduces the same bar, and a two-sided gate means the deterministic lint and the qualitative review must both pass.
- Memex-style associative discovery — saved reading trails and "unexpected connection" surfacing that the other implementations don't carry.
The rest — the knowledge graph, contradiction tracking, cascading updates, plain-markdown/Obsidian output — many LLM-wiki tools have in some form.
Installation
git clone https://github.com/alfadur7/llm-wiki-newsroom.git
cd llm-wiki-newsroom
pip install -r requirements.txt
No API keys, no accounts — the dependencies are the whole setup. If
igraph/leidenalghave no wheels for your platform (e.g. Termux/Android), delete those two lines fromrequirements.txt: everything else still installs, andtools/build.pyfalls back to a pure-Python partition.
Or click "Use this template" to create your own wiki repo from this scaffold. To start from a clean slate, delete the example pages under
wiki/(keep the folders andgraph/cluster_labels.json), then ingest your own sources with/wiki-ingest.
This project assumes an environment where the AI agent reads and edits files and invokes tools on its own. Support levels by agent:
| Agent | Config file | Support level |
|---|---|---|
| Claude Code (primary) | CLAUDE.md + .claude/commands/ | All 9 slash commands + advanced features (cascading updates, associative discovery, etc.) |
| Codex | AGENTS.md | Basic workflow only (drive it with natural language) |
| Gemini CLI | GEMINI.md | Basic workflow only (drive it with natural language) |
Claude Code-only features include cascading updates that refresh related existing pages whenever a new document is added, a backlink index across all pages, automatic contradiction tracking, and associative discovery that follows connected concepts. AGENTS.md and GEMINI.md carry only the basic workflow from the original SamurAIGPT project. The Python tools used to build the wiki run locally with no external API keys.
Slash Commands (Claude Code)
In Claude Code, typing a /-prefixed command like /wiki-ingest runs the matching workflow. The table below gives each command's role in one line; the Key Features section explains how they work. Argument notation follows <required>, [optional], and a | b | c (pick one); invoking a command with no required argument prints usage and stops.
Core workflow
| Command | Arguments | Description | Example |
|---|---|---|---|
/wiki-ingest | <file | folder | inbox> | Absorb one document into the wiki while also refreshing related existing pages. inbox processes the mobile share-sheet queue in a batch | /wiki-ingest raw/NewsScrap/article.md |
/wiki-query | <question> | Find pages related to the question via the graph and answer with supporting evidence | /wiki-query open source AI definition |
/wiki-lint | [--fix] | Health-check for broken links, missing pages, contradictions, etc. (--fix auto-repairs) | /wiki-lint --fix |
/wiki-graph | — | Compute the connections between pages and generate an interactive graph | /wiki-graph |
News & sharing
| Command | Arguments | Description | Example |
|---|---|---|---|
/wiki-news | [cluster|keyword] | Search the web for the latest news related to the wiki's topics and recommend only new articles | /wiki-news open-source-ai-definition |
/wiki-export | — | Merge the entire wiki into files for upload to a Claude.ai project | /wiki-export |
Associative discovery
File tree
FAQ
llm-wiki-newsroom is a Claude Code plugin with 6 hand-picked skills for content work, indexed on Flowy. Install it with the command on its page. It includes consulting-writing, encyclopedia-writing, guideline-writing. Its skills do not fire on their own yet. Request auto-invocation to have Flowy route them as you prompt. Free and open source.
- What is llm-wiki-newsroom?
- A multi-agent AI knowledge base run by a five-role "newsroom" — open-source, local-first, no vendor lock-in.
- How do I install llm-wiki-newsroom?
- Run these in Claude Code: npx -y skills add alfadur7/llm-wiki-newsroom --agent claude-code. Then prompt normally.
- Does llm-wiki-newsroom auto-invoke its skills?
- Not yet. It is indexed on Flowy as a plain plugin. Request auto-invocation on its page and Flowy will route its skills for you as you prompt.
- Is llm-wiki-newsroom free?
- Yes. Flowy is free and open source, with nothing gated. You can read every skill in full before you install.
Is this plugin yours?
Claim it with GitHubSubmit a pluginPromote it