NanoResearch


端到端自主 AI 科研引擎 — 从研究想法到完整论文,全程自动化



快速开始 ·
效果展示 ·
流水线 ·
Claude Code ·
飞书机器人
🔬 NanoResearch 真正运行计算实验——它不仅生成代码,还能将代码提交到 GPU 集群执行训练,收集真实实验结果,生成论文配图,最终输出一篇有实验数据支撑的完整 LaTeX 论文。论文中的每一个数据、表格、图表都来自实际运行的实验结果,而非 LLM 编造。
📖 目录
- 📊 论文实测展示
- ⚡ CLI 演示
- 📢 最新动态
- ✨ 核心特性
- 🆚 为何选择 NanoResearch
- 🎯 应用场景
- 🖼️ 效果展示
- CLI:标准输出与 TUI 对比
- 🔬 流水线
- 📦 快速开始
- 🧬 Evo 自进化流水线
- 🧩 Claude Code 模式
- ⚙️ 配置
- 💻 CLI 参考
- 🍪 示例与 Demo
- 📂 输出结构
- 💬 飞书机器人
- 🏗️ 项目结构
- ❓ 常见问题
- 🎯 路线图
- 📋 环境要求
- 🙏 致谢
- 🤝 贡献
- 📝 引用
- 📄 许可证
📊 论文实测展示
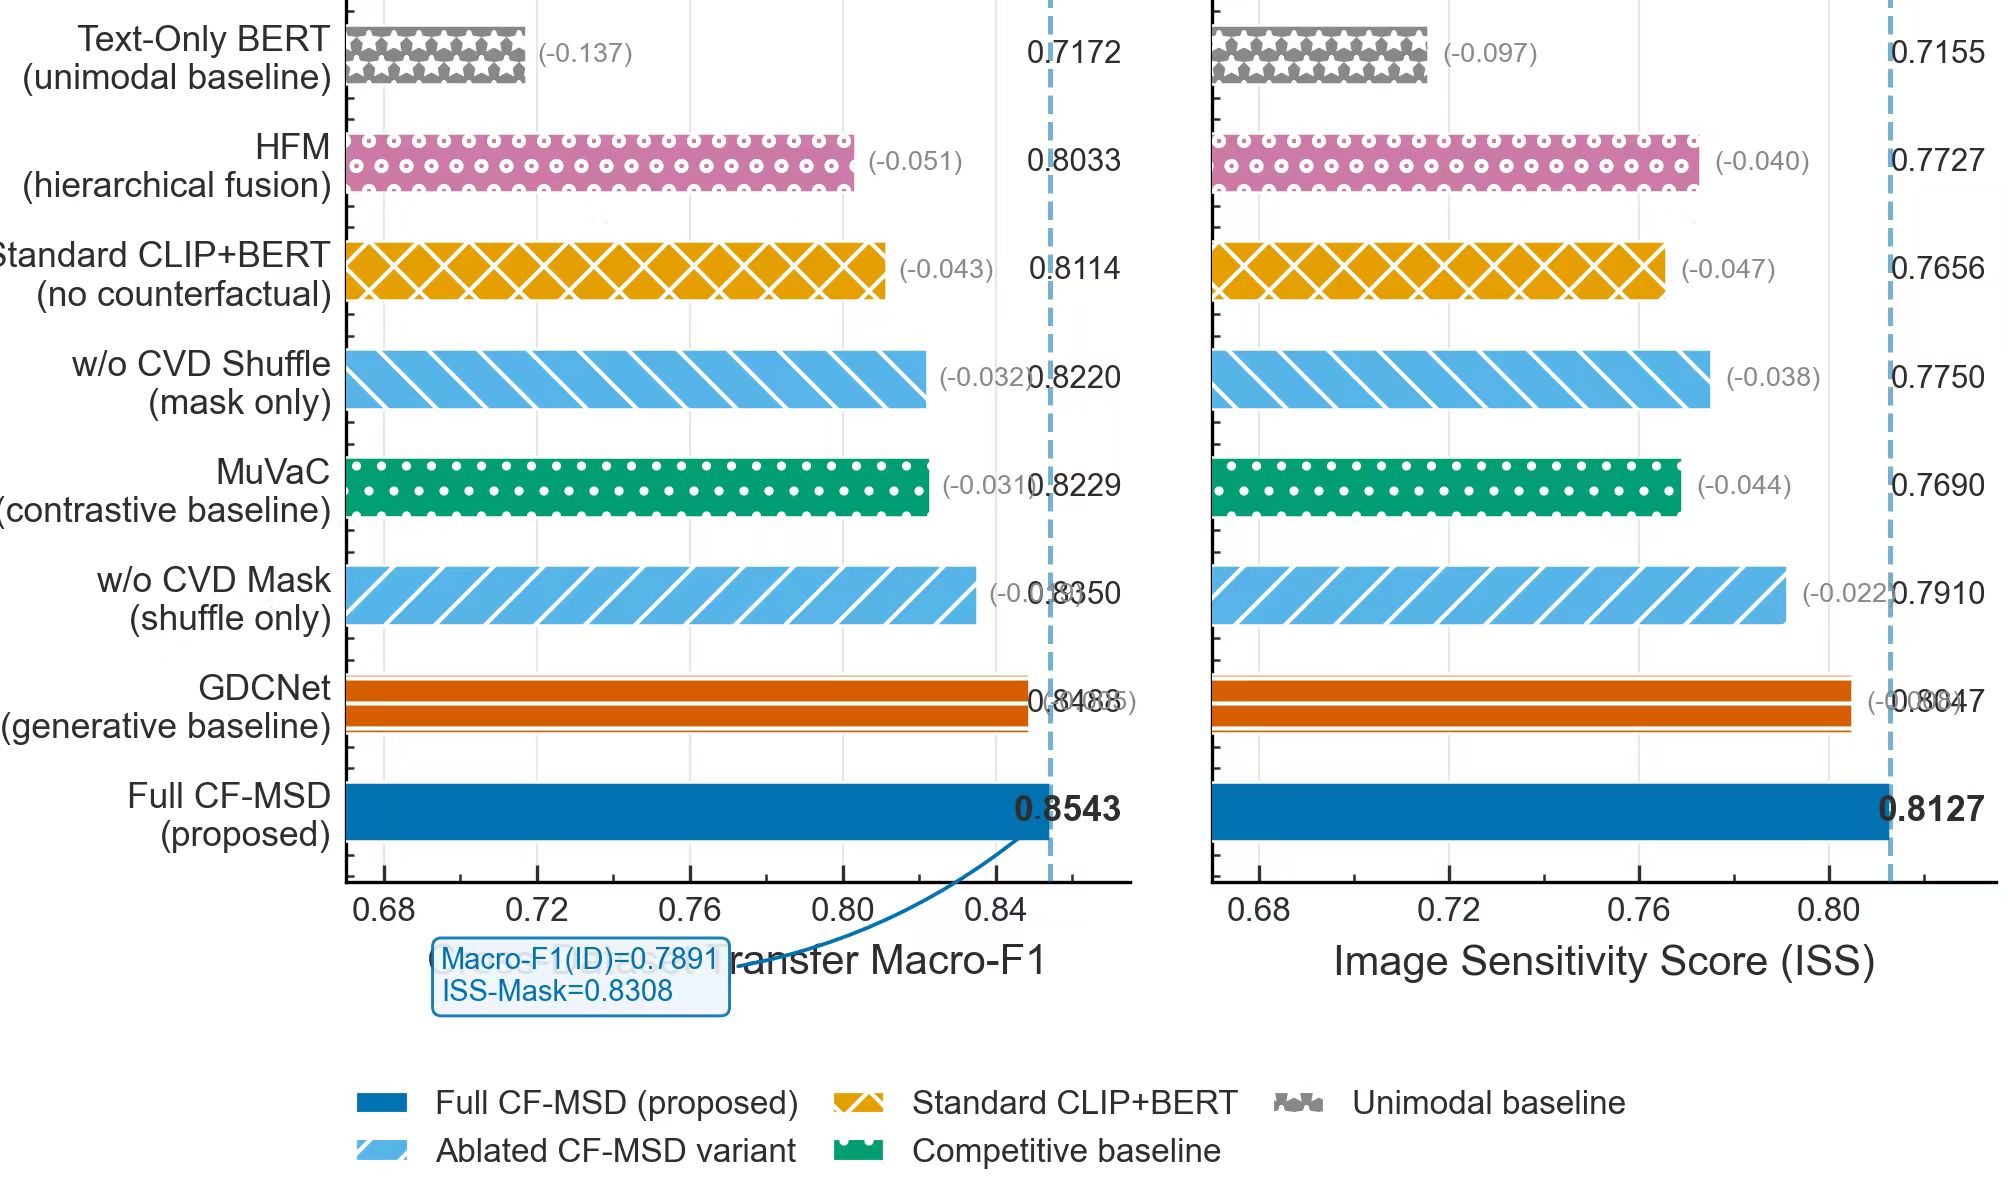
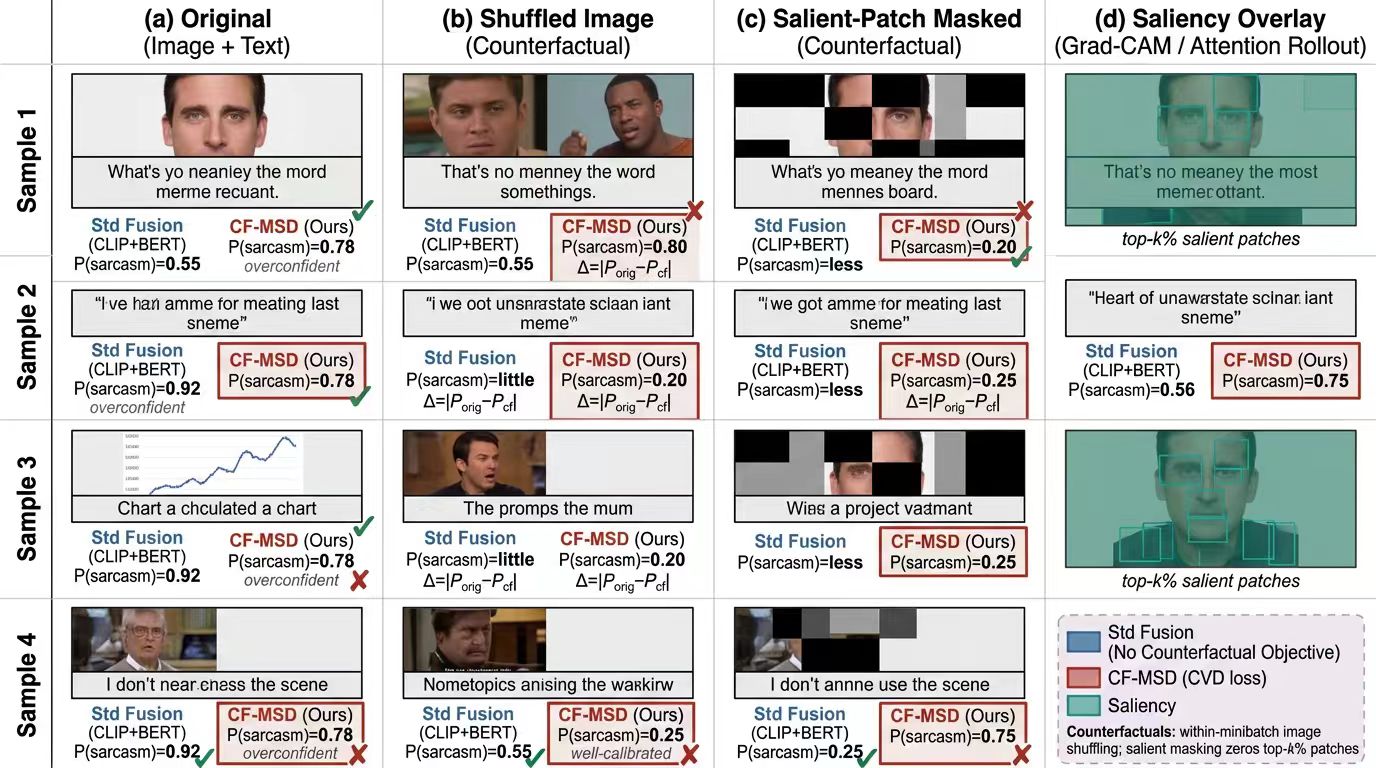
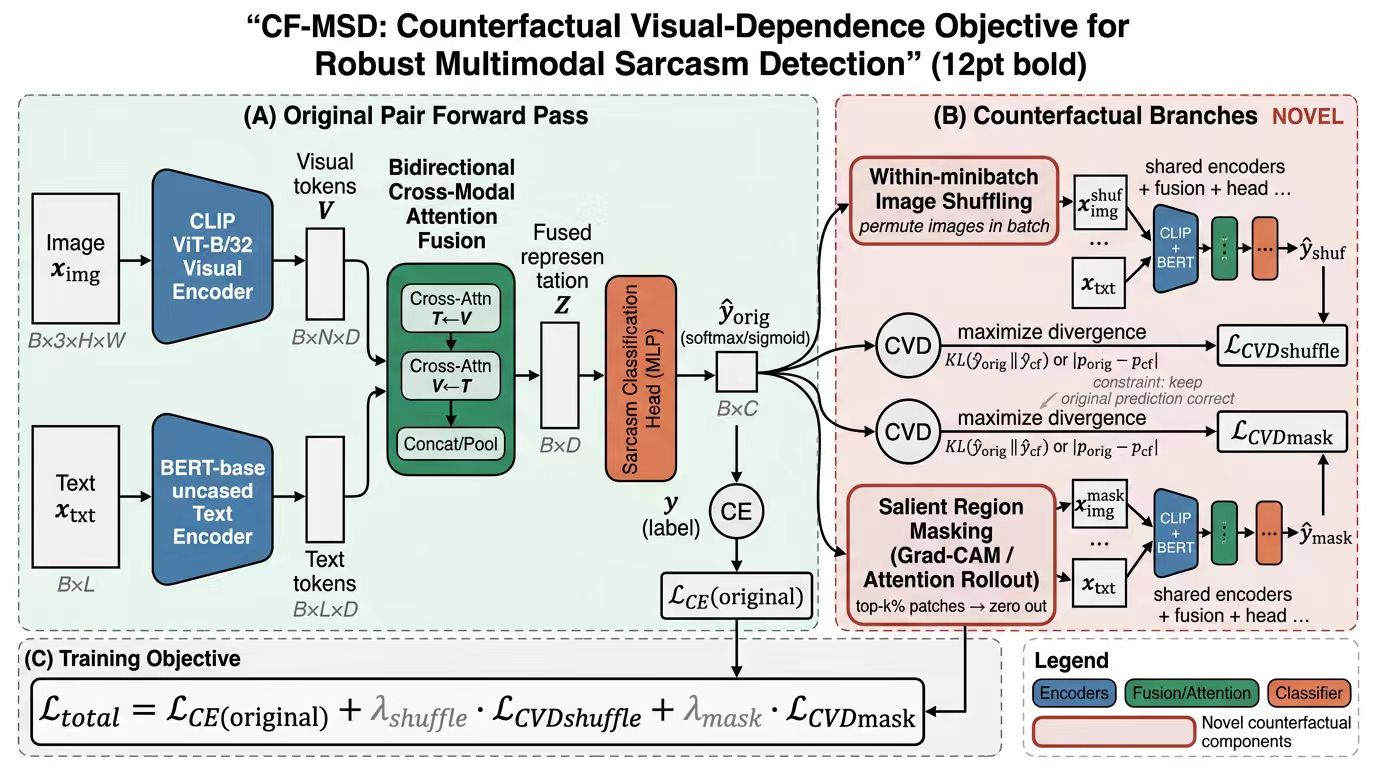
以下为 NanoResearch 自动生成论文中的真实配图,所有数据、曲线、表格均来自实际运行的实验结果,非 LLM 虚构。
实验结果展示
方法对比 / 主结果
消融与可视化
以上配图均为流水线自动生成,数据来源于真实训练日志与实验结果。
⚡ CLI 演示
NanoResearch 命令行(CLI) 提供 TUI 全屏界面 与 传统流式日志 两种呈现方式。下方为 CLI 端 TUI 主题与界面 演示视频(配色切换与布局优化)。其他入口(如 Claude Code、飞书机器人)见文档对应章节。
Why NanoResearch
| 特性 | 传统 AI 写作工具 | NanoResearch |
|---|
| 文献检索 | 部分支持 | ✅ OpenAlex + Semantic Scholar 自动检索 |
| 实验设计 | ❌ | ✅ 自动生成实验方案 |
| 代码生成 | 部分支持 | ✅ 完整可运行的实验代码 |
| GPU 实验执行 | ❌ | ✅ 本地 / SLURM 自动训练 |
| 结果分析 | ❌ | ✅ 解析真实训练日志 |
| 论文配图 | ❌ | ✅ 基于真实数据 |
| 论文撰写 | 大纲/草稿 | ✅ 完整 LaTeX 论文 |
| 断点续跑 | ❌ | ✅ 任意阶段可恢复 |
| 多模型协作 | 单一模型 | ✅ 按阶段路由 |
🎯 应用场景
- 科研原型验证 — 快速将研究想法变成完整的实验 + 论文工作空间
- 自主实验 — 系统自动生成代码、提交 GPU 训练、分析结果
- Benchmark 批量生成 — 对多个课题批量运行,生成可复现的实验结果
- 论文初稿辅助 — 基于真实实验数据产出 LaTeX 草稿,加速写作
- 科研流程审计 — 完整工作空间、中间产物和日志,可追溯每一步
🖼️ 效果展示

CLI:标准输出与 TUI 模式对比
CLI 支持 传统流式日志(非 TUI) 与 全屏 TUI 面板 两种呈现方式,可按习惯切换。
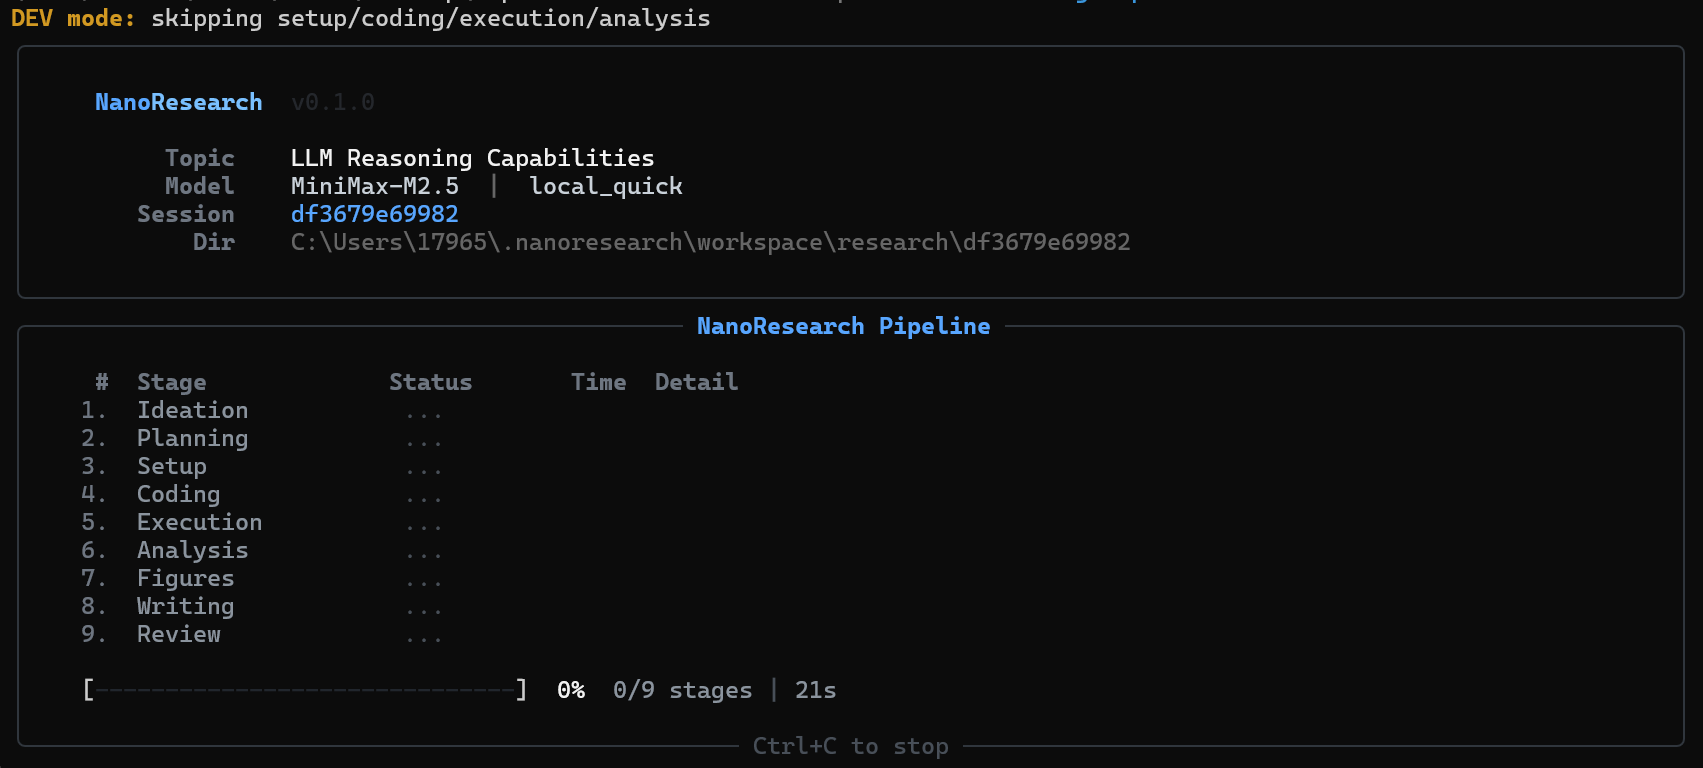
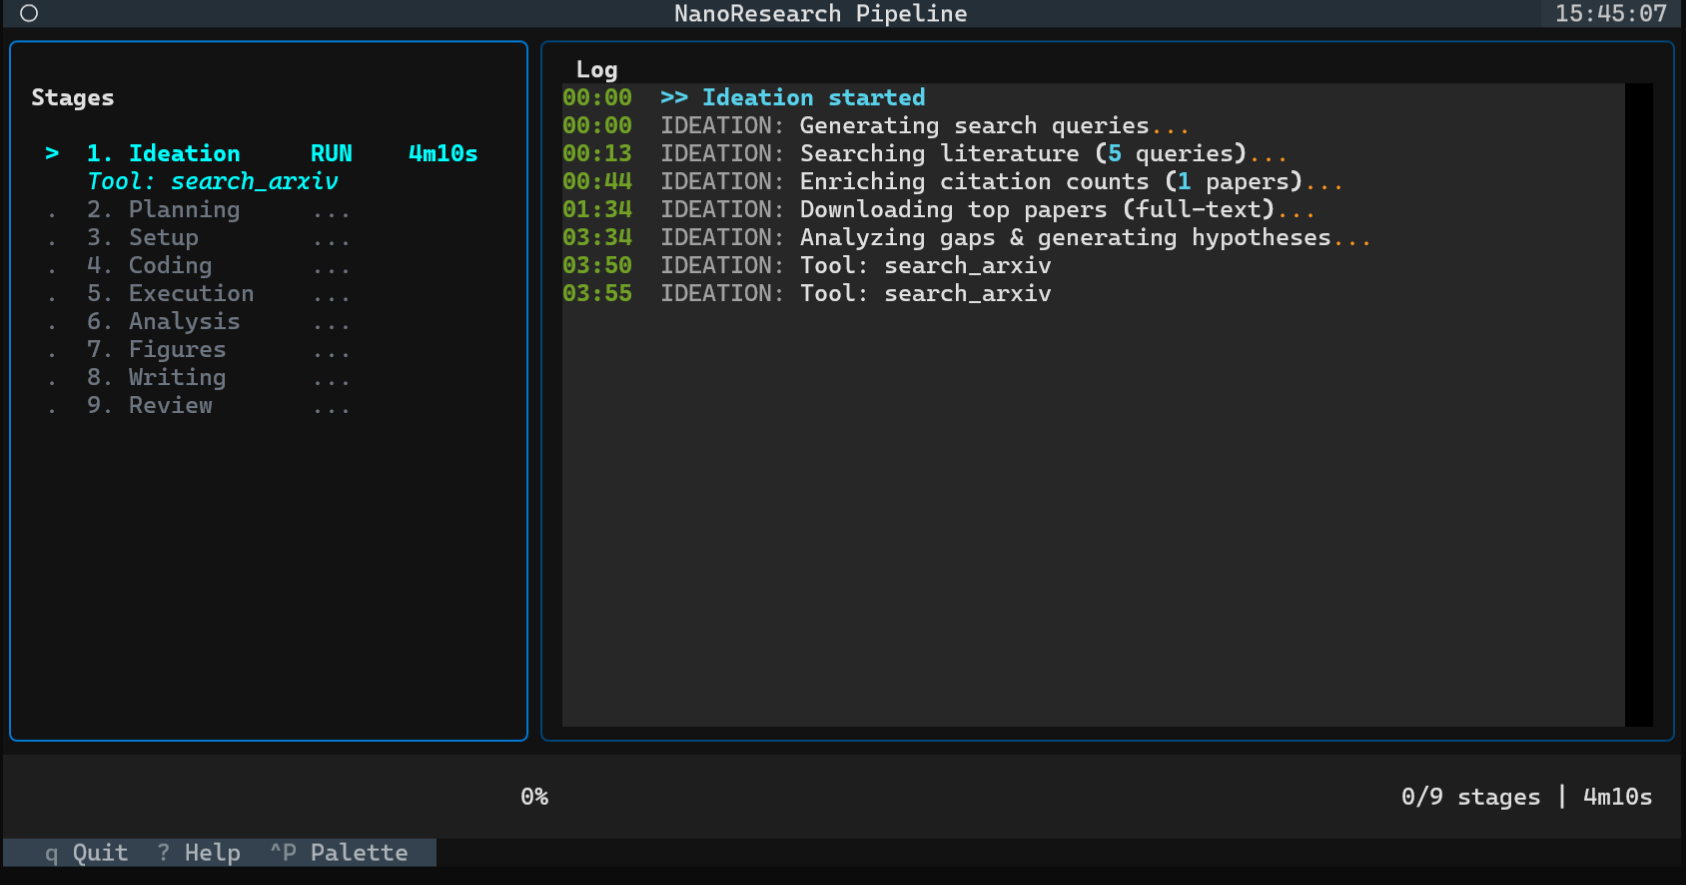
示例输出
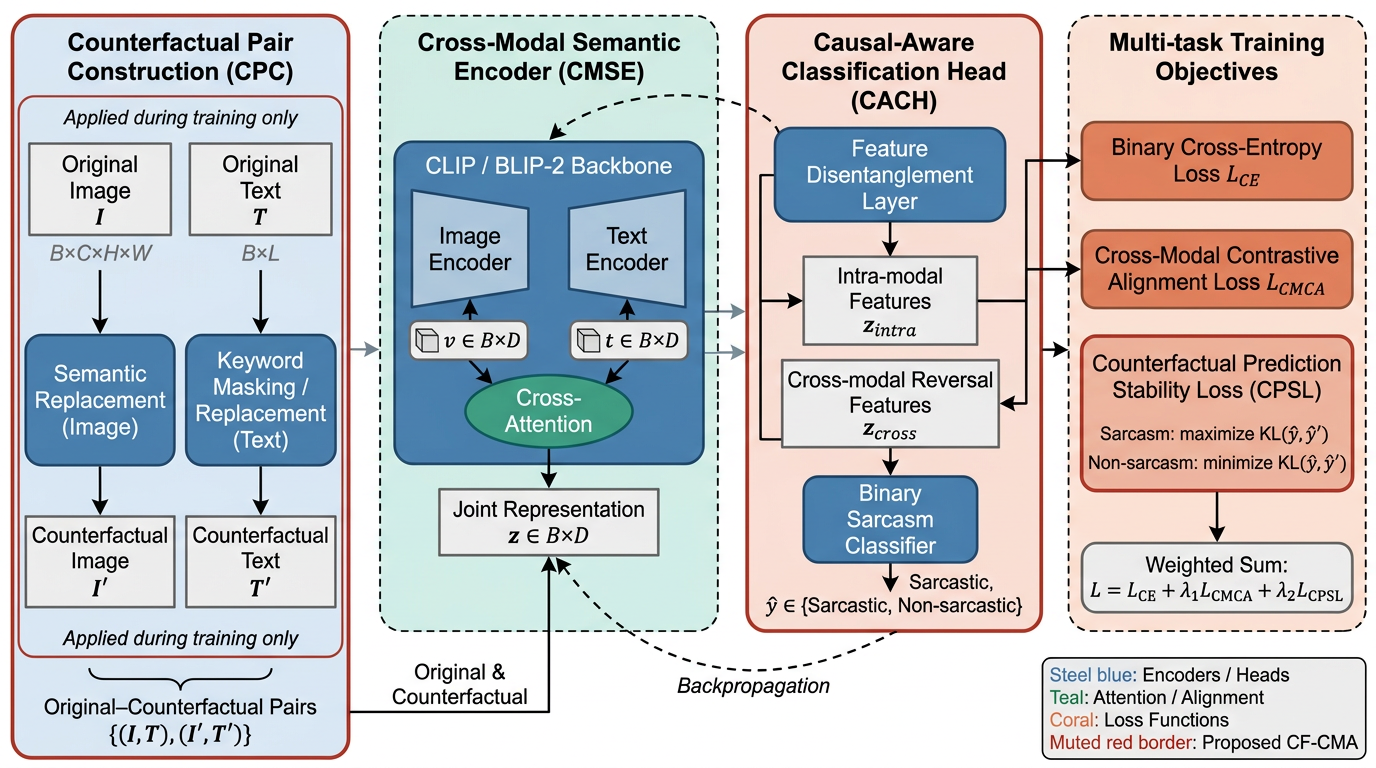
框架概览
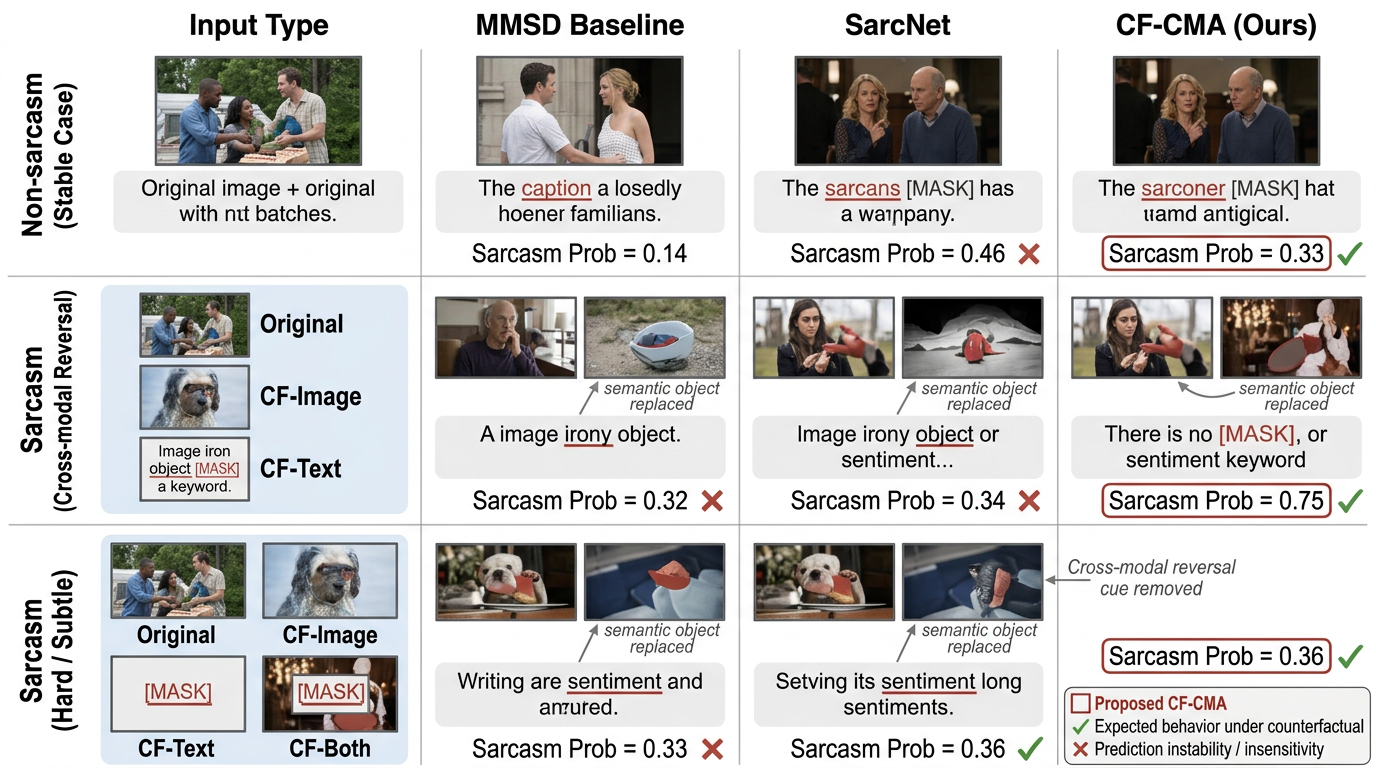
生成论文示例
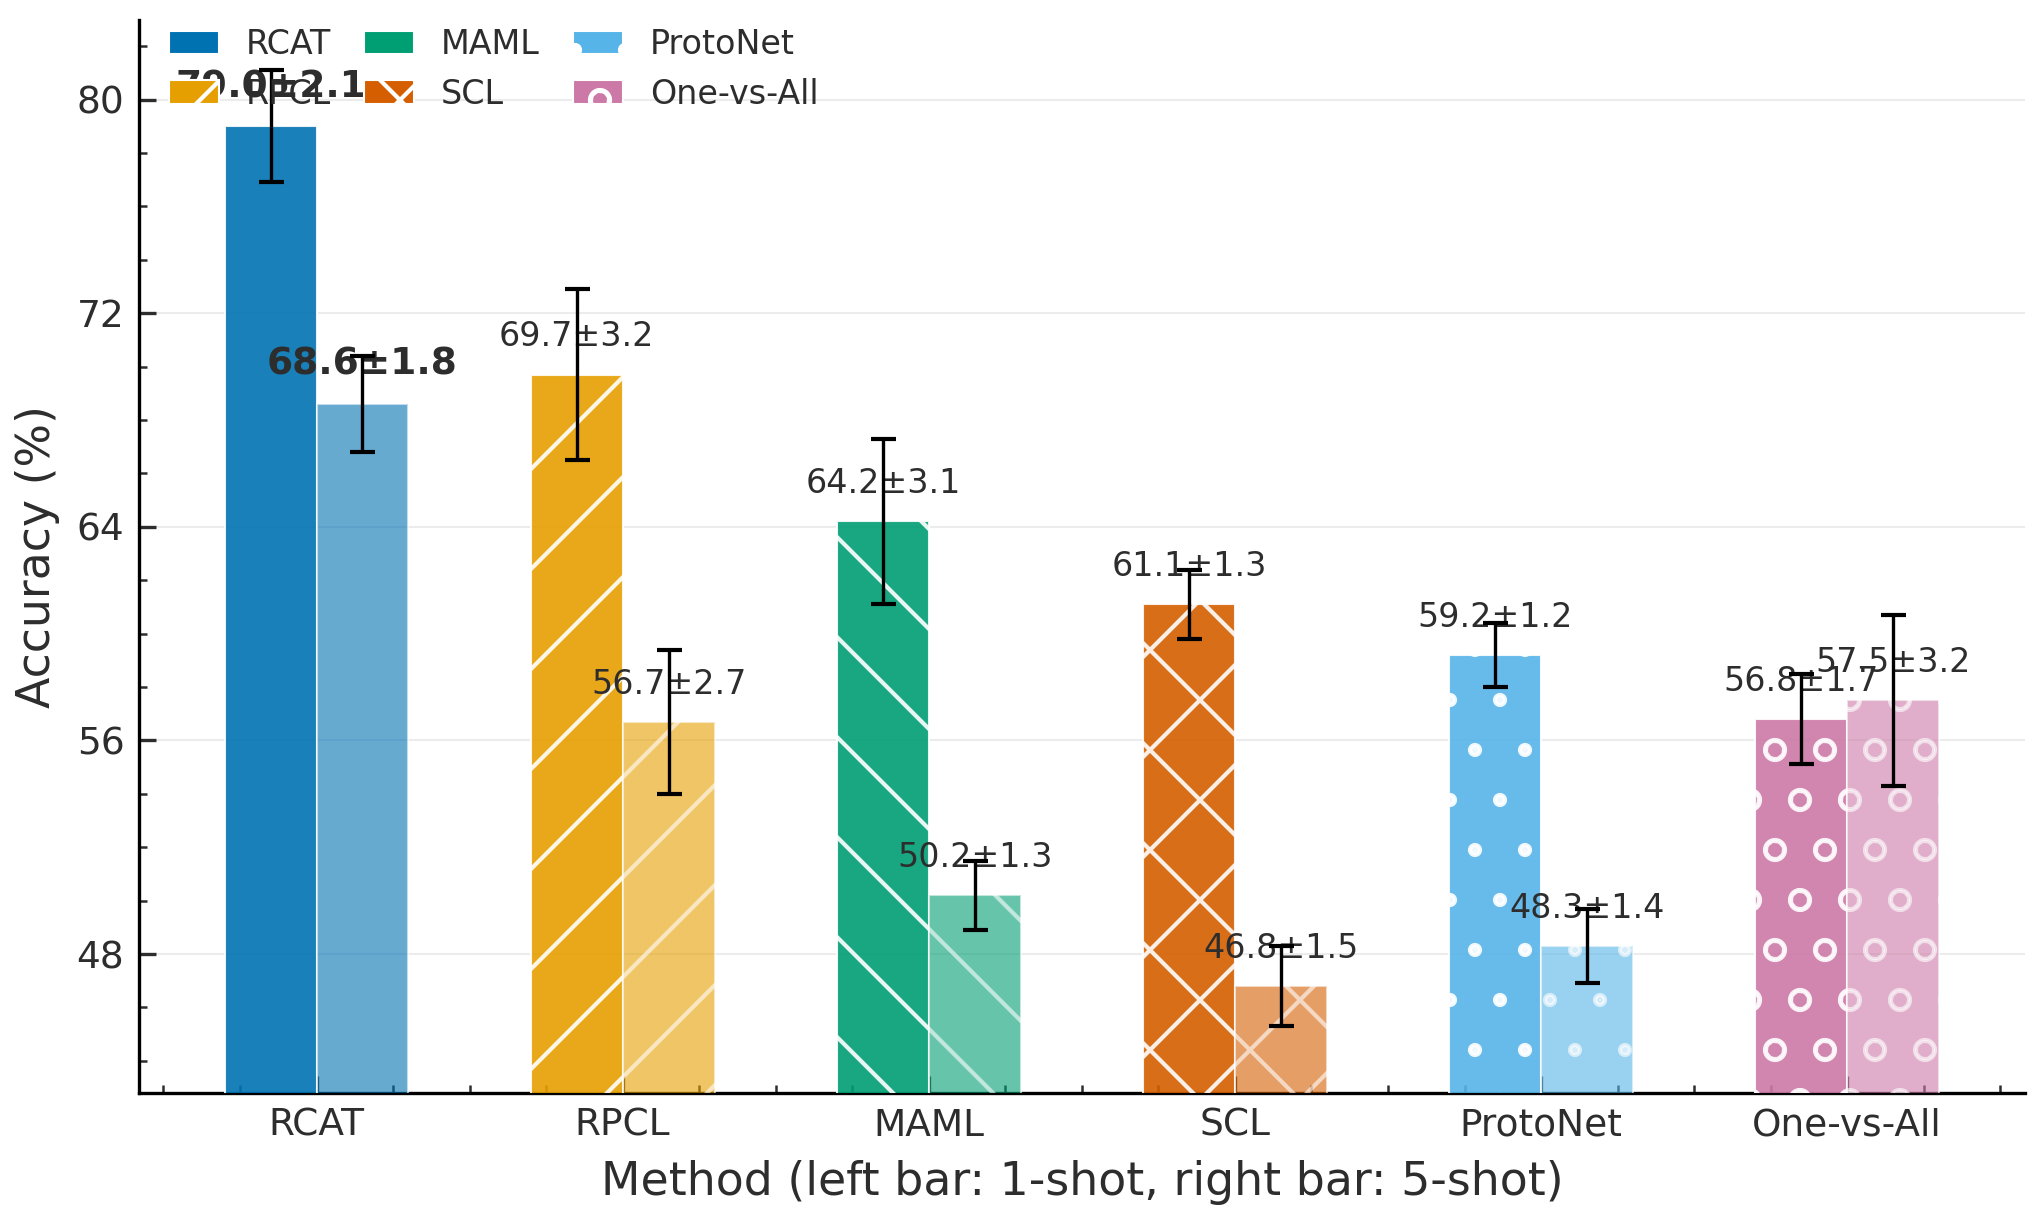
主结果(真实实验数据)
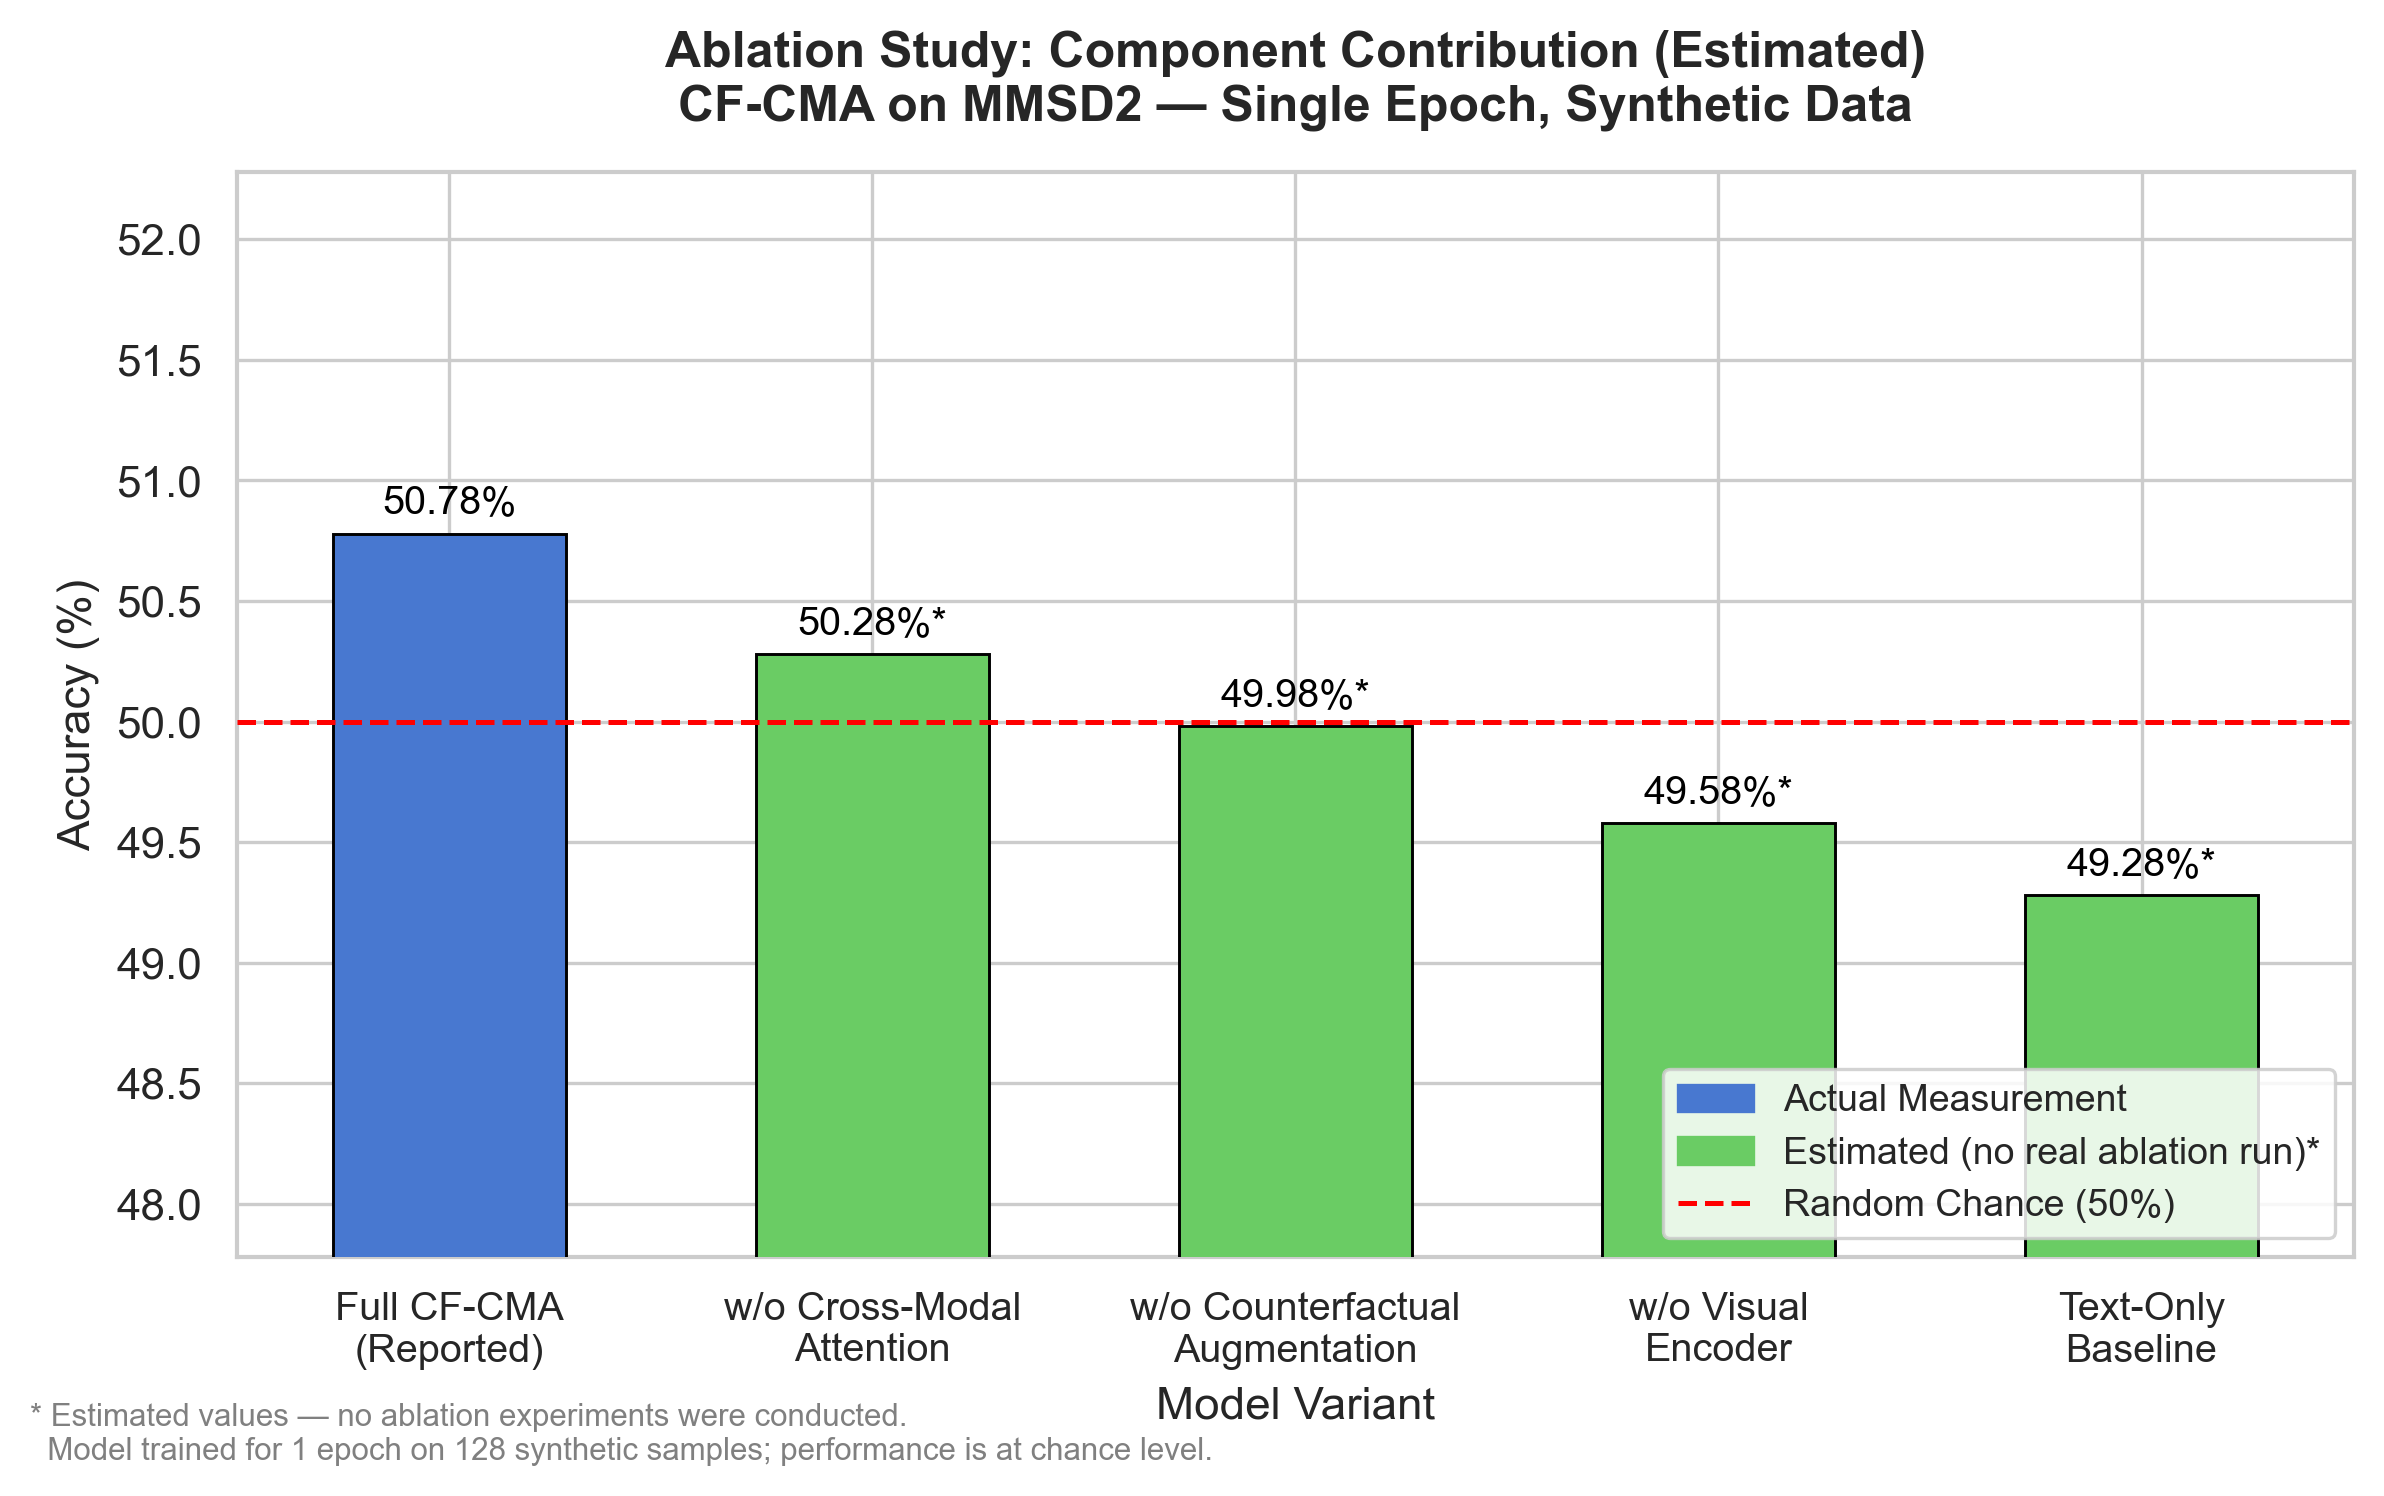
消融实验
🔬 流水线
Research Topic
     ↓
 IDEATION → PLANNING → SETUP → CODING → EXECUTION → ANALYSIS → FIGURE_GEN → WRITING → REVIEW
     ↓
 Exported: paper.pdf / paper.tex / references.bib / figures / code / data
📋 各阶段详细说明
| Stage | 功能 | 说明 |
|---|
IDEATION | 文献检索与创意生成 | 搜索学术文献、发现研究空白、提出假说、收集必引文献 |
PLANNING | 实验方案设计 | 将研究想法转化为详细的实验蓝图(数据集、基线、指标、消融) |
SETUP | 环境准备 | 准备代码仓库、依赖环境、模型和数据集 |
CODING | 代码生成 | 生成完整可运行的实验项目(含训练脚本、数据处理、模型定义) |
EXECUTION | 实验执行 | 在本地 GPU 或 SLURM 集群上运行训练,支持自动重试和调试 |
ANALYSIS | 结果分析 | 解析训练日志和指标,生成结构化实验证据 |
FIGURE_GEN | 图表生成 | 创建架构图、结果对比图、消融实验图 |
WRITING | 论文撰写 | 基于实验证据和引用撰写 LaTeX 论文 |
REVIEW | 审稿与修订 | 自动审阅各章节,检测问题并修订 |
🚀 EXECUTION 阶段核心能力
EXECUTION 阶段是 NanoResearch 的核心差异化能力:
- 自动提交 SLURM 作业 — 生成 sbatch 脚本,提交到集群,监控作业状态
- 本地 GPU 执行 — 自动检测可用 GPU,管理训练进程
- 自动调试与重试 — 训练失败时自动分析错误日志,修复代码并重新执行
- 实时日志监控 — 追踪训练进度和指标变化
- 混合执行模式 — 可根据任务复杂度在本地和集群之间自动切换
📦 快速开始
遵循以下步骤,约 5 分钟即可完成从安装到首次运行的完整流程。
步骤一:安装
git clone https://github.com/OpenRaiser/NanoResearch.git
cd NanoResearch
pip install -e ".[dev]"
步骤二:配置
Tip
创建 ~/.nanoresearch/config.json,替换 base_url 和 api_key 为你自己的 OpenAI 兼容 API 端点。
查看完整配置示例
{
  "research": {
    "base_url": "https://your-openai-compatible-endpoint/v1/",
    "api_key": "your-api-key",
    "template_format": "neurips2025",
    "execution_profile": "local_quick",
    "writing_mode": "hybrid",
    "max_retries": 2,
    "auto_create_env": true,
    "auto_download_resources": true,
    "ideation": { "model": "your-model", "temperature": 0.5, "max_tokens": 16384, "timeout": 600.0 },
    "planning": { "model": "your-model", "temperature": 0.2, "max_tokens": 16384, "timeout": 600.0 },
    "code_gen": { "model": "your-model", "temperature": 0.1, "max_tokens": 16384, "timeout": 600.0 },
    "writing": { "model": "your-model", "temperature": 0.4, "max_tokens": 16384, "timeout": 600.0 },
    "figure_prompt": { "model": "pro/gpt-5.5", "temperature": 0.5, "max_tokens": 4096, "timeout": 300.0 },
    "figure_code": { "model": "pro/gpt-5.5", "temperature": 0.1, "max_tokens": 16384, "timeout": 600.0 },
    "figure_gen": {
      "model": "gpt-image-2",
      "image_backend": "openai",
      "base_url": "https://your-image-endpoint/v1/",
      "api_key": "your-image-api-key",
      "temperature": null,
      "timeout": 600.0
    },
    "review": { "model": "your-model", "temperature": 0.3, "max_tokens": 16384, "timeout": 300.0 }
  }
}
环境变量覆盖:NANORESEARCH_BASE_URL / NANORESEARCH_API_KEY / NANORESEARCH_TIMEOUT
步骤三:验证与运行
# 验证配置
nanoresearch run --topic "Adaptive Sparse Attention Mechanisms" --dry-run

# 启动完整流水线
nanoresearch run --topic "Adaptive Sparse Attention Mechanisms" --format neurips2025 --verbose

# 从断点恢复(若某阶段失败)
nanoresearch resume --workspace ~/.nanoresearch/workspace/research/{session_id} --verbose

# 导出论文
nanoresearch export --workspace ~/.nanoresearch/workspace/research/{session_id} --output ./my_paper
步骤四:预期输出
完成流水线后,你将得到包含真实实验数据的论文配图与 LaTeX 源码。
🧬 Evo 自进化流水线
evo 是 NanoResearch 的自进化流水线,面向个性化科研自动化。它围绕技能演化、记忆演化和反馈驱动的 planner / router 适配运行,让系统在多轮研究中复用经验并逐步贴合用户偏好。
什么时候使用 evo
- 希望系统跨多轮研究积累可复用技能和项目记忆。
- 希望根据个人偏好、算力约束、目标 venue 和反馈逐步调整研究计划。
- 希望规划阶段明确生成 proposed method、baseline、ablation、optimization/history 和 complexity 相关实验,并让论文只基于真实 artifact 写作。
从用户初始化到论文产出
# 1. 初始化或更新用户画像、偏好和运行配置
nanoresearch init

# 2. 启动自进化完整流水线
nanoresearch run --pipeline evo --topic "your research topic" --format neurips2025 --verbose

# 3. 中途失败或断开后恢复
nanoresearch resume --workspace ~/.nanoresearch/workspace/research/{session_id} --verbose

# 4. 查看阶段状态和产物
nanoresearch status --workspace ~/.nanoresearch/workspace/research/{session_id}
nanoresearch inspect --workspace ~/.nanoresearch/workspace/research/{session_id}

# 5. 导出最终论文包
nanoresearch export --workspace ~/.nanoresearch/workspace/research/{session_id} --output ./paper_export
Evo 模式会产出什么
evo 仍然运行 9 个阶段:IDEATION -> PLANNING -> SETUP -> CODING -> EXECUTION -> ANALYSIS -> FIGURE_GEN -> WRITING -> REVIEW。区别在于它会在这些阶段之间持续更新和复用用户画像、技能库、项目记忆和反馈路由。
关键机器可检查 artifact 通常位于:
~/.nanoresearch/workspace/research/{session_id}/experiment/configs/experiment_matrix.json
~/.nanoresearch/workspace/research/{session_id}/experiment/results/metrics.json
~/.nanoresearch/workspace/research/{session_id}/experiment/results/run_manifest.json
~/.nanoresearch/workspace/research/{session_id}/experiment/results/final_metrics.json
~/.nanoresearch/workspace/research/{session_id}/experiment/results/optimization_history.csv
~/.nanoresearch/workspace/research/{session_id}/experiment/results/pareto_front.json
写作阶段只读取真实执行结果、分析报告和图表 artifact。若某类实验或指标没有真实产物,系统会降低证据范围或写入 limitation / future work,不会补 synthetic 数值。文献检索可匿名使用 OpenAlex;如需更高速率,可自行配置 OPENALEX_API_KEY。
SDPO adapter 训练
Evo/RAM 运行产生的完整 (x, y, feedback) 三元组会保存在 ~/.nanoresearch/ram_data/。安装可选训练依赖后,可训练或续训 RAM LoRA adapter:
pip install -e ".[sdpo]"
nanoresearch ram-train \
  --model Qwen/Qwen2.5-7B-Instruct \
  --data-root ~/.nanoresearch/ram_data \
  --output ~/.nanoresearch/adapters/ram-sdpo
训练完成后,将配置中的 ram_checkpoint_path 指向输出目录即可在后续 Evo 运行中加载该 adapter。
🤖 推荐模型
| Stage | 任务 | 推荐模型 | 经济型 |
|---|
ideation | 文献检索 + 假说生成 | DeepSeek-V3.2 | DeepSeek-V3.2 |
planning | 实验设计 | Claude Sonnet 4.6 | DeepSeek-V3.2 |
code_gen | 代码生成 | pro/gpt-5.5 | DeepSeek-V3.2 |
writing | 论文撰写 | pro/gpt-5.5 / Claude Sonnet 4.6 | DeepSeek-V3.2 |


 @openraiser



