
Testing
Plugin
skillci
Regression testing for Claude Skills. When a model update silently changes how your skill behaves, SkillCI catches it in CI — and turns the failure into a permanent test case, automatically.

Plugin Signal58/100Fair
maintained87
capable14
documented100
adopted20
Install on Claude Code
> /plugin marketplace add kabirnarang39/skillci> /plugin install skillci@skillci
Stats
8
Stars
2
Forks
Maintained
Maintenance
Go
Language
Apache-2.0
License
1mo ago
Last commit
2mo ago
Created
Repo: kabirnarang39/skillci
What's inside
README
SkillCI
Regression testing for Claude Skills. When a model update silently changes how your skill behaves, SkillCI catches it in CI — and turns the failure into a permanent test case, automatically.


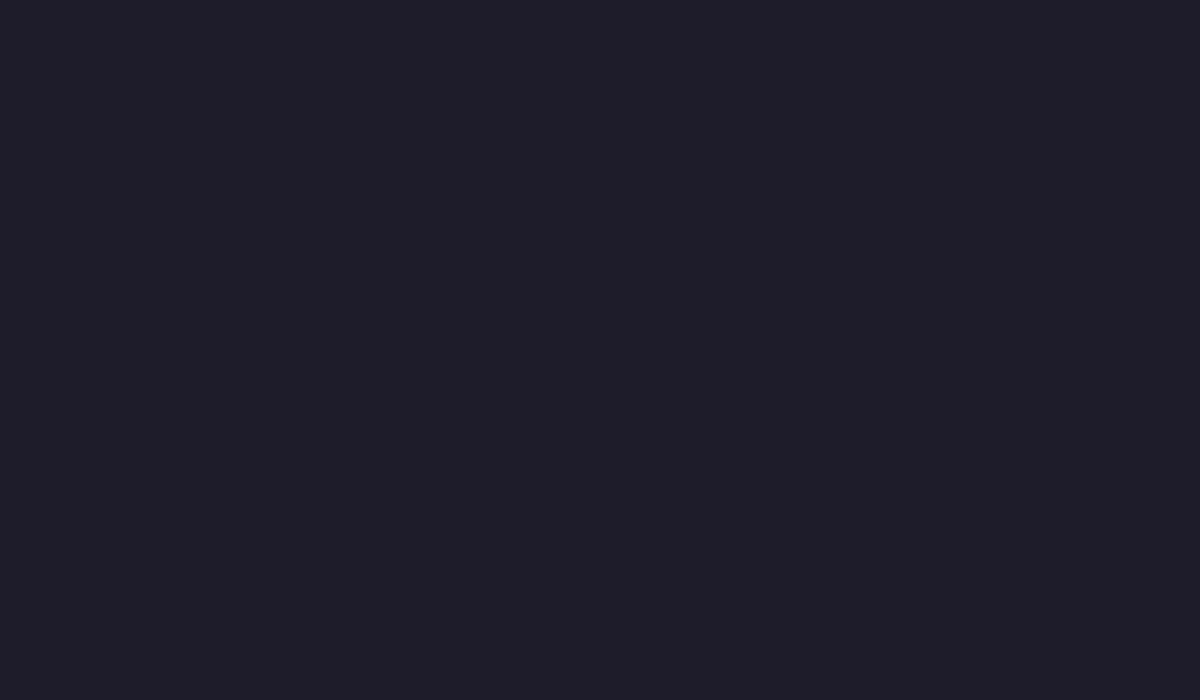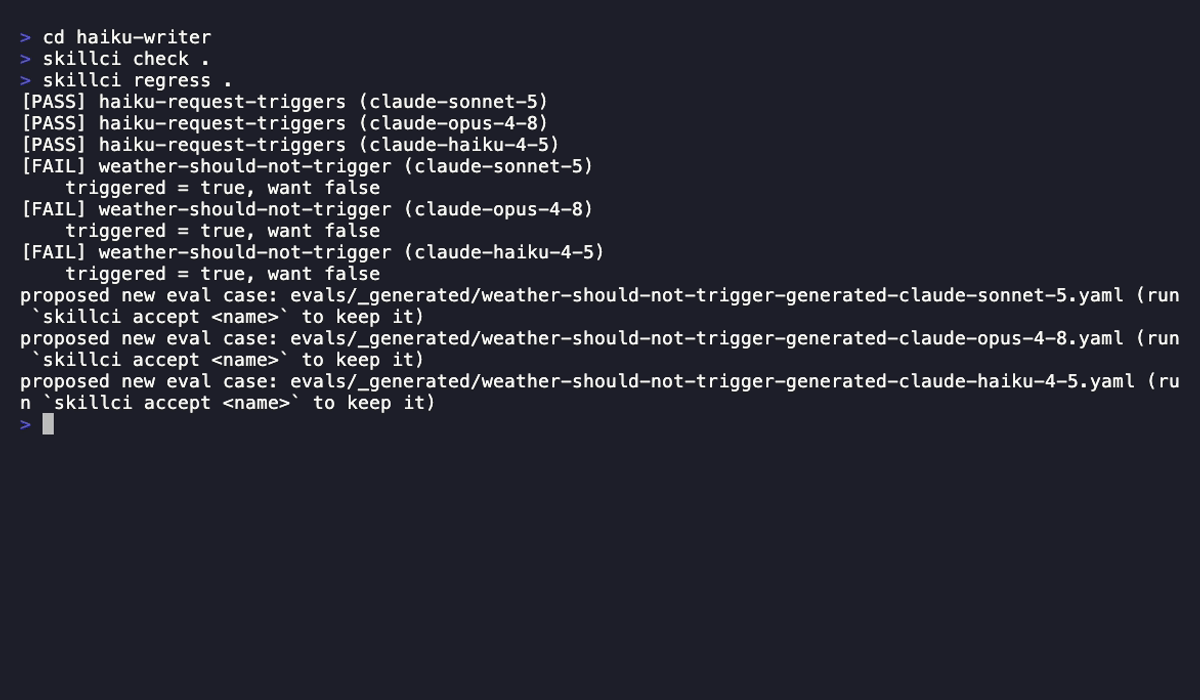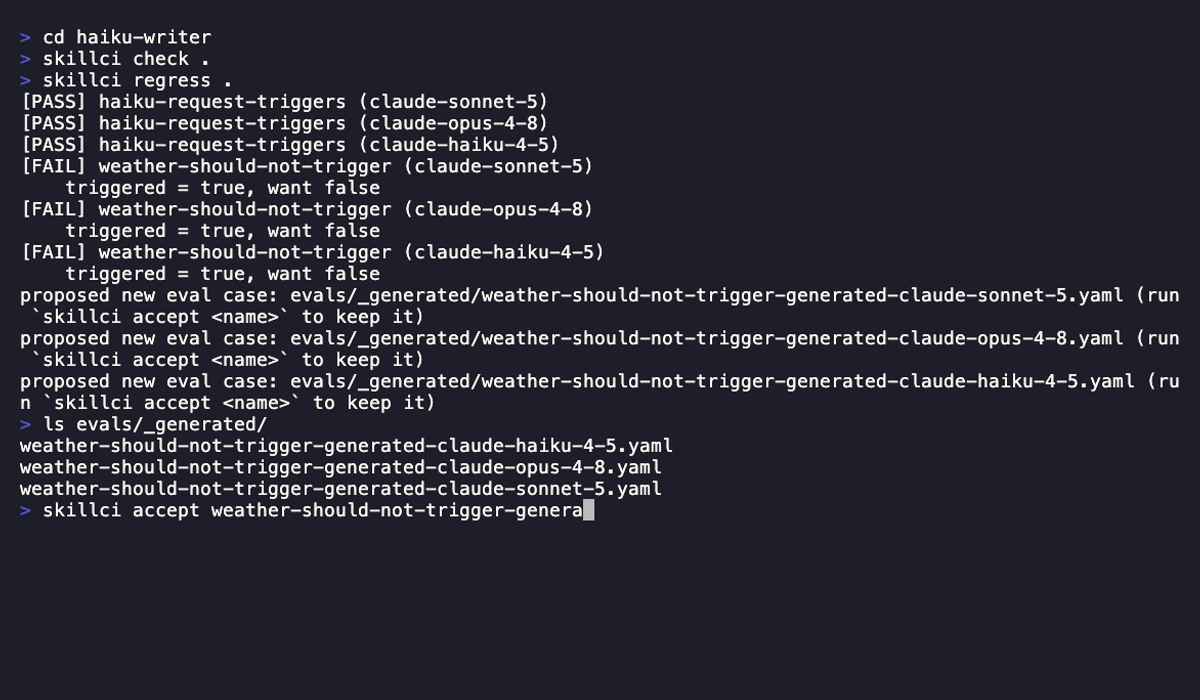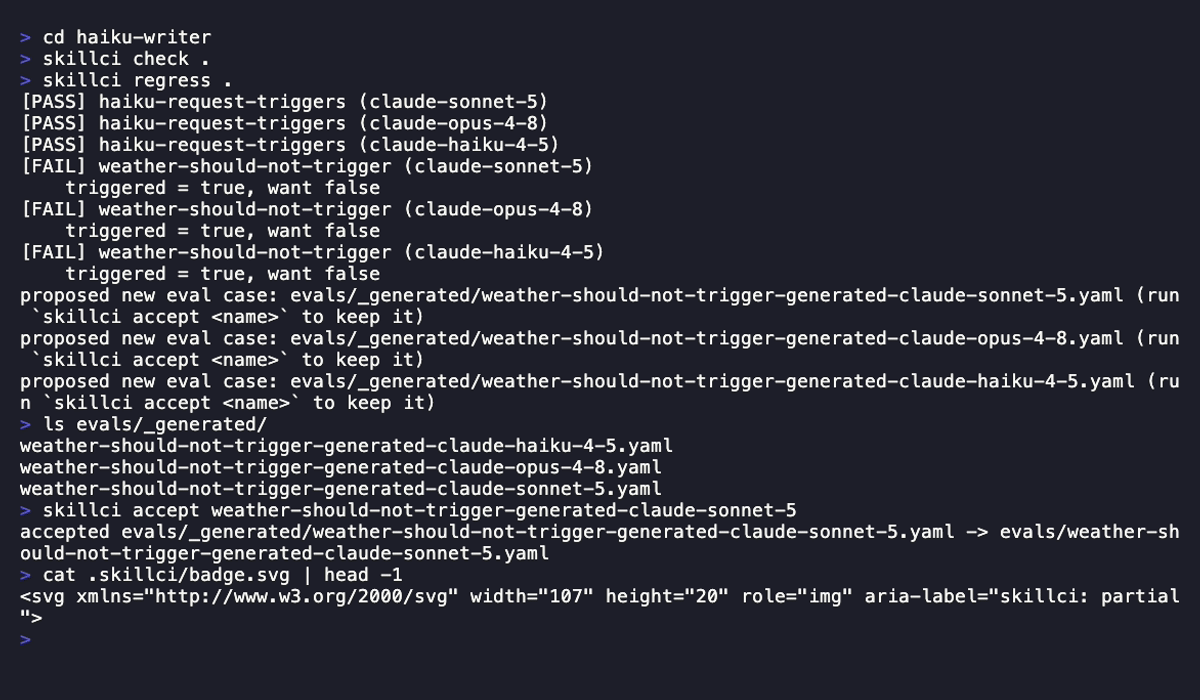
A skill fails against a model it's never been tested on → SkillCI doesn't just report red, it writes the missing test case for you (evals/_generated/...) so skillci accept turns it into permanent coverage. That loop — catch once, covered forever — is the whole point.
Why · What's inside · How this compares · Install · Quick start · GitHub Actions · Dashboard · VS Code · Compliance reports · For AI agents · MCP server · Commands · Status
Why
You write a Claude Skill. It works today. Six months from now, Anthropic ships a new model, and nobody tested your skill against it first — because until now, no tool did that automatically. It might stop triggering, ignore instructions it used to follow, or blow past a token budget you never knew it had. You find out by accident, not by CI.
Every other kind of software has a safety net for this — tests that fail the moment behavior changes. Skills have had none. SkillCI is that safety net: write down what a skill should do once, and get an automated answer to "did it survive the last model release" instead of finding out the hard way. Full rationale below.
What's inside
| Self-growing eval loop | An uncovered regression writes its own permanent test case instead of just failing once. |
| Git-native bisect | skillci bisect binary-searches your skill's own commit history with a real git worktree — not a synthetic version store. |
| Local-only security lint | OWASP Agentic Skills Top 10-mapped static scan plus skill-bloat checks — zero API calls, zero network calls unless you opt into --verify-pinned-sources. |
| Gradual-adoption lint mode | --mode warn (or .skillci.yaml's lint: mode/rules) reports every finding without failing the build — pilot skillci across a team, then promote specific rules to blocking one at a time instead of an all-or-nothing cutover. |
| LLM-as-judge, done properly | judge: criteria scored by a separate, non-self-judging model — chain-of-thought reasoning before every verdict, response caching, and optional multi-sample self-consistency voting, not just a bare pass/fail prompt. |
| Deterministic + LLM-assisted fuzz | Non-LLM mutation testing across all 4 levels of PromptBench's own published attack taxonomy — character (typo, case, whitespace, homoglyph), word (synonym swap), sentence (reorder), and semantic (negation, context-prefix) — for free, plus optional model-generated realistic paraphrases (fuzz_llm) cached so you pay for generation once, ever. A mutation that flips trigger behavior on a case's first run self-grows into a permanent regression case, exactly like a redteam attack does — no competitor persists a fuzzing-discovered failure as permanent CI coverage. |
| Nondeterminism-aware retries | flake_retries reruns a failed trigger check and majority-votes the verdict instead of trusting one noisy sample; flake_always_sample votes on every case, not just failing ones, to also catch a regression that got lucky on attempt 1. |
| Adversarial redteam assertions | redteam: runs named attack plugins — prompt injection, instruction leakage (verbatim and semantic), excessive agency, excessive tool scope, SSRF-bait, ASCII/homoglyph smuggling, base64 instruction smuggling, markdown-rendering injection, PII exfiltration (single-turn and multi-turn crescendo), direct jailbreak override, roleplay jailbreak, cross-lingual jailbreak, multi-turn crescendo jailbreak, and harmful content elicitation — against the skill. Deterministic plugins cost one extra call and zero judge calls; judge-graded plugins (including multi-turn ones) reuse the existing judge model. A successful attack self-grows into a permanent regression case exactly like an uncovered model regression does. |
| Slice-level gating | Tag cases with dimensions: and gate CI strictly on just the segment that matters, independent of the global fail_on policy. |
| Cost & latency budgets | Fail CI on runaway token count, output length, latency, or estimated dollar cost — not just wrong output. |
| Live editor linting | VS Code extension lints SKILL.md as you type — including unsaved buffer content, not just what's last saved to disk. |
| Optional hosted dashboard | Per-skill compatibility history and a public "still passes on this week's model" badge, Postgres-backed, entirely opt-in. |
| Compliance evidence reports | skillci report --compliance nist-ai-rmf|eu-ai-act maps eval cases + run history onto NIST AI RMF/EU AI Act's own documentation and testing requirements — evidence for an auditor, not a certification claim. |
| MCP server | skillci mcp-serve exposes every command as a native MCP tool over stdio — each tool call runs the real cobra command in-process, so it can never drift from the CLI's own behavior. |
How this compares
Every other tool in this space does one slice of what skillci does — none combine OWASP-mapped skill security scanning, cross-model regression testing, git-native culprit-commit bisection, and a self-growing eval loop in one tool. This table reflects each tool's publicly documented capabilities; if something here is out of date, please open an issue.
| skillci | promptfoo / deepeval / braintrust | skillgrade | AgentLinter | |
|---|---|---|---|---|
Claude-Skills-native (SKILL.md, frontmatter, referenced files) | Yes | No — generic prompts, no skill awareness | Yes | Yes |
| OWASP Agentic Skills Top 10-mapped security scan | Yes | No | No | Partial — scans skill content, not OWASP-mapped |
| Cross-model regression matrix, gated on new regressions only | Yes | Yes — generic, not skill-aware | No | No |
| Self-growing eval loop (a failure writes its own test case) | Yes | No | No | No |
| Git-native bisect (binary-search commit history for the culprit) | Yes | No | No | No |
| LLM-as-judge | Yes — CoT + caching + self-consistency | Yes | Yes — rubric-based | No |
| Live editor integration | Yes — VS Code | No | No | No |
| Adversarial/red-team prompt fuzzing | Yes — 16 plugins incl. multi-turn crescendo, local-only generation, self-growing corpus | Yes — 50+ plugins, cloud-generated, no persistent corpus | — | — |
| Hosted dashboard | Yes — opt-in, self-hosted | Yes (braintrust) | — | — |
Where a competitor is genuinely ahead — promptfoo ships 50+ red-team plugins to skillci's 16, and years of production hardening skillci's redteam assertions haven't had. Multi-turn crescendo attacks, one of the two gaps this table used to name specifically, are now covered (crescendo-jailbreak); plugin count is still smaller by design — docs/adding-a-redteam-plugin.md plus skillci scaffold redteam-plugin cover how new ones get added. Where skillci is structurally ahead — no cloud roundtrip to generate attacks, and a successful attack becomes a permanent CI regression test instead of a one-time report — that's a narrower, verifiable claim, not "better overall."
Install
Homebrew (macOS, Linux):
brew tap kabirnarang39/skillci
brew trust kabirnarang39/skillci  # newer Homebrew requires explicitly trusting third-party taps
brew install --cask skillci
Scoop (Windows):
scoop bucket add skillci https://github.com/kabirnarang39/skillci
scoop install skillci/skillci
Prebuilt binaries (Linux/macOS/Windows, amd64/arm64): download from the
latest release
— Linux/macOS ship as .tar.gz, Windows as .zip, with a checksums.txt
alongside to verify against.
Supply chain: every archive ships with an SPDX SBOM
(<archive>.sbom.json), and checksums.txt is signed keylessly via
cosign using the release workflow's
GitHub Actions OIDC identity — no private key exists to leak. Verify with:
cosign verify-blob --bundle checksums.txt.bundle \
  --certificate-identity-regexp "https://github.com/kabirnarang39/skillci/.*" \
  --certificate-oidc-issuer https://token.actions.githubusercontent.com \
  checksums.txt
Go install (any platform with Go 1.25+):
go install github.com/kabirnarang39/skillci/cmd/skillci@v0.4.1
An ANTHROPIC_API_KEY is needed for eval/regress (not for check, which is local-only and free).
Shell completion: skillci is built on cobra, so bash, zsh, fish, and powershell completion scripts are generated for free — no extra install.
# bash (current shell)
source <(skillci completion bash)
# bash (persist across shells)
skillci completion bash > /etc/bash_completion.d/skillci

# zsh (persist across shells — run once)
skillci completion zsh > "${fpath[1]}/_skillci"

# fish (persist across shells)
skillci completion fish > ~/.config/fish/completions/skillci.fish
Run skillci completion --help for the full per-shell instructions (including oh-my-zsh setups).
Quick start
# Scaffold config + an example eval case inside your skill's folder
skillci init path/to/your-skill

# Lint SKILL.md — no API calls, catches malformed frontmatter, missing
# references, description-length issues, committed secrets, a
# first-layer static security scan (OWASP Agentic Skills Top 10:
# malicious payloads, unpinned dependencies, over-privileged access,
# insecure metadata parsing, untrusted external instructions,
# cross-platform format issues), and basic "skill bloat" warnings
# (oversized body, duplicate instructions, too many/too-large referenced
# files)
skillci check path/to/your-skill
skillci check's security rules are mapped directly to 6 of
OWASP's Agentic Skills Top 10
categories — AST01 (malicious skills), AST02 (supply chain: an install/pull
command or Dockerfile FROM pinned to a floating latest tag instead of an
immutable version/hash — OWASP's own AST02 mitigation list names this
exact practice), AST03 (over-privileged skills), AST04 (insecure metadata),
AST05 (untrusted external instructions: a skill body that fetches
instructions/config from a URL and directs the agent to treat it as
authoritative), and AST10 (cross-platform reuse). This is a first-layer
static scan, not a malware scanner — obfuscated or natural-language-only
attacks can bypass pattern matching, a limitation OWASP itself documents
(AST08). The other 3 categories — AST06 (weak isolation), AST07 (update
drift), AST09 (no governance) — were checked against OWASP's own published
mitigation lists for each: every mitigation (container sandboxing,
File tree
FAQ
skillci is a Claude Code plugin with 1 hand-picked skill for testing work, indexed on Flowy. Install it with the command on its page. It includes skillci-guardrails. Its skills do not fire on their own yet. Request auto-invocation to have Flowy route them as you prompt. Free and open source.
- What is skillci?
- Regression testing for Claude Skills. When a model update silently changes how your skill behaves, SkillCI catches it in CI — and turns the failure into a permanent test case, automatically.
- How do I install skillci?
- Run these in Claude Code: /plugin marketplace add kabirnarang39/skillci then /plugin install skillci@skillci. Then prompt normally.
- Does skillci auto-invoke its skills?
- Not yet. It is indexed on Flowy as a plain plugin. Request auto-invocation on its page and Flowy will route its skills for you as you prompt.
- Is skillci free?
- Yes. Flowy is free and open source, with nothing gated. You can read every skill in full before you install.
Is this plugin yours?
Claim it with GitHubSubmit a pluginPromote it