Polygraph
Your tests check the paths you thought of. Polygraph checks the ones you didn't.
Polygraph is a Claude Code plugin (and standalone CLI) that finds bugs in
stateful code — workflows, reducers, protocol handlers, checkout flows,
session managers — by exhaustively exploring every state the code can reach
over a finite, declared domain of actions and payloads, and flagging the
ones that break rules you care about, like "a customer is never charged
twice."
You don't need to know anything about formal verification to use it. You
write the rules as plain JavaScript predicates. The heavy lifting — deriving a
formal model of your code, exploring the state space, producing a shortest
path to each violation — is done for you.
Disclosure — read this first. Polygraph is experimental, not
peer-reviewed, unproven technology. It is a consistency check, not a
proof: a clean run means the code's observable behavior matches an
independent reading of its own source, and nothing more. "Exhaustive"
always means exhaustive over the finite (action, data) domains declared
in the contract — not over unbounded real-world data (see
What "exhaustive" means).
Every finding is a
lead to investigate by hand, not an established result. Do not rely on it
as your only safeguard for correctness- or safety-critical code.
About
Polygraph is developed by Cognitive Fab LLC (https://cognitivefab.com). For
questions, commercial support, or collaboration, reach us at
hello@cognitivefab.com.
Demos & write-ups
The DAAO demo — a Dual-Authorization Action Order machine taken end to end
through the method (author it, break it, catch it, version-gate it) — lives in
its own repo: cognitive-fab/polygraph-demo-daao.
Three articles walk the demos:
- DeepSeek wrote the code. A two-line prompt checked every reachable state. — auditing existing code with
/polygraph:verify.
- polygen wrote the dual-authorization code — authoring verified-from-birth code with polygen.
- You just changed the code of your state machine. Now what? — version-gating a change against the live fleet with polyvers.
Why Polygraph
Unit tests execute the scenarios you wrote. A state machine of even modest
size has orders of magnitude more reachable states than any test suite
visits — and the bugs that hurt in production live in the combinations nobody
wrote a test for: a retry landing after a cancel, a timeout racing a
confirmation, an event arriving in a state where nobody expected it.
Polygraph attacks that gap in two ways:
-
Audit existing code (/polygraph:verify). An LLM reads your source and
writes an independent, executable specification of it — a second opinion on
what the code does. Polygraph then (1) replays real execution traces
against that spec to confirm it's faithful, and (2) model-checks it:
starting from the initial state, it tries every action with every declared
payload value, visits every state reachable that way, and reports any state that violates
one of your rules — with the shortest sequence of actions that gets there.
That counterexample path is a ready-made repro for the bug.
-
Author new code (polygen). Give it a one-sentence feature description
and it writes the state machine and its rules, model-checks its own
output, repairs violations, and hands you code with a passing exhaustive
check plus a generated regression trace corpus — verified from the moment
it's written.
Real result: on a production SaaS subscription-billing machine, this method
independently corroborated a genuine double-charge bug
(examples/case-study-subscription.md).
In the controlled eval, replay alone found 0/5 seeded bugs — model checking
found 5/5, with counterexamples
(eval/FINDING-faithful-reproduction.md).
Why not use TLA+ / Alloy / a model checker directly?
Those tools work — but you have to hand-translate your code into their
language and keep the translation current, which is why almost nobody does
it. Specifying even a small-to-midsize system is a multi-month effort, and
every code change invalidates the spec. Polygraph's bet is that an LLM can
produce that formal model from your source cheaply enough to rerun on every
change, and that replaying real traces against the model tells you whether to
trust it. You stay in JavaScript the whole time. (If you do want the real
thing, an optional --tla flag mechanically transpiles the winning spec to
TLA+ and runs TLC over it.)
This bet is no longer a fringe position — and the strongest evidence for it
comes from a project that is ahead of Polygraph on the one axis the two
share:
Specula: Scaling formal specifications for autonomous model checking of
system code. arXiv:2607.25333v2, August 2026.
https://github.com/specula-org/Specula (Apache-2.0)
Specula is an agentic TLA+ pipeline standing on the same three legs Polygraph
does — spec generation, model checking, trace validation. Its paper reports
249 bugs across 48 projects (MongoDB, Etcd, ScyllaDB, GCC libgomp, LLVM
libomp) in seven languages and 2K–95K LoC: 207 previously unknown, 89
reported upstream, 68 confirmed and 24 fixed, at a median of $57 and 3.7
hours per system. 200 of the 249 surfaced through model checking; the rest
came out of code comprehension along the way. The convergent finding is the
one that matters: the LLM alone is not trustworthy, but an LLM held
accountable by a model checker and trace validation is a practical
bug-finder.
On coverage, the two are closer than the languages suggest. It is
tempting to read this as rigorous-TLA+ versus pragmatic-JS. That is not
where the difference lies. Specula builds a reference model of the system
at whatever abstraction its invariants require, then projects that model
into smaller scenario models — bounding how often an action can occur,
collapsing a multi-step protocol into one atomic step, forcing an ordering.
The projection is sound in the direction that matters: a violation found in
a projection is a violation in the reference model. Polygraph enumerates a
finite (action, data) domain declared in the contract and visits every state
reachable over it. Both make an unbounded space tractable by declaring an
abstraction, then search what is left close to exhaustively — 93.5% of
Specula's model-checked bugs fall out of plain breadth-first search, at a
median counterexample of 9 steps. And neither measures the distance between
the declared abstraction and the real system. Their paper says so plainly:
"there is no formal guarantee that it models everything perfectly… A model
can therefore remain inconsistent with the implementation in ways we did
not catch, and a bug that depends on such a gap can remain undetected."
That is the same caveat we give in
What "exhaustive" means, from
a project with 249 bugs behind it. Read it as the shape of the field, not
as either project's weakness.
Where Specula is ahead of Polygraph's audit engine, plainly:
- Its capture is engine-owned and repeatable. Its agents instrument the
target, and a replay harness verifies post-state agreement inside the
pipeline, with a conformance repair loop. Polygraph's capture is owned by
the agent per run (Step 2 of the skill), so the harness is not by default a
committed, re-runnable artifact.
- It reproduces bugs in the running system, forcing the counterexample
schedule at code level and assessing consequence — 98% of the violations
it judges real, with reproduction a gate rather than an attempt. Polygraph
stops at a spec-level counterexample path.
- It guards its own repairs. When a spec is repaired to pass trace
validation, the repaired model is model-checked against protocol-level
invariants — catching repairs that bought conformance by admitting illegal
behavior. Polygraph's positive/negative controls prove the harness can
tell a good spec from a mutated one; that is a check on the instrument,
not on each repair. Different points, and we only have the one.
- It triages, and publishes the split. Of the violations that reach
reproduction: 47.5% confirmed as real bugs, 48.8% discharged as masked
with evidence — real invariant breaks with no observable consequence — and
1.0% left unreproducible. Polygraph hands you all of them as leads to
check by hand.
- It has third-party confirmation. Upstream maintainers confirmed 68 of
its 89 reported findings and fixed 24. Polygraph has one corroborated
production bug and a seeded-bug eval.
- It requires invariants to cite their evidence — a commit, code
location, issue, or advisory, and it reports the distribution (code and
comments back 87% of its invariants, issue trackers and pull requests
74%, commit history 43%). polynv harvests candidates but does not demand
provenance.
- It is agent-agnostic. Adapters ship for Claude Code, Codex, Copilot
CLI, OpenCode and Pi, and any phase can be routed to a different agent or
model. Polygraph's generation steps shell out to
ANTHROPIC_API_KEY.
The difference is not that Polygraph audits better. It is that auditing is
one engine of several here, and Specula has no authoring, no CI gate, no
runtime, and no versioning — its paper states specs are generated from a
snapshot and must be regenerated when the code changes. Its evaluation ran
on a 96-core, 384 GB machine driving Opus-4.8 at 1M context and maximum
reasoning; a single CometBFT module took 670 agent steps and 1.9 billion
generated states. At a median of $57 and 3.7 hours per system — 5–37× the
token cost of an unaided agent — it structurally cannot run on every merge
request; Polygraph's model check and replay are keyless and deterministic,
which is what makes polygate possible. Different bet, different slot. If
your problem is deep bugs in a large concurrent or distributed system
written in C, C#, C++, Erlang, Go, Java, or Rust, use Specula — that is
what it is for, and it is good at it.
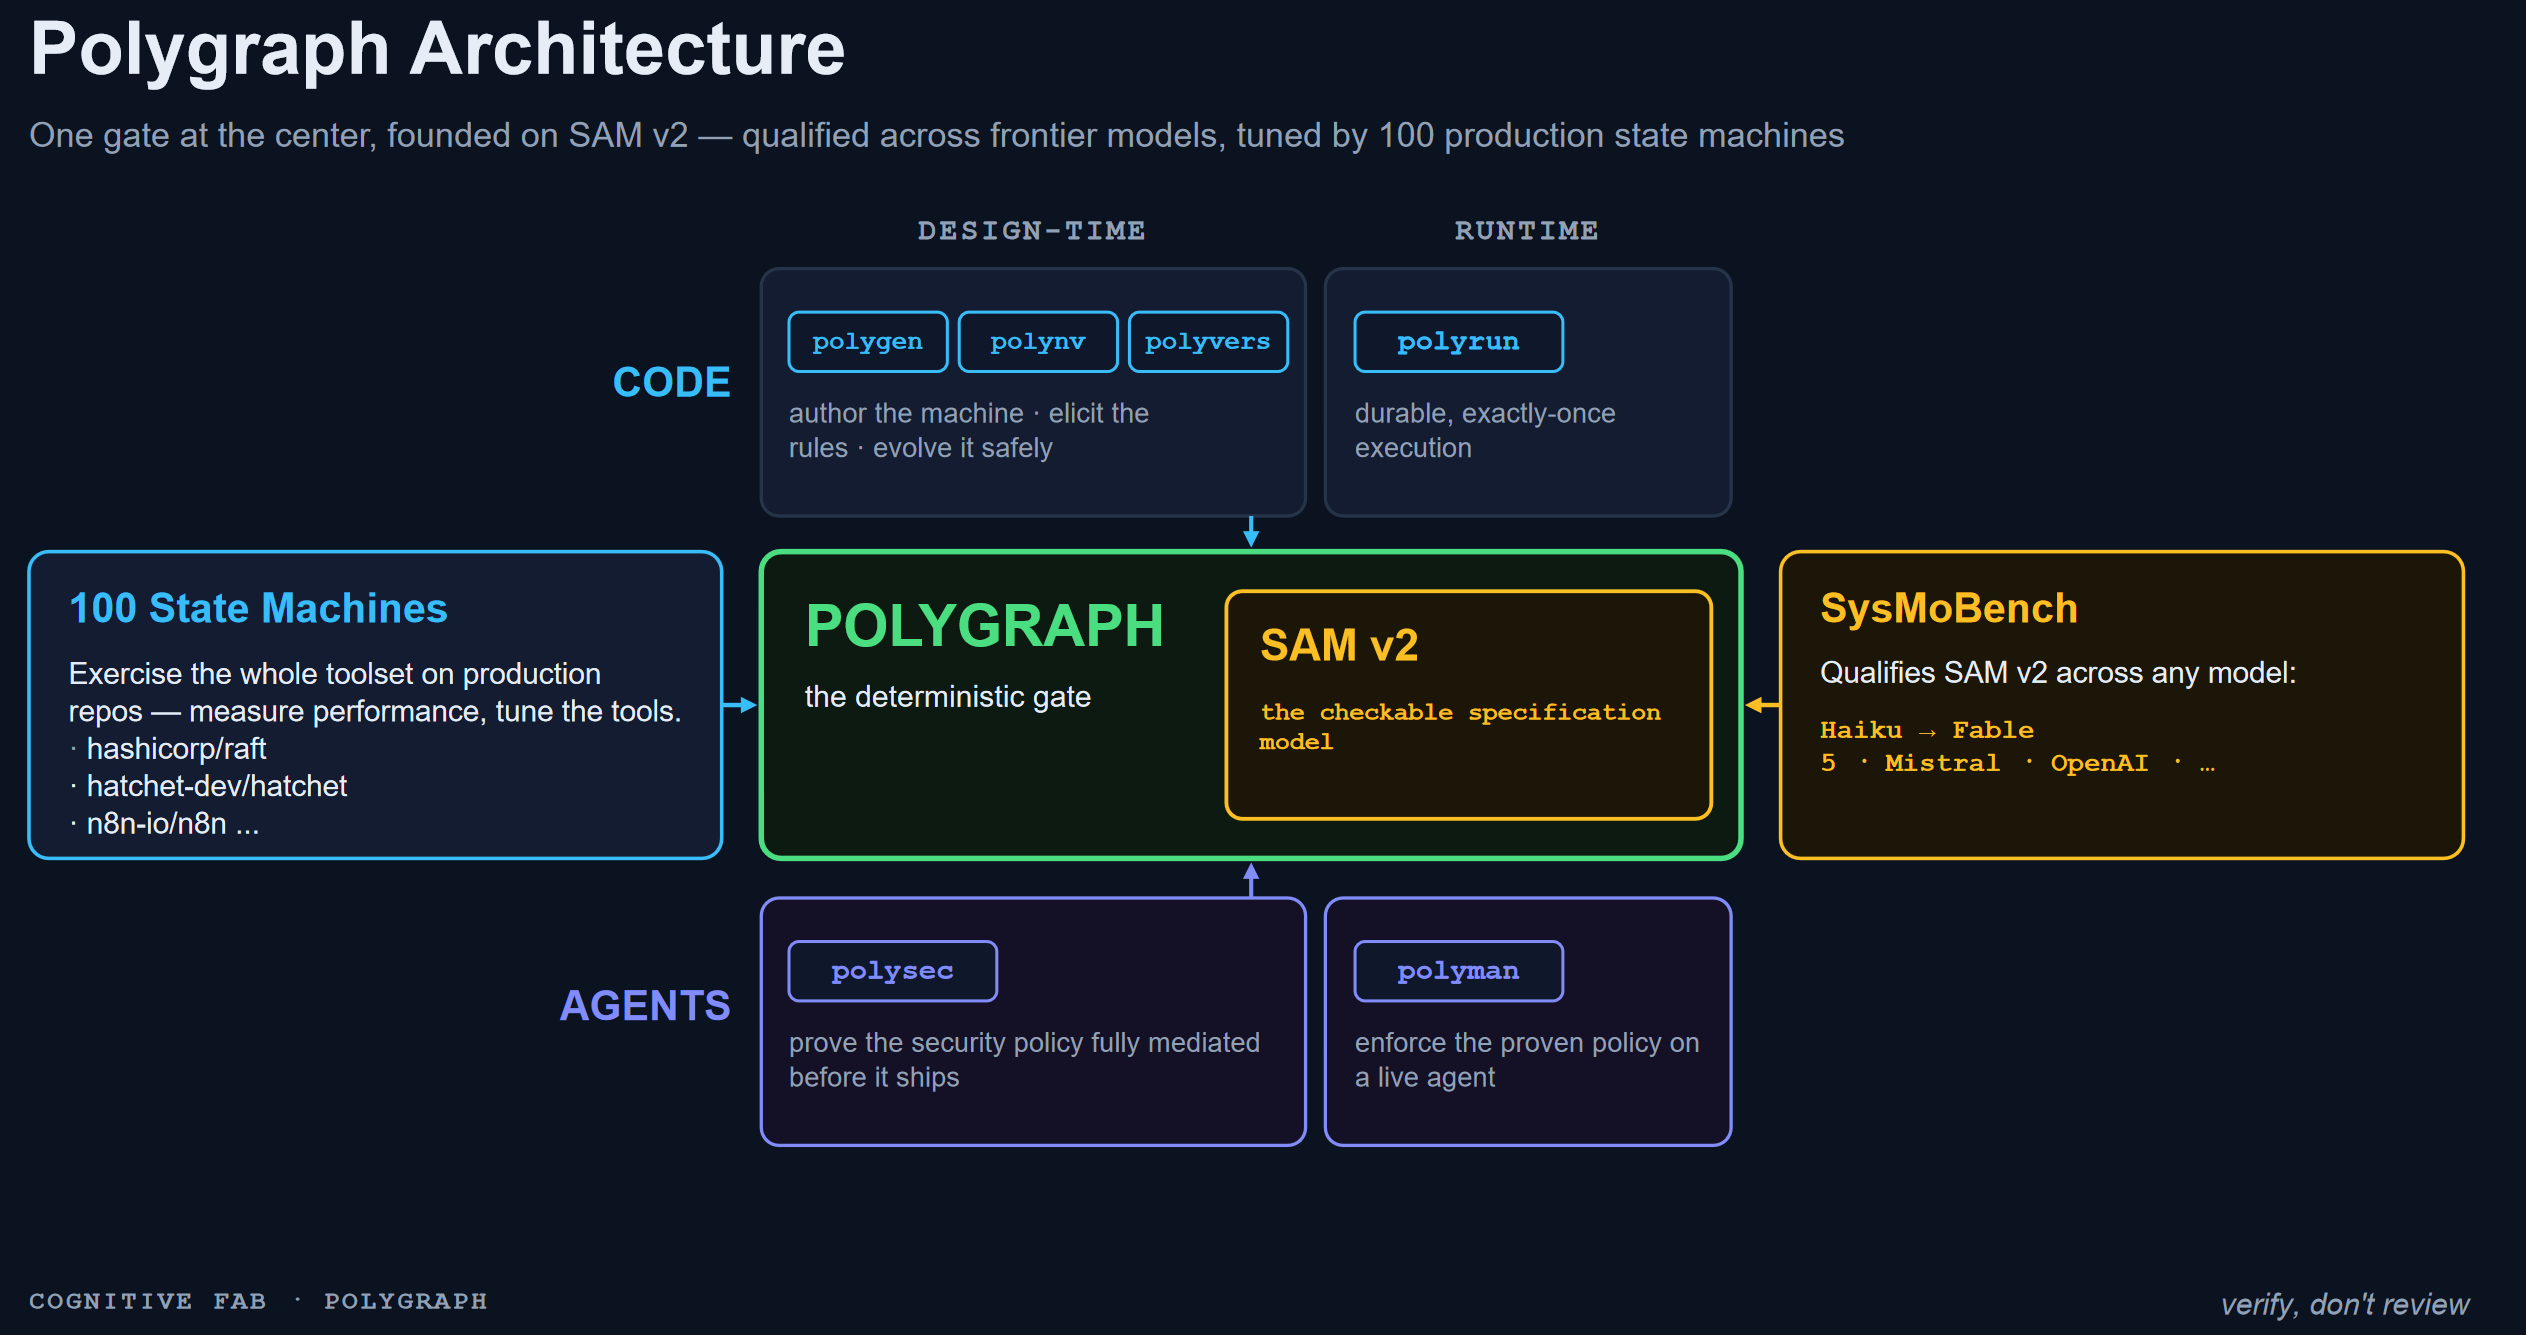
The five engines share one artifact family, so what one produces the
next can consume: Polygraph audits (this document), polygen
authors, polyrun executes,
polyvers evolves, polynv
elicits the rules they all check against.
Deep dives: docs/ARCHITECTURE.md — how the
five engines fit together;
docs/SDLC.md — a team lifecycle for
integrating them into agentic workflows, with the human gates spelled out;
docs/polyrun-spec.md — the durable-execution
harness specification; docs/VERSIONING.md — an
essay on why versioning state machines is hard and how the gates here
make compatibility a checked property instead of a review vibe. Each doc
has interactive diagrams inline; browse them all at
docs/diagrams/index.dc.html.
How it works



 @microsoft


